It's the first time in the history of the world.
AI mathematics is crossing a very fine line.
In the past, we've asked: Can big models solve a problem? Can they write rigorous proofs? Can they find counterexamples that humans haven't discovered in decades?
And now there's a question that's more like "scientific research itself": when a path to proof fails, does AI know what to do next? Do it go ahead, change paths, shrink propositions, or just come up with a new, falsifiable mathematical guess?
AI Has Taste, developed by researchers at the University of Singapore, is trying to turn this problem into a sustainable research system.
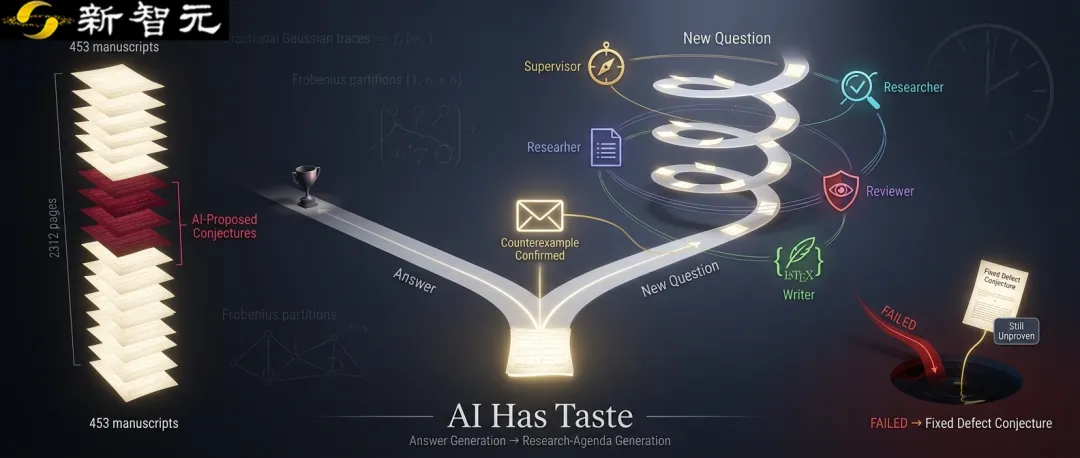
The project's public repository currently records 453 mathematical research manuscripts and 2312 pages of content, six of which are explicitly classified as "AI-Proposed Conjectures".
From Answer Generation to Research-Agenda Generation: From answer generation to research agenda generation.
The main page of the project:github.com/ArtificialZeng/AI-Has-Taste
AI overturned the speculation in the paper
Confirmed by the original author
AI Has Taste did not originate from the belief that "AI must be good at mathematics". He recalled that at the beginning of the project, he was not convinced that big models could actually advance mathematical research. One accidental test turned out to be a turning point: he gave the assumptions in a paper directly to AI, just to see how far the model could go.
His first reaction was not excitement, but disbelief. He wrote to the authors of the original paper to verify the contradictions and the inferences.
"At first I didn't believe it.AIIn mathematical power. Until I entered a paper's guess, AI directly gave a counter-example overturn; I immediately wrote to the original author and the other replied that it was correct.
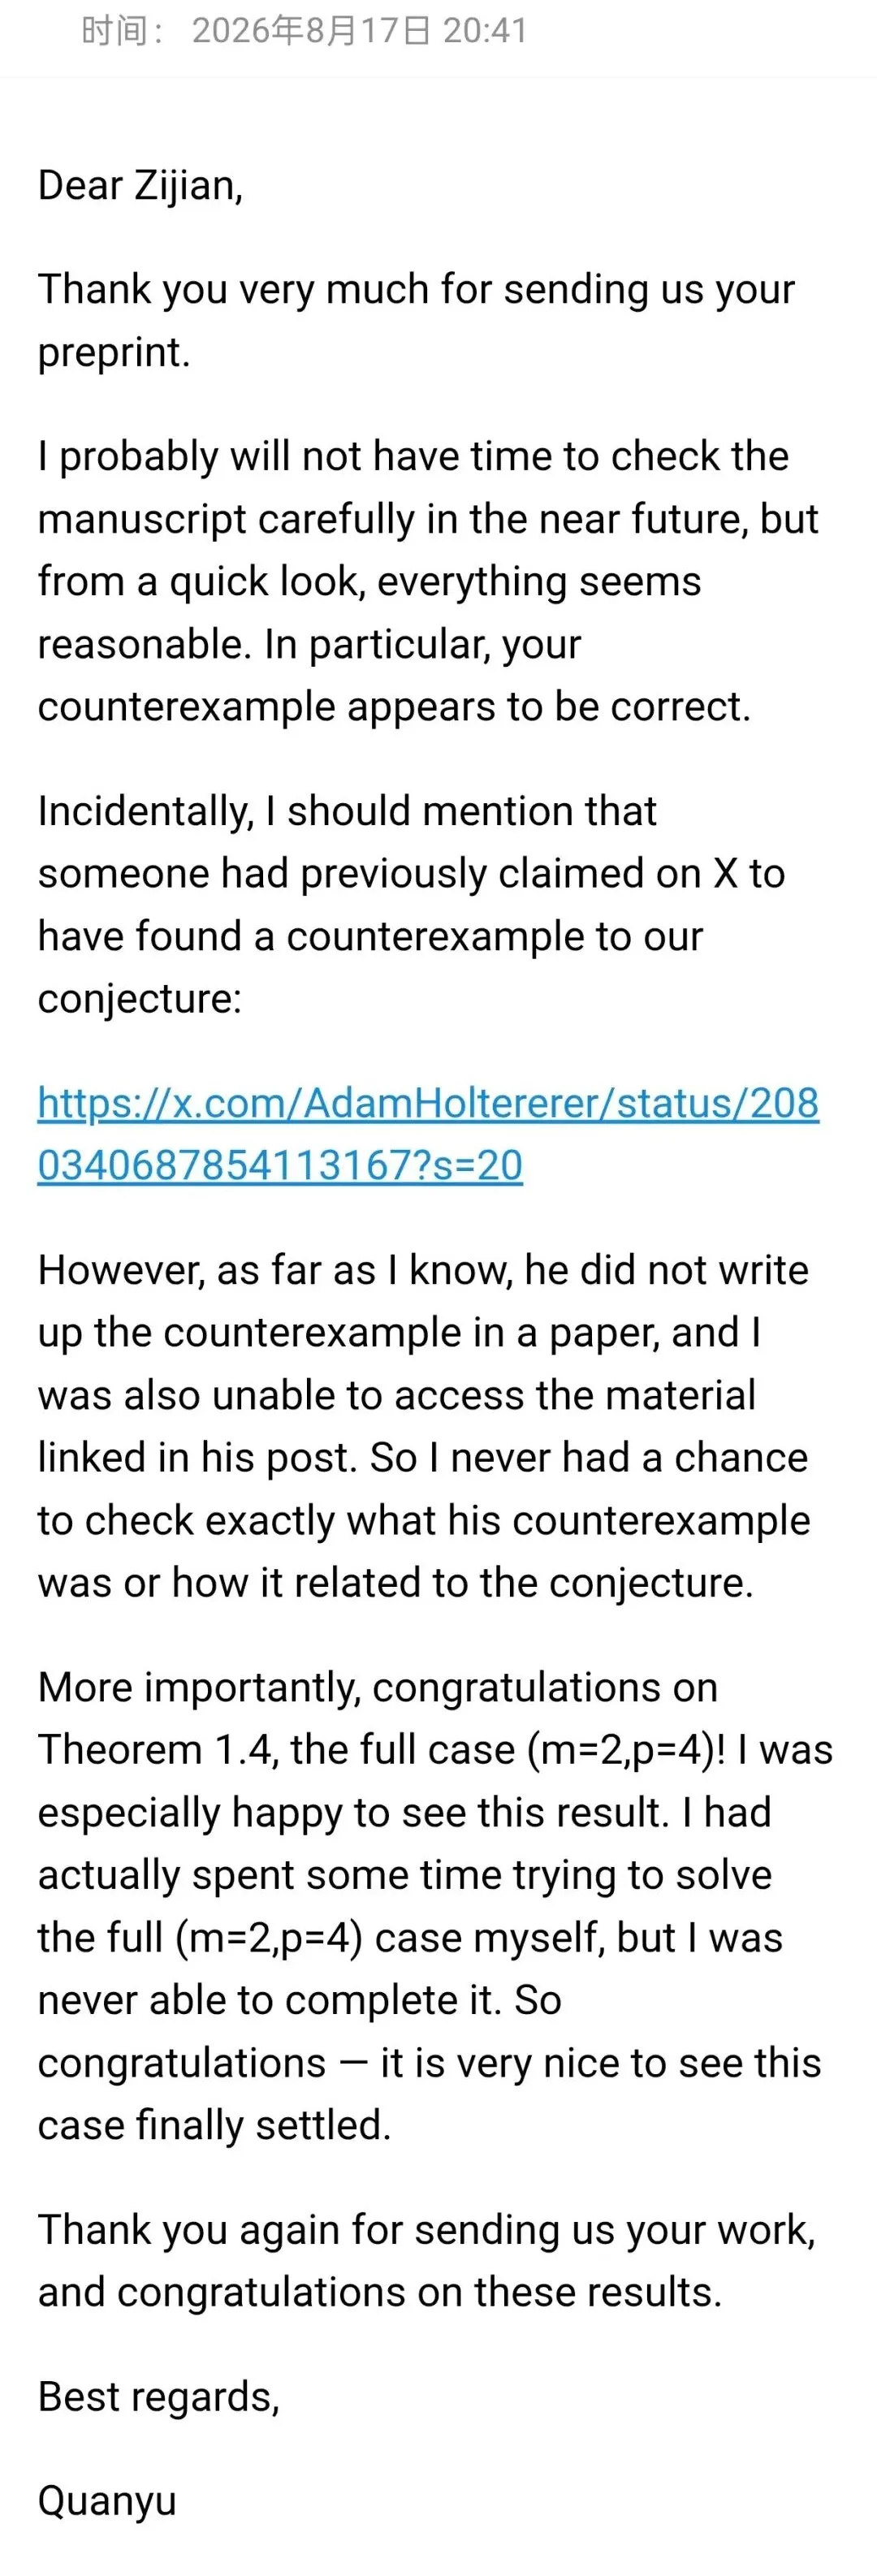
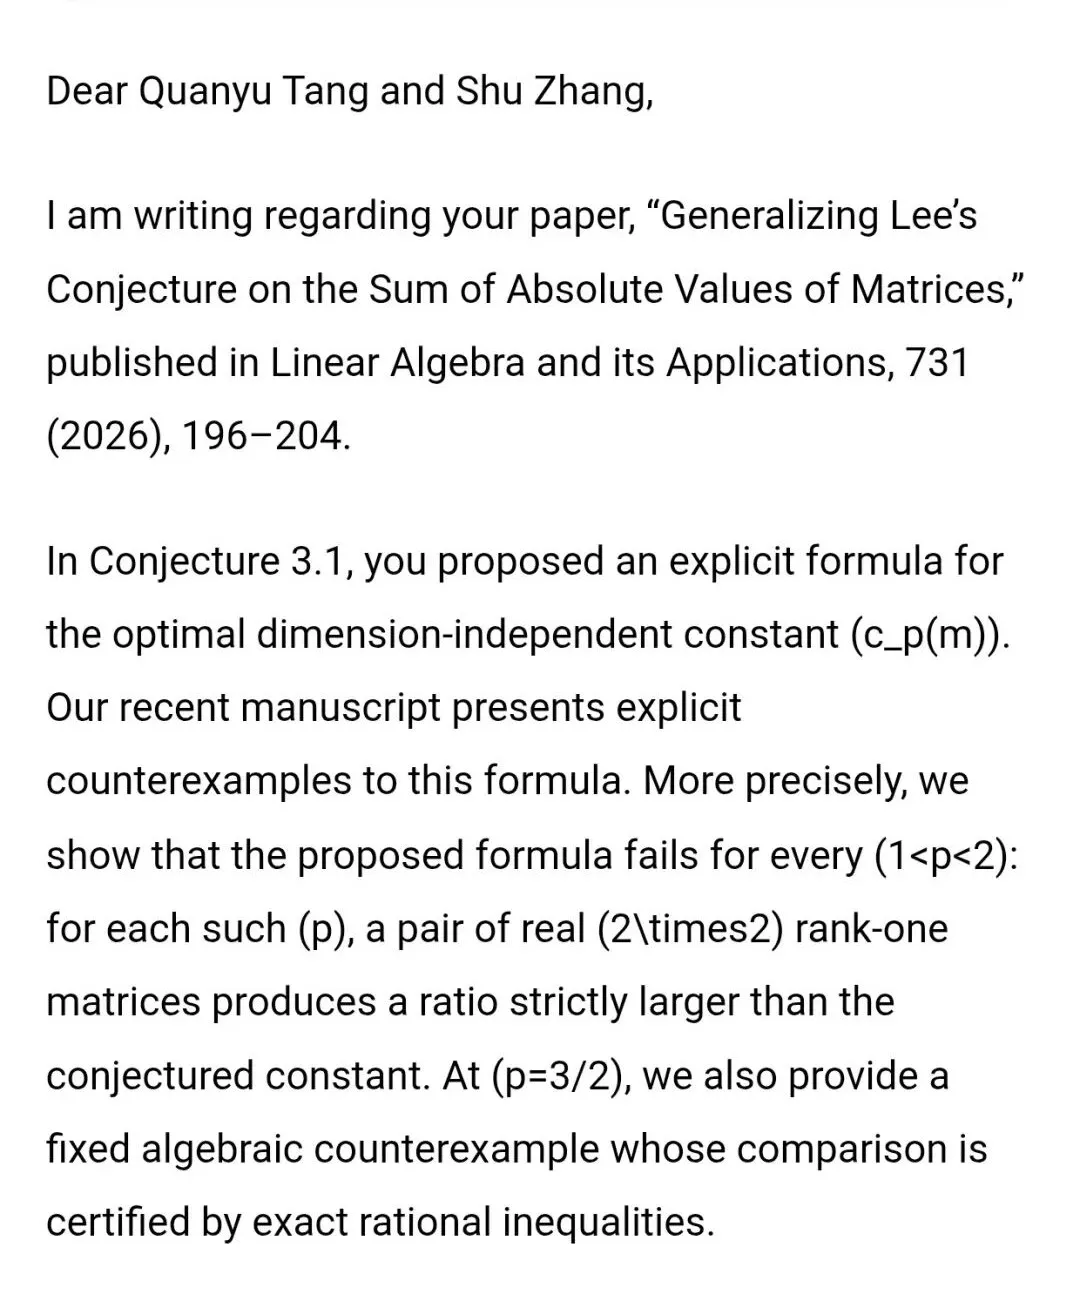
The email does not change a guess, but the scale of the project. If AI can not only replicate knowledge, generate text that looks like proof, but also actively attack new speculation in the paper, and find a contradiction that has been confirmed by the original author, then it has a chance to really enter the "research cycle".
A real changeIt's not "how many books have been written".453 manuscripts are sufficiently exhaustive, but if the project is understood only as an "AI mass-writing mathematical paper", the most remarkable part is missing.
The project itself has repeatedly stressed: 453 is the number of "research manuscripts" that are not equal to 453 original open problems that have all been solved. The products include complete proofs, counterexamples, local results, limited computational certificates, structured approximations, and papers that come up with new speculations.
True change occurs in the research chain. Traditional AI benchmarks often start with "theme already given": humans are responsible for the task, AI is responsible for solving the problem, and finally succeeds or fails. AI Has Taste extends the process back and forth so that AI can filter out candidate problems, compare routes, and actively find counterexamples; one route fails, it can also analyze the failure structure, modify the hypothesis, and continue to attack by handing over new mathematical objects to another independent agent.
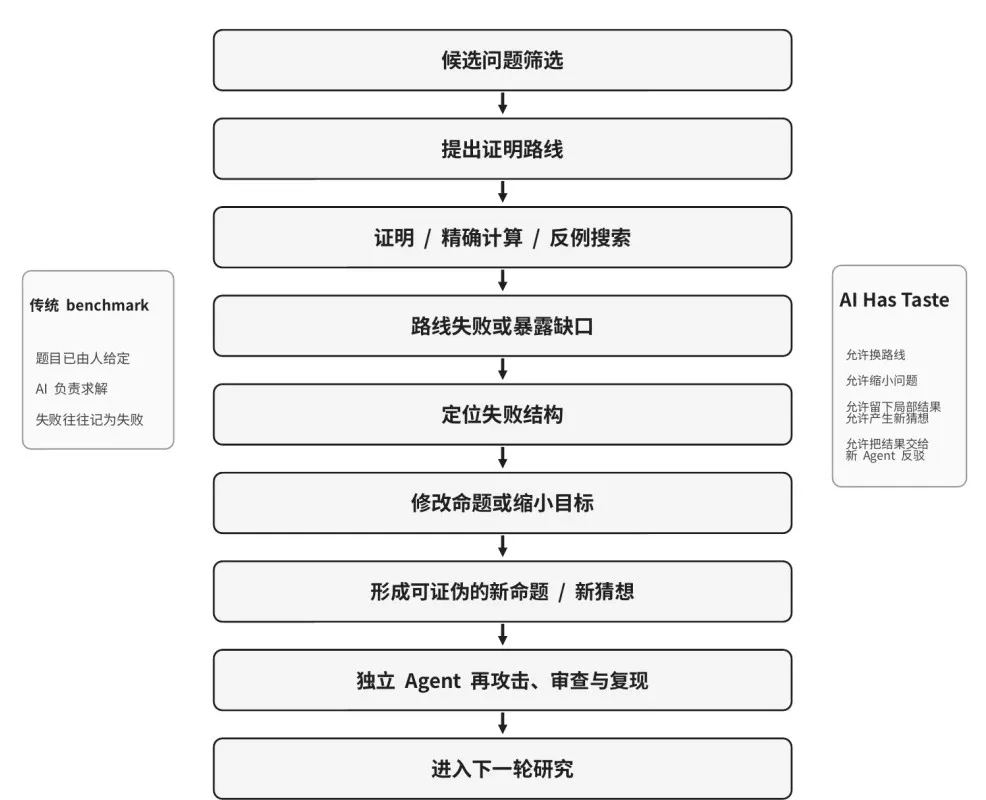
The key to AI Has Taste is not "more Prompt", but to turn failure into the next round of research inputs.
Subjects, proofs, mistakes, writing agents
The system is not "a model asks itself in a dialog box". Publicly readME divides the role of Agent into four layers:
Supervisor/Screener is responsible for selecting candidates, comparing nearby results and finding the cheapest decisive experiment;
The researcher is responsible for proof, counter-cases and accurate calculations;
Fresh-context Reviewer specifically attacks frozen propositions, key arguments and certificates in the new context;
The Writer/Release Checker is responsible for making clear the scope of final acceptance, and for checking references, builds and publishes materials.
Geng further deployed the workflow into multi-machine collaboration: different machines could individually advance proofs, search for counterexamples, run accurate calculations, and do independent reviews. Sharing was the freezing of propositions, experimental records, failure causes, code and evidence, rather than letting an agent generate results and stamp itself at the same time.
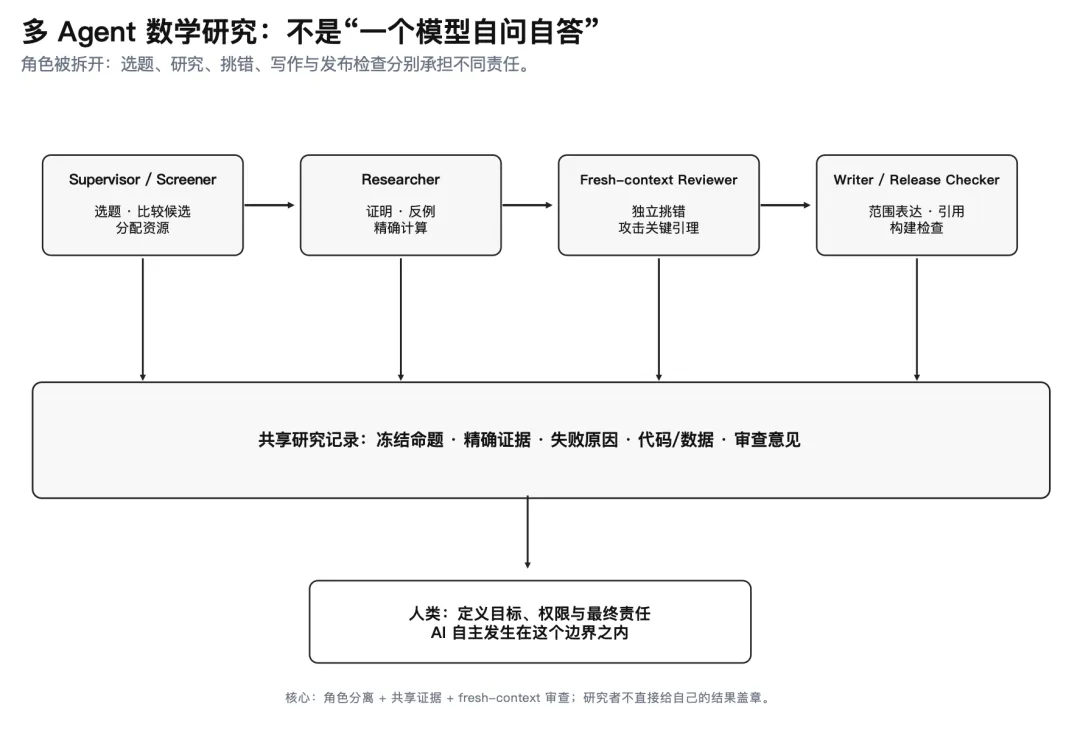
The core design of Multi-Agent: character separation + shared evidence + fresh-context review.
Criticism is part of the engine, not an afterword.
Mathematicians, robotics scientists and automakersAccess to the verification chainAs the study manuscripts grew from dozens to hundreds, another question became acute: Who would judge that these Agent products were not systemic hallucinations?
AI Has Taste uses the Fresh-context Reviewer to separate "research" and "make mistakes", but the project does not consider AI self-assessment as the end goal.
As the work progressed, Zhengjian also began inviting real scholars from different fields to participate in the verification, review and academic discussion of some of the results.
According to the project team, the collaborators and auditors involved in some of the work include: Academician of the Malaysian Academy of Sciences, Honorary Professor of the Institute of Mathematical Sciences at the University of Malaya, Ong Seng Huat; Academician of the Malaysian Academy of Sciences, Honorary Professor of the Institute of Mathematical Sciences at the University of Malaya, Kurunathan Ratnavelu; and Professor of the Institute of Artificial Intelligence and Automatic Chemistry at the Chinese Geological University (Wuhan).
A distinction needs to be made between "participatory verification" and "back-to-back for all results": the above scholars have not verified, audited or discussed 453 manuscripts individually, but have verified, reviewed, or discussed some of their questions, proofs, computational results, or research directions.
For a highly automated scientific research system, this combination of "in-machine red teams + human expert screening/reviewing" is more critical than handing all the reviews to the same set of agents.
AIResponsible for pushing the speed of research to the limit; human experts responsible for pulling "looking established" back to "believable" at key nodes.
After FailureIt's a better question.
The best example of "research taste" in the project is that it is not a beautiful success, but a failure.
In the problem of fractional Gaussian trace, the system initially attempted a single-tone and one-sided paired path, but precise counter-examples continued to emerge. The common benchmark here usually leaves only one label: FAILED.
But the workflow didn't stop. Agent continued to ask: What exactly did the counter-examples destroy? Did the failure have a stable structure? The final study turned attention to a fixed negative defect, constructed ten corrective structures, and proposed a new unifying hypothesis. More importantly, the new hypothesis was subsequently attacked by another round of precise calculations and independent review.
The point is that the original problem was not solved, but the failed pathway was compressed into a clearer, more falsifiable one, and once established it could reconnect with the original problem. The research did not end in failure, but grew into the next problem in failure.
In the past: Human issues,AIThe answer is:Now: AI answers, also starting to participate in deciding "what is the next question".
6 new AI guesses
As of the current public snapshot, the warehouse has separately classified six papers into "AI-Proposed Conjectures". These work span combinations, diagrams, numerical and analytical problems, including the infinite binary-kernel matrix non-uniqueness of the three sub-sequences A182510, CDS-colorability of Young graphs, unary-theta coefficient formulae of 18-colored generalized Frobenius partitions, non-negative Newton-number probability of recurcal-subsum denominators at the diadic stages, and the aforementioned fractional Gaussian trace fixed defect hypothesis.
The real concern is not whether AI can "brainhole a guess". It's not hard to guess. It's difficult to write a guess into a precise definition, explaining where it came from, what evidence supports it, what counter-examples it can overturn, what results it would lead to if it did, and leaving the calculations and source code to follow-up reviews.
This is why the project considers "providing conjecture" to be a higher-level research activity than "generating answers": proving that the answer to a question already exists and that conjecture will change the direction of research resources afterwards.
453 manuscripts behind itIt's a form of "Agent-scaled science".
AI Has Taste has released 453 research manuscripts totaling 2,312 pages, of which the BigWIN2 workflow corresponds to 223 manuscripts and provides a paired LaTeX/reproduction package for these 223 works.
The most counterintuitive part of this kind of scale is not "AI typing fast". Mathematical research is really expensive in context switching: this question requires graph theory, the next question is numerical theory, and the next question may require SAT, arithmetic, precise rational computation or matrix computation. A human researcher cannot simultaneously maintain hundreds of completely different ideas, but an Agent system can break them down into separate tasks, preserving failed routes, local theorems, and replicable experiments.
So the role of individual researchers is changing: not every step of the way, but rather, as a PI set the boundaries of research, choosing the pool of questions, deciding which results are worth continuing to invest, when to stop, and which conclusions are eligible to be made public.
Why is it called "AI Has Taste"?
"AI has taste" sounds very personalized, but the theme of the project README sets the boundary: taste is not a conscious or subjective experience, but "mathematical judgement expressed through research and decision making".
For example: which of the two questions can be done first? one route has already made local progress, but marginal gains are getting lower, don't stop? one counter-example is to put the proposition to death, or to show that the real theorem should be changed into an expression? one small result is not independent enough? these decisions were often implicit in the researcher's experience in the past and are difficult to measure by standard benchmarks.
AI Has Taste tries to leave these decisions in a verifiable trajectory: which problem was chosen, why the path was changed, what structure failed to leave, where the next proposition came from, and how new conclusions were independently attacked again in the context.
How far are we from "autonomous mathematicians"?Where the project is most likely to be exaggerated, it also needs to be made clear. 453 manuscripts are not 453 peer-reviewed journal papers; Agent Internal Review is not the same as an independent review by the mathematical community; the scope of limited computational coverage cannot be automatically extended to infinite situations.
However, ignoring the way the research is organized simply because these results have not yet been fully externally verified misses another change: the boundaries of AI's capabilities are moving from "performing a given task" to "engaging in the design of the next task".
The real scarcity of resources for mathematical research has never been limited to the length of arithmetic and reasoning, but also includes: what problems are worth spending time on, what failures are worth keeping, and when should they be replaced.
As AI enters these domains, the competition for AI for Math will no longer be just "who will prove more", but will gradually turn into: who has a better research loop, who can refine a more worthy direction to pursue in the face of massive failures.
One More Thing
The story of AI research in the past is very much like that of a super student: a teacher poses a question and he is responsible for solving it.
And what AI Has Taste wants to do is be more like a group of researchers: humans give boundaries and value judgments, agents look for problems, test problems, make mistakes, overturn themselves, leave local results, and then come up with the next problem.
If this path continues, perhaps the most important human division in future basic research will shift from "human thinking, AI computing" to a more complex structure: human responsibility for goals, values and ultimate responsibility; AI undertakes large-scale search, verification, failure management and the generation of candidate research directions; formalized tools and public evidence are responsible for making the results verifiable.
After AI does the quiz, the next thing is probably true: AI won't do the quiz.