One, what is OmniVChat?
From audio video questions and answers to native audio video conversations
In existing studies of audio-video interaction, the definition of a tangent interaction is often the answer to a question about audio-video content, such as for a streaming video, a user enters a text question, and then the model selects the appropriate time to answer. Such interaction differs significantly from the interaction paradigm between everyday users and AI (such as making video calls with AI).
In this article, we define OmniVChat (Omni Video Chat) as native audio video conversation: the model directly receives user audio and video at the same time, without any additional text problems, external subtitles or voice recognition transcripts, so as to retain tone, pause, facial expressions, and lens-facing clues. For example, the user holds a cell phone and shoots the question: "Does the door to the left of the conference room open?"
Author units: Chinese University of Hong Kong, Alibaba Token Hub, Shanghai University of Transportation, Shanghai Institute of Innovation and Technology, and Zhejiang University
The title of the paper is:
OMNIVCHAT: SYNTHESIZING, BENCHMARKING, AND TRAINING FOR NATIVE AUDIO-VISUAL DIALOGUE
The following is a link to arXiv:https://arxiv.org/abs/2609.21465
Hugging Face data collection:https://huggingface.co/datasets/Harland/OmniVChat
GitHub code:https://github.com/HarlandZZC/OmniVChat
The first author is Dr. Ho Chi Minh, DSP LAB at the Chinese University of Hong Kong; Dr. Chu Yun, Alibaba Token Hub (ATH) algorithm scientist, key contributor to the Qwen-Omni series; Dr. Chen, X-LANCE LAB at Shanghai Transport University.
Qwen-Omni series project manager and assistant professor at the Chinese University of Hong Kong
Second, study the state of affairs:
What's missing is both data and rating standards.
To study this capability, users need audio video data that is actually directed to the model to be trained and evaluated. However, the recording data of user conversations with the model on their own devices is still very scarce, making it difficult to cover the details of different environments and interactions. In particular, multiple rounds of native audio video conversation data, which include AI's responses to the user in the first round, are almost impossible to find. Due to the scarcity of data, the existing Omni model's native audio video conversational capabilities are in fact improved, often requiring various auxiliary modules (such as voice transcription) to assist the interaction, but voice transcription text-assisted modules tend to bring additional computational losses and information loss, drawing the upper limit of the interaction experience.
Second, a good answer often takes into account the environment, objects and emotions, and the same multiple expressions, and it is difficult to accurately judge the quality of AI responses based on keywords alone.
Three, created to understand.
The advancements in audio video co-generation and Agent make it possible to see "generation for understanding" as a viable route: first defining the ability to test, then synthesizing the corresponding dialogue, and forming reference responses and rating standards based on actual audio video content.
As a result, we built the OmniVChat-Studio data engine, the OmniVChat-Bench rating benchmark, and the OmniVChat-RL reinforcement learning incentive design to combine the data creation, measurement and improvement models of native audio and video conversations.
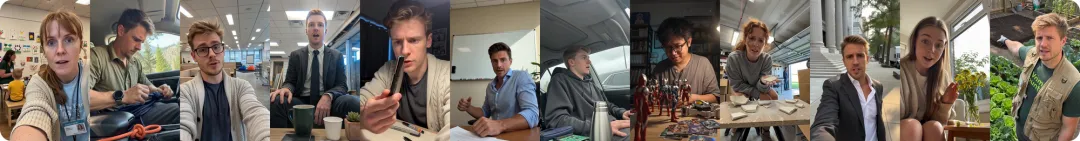
Figure 1: OmniVChat-Bench overview. Each card is taken from a user image in a synthetic conversation.
It's the first time I've ever heard of this.
Single-wheel and multi-wheel native audio and video conversational data engine
We designed OmniVChat-Studio, a Multi-Agent native audio video conversation data engine, with input as a subset of configuration and text content (as a random seed) and output as a single, multi-round audio video conversation with reference responses and layered judging standards.
In OmniVChat-Studio, there are four intelligent body collaborations. The Director is responsible for scenario conception, script and prompts, audit decisions, and reference responses and rating standards.