Real homework often starts with "incomplete information": robots don't know where the target is, and users don't have to be able to say what they want. Faced with vague instructions like "help me get snacks off the table", robots not only actively search for candidate objects, but also ask users to confirm which one to pick after finding bread and several doughnuts.
In the real world, exploring the environment, understanding intentions and executing actions are not three separate issues.
Researchers from the Shanghai University of Transportation and the Shanghai Artificial Intelligence Laboratory have put forward a proposal to address this issue.REALAn explorable, interactive, deployable visual and physical intelligence framework for mobile operations in an open world, and a complete technical link between simulation, data generation, model training, system evaluation, and real-machine deployment.ECCV 2026Received.
The following is a link to the paper:https://arxiv.org/abs/2607.13653
️ Main page of the project:https://internrobotics.github.io/REAL/
Open the source code:https://github.com/InternRobotics/REAL
One, from simulation to the real world:
There is no "God's point of view", and there is no "perfect direction".
In its move from simulation to the real world, REAL focuses on two over-idealized assumptions in existing physically-intelligent simulation environments:Environmental information is well knownwithThe user's intent is clearIn real deployments, smart bodies often face the opposite.Environmental Unknownthe lack of prior perception of robots; andIntent is unclearIt is difficult for users to specify one-time requirements at the start of tasks. Specifically:
First of all,Lack of information on environmental statusExisting simulation environments typically provide real information such as the number and location of mission-related objects through privileged perception interfaces (oracle perception API), but in real environments, such information cannot be directly accessed, and intelligent entities need to rely on active exploration to discover objects.
The second isConfusing information about user intentExisting physical intelligence assessment tasks usually assume that the instructions are clear and clear, but users in real situations do not necessarily know the full picture of the environment, often only give vague requirements, and gradually fine-tune tasks according to the feedback of the intelligent body. Therefore, the intelligent body in the real environment needs to be able to feedback on the current state of the environment and adjust subsequent behaviour according to user needs.
To address these two types of uncertainty, REAL will actively integrate exploration, visual target positioning, natural language intent disagreements, and physical operations into a single decision-making loop: the system uses first-person perspective RGB observation as the primary perceptual input, and combines the carrier areas provided by the mapping system (such as desktops, cabinets) as the search prelude; when the intelligent body discovers multiple candidate targets during the exploration phase, the intelligent body actively reports the exploration results and asks the user for detailed instructions (e.g. "I found a package and two desserts, which one do you want?"); the intelligent body's inquiries from the previous exploration results further detail the user's feedback on the task objectives.
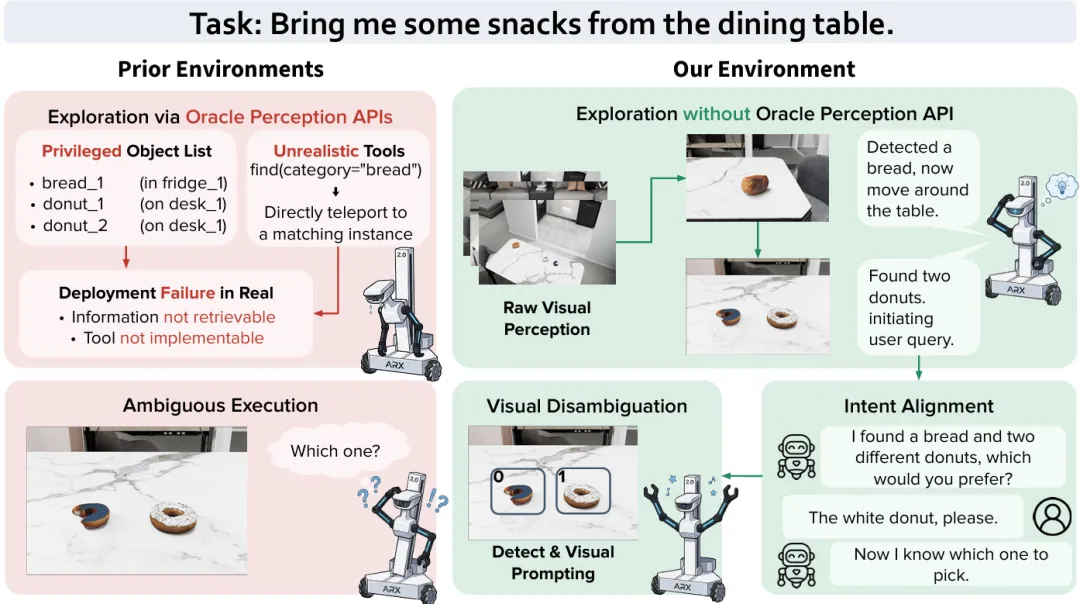
Figure 1. The contrast between the REAL working model and the existing execution model
Second, REAL:
Agentic architecture for an open world of mobile operations
Built on top of the InternUtopia simulation platform, using its high-fidelity rendering capabilities, rich interactive simulation scenarios and assets, REAL designed a data collection, training and evaluation pipeline for mobile operators, ultimately forming an Agentic framework for open world mobile operations. The top layer architecture of the framework consists of three core components:
Brain: Intelligent bodies use Qwen3-VL-8B-Instruct as a basic visual language model. The brain is responsible for processing multimodal observational information, maintaining structured historical abstracts, and performing high-level task planning and tool calls.
Tools and Interfaces: REAL Environment provides a set of standardized tool chains that do not rely on privileged perceptual information, mainly including: four-step exploration tools for actively obtaining environmental information
Nav_to、Walk_around、Show_object_by_category、Gaze_atThe control interface used to execute underlying physicsPick、Place、Open、CloseIt is also used as a tool for identifying discrimination and asking questions.AskIn order to implement the effective organization of tools, the framework introduced the Model Context Protocol (MCP) as a unified interface standard. The high-level brain only needs to output discrete tool calls, which are sent down and executed through the MCP server, thus achieving the breakdown of cognitive planning and underlying execution.
Status and memory: The REAL environment organizes the return results of MCP tools into structured multimodal information as perceptual information for the intelligent body, including visual partitioning masks and corresponding object categories, original RGB observations, user feedback, and autonomously summarized mission sub-goals and historical status for the intelligent body. This design also helps the intelligent body to make decisions always around the original mission goal while maintaining effective observation information.
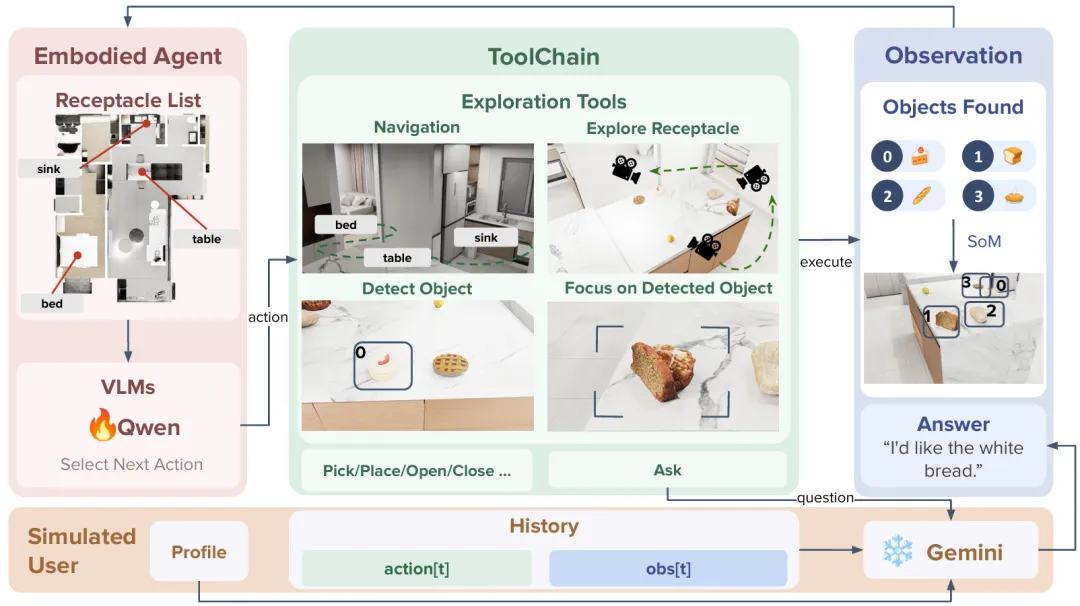
Figure 2. REAL framework design
Based on this top-level architecture, REAL has made three core contributions at the environmental, data and deployment levels:
The following is a summary of the results of the survey:Simulators remove privileged perceptual interfaces that directly target targets, requiring intelligent agents to rely on tool chains to explore freely in scene nodes. At the same time, the environment has introduced simulation.UsersIntelligent entities can make dynamic inquiries and coordinate intentions in execution.
Automated data generation and two-phase training pipeline: REAL, based on a scenario-asset automated combination of tasks, generates executable expert trajectories through rules planners, and uses the Gemini 3 Pro model to supplement the trajectory with progressive reasoning and structured historical status. On this basis, the team uses the basics of monitoring micro-training to train the intelligence body's ability to call, and further train its closed-loop discovery, error recovery and proactive inquiry skills through online reinforcement learning.
Simulation to real-world deployment under a unified interface: The team built a REAL-Bench containing 241 mission instances to verify real-world performance. Thanks to the MCP protocol, the same high-level strategy allows zero-sample migration to real-arms mobile robots, verifying the deployability of the framework.
Three, technological achievements:
Actively exploring, communicating and solving problems at high and low levels
Actively exploring and interacting with disadvantaged perception
In the REAL framework, the intelligent body only receives accessible structural prefixes, i.e. the ID and semantic categories of the area or scene nodes (such as desktops, cabinets).Four steps to exploring tool chains(navigation, multi-point scanning, target detection, coordinated observation) to actively obtain visual information. The system will split detected 2D masks into 3D space to construct temporary exploration maps and assign visual IDs to objects through SoM (Set-of-Mark). Subsequent capture and placement operations are all based on visual ID calls, allowing the robot to complete the task.Visual target positioning and divergenceAt the same time, REAL accesses a simulation user driven by a large model that can respond based on the object and task configuration currently discovered, making active communication the execution link directly triggered by the results of the exploration.
High-low-level decryption execution based on MCP protocol
Thanks to the introduction of the MCP protocol, the "brain" model can always focus on task planning and state tracking, and output a unified format of discrete tool calls.The simulated environment and the real environment are abstracted as consistent interaction spaces through unified tool interfacesWhen the system migrates to real-machine deployments, the underlying continuous physical control is taken over by specialized physical skills such as the $\pi_{0.5}$ model. This high-low-level puzzle design allows high-level strategies to migrate zero samples directly to real physical robots without completely retraining them.
SFT and GSPO: Tools aligned first, learn closed-loop decision-making
Intelligences use Qwen3-VL-8B-Instruct as a baseline model to accommodate multi-modal capabilities and the robotic side of reasoning efficiency. For the above-contextual expansion problems that are easy to encounter in long-range tasks, the system models the decision-making process into parts that can be observed in Markov's decision-making process, and uses structured auto-abstract historical states to avoid the complete interaction trajectory being rewritten at each step. The entire training pipeline is divided into two core phases:
Supervise fine tuning (SFT) to achieve tool alignment: At this stage, the system uses a rule planner to generate expert trajectories and transcribe some clear instructions into blurry instructions through automated markup modules while injecting them into the trajectory.
AskCalling and simulation of user responses. This allows the model to initially master the basic call paradigm of exploration, operation, and communication tools.Online Reinforcement Learning (Online RL) Improves adaptability: In order to avoid trajectory simulations of models trapped in a dead board, REAL introduces closed-loop reinforcement training in Group Sequence Policy Optimization (GSPO). Compared to GRPO, GSPO will raise the importance ratio with cuts from token level to sequence level to better match sequence level rewards and enhance the stability of trajectory reinforcement learning.
Through this two-stage training pipeline, the training strategy will be based on real feedback from the environment, independently deciding when to continue exploring, when to redesign, and when to confirm to users.
Four, the REAL-Bench:
Assessment of design and experimental results
REAL-Bench included.241 mission examplesThey are divided into four mission families:
Furniture-Distractor Pick-and-Place, FDP)(72): Complete cross-container displacement in a similar furniture disruption scenario, explore the active exploration and basic operation of the closed loop;
Furniture & Object-Distractor Pick-and-Place, FODP)(56): At the same time, including furniture- and object-level interference, exploring the positioning and distortion of fine-grained vision in open vocabulary scenarios;
Furniture-Distractor Open/Close, FDO)(48): Completion of operations around convertible furniture, consideration of object operations and timing consistency under dynamic visual changes;
Simulator-User-Loop, SUL) is a simulated user loop control.(65): By deliberately setting ambiguous instructions, we examine whether intelligent agents can actively call.
AskThe goal of the project is to achieve a consistent goal based on user feedback.
The four categories of missions together cover the entire execution process of "exploring the positioning of the antenna and the operation of the antenna communication", and from different angles test the ability of the intelligent body to respond to visual interference, perceptual dynamics, interactive decision-making and active exploration.
Experimental results: SFT learns to "use tools" and RL learns to "interact autonomously".
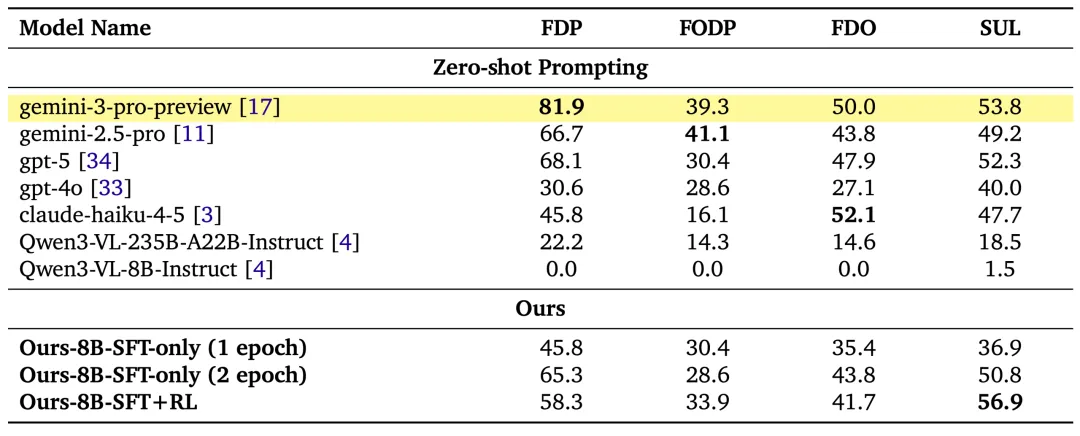
Tool alignment is a prerequisite for the formation of a closed loop of perceptual fluid motion. The untrained Qwen3-VL-8B has a success rate of 0 on FDP, FODP and FDO, and only 1.5% on SUL; after one epoch of SFT, the FDP success rate has risen to 45.8%.[3]
Simply increasing simulation learning can damage open-scenes generalization. When SFT increases from 1 epoch to 2 epochs, the FDP increases from 45.8% to 65.3%, but the stronger disruptive FODP decreases from 30.4% to 28.6%, indicating that rigorous simulation trajectories may cause over-adaptation.
Online RL helps restore adaptive exploration capabilities. Following GSPO training as a starting point for 1-epoch SFT models, the FODP success rate increased to 33.9%, indicating that environmental feedback can drive dynamic adjustment of the model rather than just replaying the training trajectory.
The most noticeable improvement in online RL on interactive missions was REAL-8B on SUL.56.9%Overall, the VLM baseline of zero-sample comparisons has surpassed the Gemini-3-Pro-Preview (53.8%) and GPT-5 (52.3%) as a teacher model. This suggests that RL has a greater success rate for tasks that require proactive interaction.
5 Real-time deployment: 60 real-world tests
Episodes 78.3% end-to-end success rate
In order to validate the sim-to-real capabilities, the team will migrate the trained high-level strategy to zero samples.ARX LIFT2 mobile robot with two arms:
High-level VLM connects the physical rear end directly via a unified MCP tool interface without re-training;
The underlying operations are taken over by dedicated modules, with the $\pi_{0.5}$ being modulated to be responsible for the underlying physical operations of opening, joining, crawling, placing, etc. This requires the agent to focus solely on visual grounding, state tracking, and higher-level task planning.
It's not.60 real-world test episodesIn the middle, the system achievesEnd-to-end success rate of 78.3%The overall executability rate for 600 VLAs in the original language is approximately the same as the total executability of 600 VLAs.85.3%。
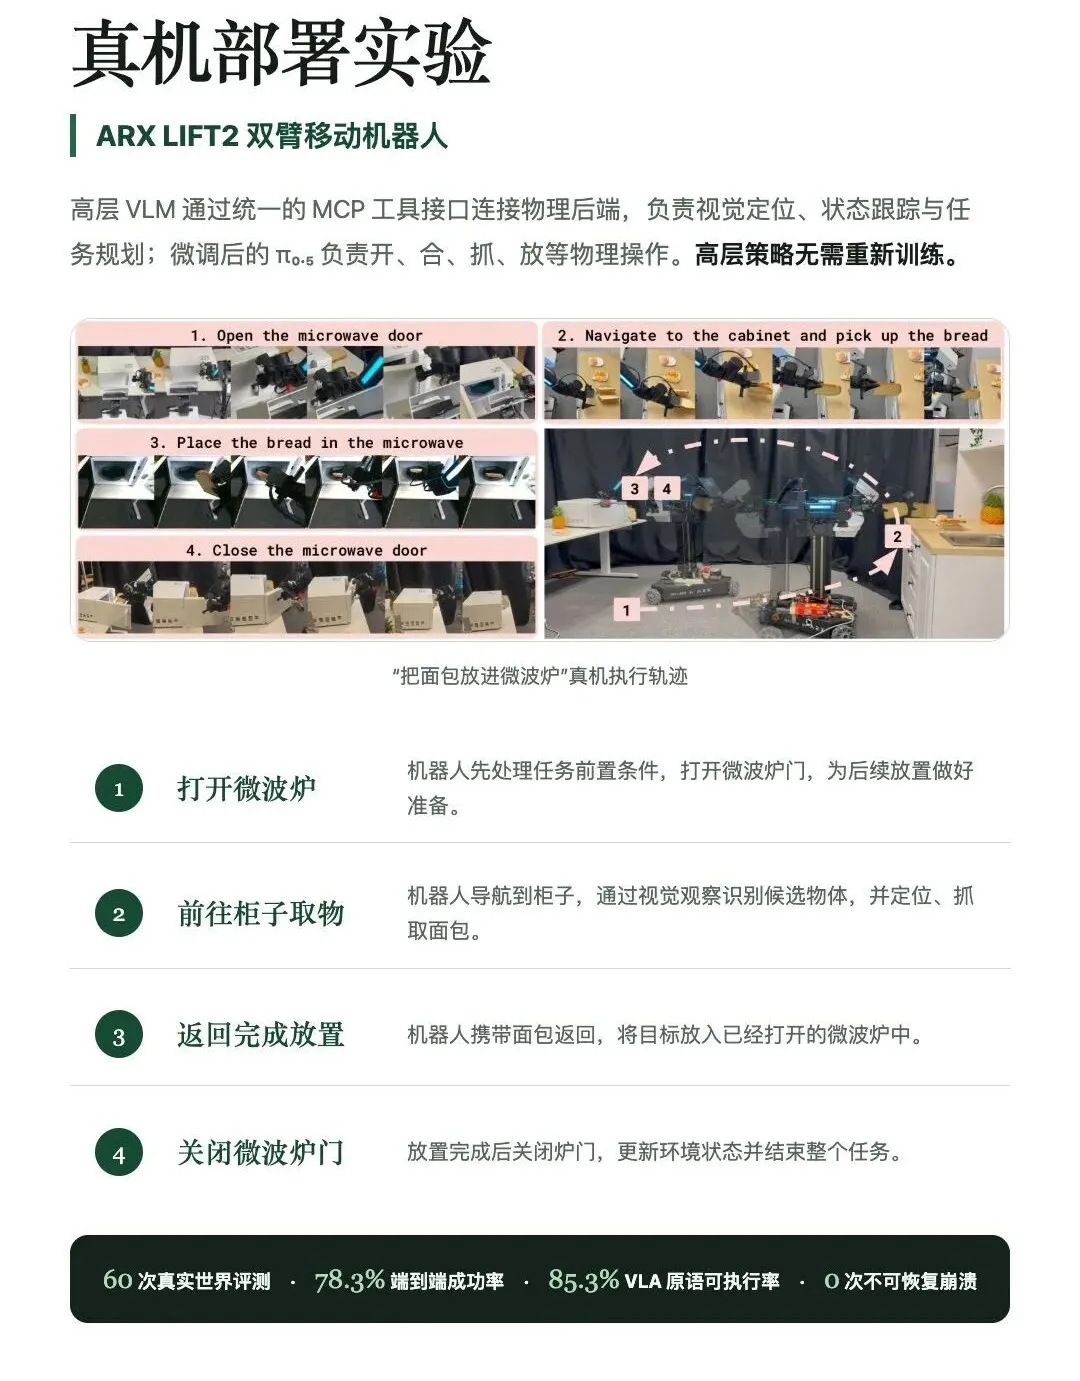
Figure 4. Deployment in real missions confirms the effectiveness of REAL
This execution sequence demonstrates the system's understanding of the relationship between mission preconditions and operational dependence. At the same time, REAL keeps track of and updates current mission progress through structured historical status records and updates, keeping the progress relevant only to subsequent decisions, and reviewing documented information through tool feedback rather than the complete historical trajectory, thus avoiding the rapid growth of the context and reducing the accumulation of neglect and errors in execution status.
Six, to sum up.
At the heart of REAL is the redesign of the information boundary between simulation training and real deployment, so that a physically intelligent body no longer relies on the two traditional idealized assumptions that are unattainable in reality - the "perfect perception" and the assumption that users can always give clear, complete instructions - and moves towards more realistic deployment conditions: the intelligent body must actively access environmental evidence through visual exploration, complete the user's intentions when necessary through communication, and ultimately call upon deployable physical skills to complete tasks.
On this basis, REAL uses a unified MCP tool interface to deeply blend high-level visual reasoning with specific physical execution backgrounds, enabling the same set of high-level strategies to migrate from simulated environment zero samples to real-arm mobile robots. REAL-Bench, in line with real-world experiments, suggests that model learning encourages enduring closed-loop decision-making under "unseen, unseen, unenforced execution-failure conditions, and provides an efficient pathway from limited intelligence to the real world".