The world model is taking a pivotal turn.
From Genie, Sora to WorldLabs, they have pushed the model of the visual world to a height. But under their appearance, they are still statistical visual simulators.
New leaps are taking place. In recent years, the trajectory of the physical world model has been steadily heating up, attracting the attention of global AI giants. The essence of the physical world model is that it aligns directly with the rules and constraints of the physical world, transforming the ability to generate video into the ability to control movement. For example, how a ball is thrown out, whether a robot arm lifts a cup and how much force is required to extract the liquid when grabbing live eggs.
The world's biggest AI companies have taken the lead. Google, Intel, Tesla, or a simulation training platform, or a self-developed robot-based model, are attempting to lead the way in this technological height. Chinese players are also reluctant to weaken in this race.
Today, Intel's Future (HiDream.ai) officially released the body world model HiDream-O1-Embodied. Adhering to the original full-mode technology concept, the model strengthens robotic physical perception and dynamic predictability, enabling body intelligence to achieve higher levels of physical interaction.
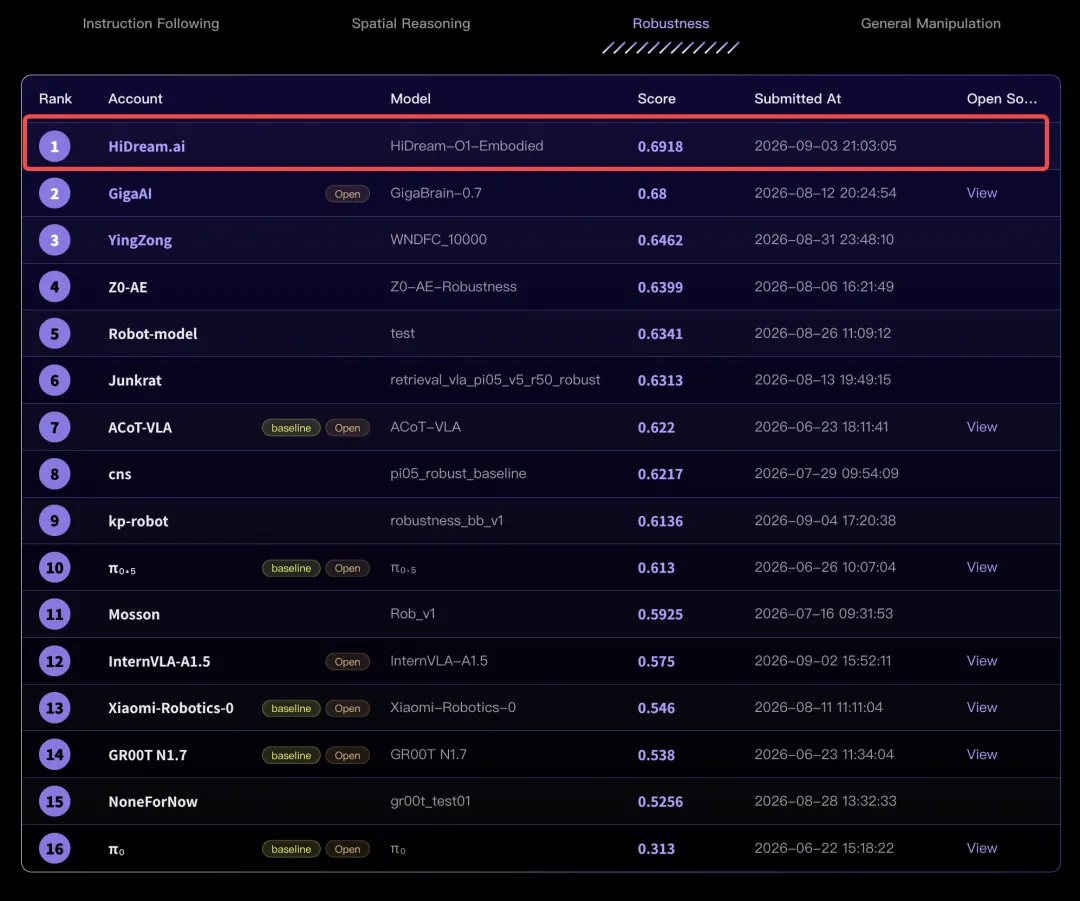
For the first time, HiDream-O1-Embodied, the body-smart model rating platform RoboColiseum, which was released in the same year, topped the list with an average score of 0.692 on the core Robustness (disruptive adaptation) sub-list.
The future CTO of Intel said: "We believe that around real-world expression, understanding and generation, building simultaneously with full-mode expression, causation and the physical world to construct the three core capabilities to establish a complete model base of the world". Intel's native all-mode world model technology concept, from the beginning of the design architecture plans towards the construction of a unified representation including all-mode including action. HiDream-O1-Embodied's release is a key milestone in this technology strategy from the simulated world to the real world.
Rising to the top of the RoboColiseum: Handing out the first hard-core answer book to the list of adapting monkeys to disruption
RoboColiseum is a multi-dimensional system evaluation system designed to help developers identify the advantages and shortcuts of models and continuously upgrade their capabilities. The platform is open to universities, research institutions, model enterprises and researchers around the world, and updates the results in real time.
The platform is based on high-fidelity simulation environments built and highly replicated in the real world. The platform introduces four-dimensional capability sub-lists, 78 high-fidelity simulation evaluation missions around the four dimensions, which include instruction tracking, spatial understanding, disruptive adaptation and general operations. Self-testing has attracted dozens of in-house and out-of-home weight-level models to conduct evaluations. In these four dimensions, disruptive adaptation (Robustness) is recognized as the most challenging component.
HiDream-O1-Embodied topped the list with a score of 0.692 points, thanks to its native full-mode base. The native full-mode world model naturally provides a foundation for cross-mode understanding and generation. While in the execution link to ensure stability in all kinds of real-world crashes, HiDream-O1-Embodied has made breakthrough innovations in three core capabilities that make understanding more accurate, sensing more robust, and resisting interference stronger.
The video shows the head view of the pick block shape clutch task. The robot needs to complete the clutch task by following instructions (e.g. clutching the trident column on the desktop with the right arm), and the task presents the model with three tests: first to accurately find the trident column from a pile of debris, then to calculate its three-dimensional position in real time, and finally to plan a steady clutch trajectory. The test also intentionally adds interference to the position of the shadow, shadows and distortion of the texture. From the image, it can be seen that in most cases, the HiDream-O1-Embodied is able to accomplish the clutch identification of the position of the clutch, sensing precision, and sufficiently robust operation.
Language comprehension: breaking the boundaries of keyword matching
Traditional robots' understanding of language instruction is often confined to the keyword matching level. It is possible for a robot to take a cup with a mouse to understand, in exchange for a mouse to give me a cup with a mouse or a mouse to give me a cup with a mouse. HiDream-O1-Embodied covers an equivalent instruction space with multiple verbs, sentences and expressions, not bound by sentences, but only locking the intent itself. Regardless of how the instruction changes, it can penetrate literally, directly to the user's intent.
Visual perception, multi-faceted collaboration, avoiding a single failure, and overall failure.
In the physical world, a robot's visual path is not ideal. The camera's position may deviate, and the identification accuracy may change over time, and single-track images may be obscured or interfered with. HiDream-O1-Embodied combines information from multiple viewpoints, so that different visual paths complement each other, rather than relying on a fixed viewpoint. When some visual information is distorted or temporarily unavailable, the model can still use other viewpoints to understand the scene, judge the task and continue to execute, allowing the system to run from a faulty, holistic failure, to be transformed into a biased, and the whole can still run.
High-capacity error mechanism in a vacuum in imperfect vacuum
Most models are trained using perfect data sets, clear images, complete images, and standard viewpoints. But this is never the case in the real world.
HiDream-O1-Embodied actively introduces a variety of non-ideal conditions during the training phase, enabling the model to repeatedly face incomplete, unstable information and learn to make reliable judgments from limited clues. This training allows the model to not only pursue the best performance under ideal conditions, but also to place greater emphasis on continuous stability in complex environments. This tolerance is not limited to some kind of visual abnormality. In the face of lighting, appearance and scene changes, the model can more flexibly exploit the impact of the environment, reducing the impact of changes on task execution.
Models + data: building real silicon base + producing enhanced silicon data production paradigm
It touches on a more fundamental proposition: the model's cognitive boundaries, influenced by the data it touches on. High-quality data, precisely the rarest and most decisive variable in physical training. Intellectual-powered silicon models + data silicon dual-drive strategies, are the true fortresses of the world model list of silicon models.
A key breakthrough in the strategy was to make data production itself an organic part of the model evolution. For this reason, Intel explored a paradigm of data production that generates real bases + reinforced data. Models are no longer passive reception of data, but the creation of active participation in data.
As an example of its collaboration with Nohimichi: its high-precision real-world action data capture as the real-world underpinnings, Intel uses its original full-mode capability to complete a hundred-fold level of data refinement and expansion. Based on single-section real-mode action samples, the model can generate variable video: changing the background environment, lighting conditions, object shapes, etc., on the premise of strictly adhering to physical constraints, producing mass-multiple training samples.
The key to this mechanism is that the model can be both a test subject and a test subject. It actively generates targeted training samples based on its own needs, forming a growth flywheel that drives data and models together. Ultimately, the HiDream-O1-Embodied exhibits extraordinary robustness in the face of real-world disruption.
Original full-mode world model matrix sunscreen perfected
Less than a month ago, Intel released the interactive world model HiDream-O1-World, which topped the Navi ranking of the interactive video world model benchmark WBench with an average score of 80.9.
The interactive world model solves puzzles by understanding and suggesting puzzles, allowing AI to have a complete understanding of space, time, movement and the relationship between objects in the digital world. While the physical world model solves puzzles by operating and executing puzzles, allowing AI to complete real tasks in the physical world. Both will form a powerful complement, laying the foundation for the development of the original full-mode world model.
As Intel's future founder and CEO, Dr. Maynard Maynard, has previously said, the key to the next generation of big model competition is not the growth of single-mode capabilities, but moving from single-mode to multi-mode to native unified full-mode. From HiDream-O1-Image to HiDream-O1-World to HiDream-O1-Embodied, Intel as an innovative big-mode enterprise is steadily forming a model family matrix that covers visual models, interactive world models and embodied world models.
The core of artificial intelligence in the physical world is to allow AI to truly step into the real world, acquire the ability to continuously learn and adapt in uncertain physical environments. From the introduction of symbols, to the explosion of big models in the data world, to the physical paradigm of physical interaction, general artificial intelligence is completing a key evolution from virtual to reality. AI is no longer just staying in the mirror of the world, but is moving to action in the vibrant world, growing in interaction.