It's the first time in the history of the world.
OpenAI has issued a military warrant, 28 days of daily assignment, with a quota to compensate for failure to deliver.
It sounds like a welfare deal, but it's a rush.
Just now, the head of the Codex, Tibo, had a post on X that exploded:
For the next 28 days, each day will either deliver one improvement that is obviously useful to most Codex and Work users, or make a complete quota reset.
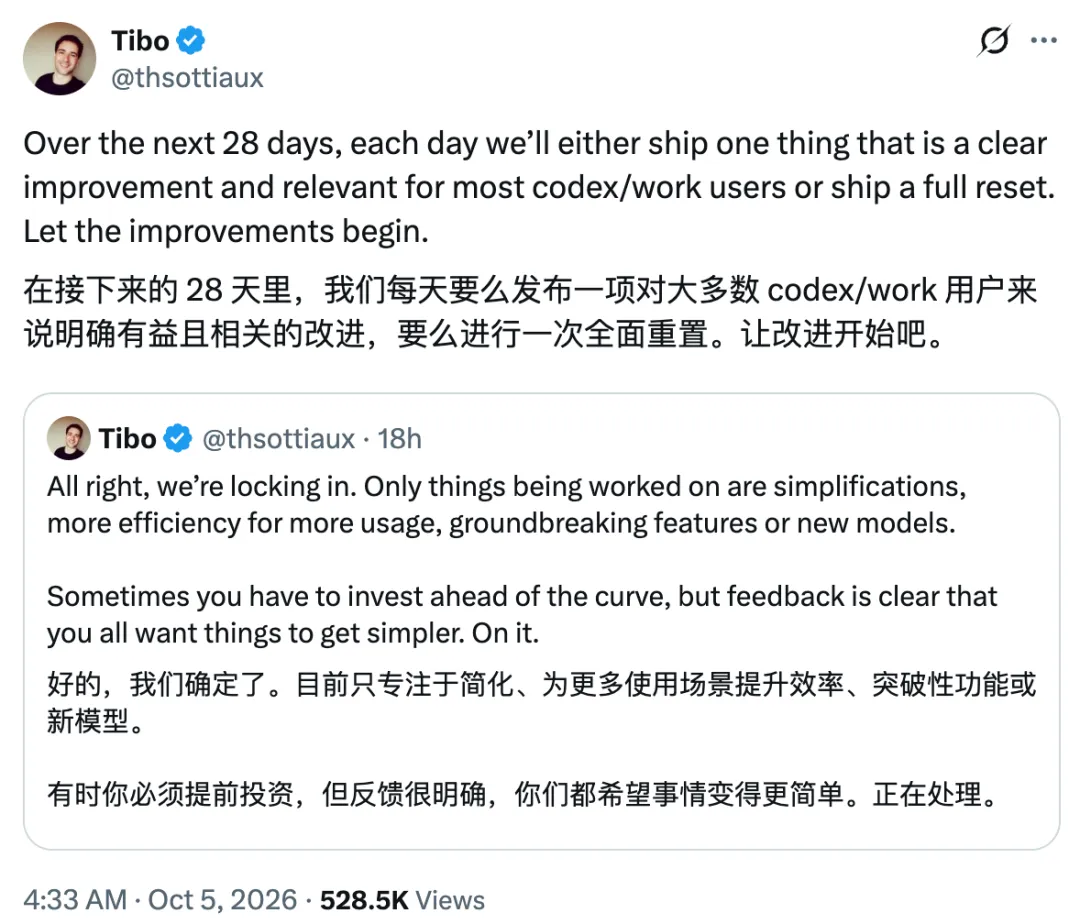
In other words, to give up work, users enjoy improvement; not to give up, you get a free round of quotas.
Just ten hours before the military order was issued, Tibo sent a definitive message.
He said that the team would take care of themselves and then do only four things:Simplify products, increase efficiency for more use, breakthrough features, new models.
At the same time, he admitted: "User feedback is clear and everyone wants things to be simpler".
What's even more interesting is that the post smells like fireworks before and after the post.
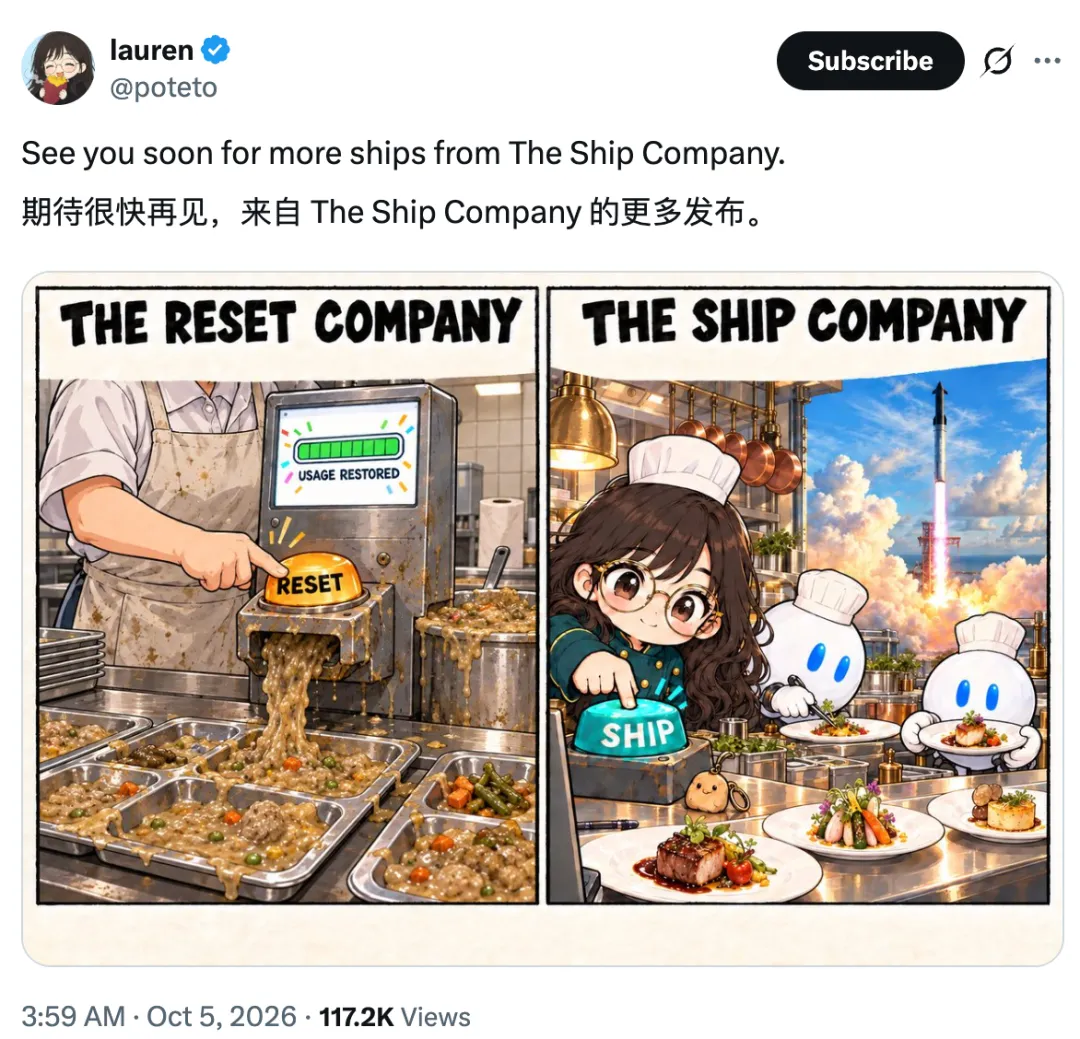
Shortly after Tibo issued the warrant, Lauren Tan of the Groc Bot team tweeted: "I look forward to seeing more releases from The Ship Company soon".
Grok was busy with his new job, so he put the salt on his face.
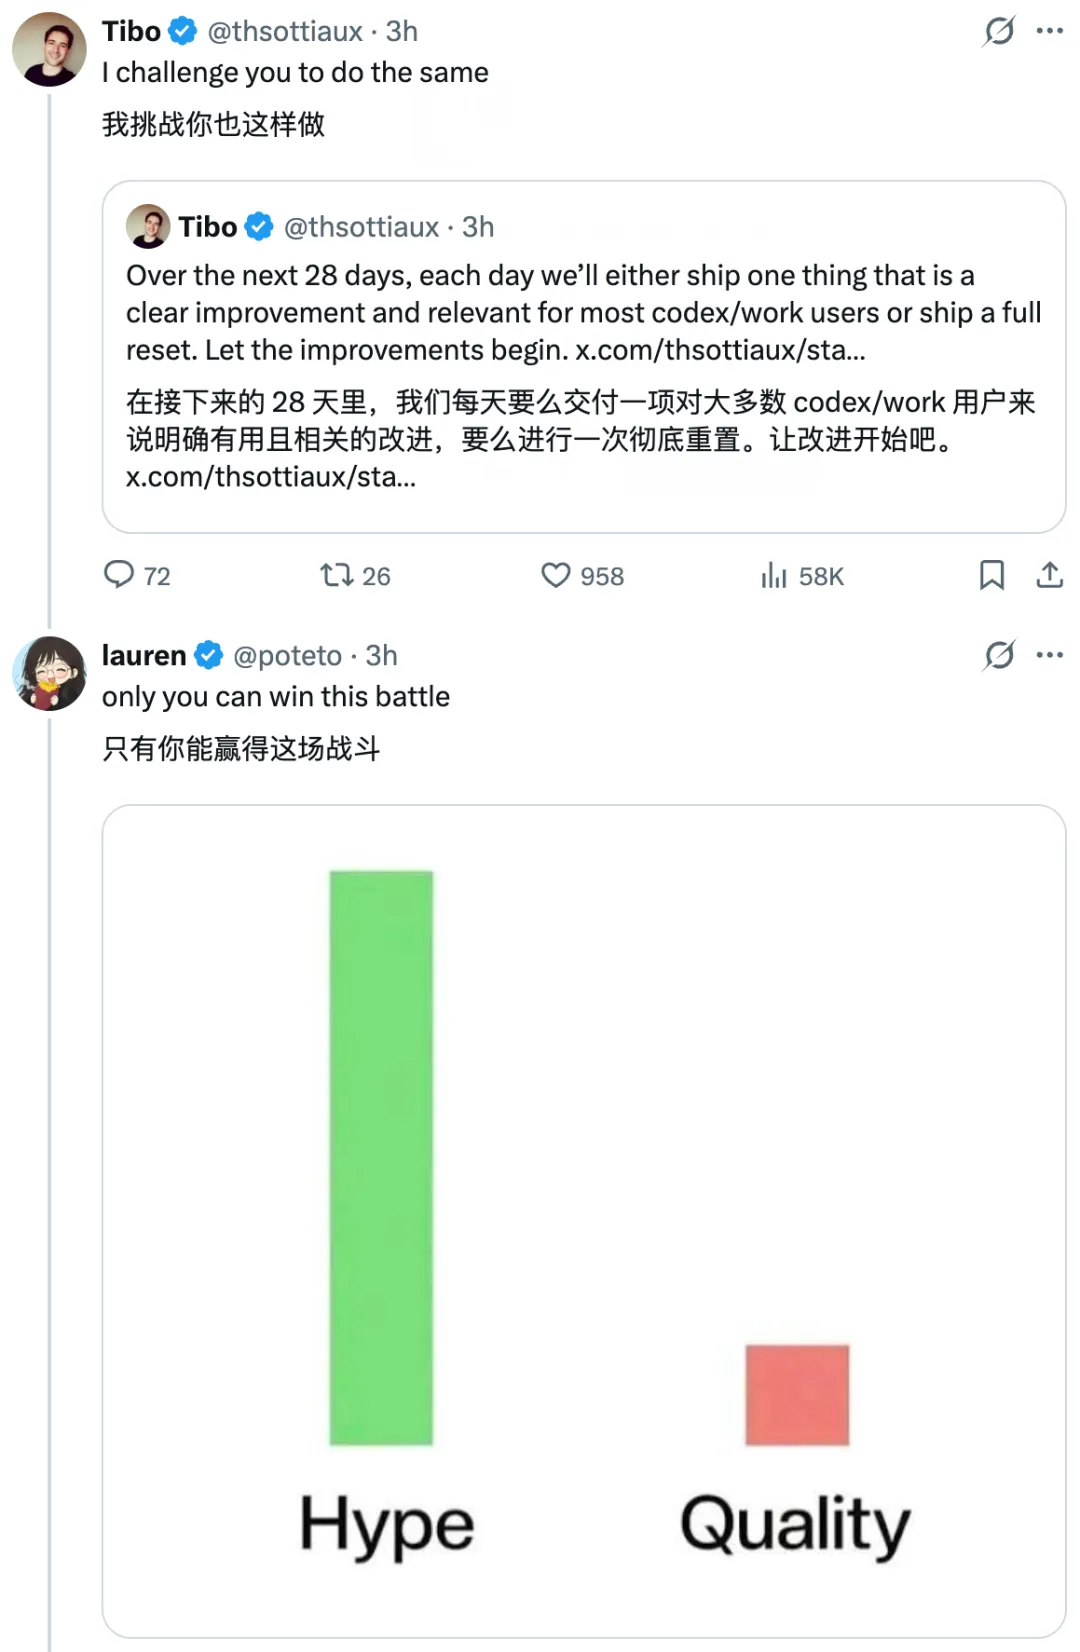
Tibo didn't. He quoted his 28-day commitment, turning to @Lauren and shouting, "I challenge you to do the same".
Lauren's response was one word:「only you can win this battle。」
Brethren, it is urgent.
He is also known for his distinctive outer rings:Put your brother back.He is also called the "Righteous Father".
In the last few months, the Codex has been reinstated nine times out of ten, as announced in his posts.
So this 28-day commitment has nothing to worry about. What if we don't make improvements?
Put it another way, he's the best.
Where did you spend your quota?Why are users so sensitive to quotas? Because the codex's quota problem is already "I don't know where to spend".
In extreme cases, a flying mission can eat up to 70% of your weekly allowance.
At the beginning of October, the problem came up again. After DevDay released GPT-6.1 Sol on September 29, the service end load was too high and the speed plummeted.
On October 2, Tibo apologized and announced that all paid ChatGPT accounts would be fully restored the next day.
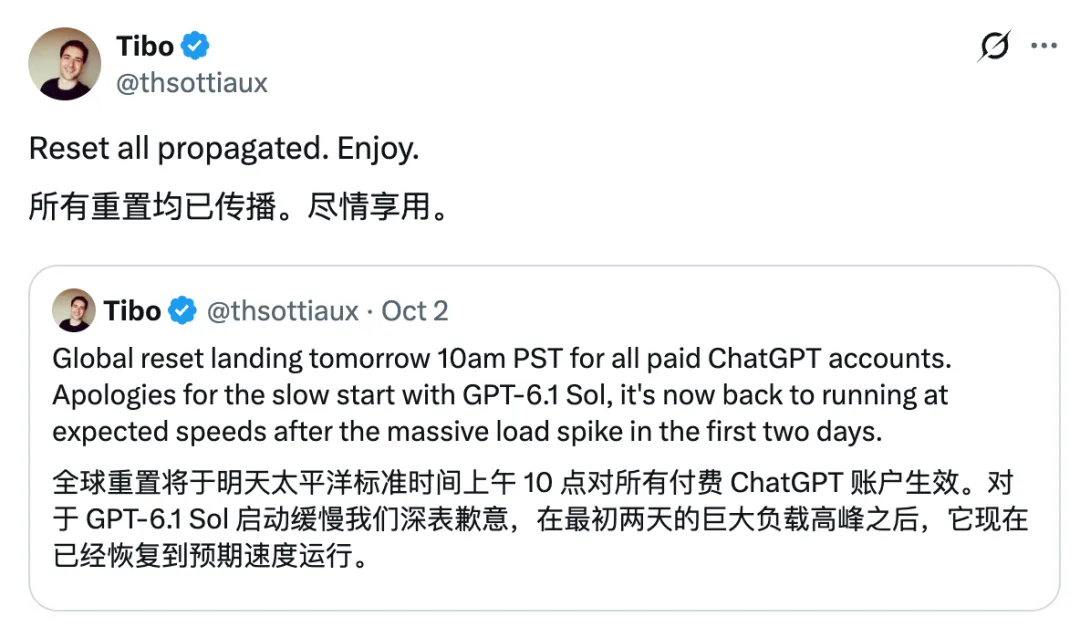
All of this together, OpenAI has been filling a gap: users pay for money, always feel that it's not enough, and don't know where to spend it.
This cave is typical of the Agent era. You tap a line of requirements in the Codex, and the backdrop can start a whole flow-through model to write code to flow Tokens, read context to flow, maintain memory, generate summaries, and schedule Agent aggregate flowers.
If only your own products have Bugs, repair is done, so don't rush to the military order.
It's the neighborhood where OpenAI can't really sit.
On September 22, Anthropic's Opus 5.5 was released, and about 90 minutes later, OpenAI followed closely with GPT-6 Sol.
A week later, on DevDay, OpenAI launched the GPT-6.1 Sol, priced at one-fifth of the price of Astra, in an attempt to buy a city back from the sexual price tag.
But the feedback from users makes OpenAI a bit embarrassing.
Although the GPT-6.1 Sol narrowed the gap, Opus 5.5 maintained the ceiling under the maximum reasoning rating.
More disturbing to Codex users is the sensitivity: many people are dissatisfied with the $100 Pro a week; while those with Claude have said that the Opus 5.5 is more efficient and significantly more durable.
A smart and conservative opponent is sitting next door. Every day reminds your users: another try?
In Tibo's tweaked post, there was already a high-profile response: "I don't care about the functionality as long as a model can play Opus 5.5".
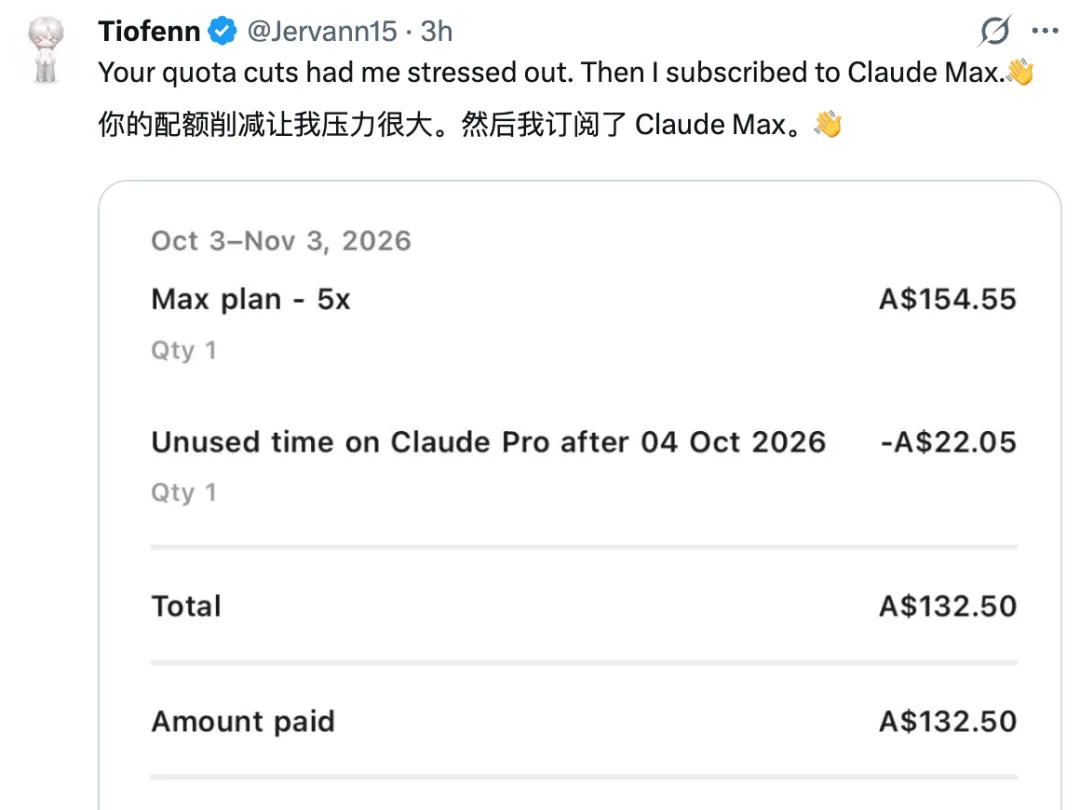
Lauren's catchphrase "only you can win this battle" isn't because she's so hard on her mouth.
Lauren delivered 2,500 PRs last month, and also did a 72-hour live-streaming challenge, starting a company with Grock Bot from scratch.
While Tibo was busy pressing the reset button, the two neighbors were talking about the product itself.
Networker Token Gremlin says the most straightforward of the 28 improvements is that it doesn't matter to users who care if one model doesn't actually play Opus 5.5.
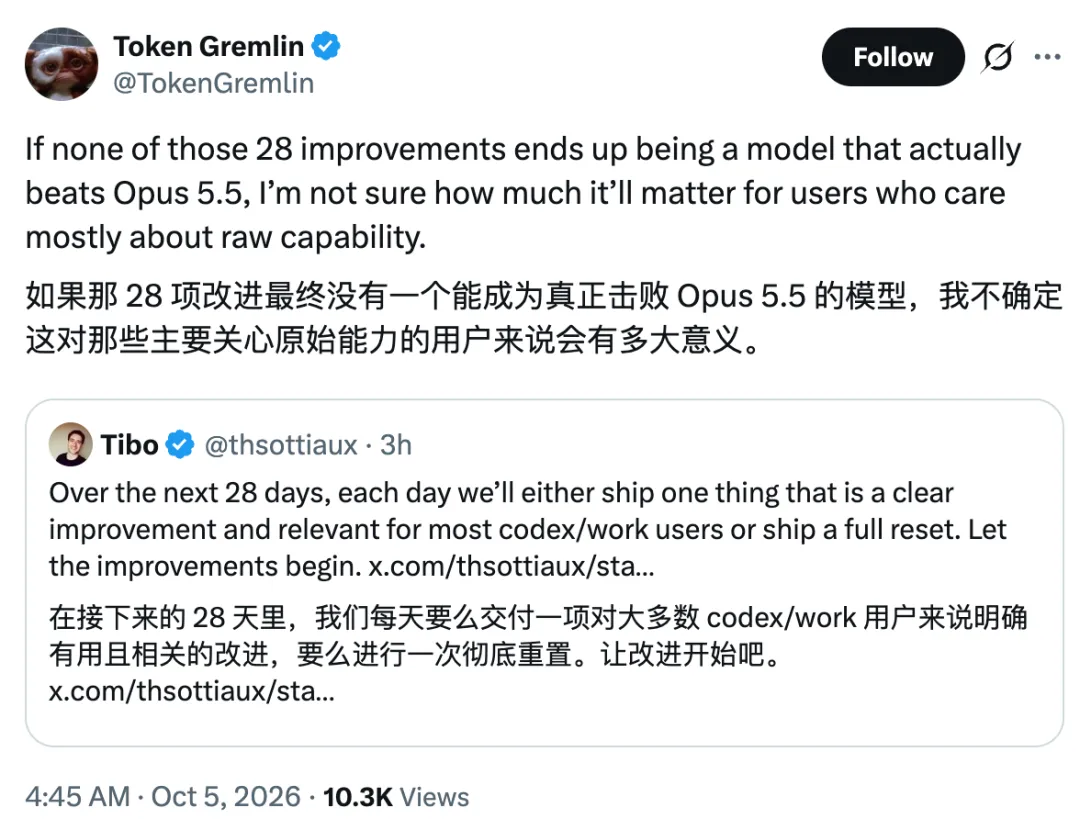
The Spitfires have already written a to-do list for Tibo.
Enlarging the button, changing the font, letting the user have a pet, changing the color of the Dots is of course an "improvement".
What will users remember after 28 days?What is "obviously helpful to most users" is not defined by Tibo.
What is the size of the button? What is the size of the panel? What are the grades that can be used to replace it?
For OpenAI, if there's an improvement, please come back and experience it, and if there's no improvement, you can continue using it. The worst result is that Tibo hits his most familiar button again.
However, the quantity can be sent repeatedly, and the liability on capacity must be reimbursed by the model.
After 28 days of preparing to switch to Claude's users, you'll probably come to the conclusion that it's a scam.OpenAI has come up with a model that deserves to be left behind.