It's the first time in the history of the world.
SpaceXAI has just released the all-new Grok 4.7!
The main selling point is one, the same price and speed, super-strong performance.
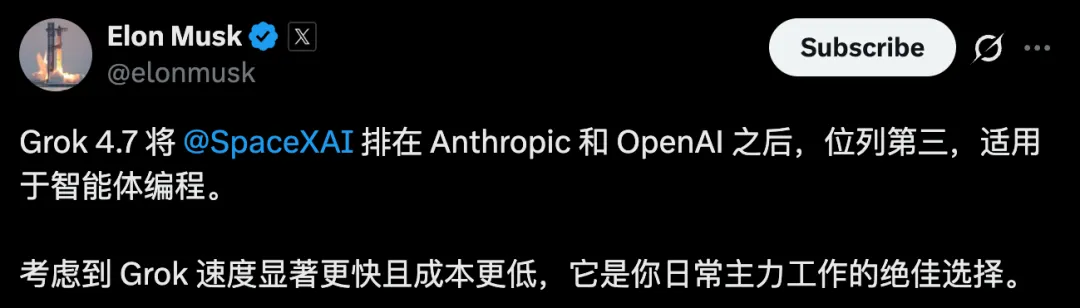
Musk shouted for the first time, "Grok 4.7 sends SpaceXAI to the third chair of intelligent programming, after Anthropic and OpenAI".
Fast and cheap, Grok 4.7 is the preferred choice for personal movers.
SpaceXAI's official ranking: the most powerful Grok in history, dedicated to programming and knowledge work.
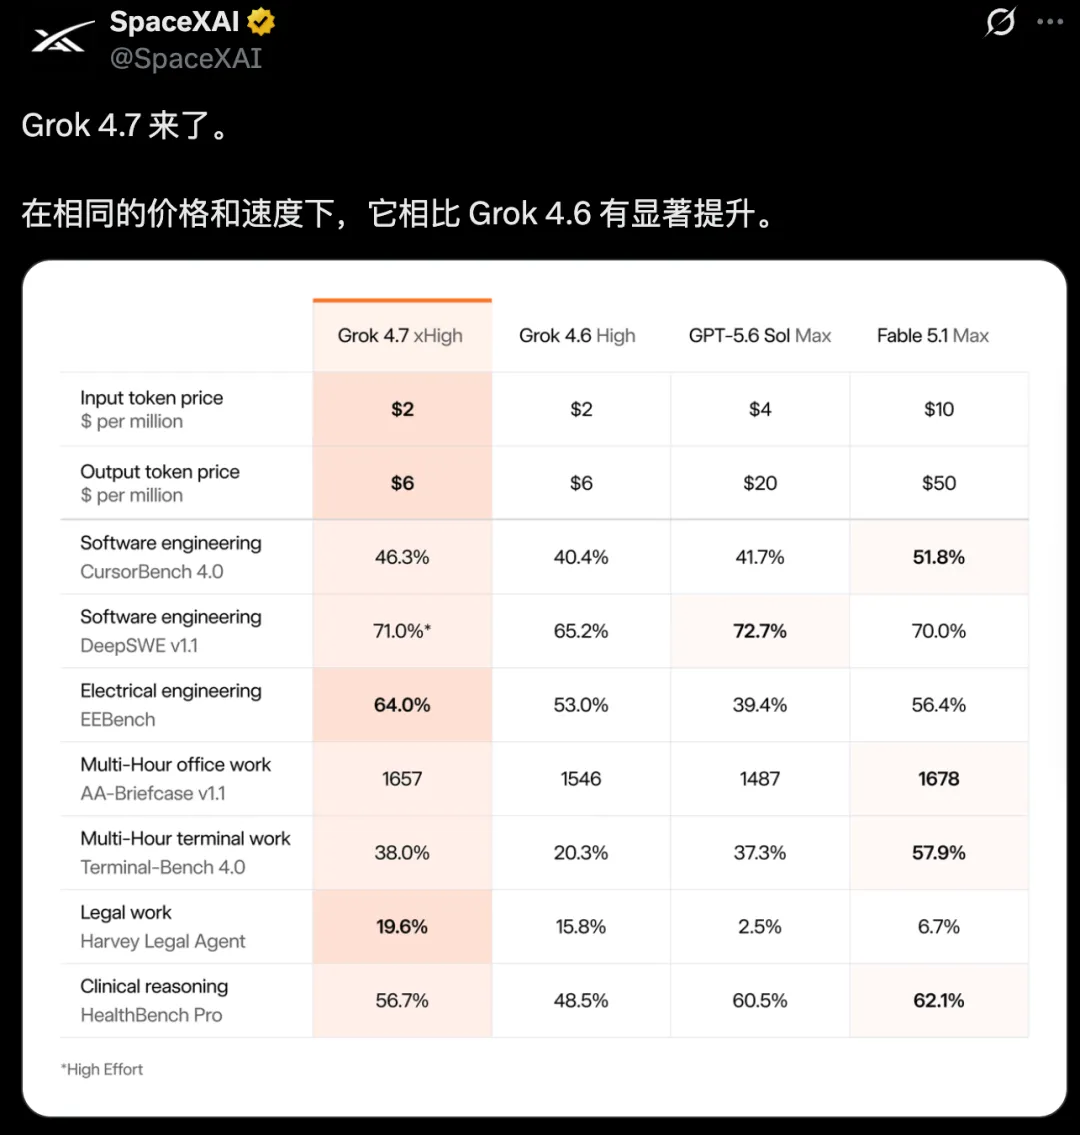
In terms of programming and knowledge work, Grok 4.7 has almost surpassed GPT-5.6 Sol Max, right behind Fable 5.1 Max.
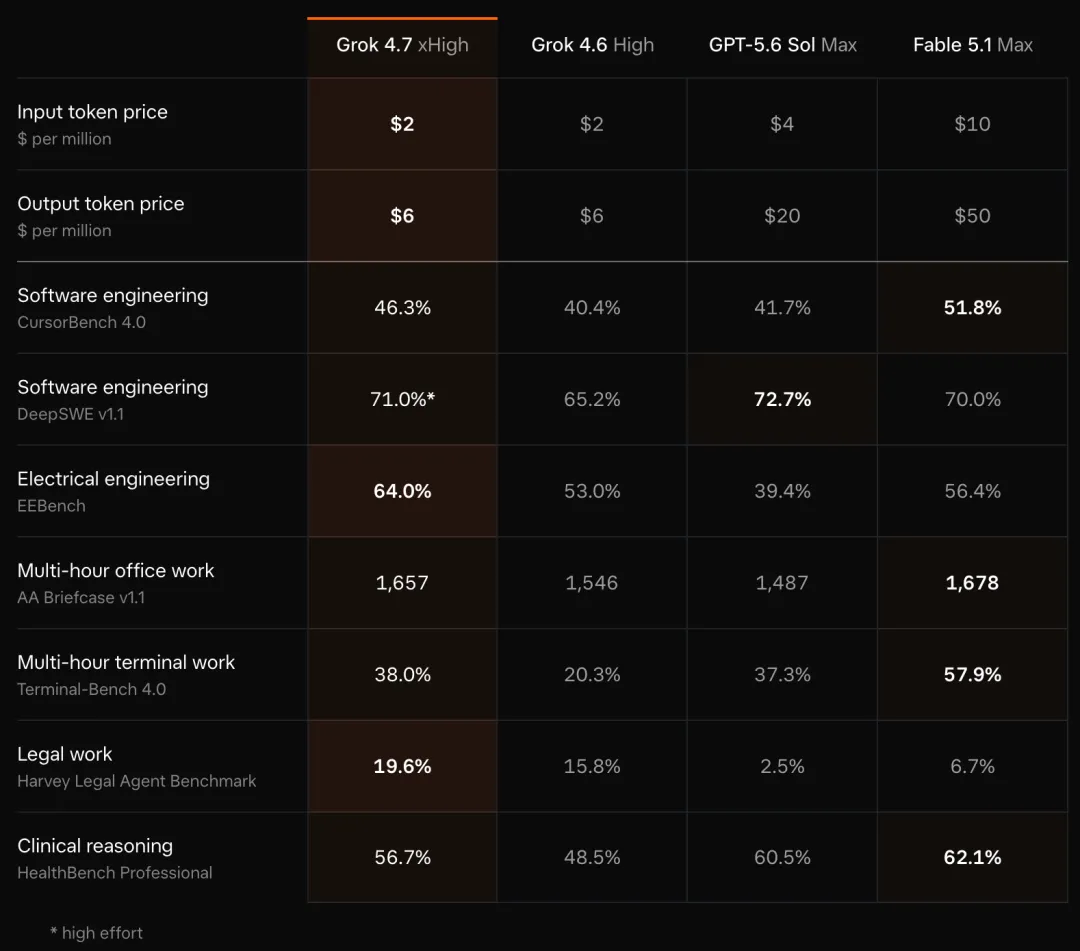
Input of $2 per million tokens, output of $6, is the same as Grok 4.6.
But the underlying model is completely changed, the base model is larger, reinforcement training is longer, and the difficulty of the task is overloaded with a tendency toward "work that takes hours to complete".
For Grok 4.7 and Grok 4.6 to play an open world city game, the gap is real.
 |  |
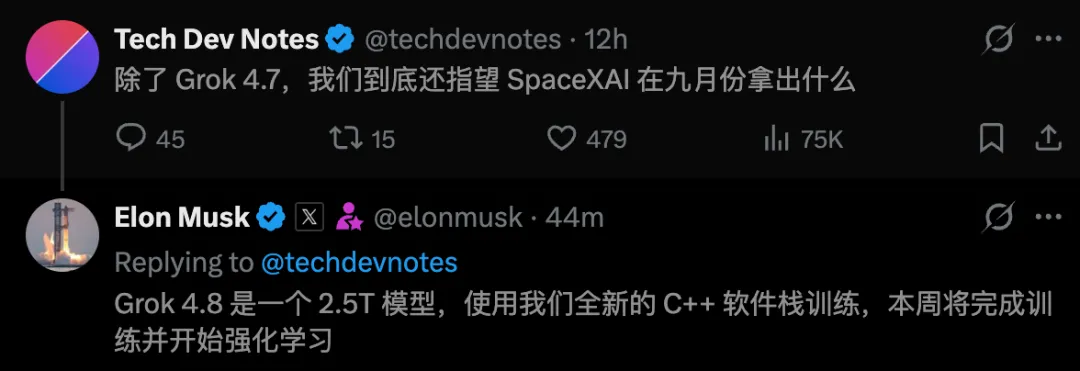
It is worth mentioning that the next generation 2.5T new model Grok 4.8 is also ready.
It's just the beginning of Musk's hands-on show.
Grok 4.7 launchesProgramming to follow the first ladder
The Grok 4.7 round of progress is more energized by programming tests.
It's interesting to break down the list of AAs.
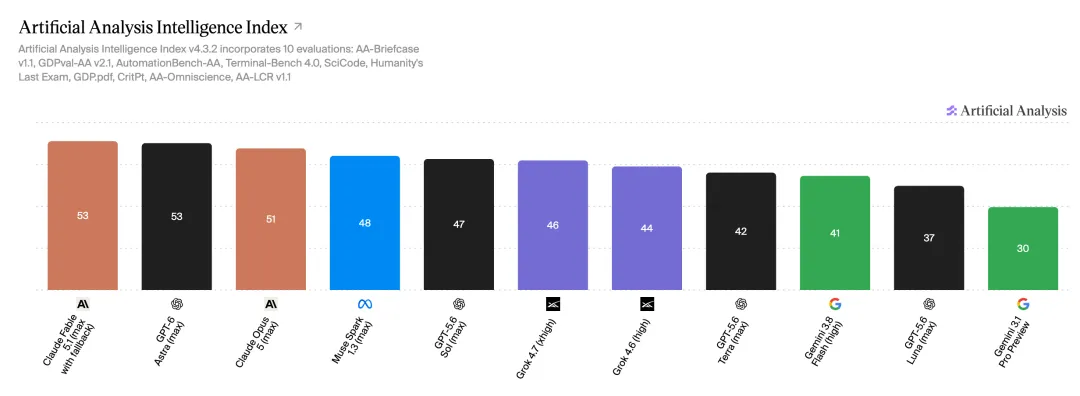
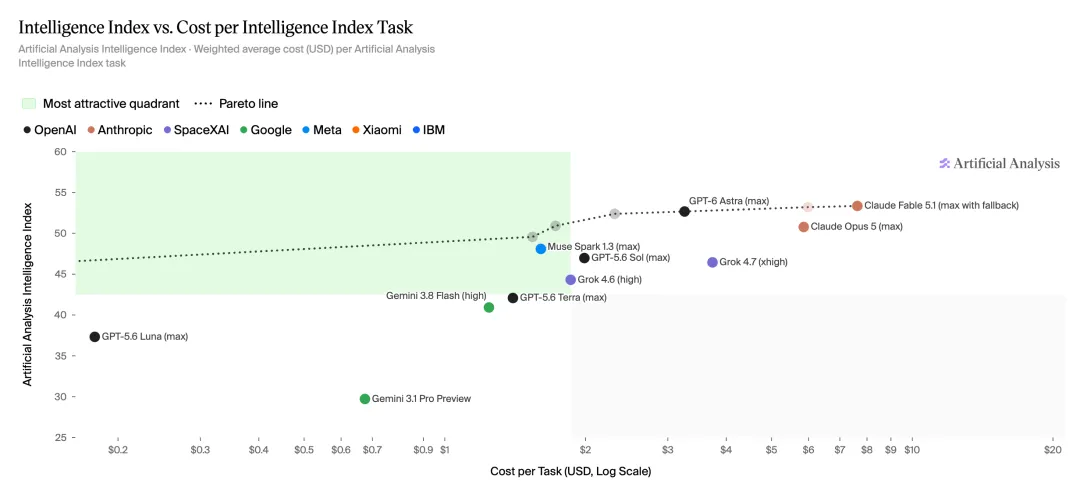
On the Comprehensive Intelligence Index, Grok 4.7 is down 46 points, down 2 points from 4.6, while Fable 5.1 and GPT-6 Astra in the first tier are 53 points overall.
It is ranked 16th in the classification; it is just shrunk to fourth in the laboratory rankings.
And the programming list that really made Musk blow up the sky is actually two.
1. Set in the GrockBuild framework, Grock 4.7 stands at 56 points, behind Fable 5.1, GPT-6 Astra and Opus 5. The "global third" in Musk's mouth, is stealthily merging the two Anthropic models into one.
2. After switching to the standardized benchmark Terminal-Bench 4.0, Grok 4.7's on-site pass rate plummeted to 26-27 percent. In contrast, GPT-6 Astra was 60 percent and Fable 5.1 was 55 percent.
However, at ValsAI, Grok 4.7 did not go up and down, falling straight from 14th to 24th place, down 5 points from the previous generation 4.6.
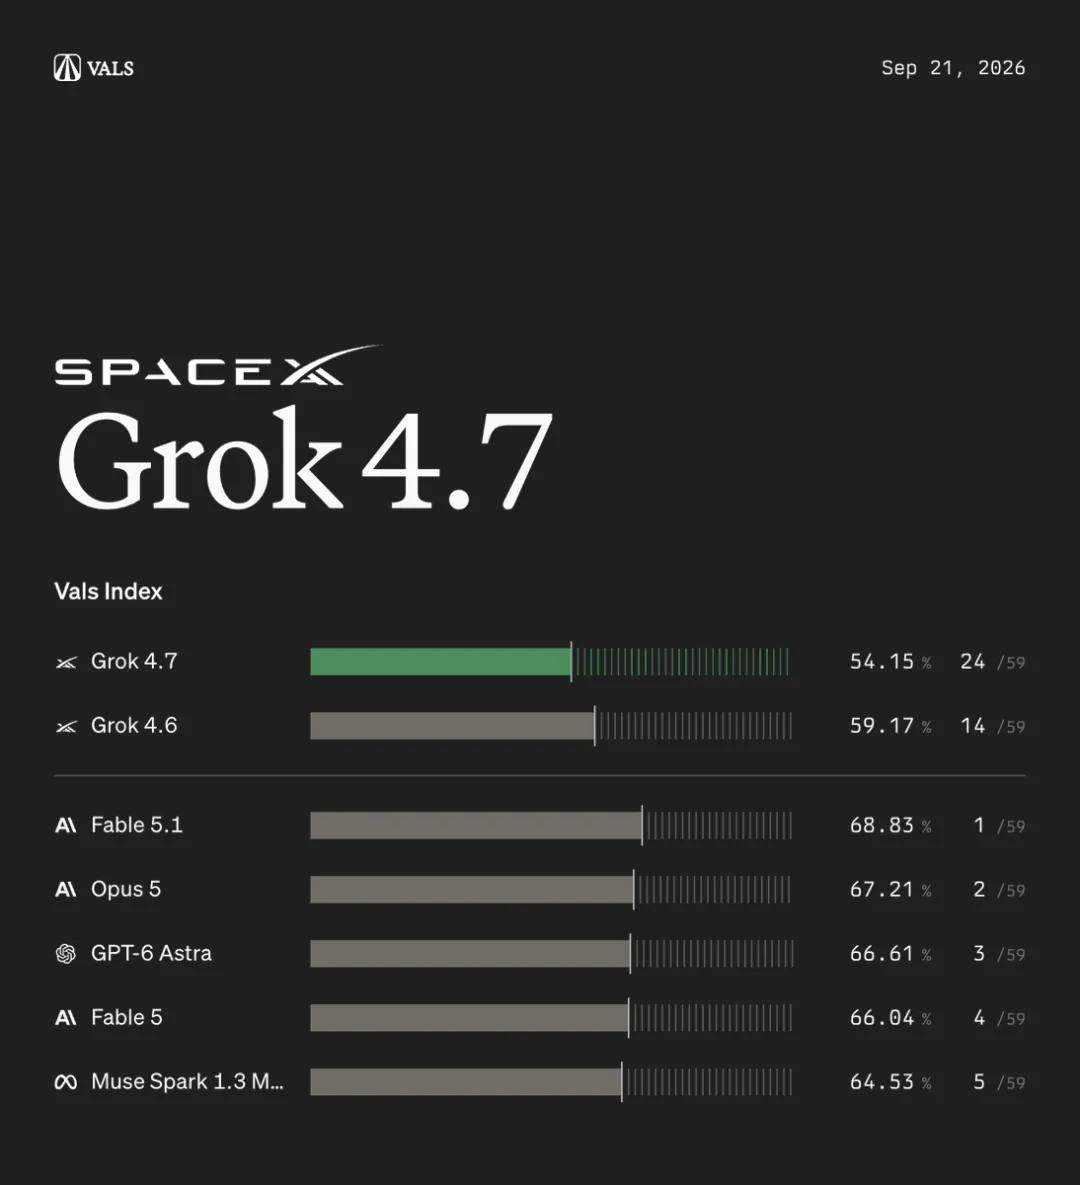
The answer lies in the appendix to the official announcement.
Grok 4.7 has deeply aligned the interaction patterns of the GrokBot framework during the pre-training phase.
In other words, it relies heavily on the call logic and task dismantling of its own tools. Once out of the greenhouse, the combat power instantly breaks down.
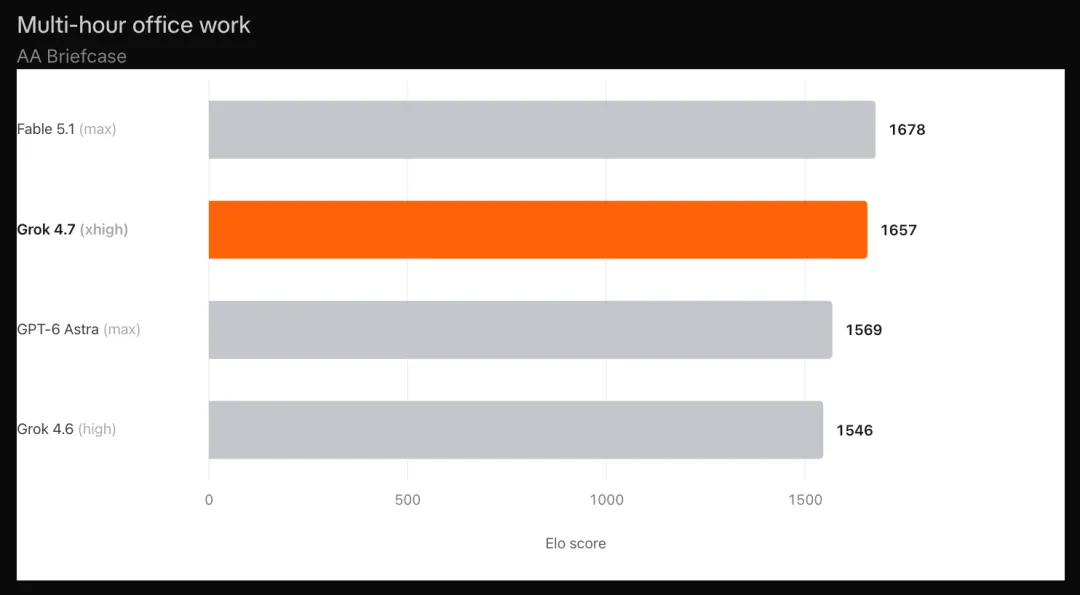
In the long process knowledge work test AA-Briefcase, Grok 4.7 received 1,657 Elo, an increase of 111 points from Grok 4.6's High grade.
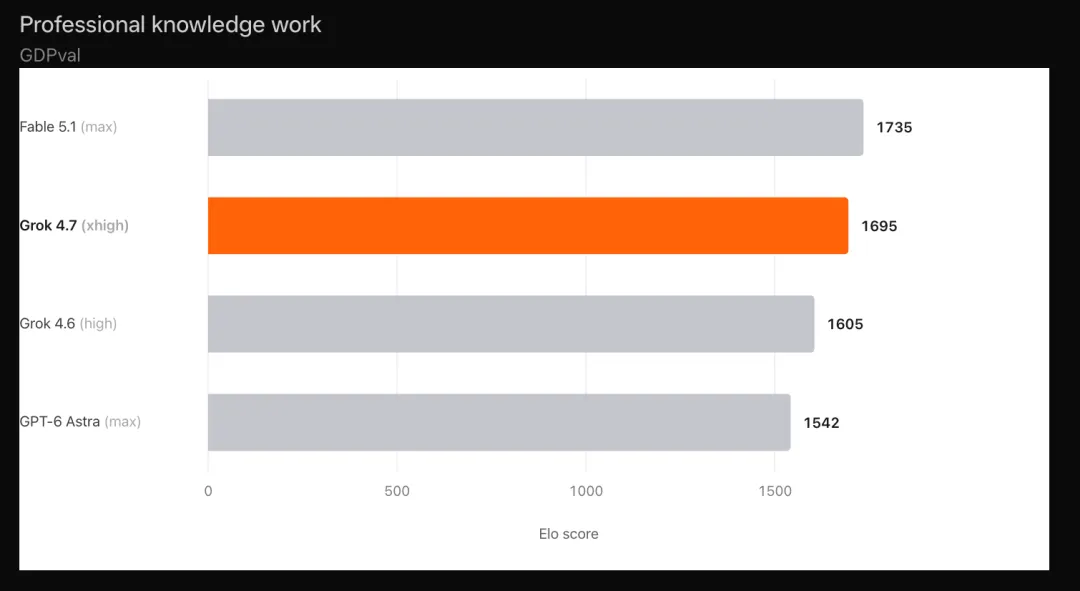
On GDPval-AA, it received 1695 Elo, 90 points higher than the previous generation.
 |  |
What is important about these tasks is that AI can't really help professionals get things done.
For example, in organizing materials, producing documents, completing analysis and presentation documents, Grok 4.7 is significantly improved from the previous generation.
In addition, in the electrical engineering testEEBench, Grok 4.7 took 64.0%, the highest of the four models.
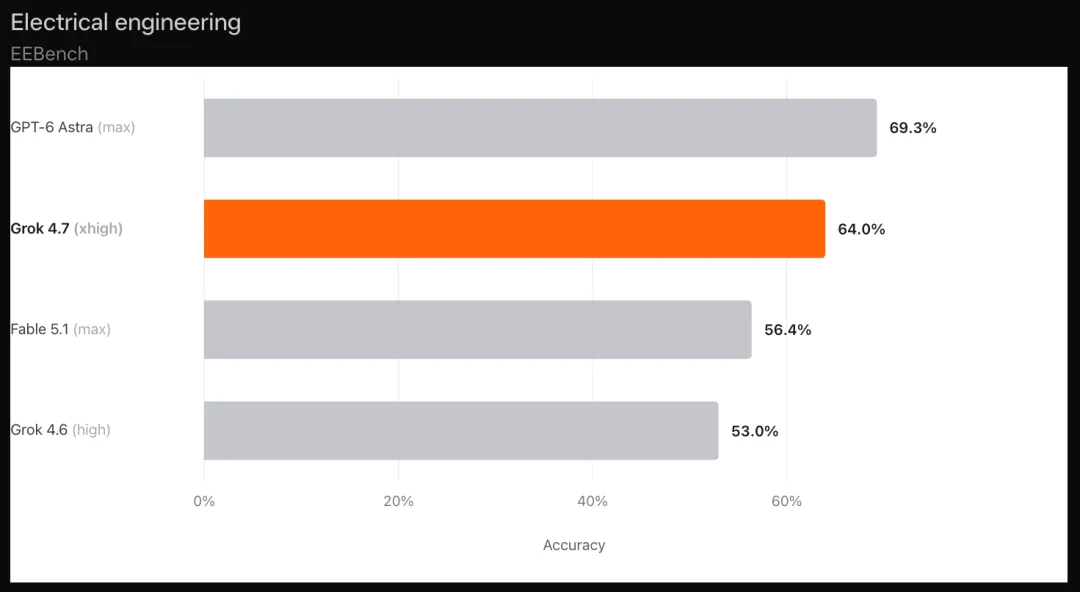
Full web testingIt's a surprise and it's a ride.
When Grok 4.7 went online, many people were already rubbing their fists and tasting it.
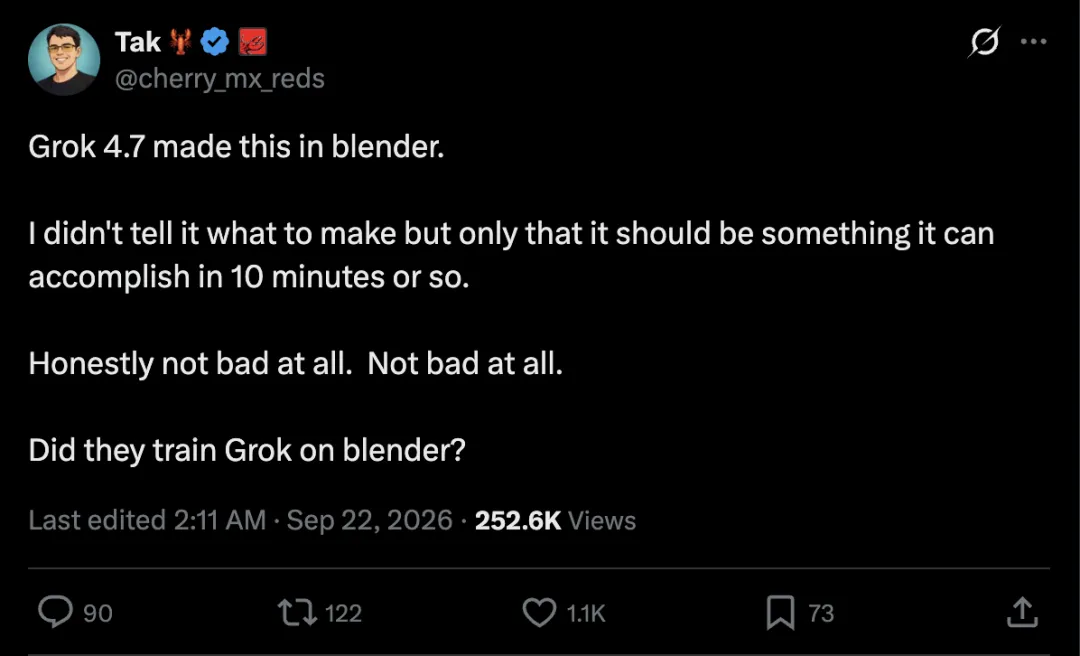
This is a demo from the developer Tak.
He didn't give Grok 4.7 any specific requirements and left a message: "If you can make a cake in 10 minutes, make a cake".
As a result, Grok himself ran to Blender and found a bronze telescope on which the planet could even rotate, drawing 250,000 people around the entire web.
Tak himself commented, "To tell the truth, it's not bad".
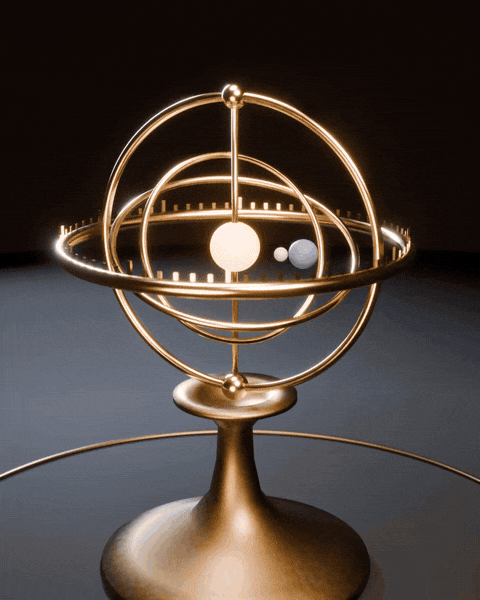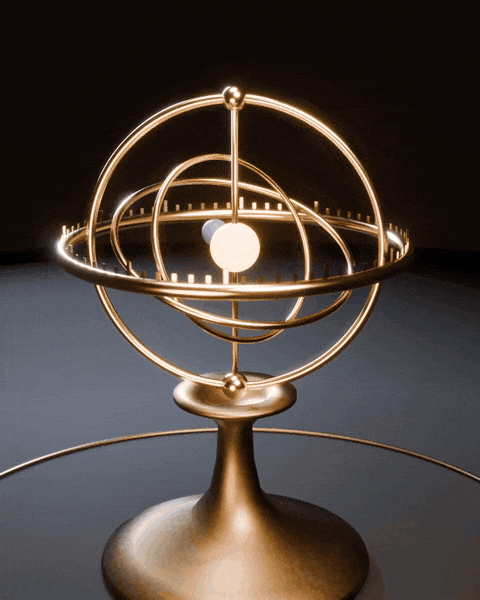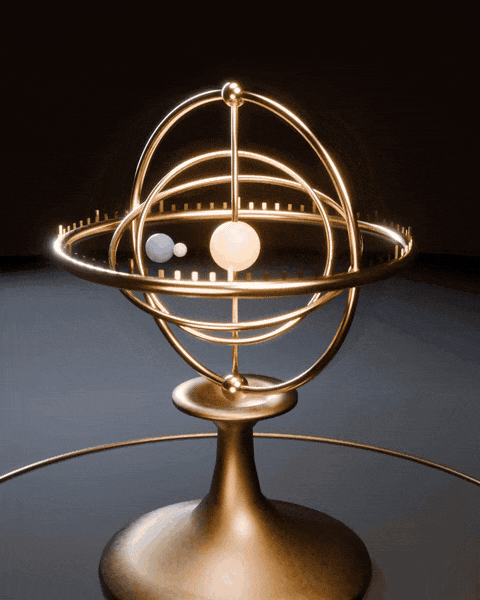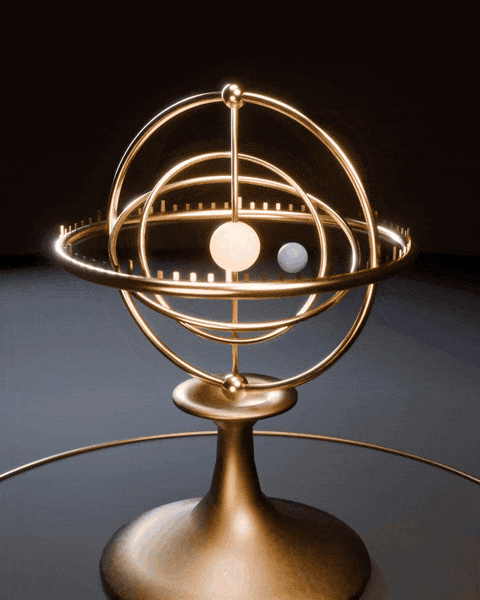
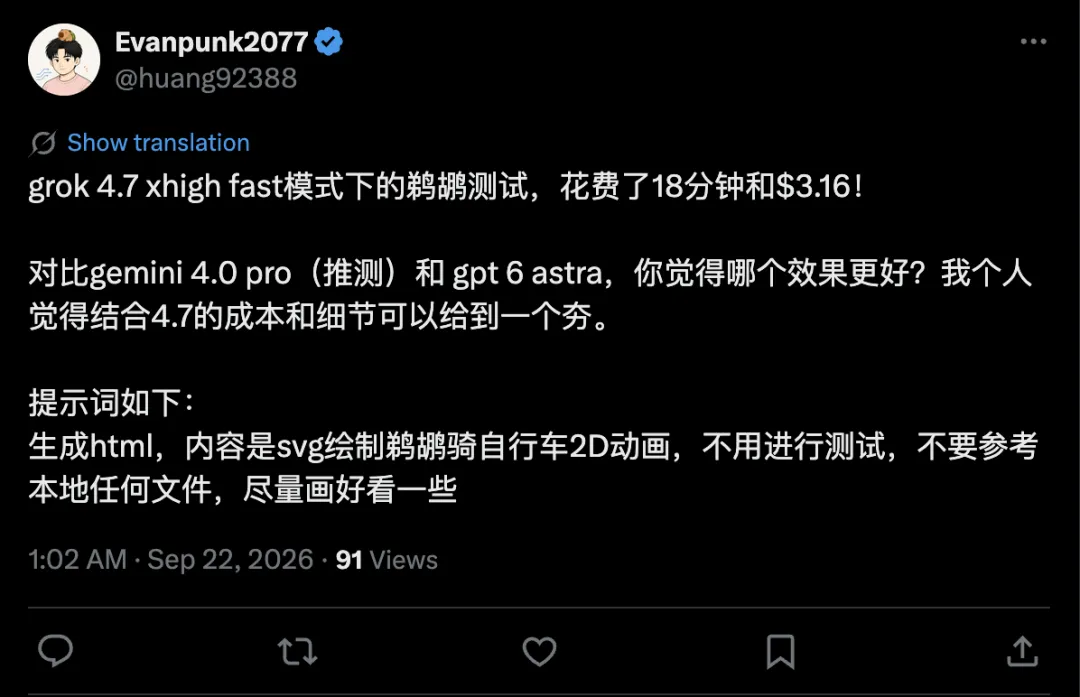
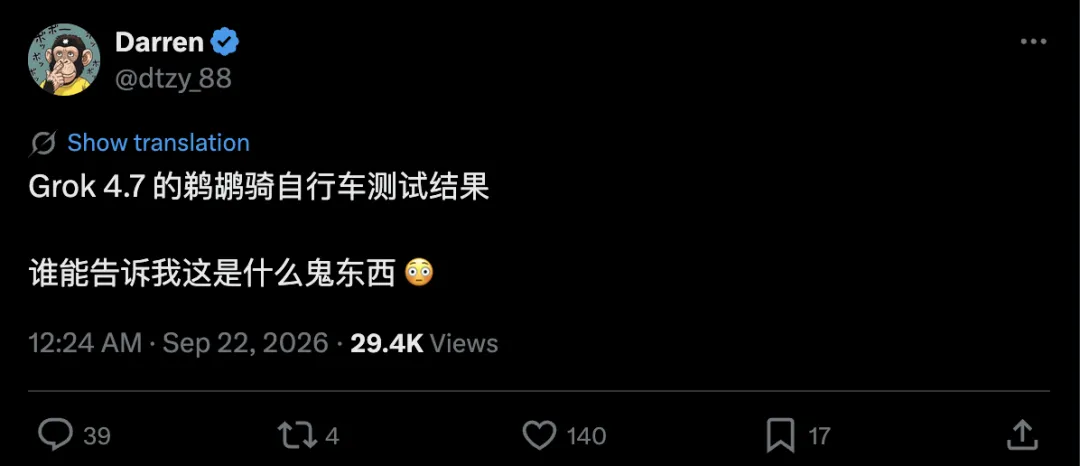
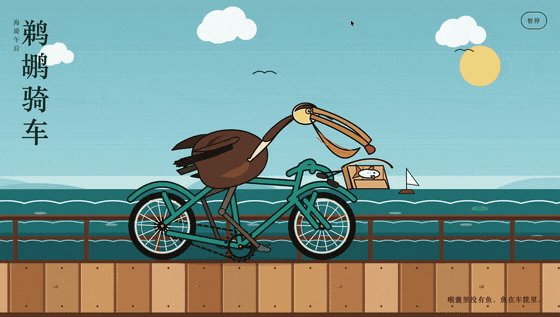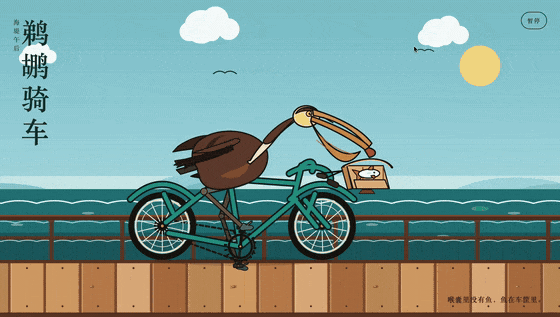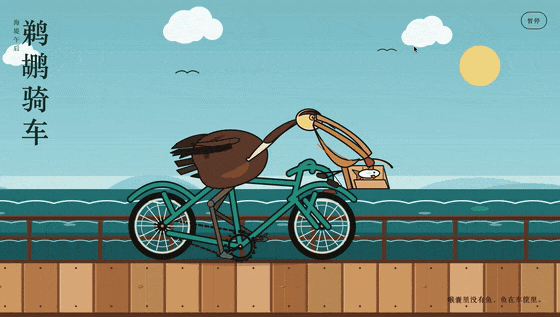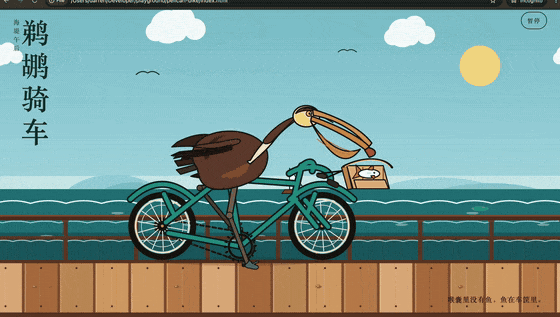
And then there's the classic show, cycling.
Someone directly loaded the configuration, ran the xhighfast mode and burned the entire 18 minutes, $3.16.
The result is something like this: the white elephant is riding by the sea, and the wings are on the carriage.
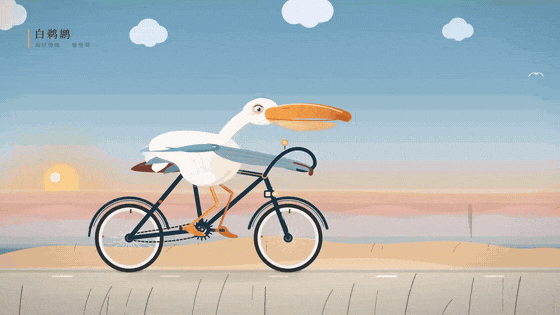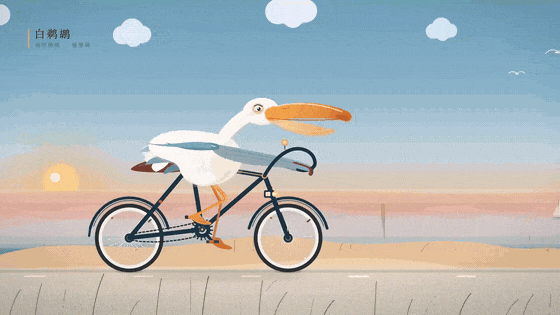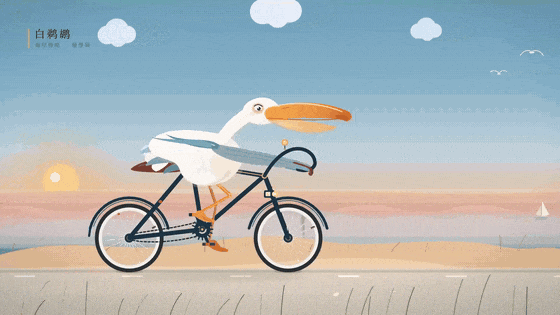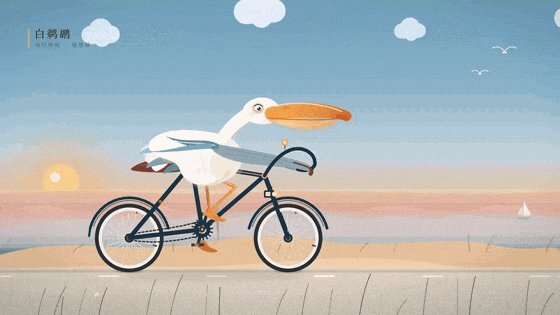
The other man ran out and dragged the brown bird straight into the bicycle.
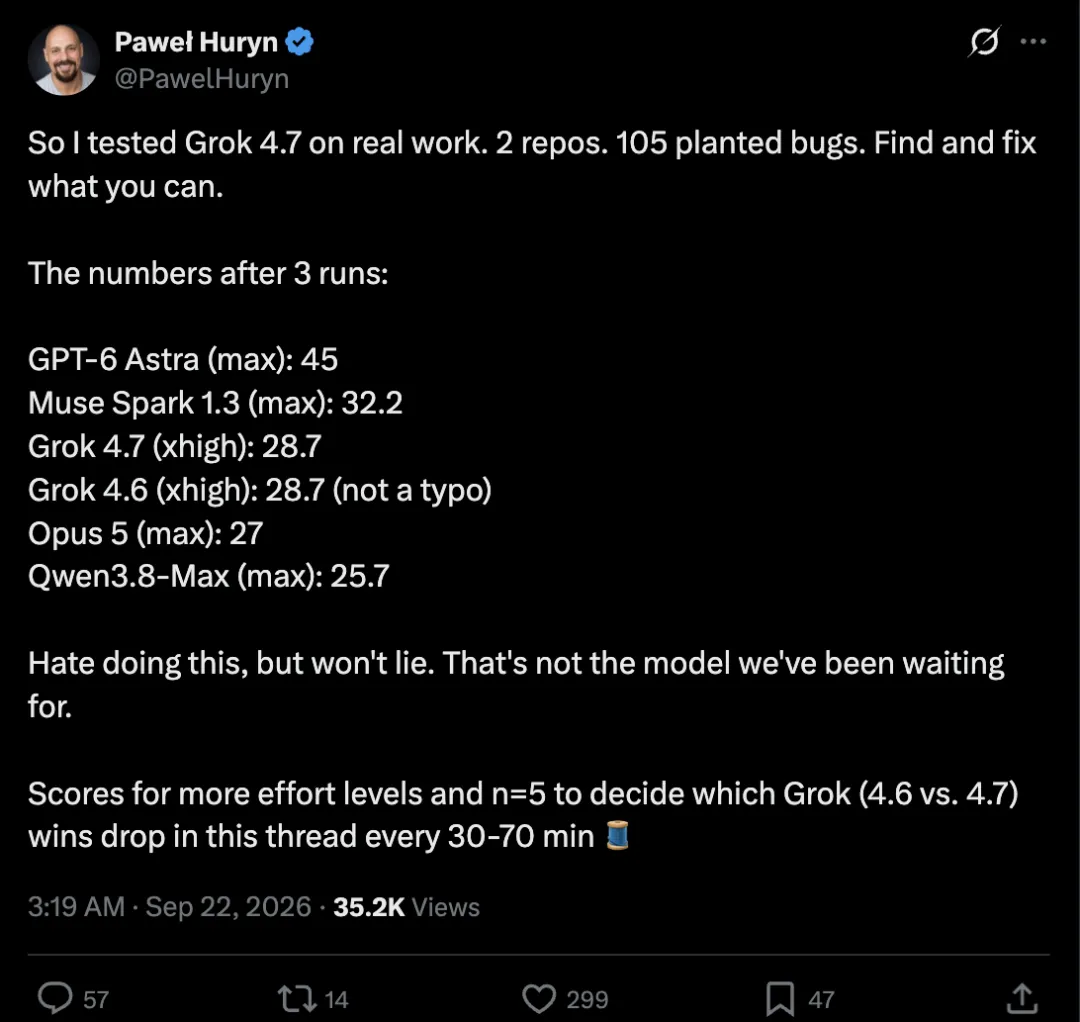
Product blogger Paweł Huryn took two real code libraries and buried 105 bugs in three rounds.
As a result, the GPT-6 Astra was able to repair 45 of them; the Grok 4.7 was able to repair 28.7 of them.
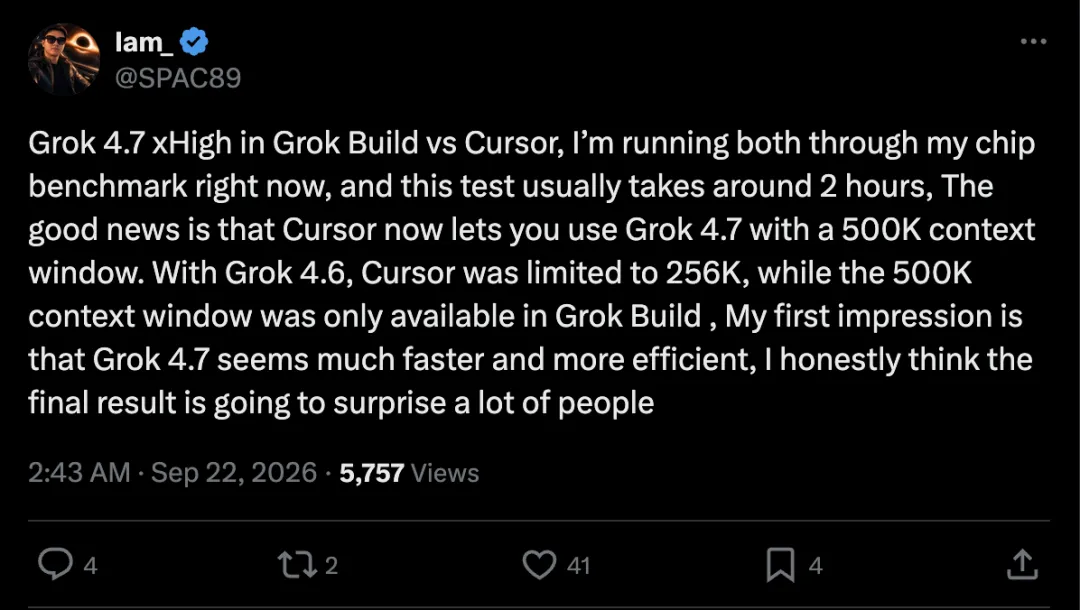
Another hard-hitting control experiment was directed at Grok Build and Cursor's Grok 4.7.
For two hours, the most intuitive feeling was four words: quick and saving.
In the meantime, a new colour egg has been unveiled, and the Cursor has pushed the Grok 4.7 up to 500K, just to let you know that the previous generation of 4.6 is only 256K.

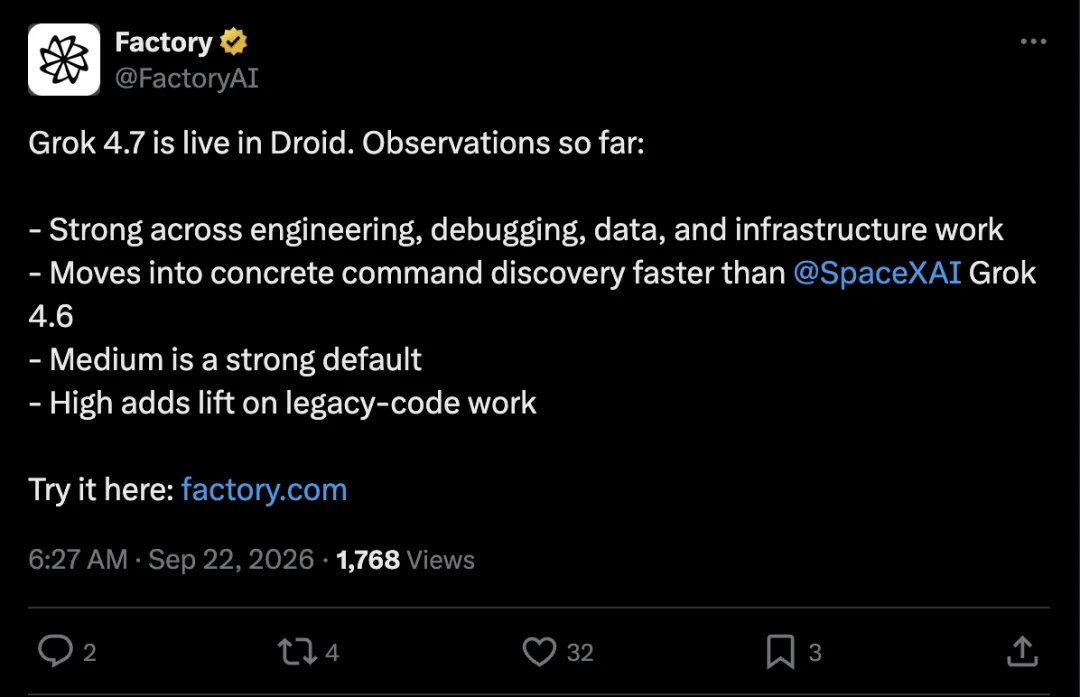
Factory, which programmed Agent, was also the first to integrate its own Droid, giving it a more controlled rating.
Engineering, debugging, data, and infrastructure all work, commands are faster than 4.6, medium files are more than enough, and high files are added to old code.
Five times cheaperIt's been a while since I've been able to do that.
Another highlight of the Grok 4.7 official announcement is that the price is half the same.
It's worth noting that her one-time price was very tempting: $2 to go in, $6 to go out.
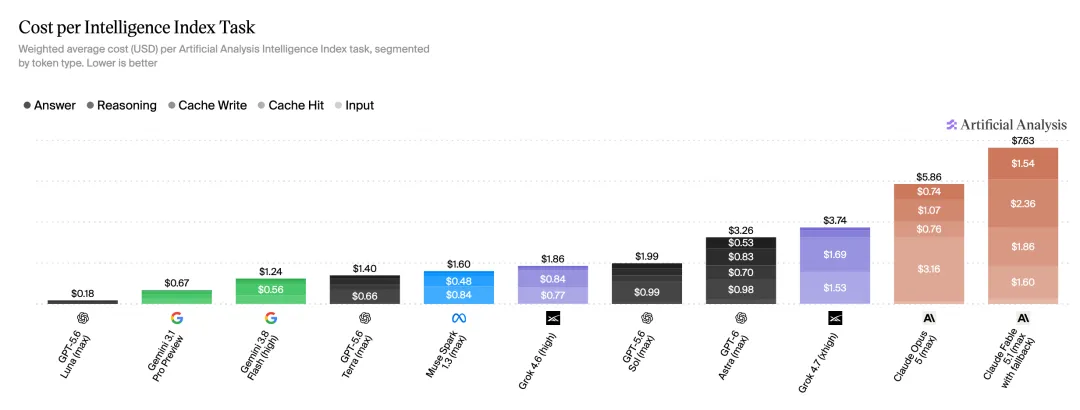
Compared to Astra and Fable, Grok is five to eight times cheaper than the Assassin's Price for 10 Inputs and 50 Outputs.
On the officially unveiled Cursor Bench 4.0 price curve, Grok 4.7 takes 46.3%, solving a puzzle costs $6.01; Fable 5.1's middle grade costs 46.8%, and a puzzle costs $7.05.
But as soon as you take a large mirror and look at the details at the bottom of the graph, the text changes.
The Fable 5.1 low-end runs 45.1%, with a single issue cost of only $5.44, which is cheaper than Grok's top-end; while the previous generation GPT-5.6 Sol high-end takes 35.7%, with a single issue costing only $2.85.
The front door is still in that amazing "physical texture".
81,000 tokens were issued, almost three times the price of the GPT-6 Astra. The single price was five times cheaper, but the crap was three times more, and the actual bill advantage was alive and well.
A developer on Hacker News said that Grok 4.7's caching readings were even higher than Sol's.
The Cursor community is even more straightforward: "It's not at all an age-old sexuality compared to monsters, spending almost double the tokens of 4.6, and the extreme cheapness of 4.5 is completely gone".
However, at pure speed, it does kill very quickly.
AA is testing 188 tokens per second, and the fast mode is twice as fast as the original.
The model plus frame is the next battlefield.
Today, the tactical intentions of Grok 4.7 are clear.
It has no intention of hitting the absolute throne of the AGI, but instead retreats to the front of the second ladder, clinging to the cheapest, fastest altitude, and exclusive price.
But the era of true industry trends exposed by this release of the single-body model is over.
Grok 4.7's high scores, most of them based on Grok Build's custom-made hard tops; once removed from its home rack, the scores are high.
Anthropic uses Claude Code to lock down long-range missions, OpenAI uses Codex to keep ecosystems, and xAI has finally taken the path of bundling developers with a private framework.
The future third-party evaluation list will lose its purity altogether, and after seeing the so-called run-score ranking, the first sentence must be asked:
What kind of framework do you use to measure?
RoboInd editorial channelResearch, robotics companies and market intelligence for cross-border sourcing.Explore the channel ↗
Share this
End of editorialExplore more from Global Robotics News ↗