From the SWE-bench Verified to the SWE Pro, and then to the DeepSWE, the models have been brushing up on the topic of fixing bugs, implementing functionalities, these bounded repair tasks, and the current large models are doing well enough to make sure that they are running safely.
But real software engineering is never just about fixing bugs.
DeepSWE has already ripped a hole in the wall, and when the question went from tweaking a few lines of code to rewriting a file-length task, the top model dropped from 96% to 70% of the pass rate.
But DeepSWE is still not the end.
The final test of Coding Agents is not a local edit, but the evolution of the entire codebase.
Removing a set of 200,000 lines of systems from C to Rust, unchanging interfaces, unchanging behaviours, unchanging old code - that's the real job on an engineer's calendar.
It's a hell of a hell of a lot harder than DeepSWE.
Navers Lab of Einsia AI recently released a new benchmark, the SWE Refactor Bench, which gained 500,000 views after the release of X and sparked more than 3,000 related discussions in overseas communities.
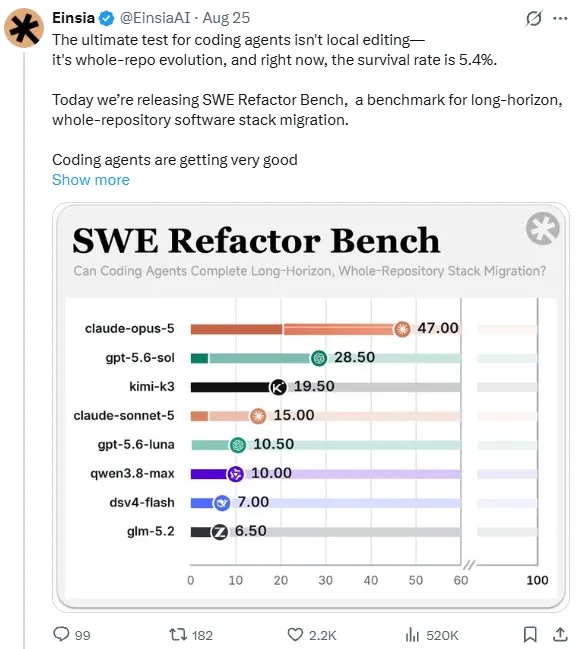
The title of the paper is: SWE Refactor Bench: Can Coding Agents Complete a Long-Horizon, Whole-Repository Stack Migration?
The main page of the project:
Arxiv:
Github repo:
If DeepSWE is looking to implement a new functionality layer in an existing code library, the SWE Refactor Bench is looking to reconstruct the layer.
20 real open-source projects, including SQLite, zlib, libsodium, GraphHopper, these industrial-grade infrastructures, have a total of 86,70,000 lines of code and 10,594 files.
The mission is divided into four categories:
C→Rust、C→Java、Python→Go、JavaScript→Rust...
The following is a list of characters that first appeared or will appear in the first episode of the first season.
The platform is ported to three: POSIX→WebAssembly、CommonJS→V8 realm...
This is a list of the most commonly used tools in the field of automation.
The requirements for each issue are the same: to move the entire warehouse to another technical shelf, delete all the old code, and the external behaviour is not bad.
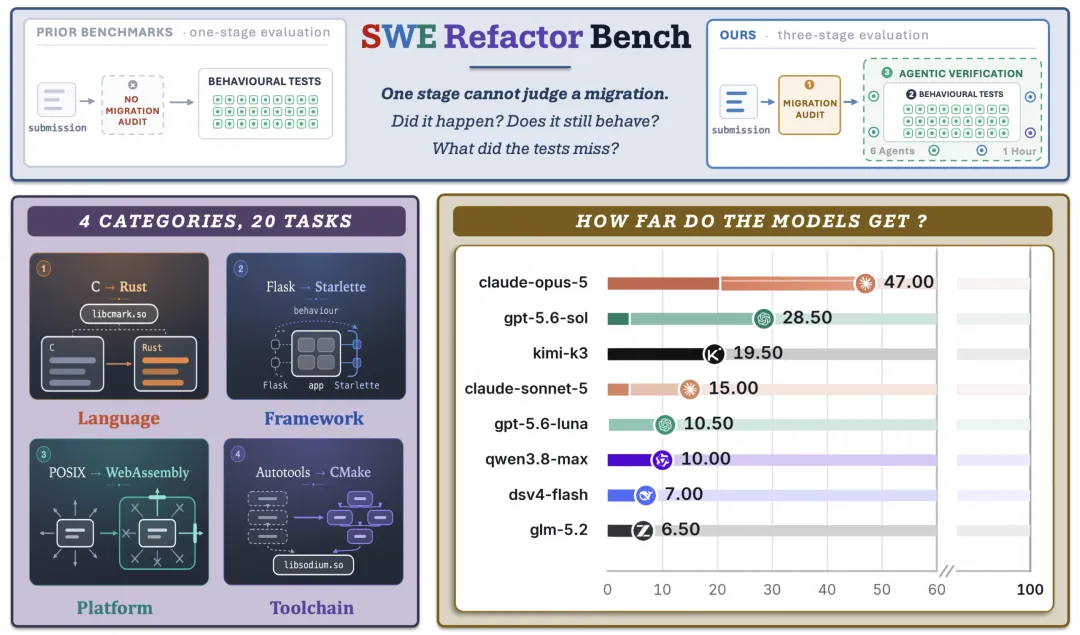
Layered Setting Card: Under three locks, there is no way back
The SWE Refactor Bench's rating is not a one-run test. It sets up three locks, sequentially executed, and any locks are automatically terminated.
Question 1: Migration review. Has the old technology bubble completely disappeared from the source code and building products?
Second link: Functional testing. 130,118 checks, whether accurate checking behaviour is not bad.
Following the passing of the first two blocks, came the most brutal third: "Let AI be hacked, let AI be black with code written by AI itself". Six independent Coding Agent verifiers, each with an hour to attack the submission, only executing counter-examples are calculated.
The result:
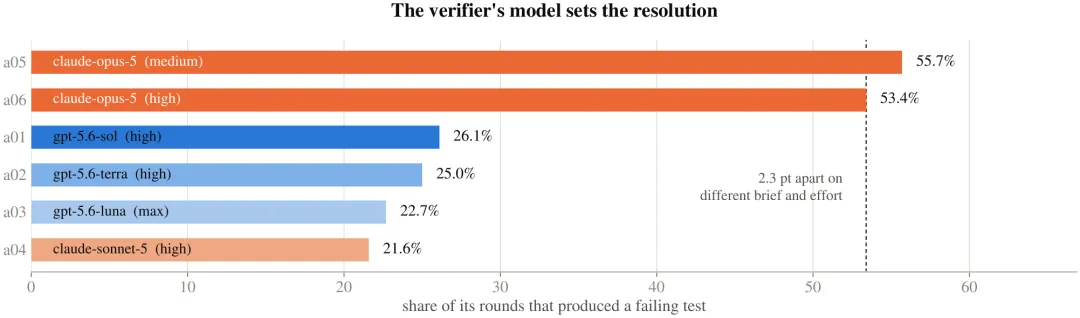
Median time for the verifier to find the vulnerability: only 17 minutes
The most powerful verifier (Claude Opus-5) has a breakdown rate of more than 50%, compared to only about 24% for other models.
All the models, the entire army was destroyed.
Eight front-end models, 26 configurations, 20 missions, and a total of 520 separate attempts resulted in only 28 submissions passing all three rounds of evaluation.
What's even more troubling is that 3 models didn't produce any acceptable submissions from start to finish, so they ran 20 missions, one of which they couldn't complete.
I've tried 520 times to break it down:
340 times (~65.4%) passed the migration review, which at least looks like a migration.
All of the pre-set tests were passed.
Only 88 of them met both conditions at the same time, entering the third round.
In the end, only 28 survived.
Of the 20 missions, 13 were unresolved.
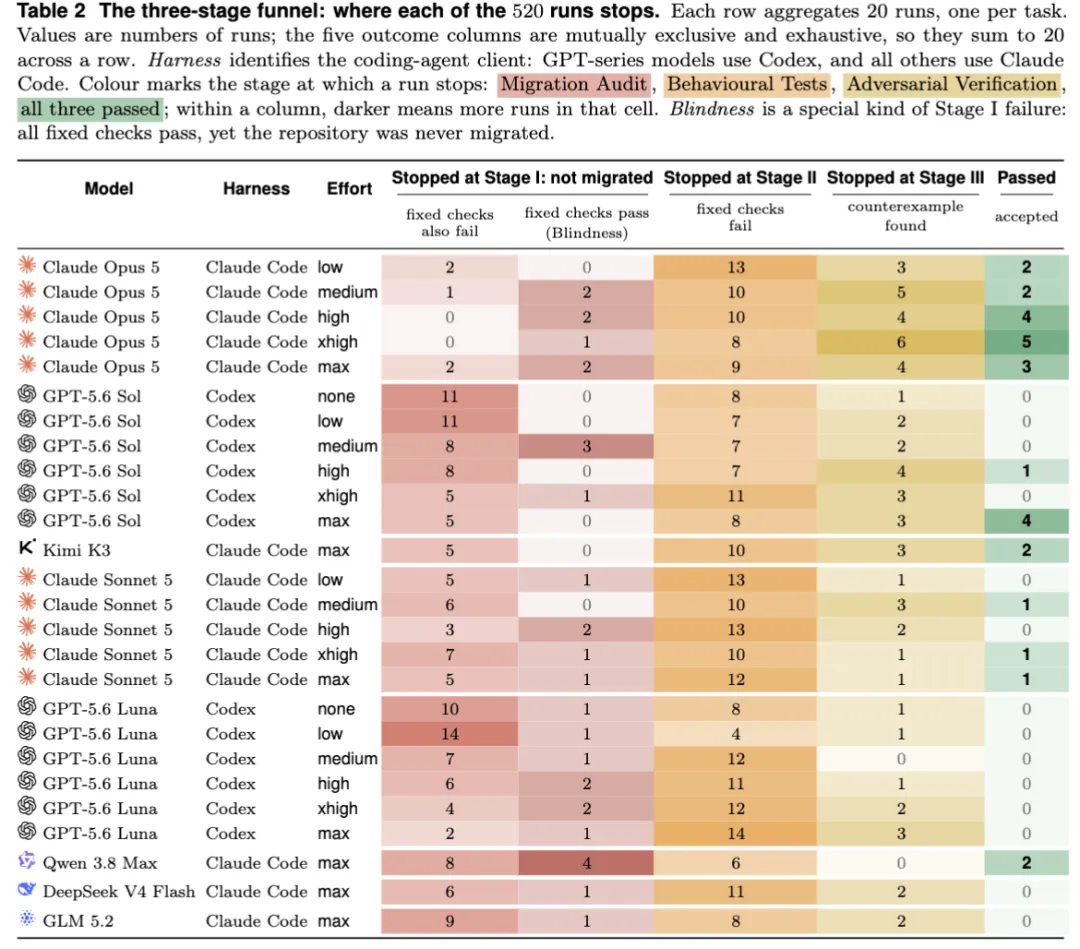
It's not the same thing to have two abilities: to be able to migrate and to be able to behave.
He's a thief, and he's a tough guy.
This is the most anti-intuitive design of the SWE Refactor Bench.
A traditional benchmark starts with a string of bugs in the code. A string of bugs hanging up and being fixed proves that you've done it. But the migration task starts with a system that can already run.
The paper manages what's called the blind zone hypothesis: the test set isn't enough, it can't even see if the hypothesis has been modified.
And stealing is just one of them.
There's another way in which a hard-skinned person submitted the migration 252 times, but the behavior didn't hold up, and the code was changed and ran incorrectly.
Stealing, behaving well but not doing. Strong, doing well but not doing well. Both paths do not reach the end. Eight models without exception, all swinging between these two directions.
The codes for the codes are correct, and the codes for the migration of codes are true. The most powerful models today have not yet learned to do so at the same time.
The last kilometre: 99% accuracy, one step away from delivery
For a warehouse migration, any unit test that doesn't pass is a significant risk. The failure of that test is a real downstream consumer, and it won't go wrong because the other 99.99% of the behavior is wrong.
This is one of the hardest things to do in a smart body.
Of the 340 migrations that have actually been completed:
91% can make a fixed test set more than half
58% to 99%.
36 percent to 99.9 percent.
Only 26% can do a good job.
Only this last small step eliminates 35 of the 123 runs that have gone up to 99.9%; and this last small step causes every bookmark on the site, every link shared out, to fail; and the project's homepage is blank after some of the packages are released.
It's not a test set, it's not done by the migration itself.
Written at the end
The SWE Refactor Bench reveals three things:
First, behavioural testing will fail in a migration scenario. The original system would have been able to pass all the tests, and the AI would have scored. This is not a test coverage curve, it is a measurement of the wrong object curve It is measuring whether the curve has changed, not whether the curve has changed.
A few models chose to sneak up on the roots without moving, and most models chose to crash and eventually spoil the behavior. The model can restore the behavior to more than 99% but ultimately passes less than one-tenth of all checks. The difficulty is not getting close to the behavior, but the last kilometre.
Third, AI will write code, but will not do system-level software engineering. 520 attempts, only 28 successful. 20 tasks, 13 unresolved.
It's not that AI doesn't work. It's that we finally have a measurement of whether AI does work.
The code can be rewritten.
This is the essence of software engineering.