We spent a lot of time harnessing the LLM to help the LLM become an agent to better accomplish tasks in complex environments, so what about this part of the environment?
Whether it's distillation, reinforcement learning or evolution, we all need agents to interact with the environment, but we have no way of controlling how the environment interacts with the agent. Compared to agent harness, the article proposes Envharness, a completely new component for controlling the way the environment interacts with the agent, to help the environment provide the agent with better training signals in various training scenarios.
EnvHarness: Awakening Static Worlds for Agent Learning
Link to the paper:https://arxiv.org/abs/2608.19880
Project code:https://github.com/google-research/envharness
The main page of the project:
Environmental Harness and Agent Harness
In the general intelligence agency scenario, an agent needs to complete a task in an environment, which can be a web page, a code library, or even a room.
In today's general setting, the core of an agent is an unchanging large language model, and we help him do his job better by adding a handshake (Harness) around it, such as memory (memory), skills (skills).
As the other end of the framework, the environment can also have its own harness to control how the environment interacts with the agent.
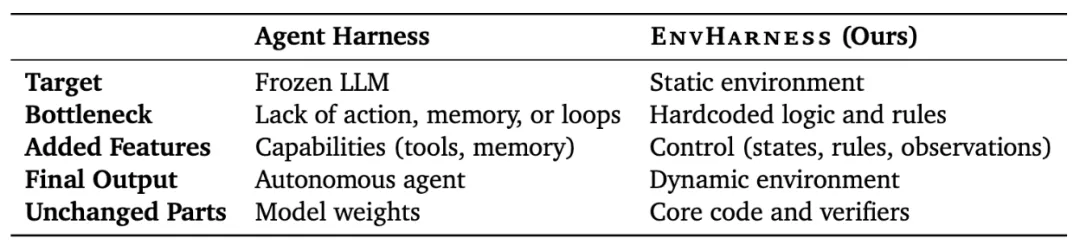
While Envharness and Agent Harness have not touched on the most central part of diplomacy - the big language model and the environment itself - they can only change the way the core content is exchanged through input and output interfaces to achieve what we want, and for the environment, a better environment is providing better training signals to train agents.
What is EnvHarness?
Envharness complies with one of the simplest interface protocols in terms of ensuring easy overlapping between each other. Simply put, we need an environment plus an environment harness after the external interface is completely unchanged.
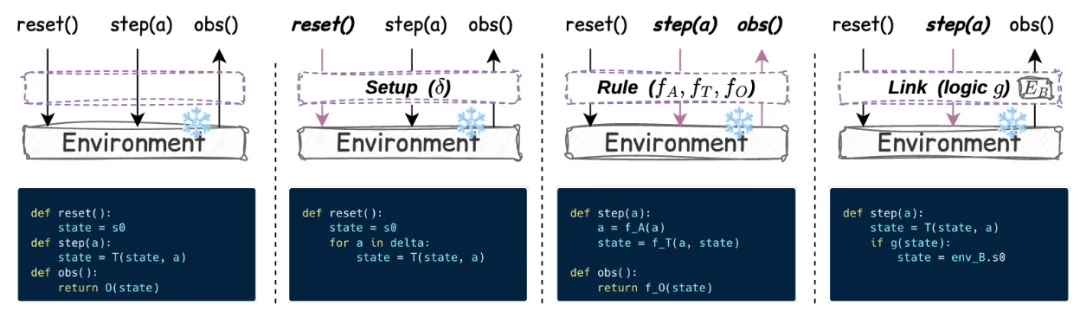
Standard environment: Following three of the most standard interfaces, reset () is used to initialize the environment, step (a), performs an operation in the environment, and obses) to understand the state of the environment through observation.
This article presents three comparatively simple components of Envharness.
Environmental layout: A series of actions to change the initial state of the environment after environmental initialization
Rules of interaction: mapping and observing the actions of an intelligent organism to a new operation or observation
Link environment: automatically jumps to another environment when the current environment meets certain conditions
Since all operations are based on standard interfaces for the underlying environment, Envharness can be installed seamlessly in any environment that meets the requirements, regardless of whether the underlying environment is a website or a docker, for robot training or gui training.
How to design EnvHarness
Returning to Envharness, the purpose is to allow the environment to provide better training signals. Referring to evolutionary agents reading actual trajectories to optimize harness, the article proposes using an agent to observe trajectories to give Envharness.
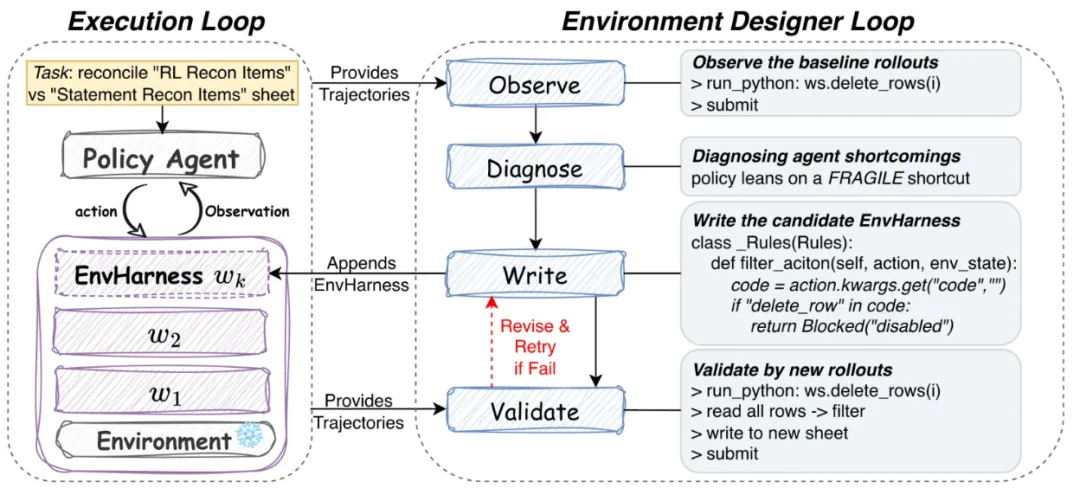
The whole process is divided into a simple four-step cycle
First, read the n trajectory of the agent in its original environment.
Based on these tracks, agents can identify if there are problems or where they can be improved.
Then try to give a first envharness
In addition to the above envharness environment, let the agent try again to generate a set of tracks, and then observe if it feels like it can help the agent solve the problem by going through or taking those tracks back to the next step.
With this kind of loop engineering, we can give the corresponding Envharness based on the ability of the current agent.
The results of the experiment
The article examines how environments beyond envharness can provide better training signals to help enhance the performance of agents in the context of reinforcement learning and evolutionary agents, while demonstrating the versatility of this approach in different benchmarks such as physical intelligence, web navigation, code generation, and so on.
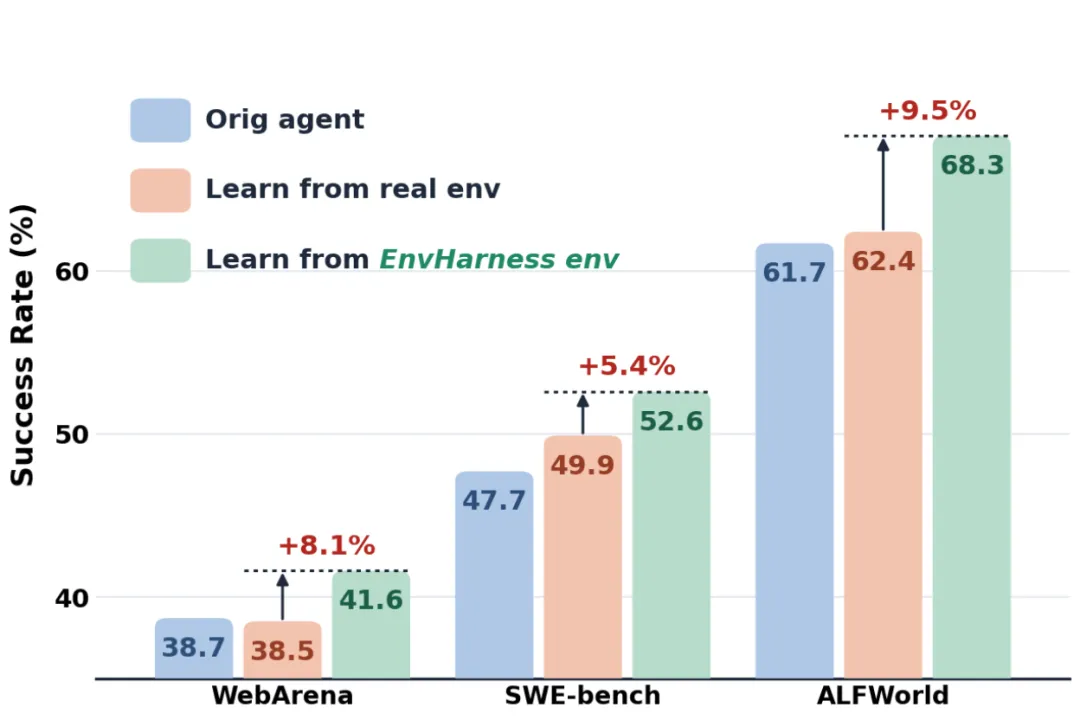
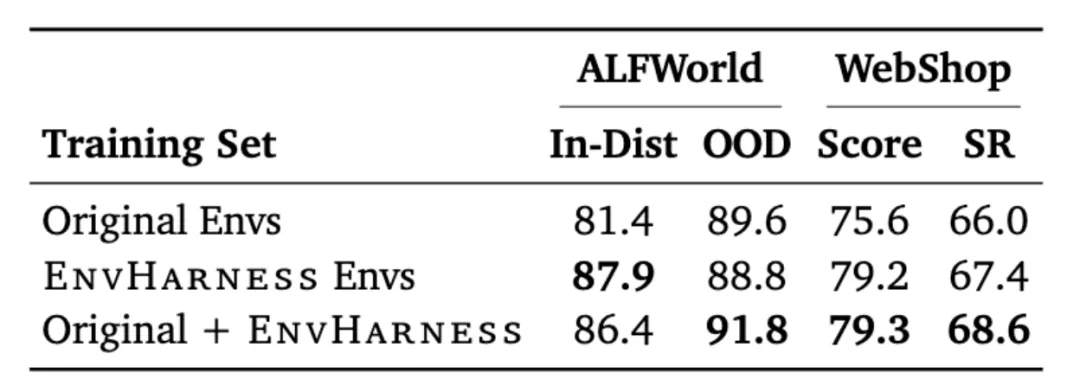
Other experiments discussed, for example, co-evolution with agents, oriented to adapt to long-sightedness problems.
Core boundaries and future prospects
The article gives many current flaws in the direction of Envharness as well as future directions such as:
As with agent harness, which includes a wide variety of components, envharness also requires a wide variety of solutions to specific problems such as long-horizon, field knowledge, context, etc.
More efficient Envharness design methods, existing methods relying on multi-cycle trajectory sampling, lower efficiency, and no way to achieve super-scale environmental enhancement research
Chengsong Huang, Ph.D. student at Washington University in St. Louis, has been cited by Google scholar more than 1,500 times, and his current research interests are mainly focused on the evolutionary agents and data synthesis direction. Machine Heart has reported his work on Lorahub, R-zero, and over 700 stars on github.