The Red Book FireRed team has released a new generation of voice generation and editing model FireRedTTS3. It uses the same model to unlock the three major capabilities of voice in multilingualism, multilingual zero-sample sound cloning, customizable voice design for "description" in natural language, and precise voice editing for "where not to change where not to change".
FireRedTTS3: Unified Speech Generation and Editing with Semantically Enriched Speech Representations
Technical report:
This is the first time I've seen this.
The code link:https://github.com/FireRedTeam/FireRedTTS3
Give it a few seconds of your voice, and it can say "you" in 24 languages, 21 Chinese dialects; give it a word of description, and it can "pick" out a voice that never exists; give it a built-in tone, and it moves just where you turn, like a document, and the rest is unchanged.
The secret lies in a speech expression called RedAE: it asks a "semantic teacher" to put the semantic "teaching" into the voice expression at the source. So without stacks of modules, without stages of training, without overlapping complex structures, it steadily suppresses the old headache that generates the most headaches of continuous speech, "the more you say, the more you run away".
The score was also tough enough: the accuracy rate and similarity of sound cloning topped the list (Seed-TTS-Eval 3.04% / 78.8%), the cloning of 24 languages topped the list (3.75% / 84.8%), and sound design and voice editing topped both lists.
First in the ear: Can you tell the difference between the two?
Following FireRedTTS-2's long conversations with podcasts generated to an industrial level, FireRedTTS3 shifted its ability from "speak a word" to "clone, design, edit hand in hand".
Listen to how friends from all over the world talk about the World Cup. During the heatwave of the World Cup, different languages, different chords are playing; but you might not think that these sounds actually come from the same set of models.
Next, we're going to listen to netizens from different regions ask teachers in a kind language. Do you think their accents are not true?
If the spelling "speak all kinds of languages" is width, then the spelling below is "no middle life". This time, we don't provide the model with reference audio, only pass the word "description of needs".
Is it possible to "operate" on an already recorded sound with an aerial sound? The last one is a bit like magic: in a finished word, we just want to change one of the words, or adjust the speed of the voice a little bit, and no word elsewhere is allowed to move.
So the question arises: how does a model do all three things well at the same time?
To clarify this, we have to go back to a more fundamental question of why we need such a model.
Over the past two years, TTS has become quite mature in zero-sample audio cloning. But the demands of users who are rapidly upgrading the sound are no longer satisfied with "repeat a sound", but hopefully:
When I say, "What kind of sound do I want?" the model gives me what kind of sound.
It's possible to make accurate local changes to already existing voices (just change the words/speed I've specified, etc., don't move anywhere else).
In a nutshell, demand is moving from "clone" to "control".
If you want the machine to "listen", where's the card?
In order to be "controlled", the model must pass through three stages: understanding natural language instructions → placing the instructions accurately on a certain speech attribute or segment → without breaking the unspecified part. The basis of all this is that the speech indicates that two types of information must be encoded at the same time: semantic (content/style/intention) and acoustic details (tone/pitch/pitch)
There are currently three technical routes, each with a shortcut on "singular + acoustic + controllable":
Non-self-returning Flow Matching: The architecture determines the ability to follow instructions in large text models that are difficult to borrow;
Dispersed Token (VQ/RVQ): Quantization will erase fine-grained acoustic details, which are easily misrepresented in sound-sensitive tasks such as voice editing;
Continuous regression (LLM-DiT): Continuous space is infinite, and minor errors accumulate continuously in the regression, causing tone drift, and order collapse.
Continuous regression is currently one of the most promising paths, but "accumulation of errors" is the only way around it. The previous academic community mainly remedied it from two directions: one to continuous representation of semantics (such as Ming-UniAudio additional module abstraction semantics; VibeVoice uses separate semantics VAE; dots.tts add ASR targets to VAE training); the second is to correct feature spaces (such as VoxCPM introducing FSQ bottlenecks) during the regression phase. However, the direction often requires additional semantic modules, or multi-stage tokenizer training directions; the latter will complicate the architecture.
So FireRed TTS3 changed its mind and asked if it was possible to mitigate the accumulation of errors in the "representation" layer while the system was still simple.
The first step: let "express" itself with the semantics of RedAE
The first cornerstone of FireRedTTS3 is the continuous voice tokenizer RedAE. Its core idea can be summarized in one sentence: not to add additional semantic modules, not to do multi-stage training, but to ask a "semantic teacher" to "teach" the semantics in continuous representation during the tokenizer training.
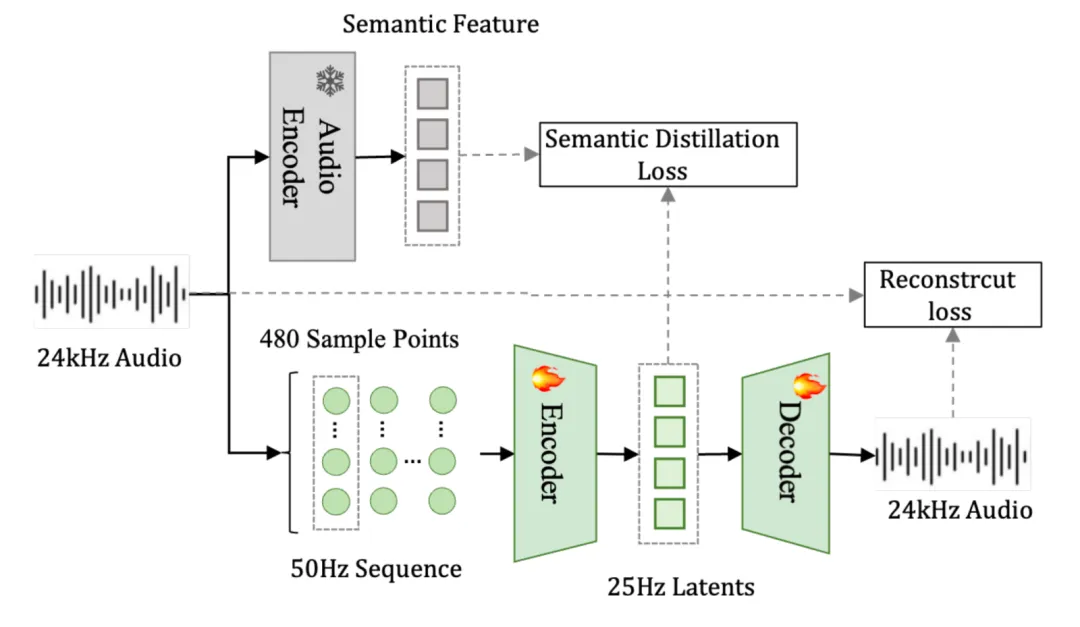
Figure 1 shows the structure of the RedAE
Where did the semantics teacher come from? The team first trained an audio understanding model, FireRedAudio, to learn how to use its Audio Encoder to understand ASR, speaker verification and other voice-comprehension tasks, and to naturally understand "content semantics" and "speaker acoustics cues".
When training RedAE, freeze this Audio Encoder as a semantic teacher, so that the output of RedAE continuously represents the attributes of the teacher that are aligned (minimizing the MSE of both, i.e. loss of semantic distillation).
Why accuracy is not compromised. RedAE deliberately omits the common KL rule to avoid overcompressing acoustic information, thus leaving the "easy to quantify erased" details in the tone intact. This is the key to its lead in sound similarity.
Structure and training details. The input 24 kHz wavelength is cut into 480 non-overlapping sample points, obtained in a 50 Hz sequence. The Qwen3 style Transformer is handled through two levels: the first modeling the context at 50 Hz, and the second sampling to 25 Hz through attention-based polarization. Each pair synthesizes a patch.
Overall, training under the GAN framework, generator losses include resistance, multi-dimensional Mel rebuilding, feature matching, four semantic distilling. The RedAE's Encoder and Decoder are combined in a single phase, with no additional semantic branches, no multi-phase flow lines; training with 500,000 hours of diverse audio (500,000 hours of clean voice 50%/band noise 25%/sound efficiency 10%/music 15%), running 550,000 steps on 32 pages of H800).
Step Two: A light frame, a vacuum, three things
The next step is to create a generating framework that uses it. On top of the RedAE, FireRedTTS3 uses a lightweight LLM-DiT framework that consists of three components:
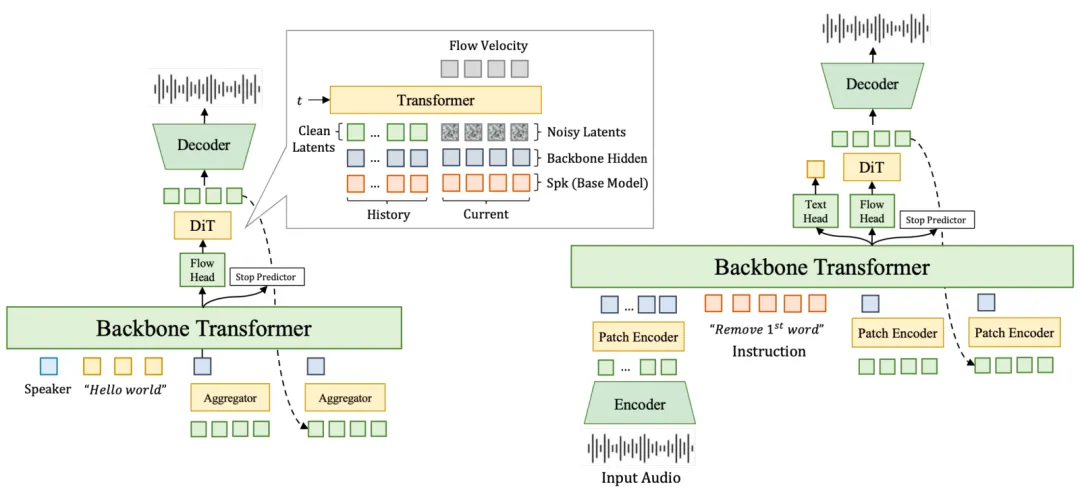
Image 2 LLM-DiT structure, left to FireRed-Base and right to FireRed-Instruct
Aggregator: The RedAE of 25 Hz is further compressed into a latent patch of 6.25 Hz, shortening the sequence, reducing modeling difficulty;
Backbone Transformer: Initializes a large text model from Qwen3 to inherit the ability to understand text and follow instructions, and is responsible for modeling "text token + latent patch" backwards;
DiT Module: An all-attention Transformer, performing patch-level noise reduction at Backbone conditions, each step of the input is "a noise-bearing current patch (((4 tonnes) + 12 tonnes clean historical latent", with the historical latent always retained to maintain time coherence; when training at a 0.1 probability randomly discarded the condition as CFG.
In the same set of frameworks, the team separated two versions of "Expert" and "Omnipotent":
FireRedTTS3-Base is aimed at multilingual, multilingual cloning.
Backbone is initialized from Qwen3-1.7B-Base; it uses CAM++ to extract speakers embedded both into the Backbone input and as a speaker condition for DiT to enhance tone consistency; the pre-text language tag indicates the target language.
Two phases of training: the first phase with 2.6 million hours of Chinese English spoken (117,000 steps) and zero-sample cloning; the second phase with 560,000 hours of training covering 24 languages + 21 Chinese dialects, extending to multilingualism.
FireRedTTS3-Instruct (Unified Cloning / Design / Editing)
Backbone was initiated from Qwen3-1.7B with instructional capabilities, using the ChatML format, to distinguish tasks with different system prompt.
The key design is "pre-planning, re-synthesis": the model first translates user instructions into a structured text programming sound design, dismantling the free description into a sequence of 12 specific acoustic attributes; when editing voice, the instruction is unfolded into target transcription + editing area masks, thus changing only the specified area, retaining the remainder.
Keeping Qwen3's text headings to support this intermediate planning process; unlike Base, Instruct does not use explicit speaker embedding and language labels. In Phase Two, 40,000 steps are trained on 330,000 hours of sound design and voice editing data.
It's a monkey, it's a horse, it's a horse, it's a horse, it's a horse, it's a horse, it's a horse, it's a horse.
It's nice to talk about it, but it's also worth talking about the results. We pulled the FireRed TTS3 into four open ratings sets, with some of the strongest models in the industry in front of us.
On the Seed-TTS-Eval of the English zero-sample sound clone in the evaluation, FireRedTTS3-Base achieved the lowest average error rate and the highest average speaker resemblance with Test-EN and Test-ZH. This confirms that "singularised continuous representations" can provide a stable modeling goal for LLM-DiT, resulting in a more robust text-to-speech alignment; and it has clear advantages in tone resemblance, especially as it avoids the quantized loss of audio information.
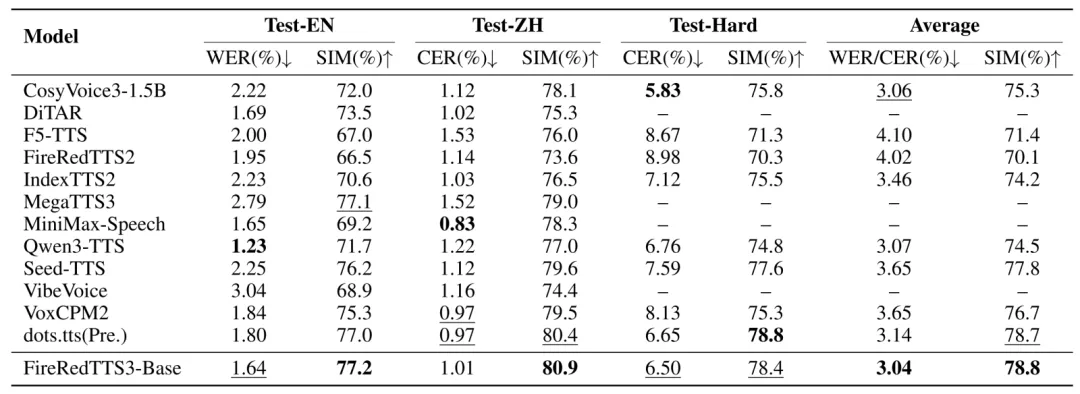
Figure 3 shows the results of zero-sample cloning of Seed-TTS-Eval.
A model that speaks fluent Chinese is not difficult, with the difficulty of being "common" in dozens of languages. When the range was extended to 24 languages, MiniMax-MLS-Test, FireRedTTS3-Base still got the lowest average error rate of all languages (3.75%) with the highest average similarity (84.8%), and placed first or second in 22/24 language similarities.
Particularly noteworthy is the fact that Portuguese and Ukrainian are not included in the training data of RedAE, and the model still gives competitive results, reflecting RedAE's ability to generalize unseen languages.
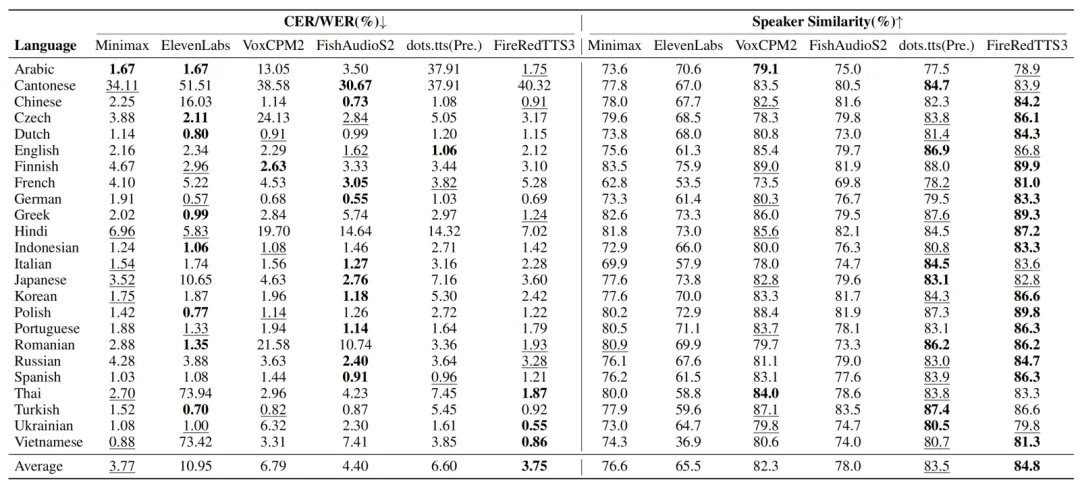
Figure 4 of the MiniMax-MLS-Test multilingual test results
In Instruct TTSEval, which examines sound design capabilities, FireRed TTS3-Instruct scored best on all three categories of instructional acoustics parameters: APS, style description, DSD, role-playing, and RP.
This is due to its design "to first analyze instructions into 12 dimensional structured text programs, then synthesize them", effectively reducing the ambiguity of natural language instructions and achieving a solution to the instructions.
Specifically, for APS tasks, it derives explicit properties from complex acoustic parameterization instructions; for DSD and RP tasks, it converts abstract style descriptions or character images into specific acoustic programs, thus improving compliance with user instructions.
In addition to deciphering instructions, FireRedTTS3-Instruct also learns the steady mapping between these well-planned sequences of acoustic properties and RedAE voice representations to effectively control target tone synthesis.
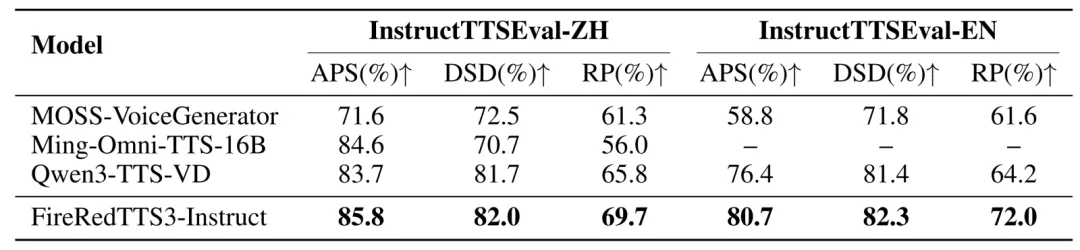
Instructions for controlling the results of sound design by TTSEval
Lastly, on the Ming-Freeform-Audio-Edit list of voice editors, whether it's audio editing (speed, pitch, volume), or semantic editing (insert, remove, replace), FireRedTTS3-Instruct is mostly at the forefront and performs equally well in the open setting of the free instruction.
From the core rating indicators: lower WER (word error rate) with NoEdit (word error rate) with unedited zone WER (word error rate), combined with extremely high ACC (editing accuracy rate), together to ensure the accuracy of content modification; significantly superior SIM (speaker similarity) ensures sound stability; and extremely low RDE/RAE (acoustic error rate) proves that it can accurately modify to the target volume and time.
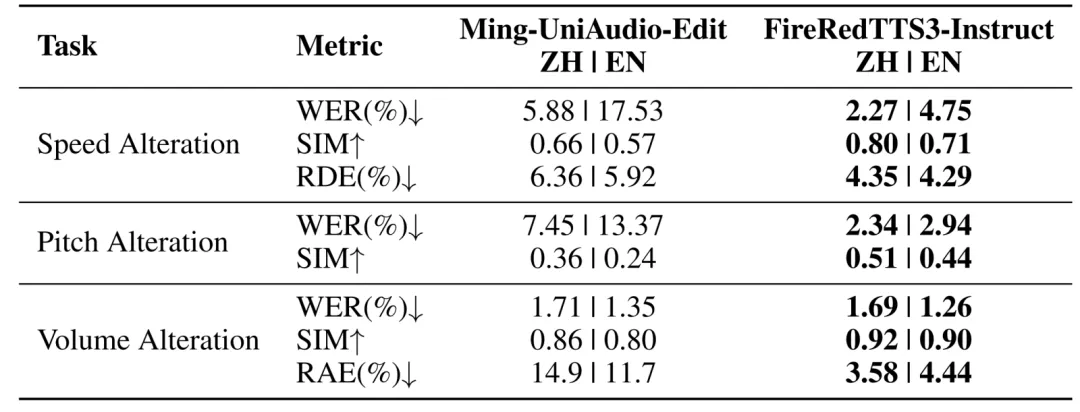
Figure 6 Mining-Freeform-Audio-Edit Acoustic editing results
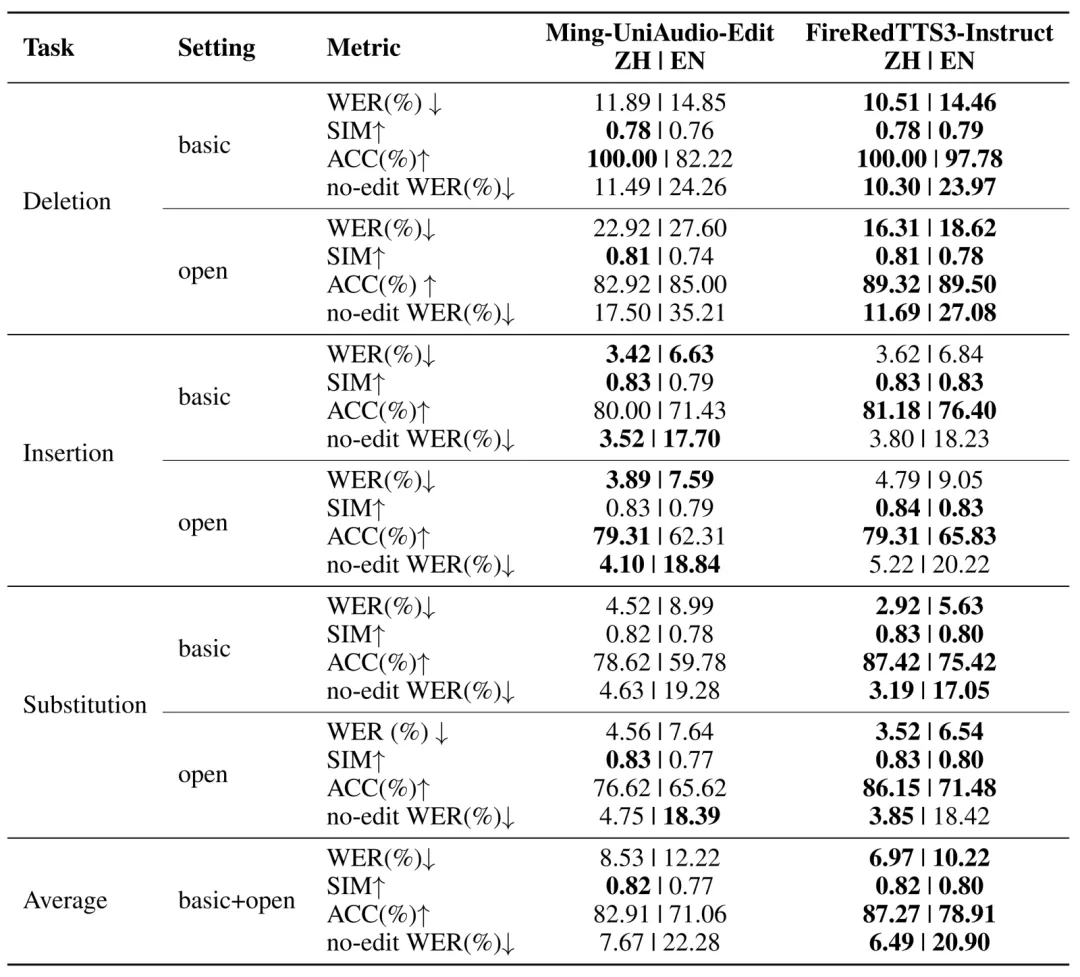
Figure 7 Mining-Freeform-Audio-Edit Semantically edited results
In the end, let the voice be as free as the text.
The first of the four lists is actually a plain judgement. The key to FireRedTTS3 is to bring the "suppression of error accumulation" down to the representation layer: using a frozen semantic teacher, injecting the semantic into the tokenizer stage with a continuous representation of RedAE, making stability an inherent attribute of representation.
As a result, sound cloning, sound design, and voice editing were for the first time integrated into the same simple set of LLM-DiT frameworks: tokenizer single-stage training, no additional semantic modules, no complex structures, but leading the way in four public assessment sets simultaneously.
From FireRedTTS, FireRedTTS-1S, FireRedTTS-2 to today's FireRedTTS3, the Little Red Book FireRed team has always been doing the same thing: building a growing voice generation infrastructure.
When both "generation" and "modification" are completed in a single sentence, the barrier to sound creation will be greatly flattened so that ordinary people who don't understand the acoustic parameters can also edit speech like text. In the future, the team will continue to expand the language and dialects, the boundaries of instructional control and editing, so that sound can truly be written, modified, and creatively expressed.
This is just the beginning of a path that "represents" as a starting point.