Currently, the field of physical intelligence is undergoing a rapid transformation in model architecture and algorithms. However, while the number of models has skyrocketed, the pain points of the gap in the scale are also increasingly highlighted: the industry lacks a unified, reproducible and truly reflective benchmark for evaluating model capabilities, and developers often find it difficult to accurately measure the real boundaries of a model with a specific shortcut.
In response to the industry's shared challenges, RoboColiseum, a standardized AI simulation assessment platform, was released on August 14. The platform aims to build a multi-dimensional system evaluation system that is highly consistent with real-time simulation evaluation, helping developers identify models' strengths and shortcuts, and continuously upgrades. The platform is open to universities, research institutions, model enterprises and researchers around the world, updating the results in real time, and is committed to building a set of credible outcomes and process-repeatable AI model evaluation metrics.
Since RoboColiseum's inception, more than 40 teams at home and abroad have trained and evaluated models on the platform.
This is the first time I've ever been in a relationship with a woman.
Focus on the Sim2Real bottle
Building high-fidelity simulation and real-time alignment
After entering the real world, lighting, materials, camera noise, contact with objects, and changes in the initial position and gesture of the robot can all lead to a decline in the performance of the model. Therefore, how to accurately measure the model's real capabilities through a simulation assessment remains a key challenge.
RoboColiseum builds on high-fidelity simulation environments that are highly representative of the real world in terms of environmental rendering and physical interaction. Test-tested, the correlation between simulation ratings and deployments is 89.5%, with less than 10% difference between the ratings of the same model in the simulation environment and the real world.
This verification link is also two-way: models using real-machine data training can directly submit simulation assessments, and models with simulation data training can also verify migration effects through real robots. The virtual environment and the real world can thus be connected in two directions, allowing developers to obtain high-confidence conclusions at a lower cost, significantly shortening simulation training, simulation evaluation, and improving the simulation cycle of simulation deployments.

Impersonating the high-level environment of the real world
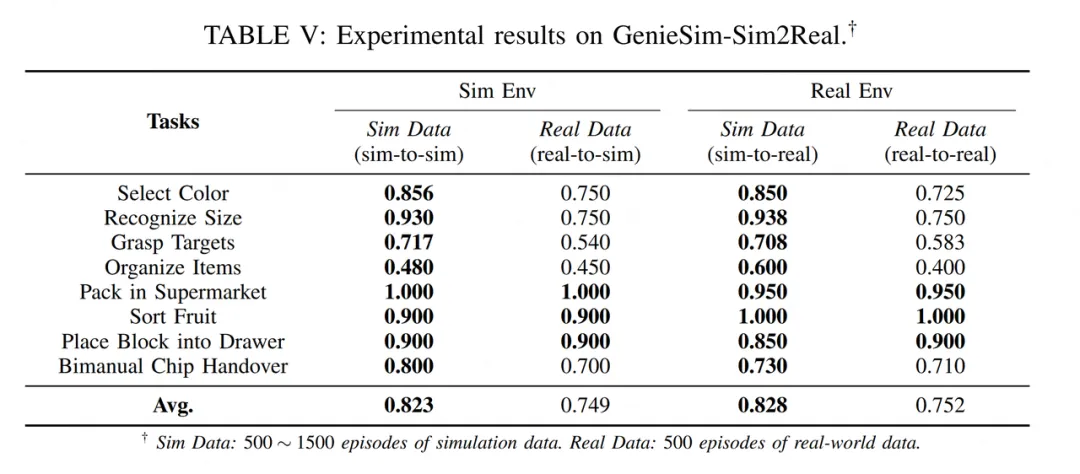
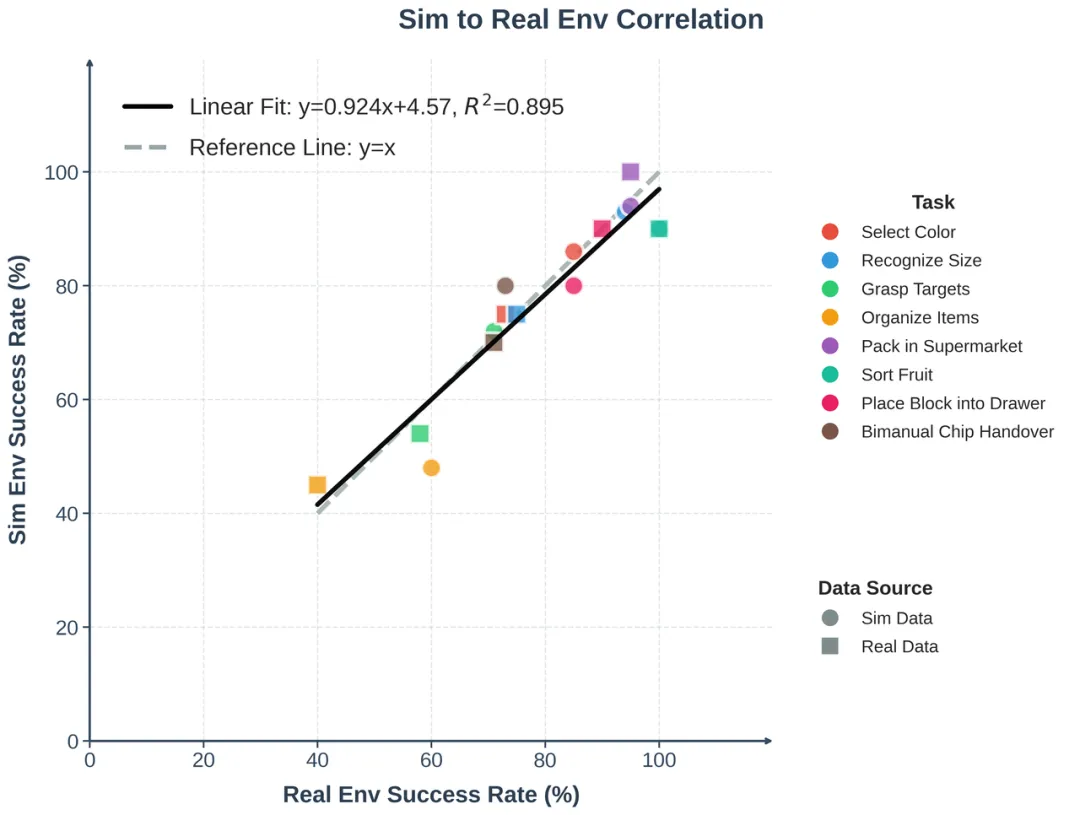
Sim2Real comparison of experiments
Farewell to the Single Success Index
Building a four-dimensional particle attribution system
Traditional assessments often generalize model performance using a set of comprehensive success rates, while RoboColiseum sets up multiple task sets around different capability dimensions, examining the performance of models in each dimension. Currently, the platform has introduced 4 sub-class capability lists, 78 high-reliability simulation assessment tasks.
4 Capability sublists:
Instruction Following is used to examine whether the model can understand natural language information such as color, quantity, shape, size, category, logic and common sense, find the target and perform the correct actions.
Spatial Reasoning is the ability of test models to understand information such as absolute position, relative relationships, size and sequence, stacking and spatial alignment.
By changing the background, lighting, materials, robot's initial state, camera position and image quality, and by diversifying the rewrite of instructions, the robustness of the model is tested by changing the stability and generalization of the model in non-ideal environments.
General Manipulation, which covers multi-step tasks such as opening doors, dropping, pulling, loading, sorting, organizing tables and two-arms collaboration, measures the ability of a model combination to use atomic operation skills.
In order to trace the cause of failure, each task is further broken down into multiple sub-steps. The assessment platform not only determines whether the final task is successful, but also records which steps the model has completed, at which steps it has failed, and its ability to generalize in different scenarios.
In assessing design, RoboColiseum reduces the chance of a single test by large-scale, diversified samples, and uses mechanisms such as domain randomization, training set and test set isolation, in-distribution and out-of-distribution testing, reducing models that rely on fixed layouts or data rules, avoiding shortcuts, and improving the stability of assessing results.
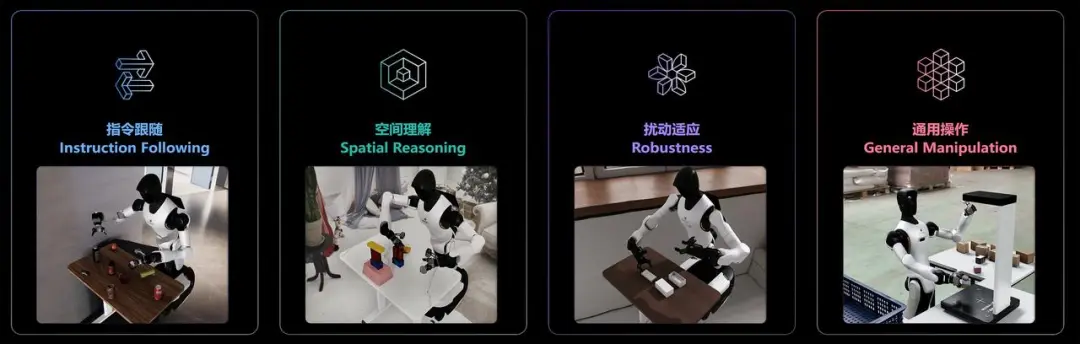
Four-dimensional rating system
One-click submission by an AI agent
30 Minutes to Get Results
For developers, high-quality ratings are often accompanied by complex environmental configurations, asset adaptations, and computational costs to build a complete and time-consuming rating chain.
RoboColiseum encapsulates these links into a suite of automated services. It takes developers just 5 minutes to register and submit, with a single-click deployment of the model and a 30-minute simulation assessment. The platform automatically returns scores, task step results, and model presentation videos that intuitively show how robots execute each task.
With AI Agent, developers can also complete data downloads, model training, local verification and evaluation submissions through natural language conversations. Model code and weighting are not uploaded, and evaluations can only be performed locally by deploying reasoning services and accessing standard interfaces, i.e. connected platforms.
5 minutes to submit the registration, 30 minutes to get the rating
Introducing the mainstream model baseline
Developers can reproduce themselves
RoboColiseum has provided baseline results for international body-based models such as ACoT-VLA,π0π0.5,GR00T. After submitting their models, developers can compare them to the mainstream models in four dimensions to quickly judge their strengths and weaknesses.
At the same time, RoboColiseum provides training code and corresponding weights for base-line models on platform tasks, allowing developers to self-replicate training and evaluation processes, verify base-line results, and conduct model contrast and follow-up research under uniform conditions.
Where did the name RoboColiseum come from?
The Coliseum originally referred to an ancient Roman circular arena, an open, neutral arena where anyone could climb. The Robo Coliseum was both a model-compared arcade arena and a developer's repetitive testing, positioning and continuous iteration arcade training arena.
The platform's long-term goal is to transform complex real-world tasks into standardized, reproducible, and sustainable updated evaluation systems, making evaluation a fundamental tool in the body model research and development process.
When models can be compared and improved under the same scale, the development of physical intelligence will also move from well-selected successful demonstrations to more reliable, transparent and verifiable real progress. The platform also expects more developers to open models and co-create physical intelligence ecosystems.
The RoboColiseum is now officially open and welcomes developers from around the world!