It's the first time in the history of the world.
LeCun has sent back the recommended, 10 million-downloaded Baidu open-source deity, and he's back!
4 months later, Baidu is officially opening a new generation of document analysis models.Unlimited OCR 2。
It is still light in weight.Total parameter 3B, with only 500M of actual activation per reasoning。
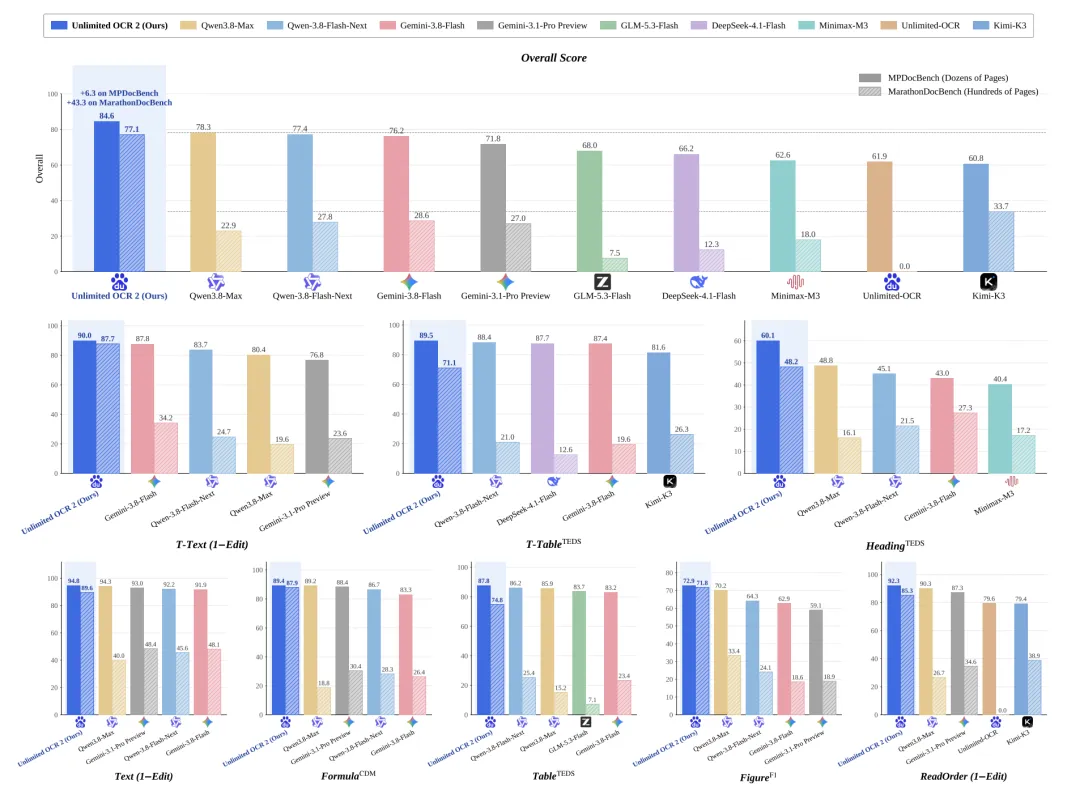
But it's this 500 million activated lightweight model that takes directly from the two great authority benchmarks.1st overall:
This is a list of all the different ways MarathonDocBench is credited in the databaseI got it.77.06 pointsIn the first place;
Multi-page cross-page benchmark MPDocBenchTake it off.84,59 pointsIt's the first in the series.
It's a great way to get a feel for the scores and the demo.
A total of more than 3,600 pages of PDFs have been uploaded to Unlimited OCR 2, including seven works by Harry Potter, from "Magic Stone" to "Holy Grail of Death".
At the bottom of the page, the page code in the upper right corner starts to go crazy.
The whole set was finished, and the watch took 1 hour and 30 minutes to look at, and it took an average of 1.5 seconds to fold a page. A total of 3623 pages were folded more than 3,000 times.
It's worth noting that the previous-generation model was limited to more than 40 pages; in just 120 days, Baidu directly limited the number of pages!
This means that whether it's a thousand-page full-length trilogy or a five-thousand-page compilation of four well-known titles, all of which can be uploaded from the first page to the last page without cutting chapters.
Even on the way to page 5,000, it flips almost as fast as page 3.
At the same time, the single-sequence KV display is more directly cut.96.2%A simple game card can run all over the place.
Currently, the model and associated weight are fully open source on GitHub and HuggingFace.
GitHub:
HuggingFace:
Breaking through the "unlimited page" zoneThree Devils, the last page of the test.Since the more than 3,600 pages of Harry Potter and the Deathly Hallows never explored the bottom of it, how deep is the power of Unlimited OCR 2?
We've just picked out the three extreme scenarios that are the easiest for a big model to roll over.
The first section, page 5026, contains four famous mirrors, creating a "cross-page brain circuit".The first step is to test its endurance limits and see how long it can hold a book.
We've made the dream of the Red House of the Western Yugoslav Movement into one.5026 pagesIt's a huge PDF, no book, no chapters, and the whole book goes straight into it.
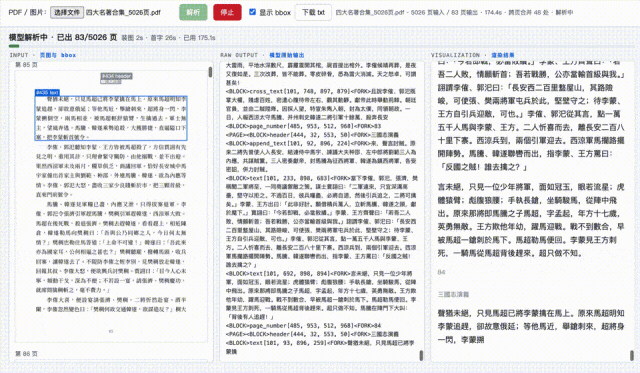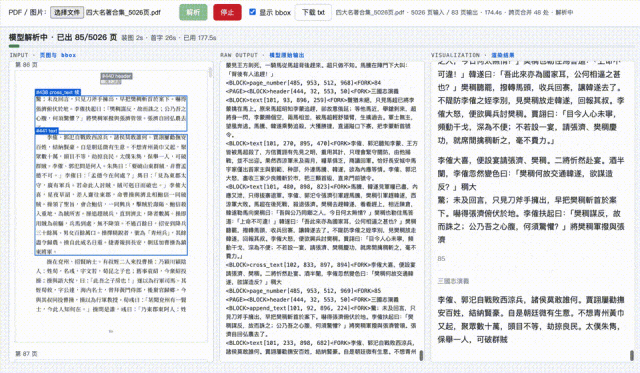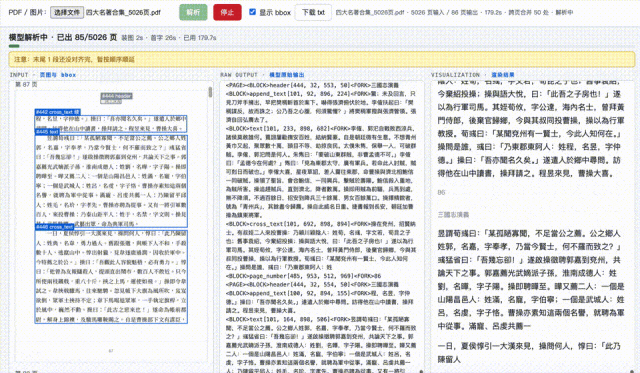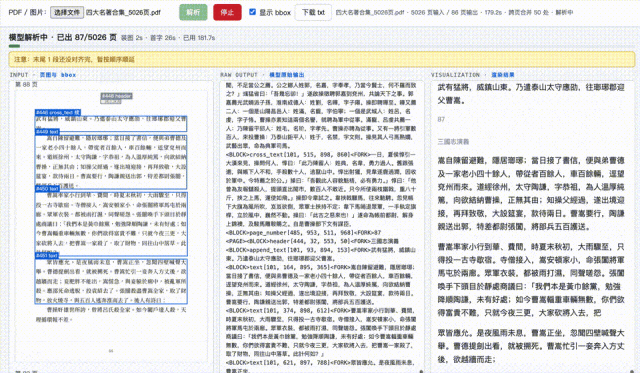
More than 5,000 pages have gone crazy, and the whole thing is neither cracked nor read.
In order to see if there was any confusion in the second half, we went straight to the last page of the progression bar.5026 pageCheck it out.
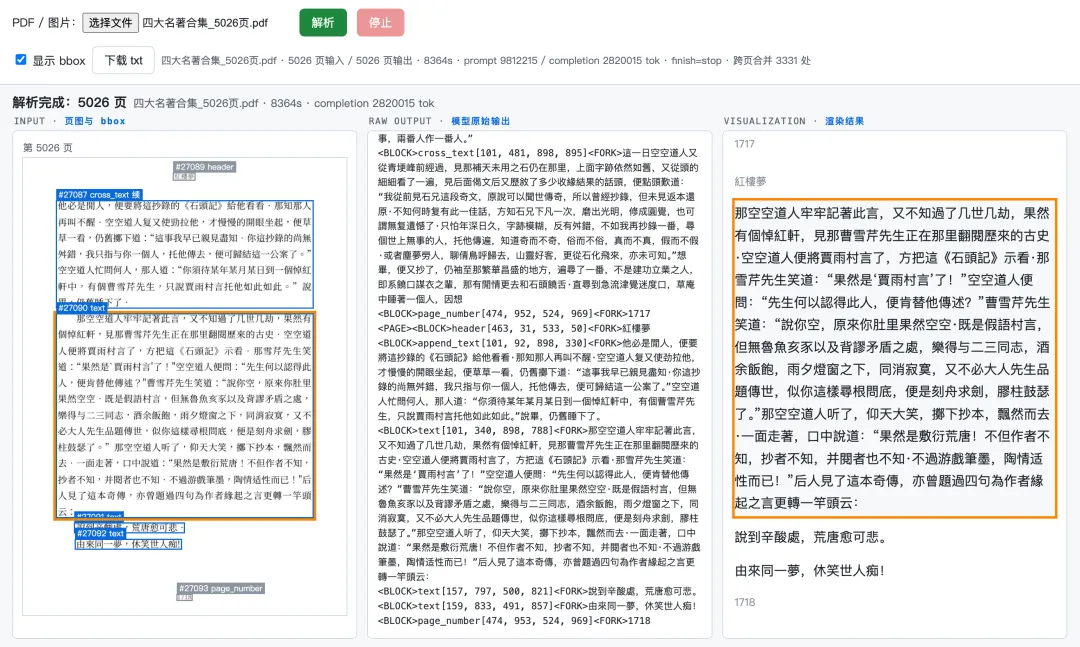
Turn the last page, and the output on the right side stops steadily at the end of the book.
"It's hard to say, it's ridiculous, it's sad. It's the same dream, let's make everyone laugh!"
But if you look at this, people who know how to do it will probably ask that the Big Four models are old-fashioned, shouldn't it be looking at the precedent based on the memory of "back-to-back brains"?
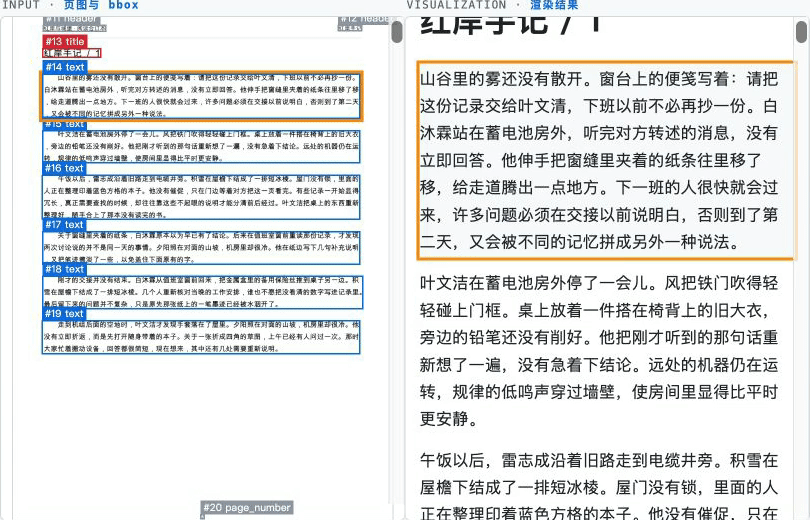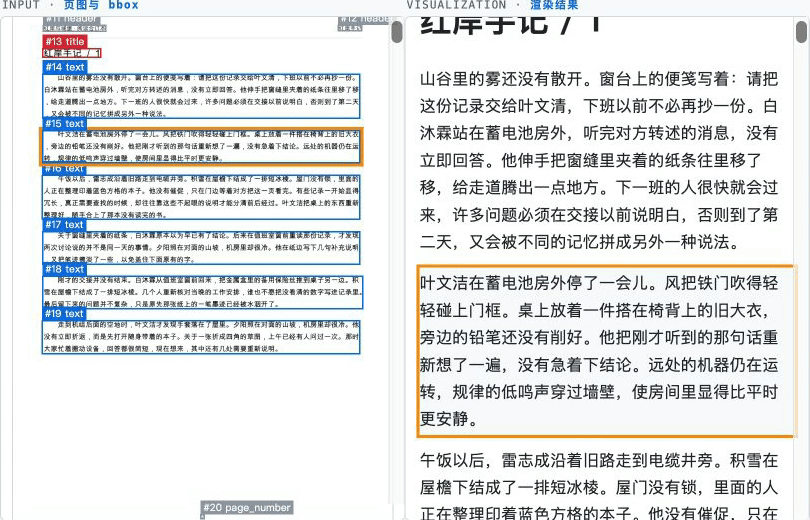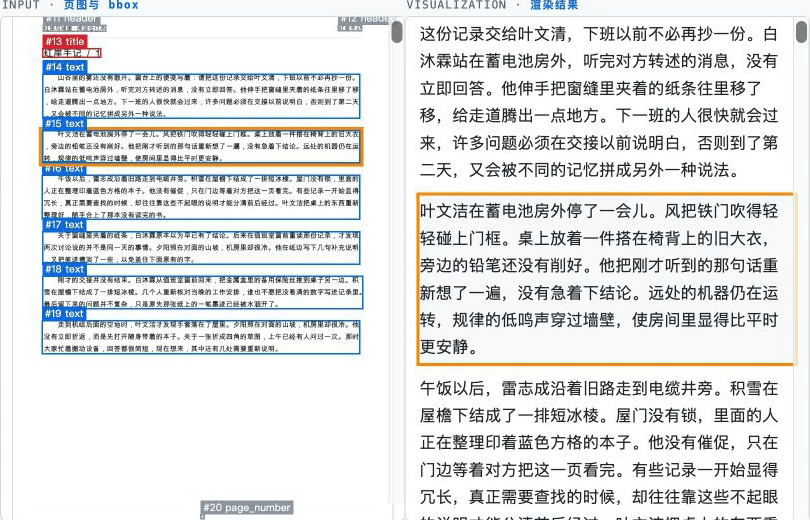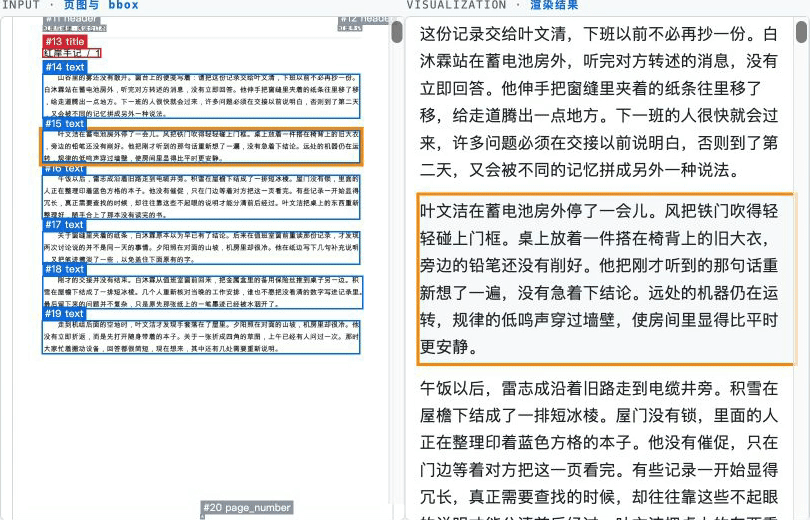
In order to verify whether it's a "real picture" or a "blind book", we specifically created an image.240 pages, 173,000 wordsThis is the first book in the series.
Between the second and the 237th pages of this long volume, we have divided eight deep spaces and buried them.Thirty-two traps.
For example, on page 2, Yvonne was mistakenly turned into a misnomer.I'm not going to lie to you.The same page still retains the normal "Yuen Jian" confusion. And at the bottom of page 237, we changed the page 742 to the dark side of the Magic Book.724 page。
Instead of the usual general model of "self-improvement", see these short words and familiar page codes and go back to your original "correction".
As a result, Unlimited OCR 2 ran a scan, and the second page, a false mix of "Yuenqing" and "Yuenqing", along with the "724th page" at the bottom of the 237th page, came out exactly as it was on the paper, the words unchanged!

What makes it so accurate, if the back of the book is excluded, that it crosses the page?
To test its cross-page judgement logic, we intercepted an entire cross-page "Don't Answer!" at the Triangle Shirtwaist Factory.1200 MHz pulse wave chartAnd buried in the context.6 sets of random anti-counterfeiting codes。
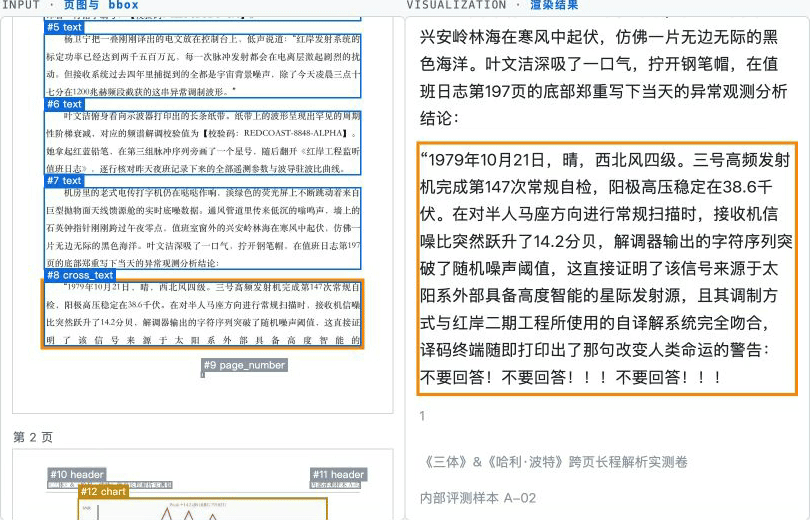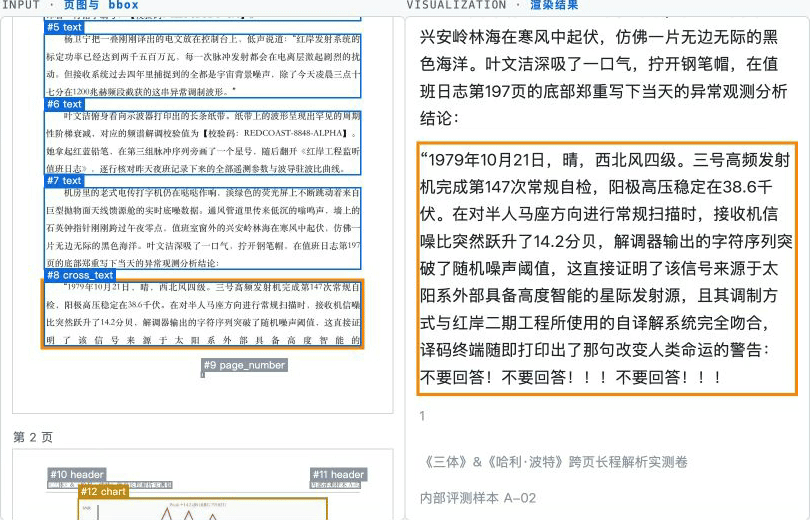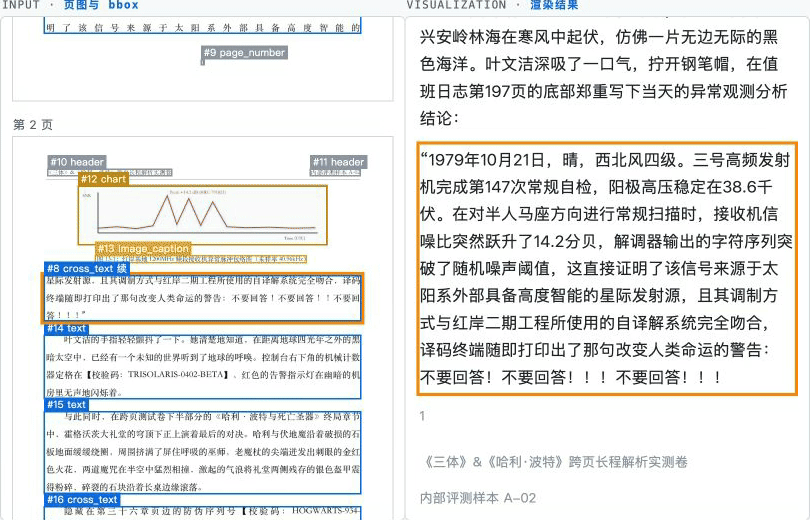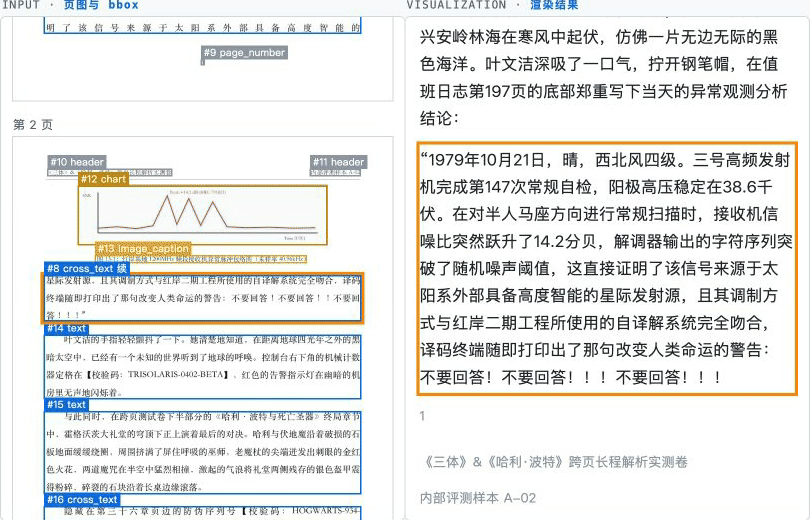
As a result, six sequences of random scanning codes all hit the same mark, and the semicircle at the end of the first page directly crosses the pulse wave chart, and the text below the second page graph is heavily fused into the same paragraph.
What's even more surprising is that by comparing the different editions, we've also been able to get the "hidden brain circuitry" that runs across the pages.
When the last line left blank on the right side of a page, the model strictly respects the version and concludes it as a paragraph.
Instead, it's only when the last line is like a real printed book.The two sides are aligned, full of right-hand borders, and the semantics are not complete.That's when it decides to trigger a cross-page merger!
The second installment, entitled "Win and Contract Assassins", is 300 pages long, with 9.25 million accurate copies.Five thousand pages of plain text is not hard to come by, and in the second link we focus directly on the most collapsed mining areas in finance, legal and auditing.Cross-page tables and digital assassins。
Those who have reviewed the book or contract know that the form is very easy to erroneously line up, and every page repeatedly has to be deleted manually and blindly; if you hide a few positive negative shoots in hundreds of pages of flowing water, it takes ten minutes to look at it.
We're going to create a direct response to this pain point.300 pages, 3,000 flooded hotels in totaland shrouded in darkness,A total of 176 negative hitsGet the whole bill in the bank account!
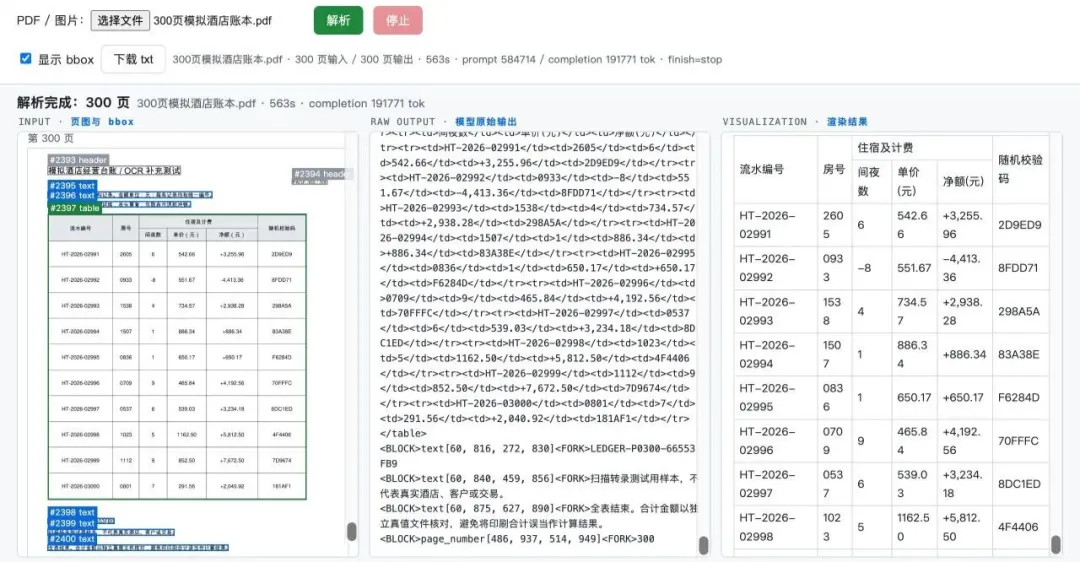
The 300 pages of the book were completely blown up, and each page repeatedly had its head removed automatically.
It's just that after we've written the script, we've been checking it out.There are 3000 records of 0 loopholes, 0 repetitions, 9,000 digital fields and 176 negative splashes without a row!
The total net amount is calculated by extracting all of the identified 3000 sums and reconciling them.$9,258,968.05Check with the original accountsIt's accurate to the point.
The third section, a 15-page English report entitled "Read Yourself".The long lines are not brainstorming, the tables are not sequential, and the last link comes back to test the most rigorous edition.Academic papers, classics and polygraphs。
The first sample, which we just released today, is from Baidu.15 pages of a single technical report in EnglishLet it "read itself!"
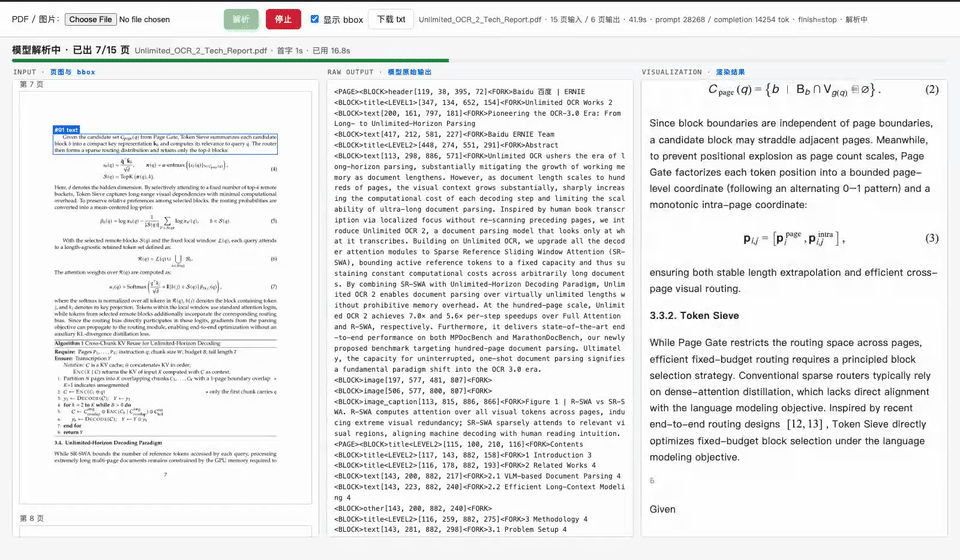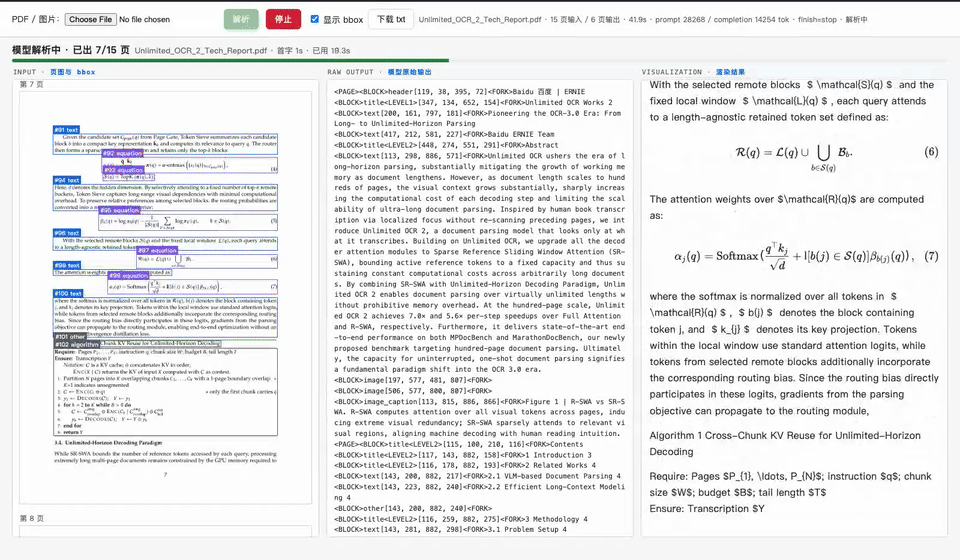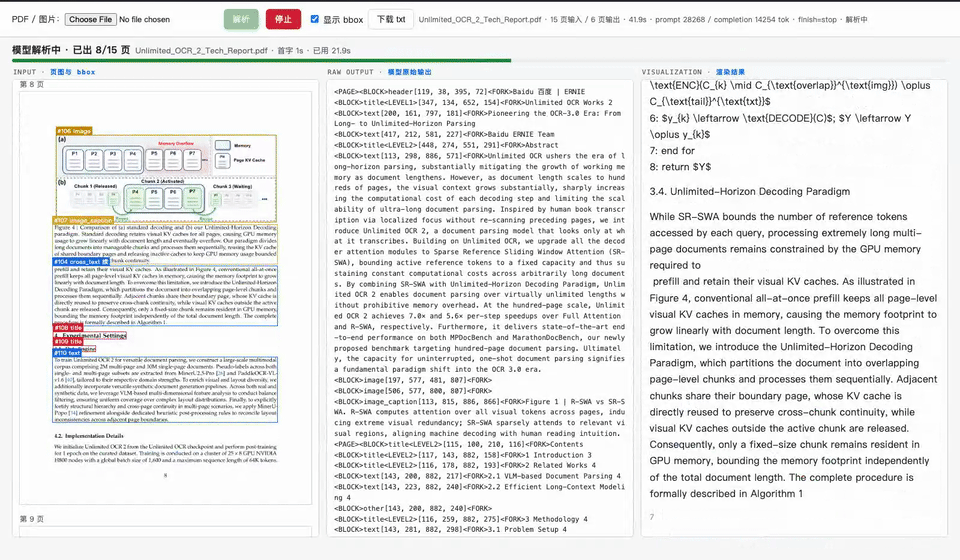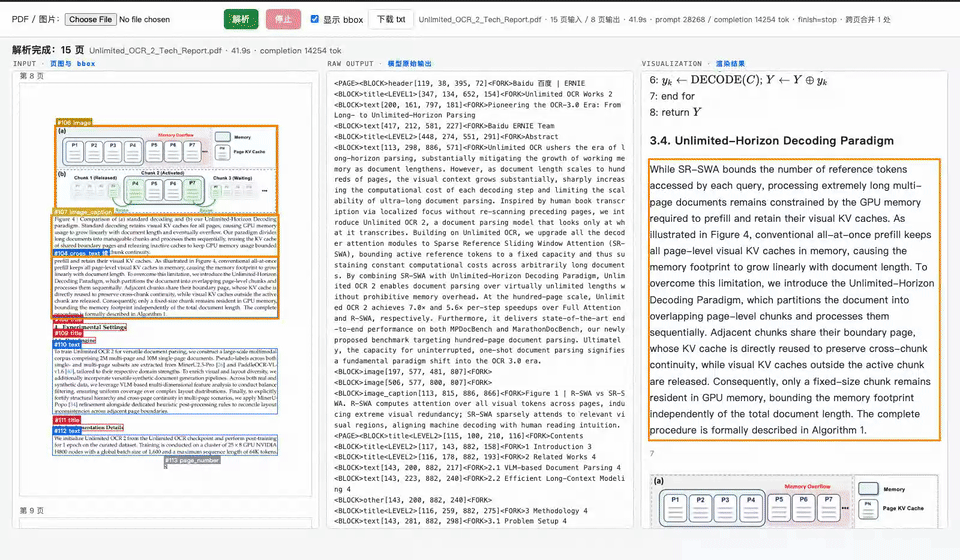
One of the most difficult lines in the entire report is found at the intersection of page 7 and page 8.
Here, at the bottom right corner of page 7, an English sentence is half-cut, while the top of page 8 looks directly at the half-page Figure 4 architecture and the six-line chart, the real second half of which is squeezed right underneath the graph.
In the face of this graphic barrier, Unlimited OCR 2 takes out a half-page chart and notation separately, and then follows it.The vision went directly across the whole graph, and the upper and lower half of the English section was tightly bound back to the same sentence!
At the same time, the paper's full-screen door control attention formulas and algorithm pseudo-codes were converted into direct compilation LaTeX source code.
It's a very complicated page and it's a very complicated page.Two-page non-symmetrical three-page foldingTwo pages of black and white papers, multiple graphs, cross-page continuity tables, and an extra bottom.6.8 pounds of small-letter footprintsIt's all in one piece.
Even if the page is so messy, the output of the left, middle, and side screen reading sequence is still clear and clear.60 table elements, inline formulas and four small footnotes, one by one corresponding to the original!
 Why Millions of Big Models in ContextOne hundred pages of PDFs on collective memory?
After looking at the three-point test above, a question arises as to why a hundred-page PDF should be collectively pulled instead.
One hundred pages of referenceMarathonDocBenchThe scoreboard is the most intuitive proof that Unlimited OCR 2 uses 500 million activation parameters.77.06 pointsIn the second round of the tournament, he finished second (33.74 points).2.3 times more。
In contrast, competitors on the same platformGemini-3.1-ProIt's falling.26.97 pointsIt was the first time the flag had collapsed when it was read on page 223.
Why would such a large window collapse? The root of the disease appears on a large amount of "visual tokens".
Because thousands of visual tokens are blown up every page in PDF, and with standard attention, every time the model writes a word down, it has to recount all the visual tokens on the previous page!
It's like transcribing a book to 200 pages and rewriting the original 199 pages every time you write a word.
The resulting cost is that the document will be increased from 2 pages to 100 pages, and the single-step decoding delay will be reduced from3 millisecond storm to 27 millisecondsHundreds of pages of unrelated pixels poured in, allowing the model to completely "walk God" in the second half.
It's the human instinct to be a copyist.Write in the SR-SWA Rare Attention
Since "full page counting" is a dead end, how does a human copyist usually work?
When people copy thousands of pages in large parts, more than 95 percent of the time they only do so by hand; they are accurate only when they copy the page or need to verify the name of the person on the previous graph.
I'm going to wear it.Information within a single page is highly concentrated and cross-page visual associations are extremely rare.
Following this most simple instinct, the Baidu team came up with a second-generation killer.Rare reference sliding window attention (SR-SWA)。
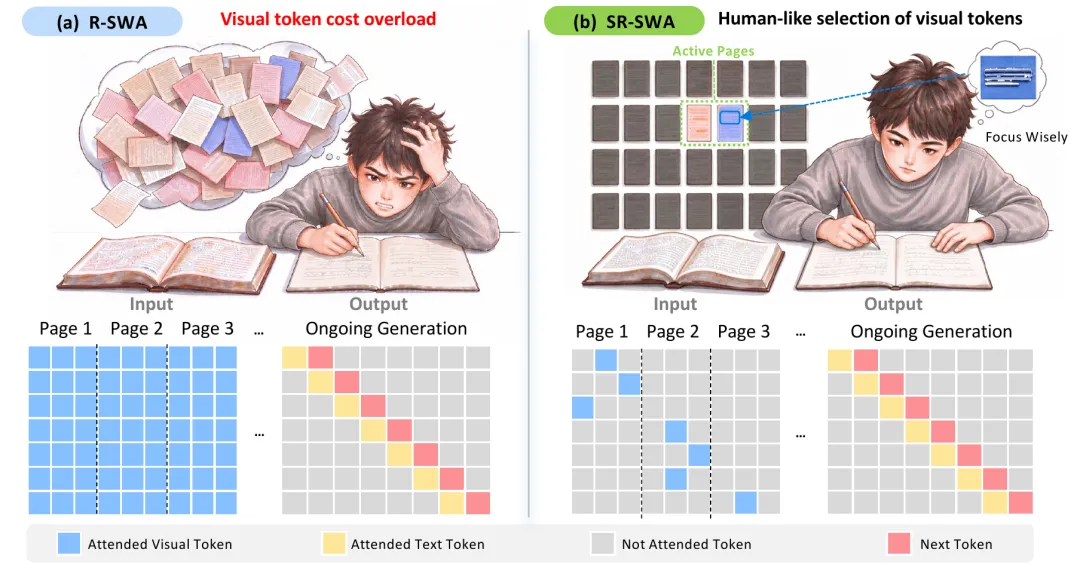 First circle, then focus.
For Harry Potter and the Philosopher's Stone, Harry Potter and the Philosopher's Stone, in the seventh volume of Harry Potter and the Philosopher's Stone, the SR-SWA calculates the quantity in just two steps.
The first step is that when the model reads a line from the final battle, the first step is that the model reads a line from the final.Page Gate (page gate control)Start with "circle scope" and narrow the view from a few thousand pages to a few candidate pages.
Step two:It's the first time I've seen this.In the candidate page, the "pick focus" is scored in real time, and only a few of the most relevant visual blocks, such as the "blitz wound" or the "soul machine", are taken into account.
Unlike the rare scheme based on "distillation simulation", this set of filters takes a direct part in front-to-back computing, and the OCR transcription gradient can be relayed end-to-end.
In other words,It's all about the instincts that the model has trained in the real world of copywriting.Whether it's 10 pages or 5000 pages, the amount of visual information calculated for each step is limited to a fixed constant.
Unlimited decoding mechanismsAfter locking one-step arithmetic to a constant, the team backed out."Unlimited-Horizon Decoding" is the name given to an unlimited decoding mechanism.The walls were demolished by hand.
It operates like a seamless transceiver that moves the oversized document through the window.Only one page ("Boundary Page") is left between adjacent windows to directly duplicate KV cache.Make sure that the passages and continuity of the tables continue to flow around the page.
Once the current window is transcribed, the cache of the historical window is immediately physically released from the display, effectively making it "side-reading thrown, light-mounted".
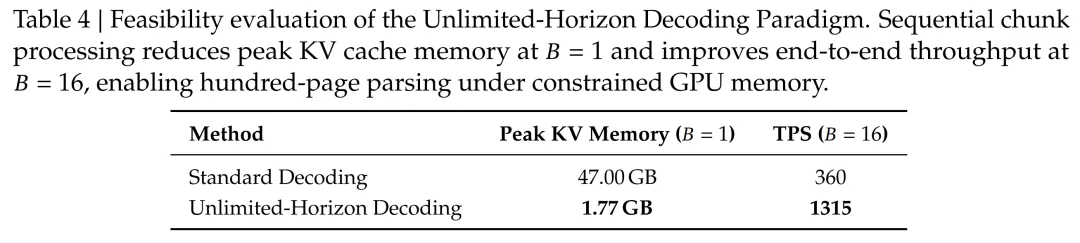
Both designs pierced the hardware thresholds of long document reasoning across the floor, resulting in three core jumps in a 100-page test set.
Single-sequence peak KV shows a sharp decline of 96.2%From the standard decoding,Pressed directly to 1.77GBIt's easy to use and it's easy to use.
16th Streetand distributedIt's 3.65 times as fast.It's been a long time coming.360 TPSRising to 1,315 TPS;
One hundred-page single-step decoding is 7.0 times fasterMore attention than the standard.That's 7.0 times faster.More than the R-SWA generation.It's 5.6 times faster。
As the document expanded to 300 pages, the general flag accuracy jumped, delayed cranking; only the Unlimited OCR 2 accuracy was as steady as the horizontal line, decoding the delayed flight.
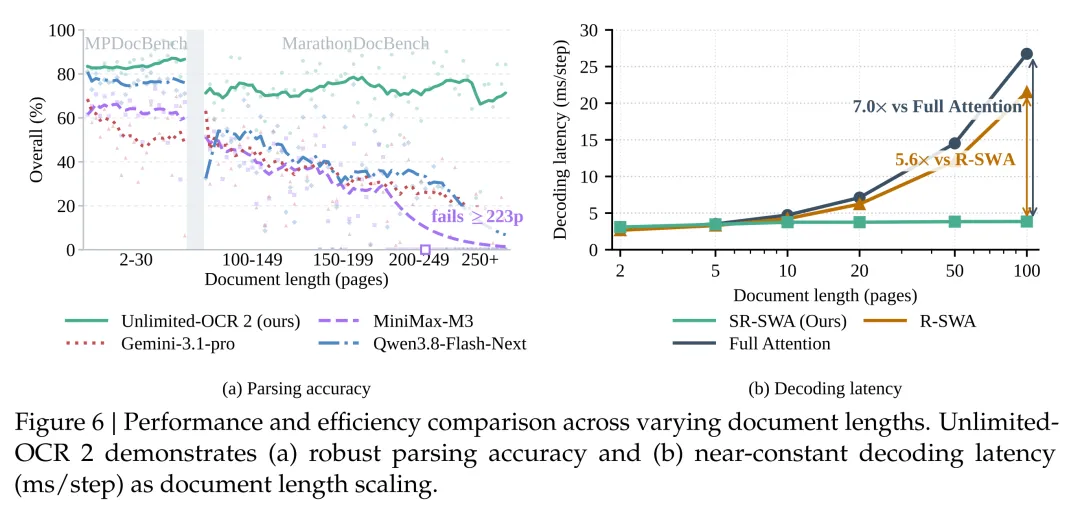 This is OCR.The Infinite Sword System crashed the OCR 3.0 gate.
The first page of the hard-core technology report opens with the first quotation printing a laughing-out-loud "song" that makes polar beings laugh.
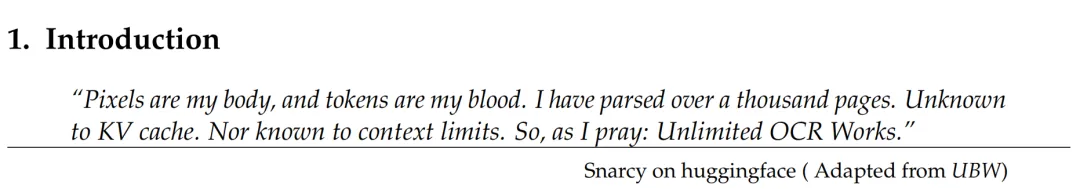
Pixels are my body, and tokens are my blood.
I have parsed over a thousand pages.
Unknown to KV cache, Nor known to context limits.
So, as I pray: Unlimited OCR Works.
The old two-dimensional and polar characters can be recognized at a glance, and this is the inherent boundary chant of the Fate/stay night anime classic."Unlimited Blade Works" is the title of the book.。
As early as the first-generation model was open source, a developer named Snarcy took a look at the naming scheme in the HuggingFace review area and changed the script to an OCR version.
I didn't expect the Baidu team to see the treasure, which has been treasured to this day, printed the first line of the quotation and re-signed the netizen's ID when they released the 2.0 technical report today.
The word "unlimited" is also used in document analysis.OCRThe age of 3.0.It's a sign.
While the AI circle was still pushing millions of Tokens' PDF analytics bills for closed-source models, Baidu used this 500 million activated small model to push the upper limit of long-document analytics directly to "unlimited".
Remember that at the end of the original paper there was a perspective that if the model learned to automatically flip a page, OCR would no longer be identifying a page of text, but reading the whole book.
Today, whether it's hundreds of pages of tender books, thousands of pages of engineering logos, or 5,000 pages of biographies, the prospect of cutting machines into pieces is no longer needed.