Once the model is deployed to the elevated NPU and the computational logic is determined, there is another difficulty: how to make the underlying hardware fully utilized? The same attention is paid to the calculation, segmentation, transportation, parallel and synchronization methods, and the running time can be significantly different.
Large models can generate code, and coding agents can call tools, compile operations and iterate modifications, but when faced with a hardware platform with insufficient knowledge reserves, how should they complete the entire process of compilation, error-correcting to performance optimization, and then apply the experience to the next algorithm?
From Experience to Expertise: Adoption-Aware Memory Learning for Data-Scarce NPU Kernel Synthesis
Link to the paper:https://arxiv.org/pdf/2609.35568
One, from code generation to high-performance implementation, what else is missing?
1. Why does the development of arithmetic require hardware experience?
The calculations of matrix multiplication, integration, and attention in deep learning models are ultimately executed by the program on the hardware. The kernel is responsible for the underlying implementation of these calculations.
For engineers, optimization often involves several types of judgments:
Data segments: A volume cannot always be stored on a single chip, and must be broken down into appropriate sized blocks; blocks that are too large may exceed capacity and too small may increase transportation and scheduling expenses.
Parallel allocation: whether tasks can be allocated to more computational nuclei, whether nuclei are balanced, and whether only a small number of nuclei are used.
Transportation and computation: whether to reduce the repetition of intermediate results, or to prepare the data for overlap with computation.
Synchronous dependence: which waits are necessary to ensure correctness, which waits are too conservative to limit the flow of water.
These choices interact with each other. Changing the partition may require rearranging the buffer zone; increasing the parallelism may change the synchronous relationship; reducing the one-time movement of the data block, or may require adjusting the reading method of subsequent computation. A viable implementation is just the starting point for performance optimization.
2. How did Agent complete this development process?
The Coding Agent in this article is a coding assistant capable of writing code, calling tools and developing large models based on feedback modification.
Produced implementation: According to input, output, and computational logic, organize host-side configuration and kernel-side code.
Compilation Repair: deals with interface, type, template parameters, and configuration issues to get executable candidates.
Accuracy verification: Running on real equipment, comparing with reference results, checking for numerical errors and operating anomalies.
Performance Optimization: Establish the correct version of the timeline, locate the bottleneck, and try to implement faster.
Each modification may reintroduce errors, so the optimized candidate will still need to be recompiled, verified, and measured. Less than once, the process may be faster, or it may read data that has not yet been written; multiple cores may simultaneously increase throughput, or may disrupt job allocation. Performance gains must be based on correct passing.
This also means that the agent needs not only the ability to generate code, but also an understanding of diagnostic information, selection tools, preservation of test records, and identification of repeatability from multiple attempts.
3. What progress has been made?
The development of large-scale model algorithms has created several complementary pathways. Understanding the problems they solve helps to understand the starting point of SAGE.
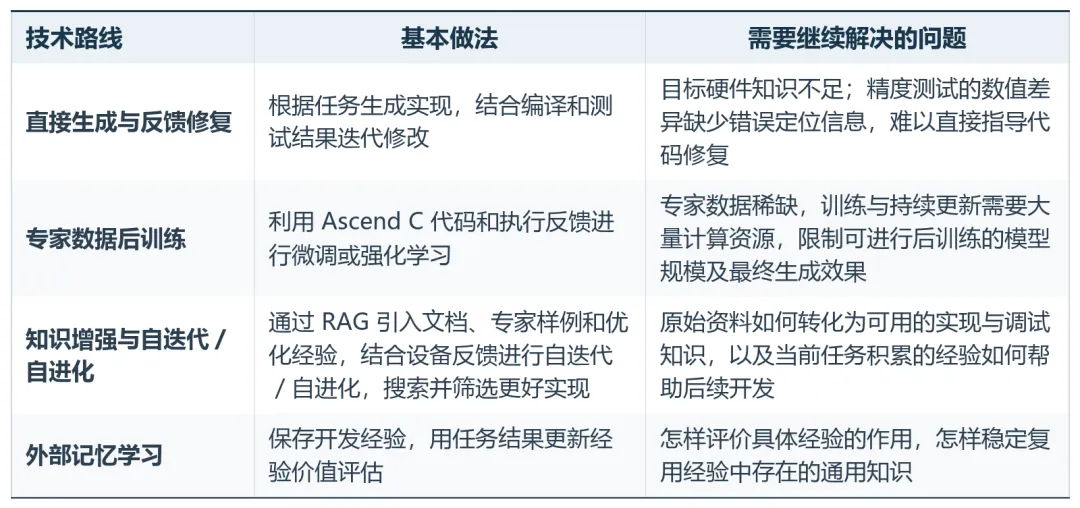
These routes have allowed models to move from generating chips at a time to verifying chips repeatedly on devices. However, on platforms with fewer open source code, a fundamental difficulty still needs to be solved: the ability of a model to be familiar with the platform cannot be directly equivalent to its ability to develop on new hardware.
According to a research report cited in the paper, GPT-5.2 has a CUDA accuracy rate of 92% on KernelBench Level-1 missions, asc.