It's the first time in the history of the world.
74 billion parametersAIIt's 22.1GB, and it's right in the laptop!
Just recently, Intel has unveiled the model weight of the Nemotron 3.5 Bolt. It was originally about 148GB, cutting down about 85% by one breath, targeting 24GB local deployment.
You can see the charts, write the code, call the tools, and this time the notebook is live.
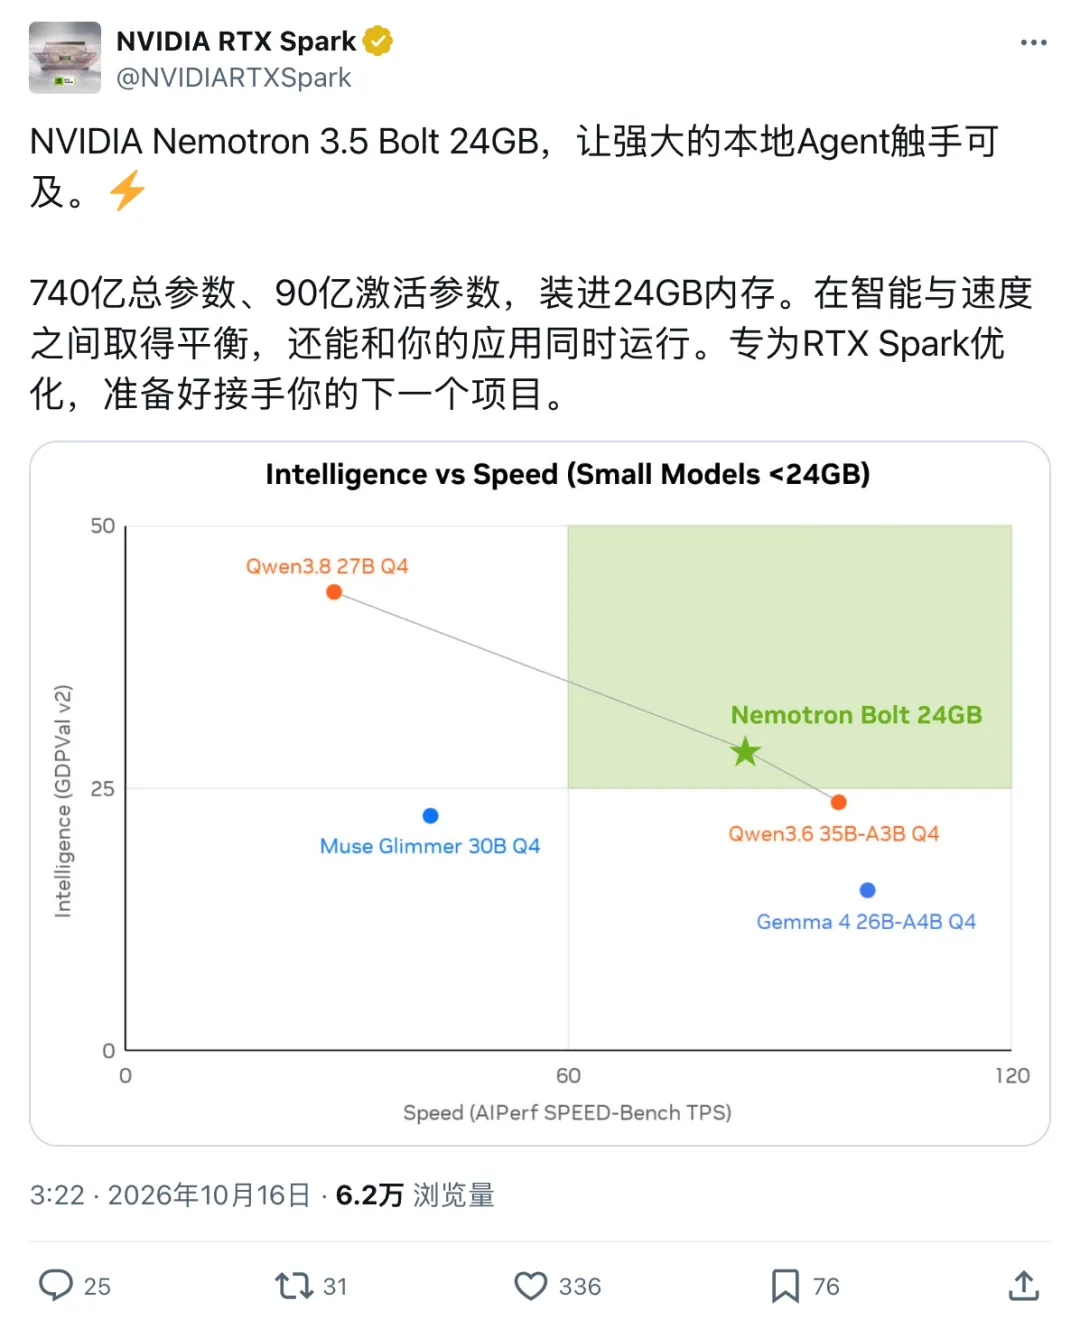
Ollama has given access to OpenClaw. Agents can read files on-premises, modify code, and logical models can also run on-premises, with less time to run in the cloud.
The model was released and the computer went on sale.RTX Spark laptops are available worldwideThe new aircraft from manufacturers such as Lenovo, Microsoft and others are officially on the market.
The big model and the new computer, the old yellow one, came together.
The Dragon's Brain Moves!The phrase "help me change the code" comes to the agent, often with a few rounds of work. Read the files, find the location, move again, run the error report, and come back again.
Every step of the way, the model behind it may have to rethink it. If all reasoning is in the cloud, these requests have to go back and forth.
What Bolt wants to do next is:These can be kept alive on a computer every day.。
It does.Each generated token activates about 9 billion parameters.It also supports tool calls, image and video inputs, and can read both code and graphs.
During the training, the team lets it get into the operation of the simulated environment practice tools, learning less to twist, less to do nothing.
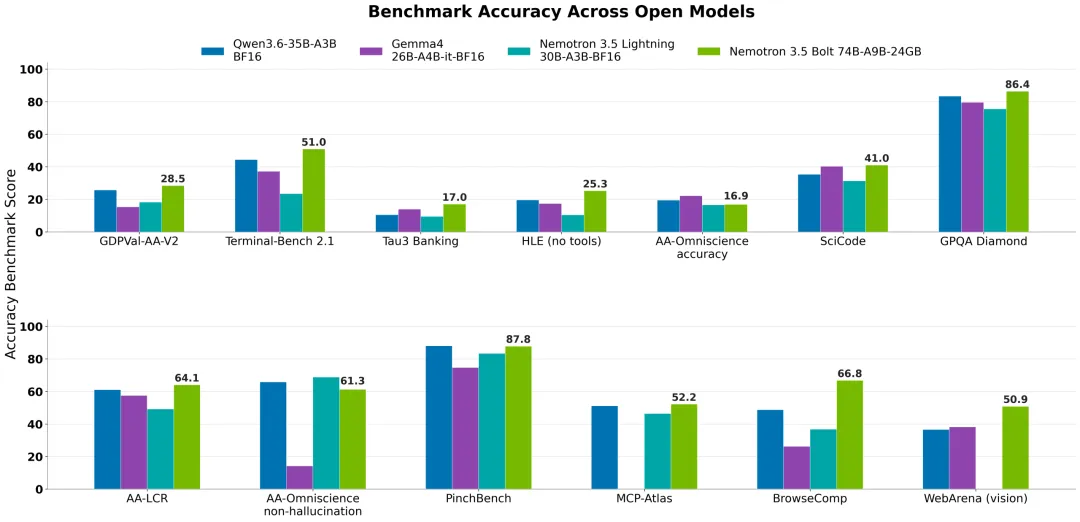
The final quantum version of Bolt, which tested the operation of the terminalTerminal-Bench 2.1 receives 50.98%I'm not sure what I'm going to do.BrowseComp took 66.75% of the vote.These are the two things that Agents have to do while they're alive.
Ollama has listed the start-up gateways for OpenClaw, Hermes, and other frameworks. Developers can give familiar agents a local model, search the Internet as usual, and give reasoning to their computers.
In this way, the documents, tools and models responsible for reasoning can meet on the same computer.
148GB is compressed to 22.1GB!
Bolt's bottom, from this release togetherAccording to the report, the number of vehicles used in the production of the VL is estimated at 120 billion.The latter activates 12 billion parameters each time, enabling enterprise Agents to read, view, and call tools, including charts, documents, and videos.
Companies can also continue to train it with their own data. In the hands of the financial platform Ramp, it is sent to recognize the bill, organize merchants, dates and payment information into program-readable data.
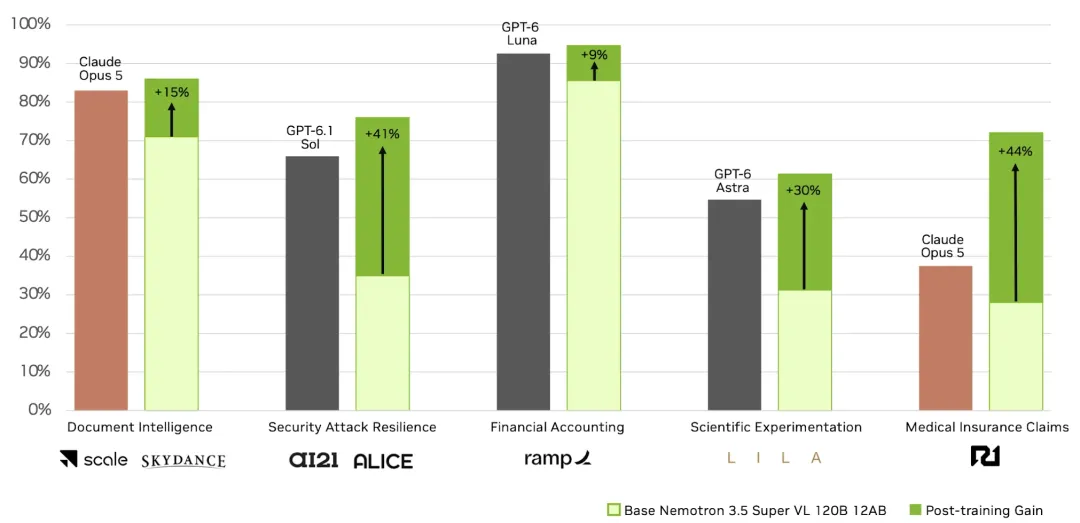
It was Bolt's turn to get the "Big Brother" to live in his notebook. The original model structure, pressed from 120 billion parameters to 74 billion, then rehearsed the damaged capabilities.
Problems appear on the screen. The front compression only moves the language part, and the restore training also preserves the writing ability; the original visual module comes back, and the shortened bottom has to be re-polished.
The problem arises when it finds a target on the screen as instructed: in the ScreenSpot Pro test, the parent model scores 41.6%.Bolt, who had just been compressed and had not yet completed his visual training, dropped to 0.。
So the team first used about 6.6 million images per round to train the visual adapters, and then to fine-tune the visual tasks.It's going back 39.79 percent.It's a lot of weight loss, and it almost saves "eye strength" as well.
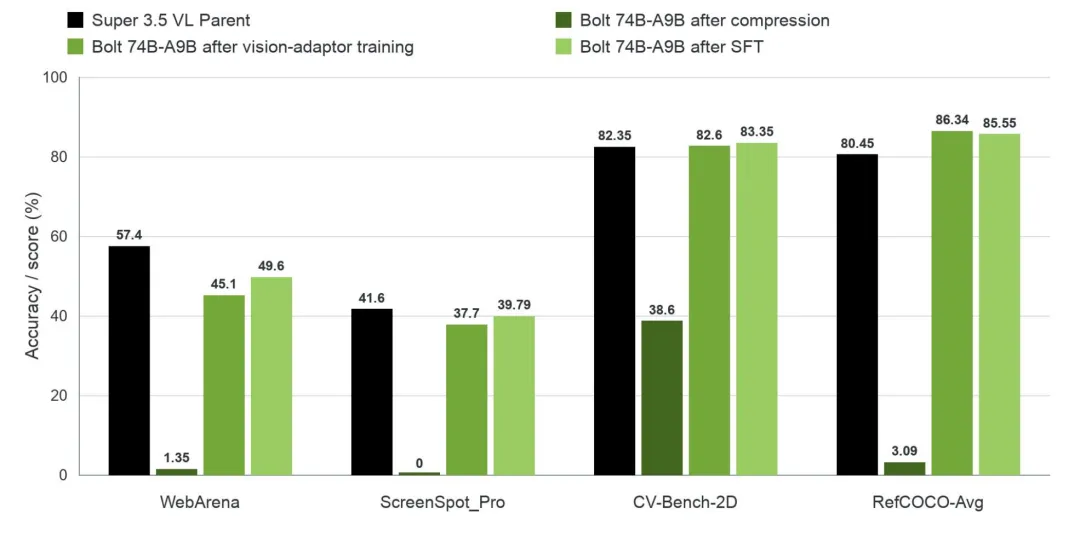
The power of the eye has returned, and the volume has not been switched off. 74 billion parameters are stored according to the BF16 accuracy, the light weight is about 148GB, and even RTX Spark laptops with up to 128GB of unified memory cannot be loaded.
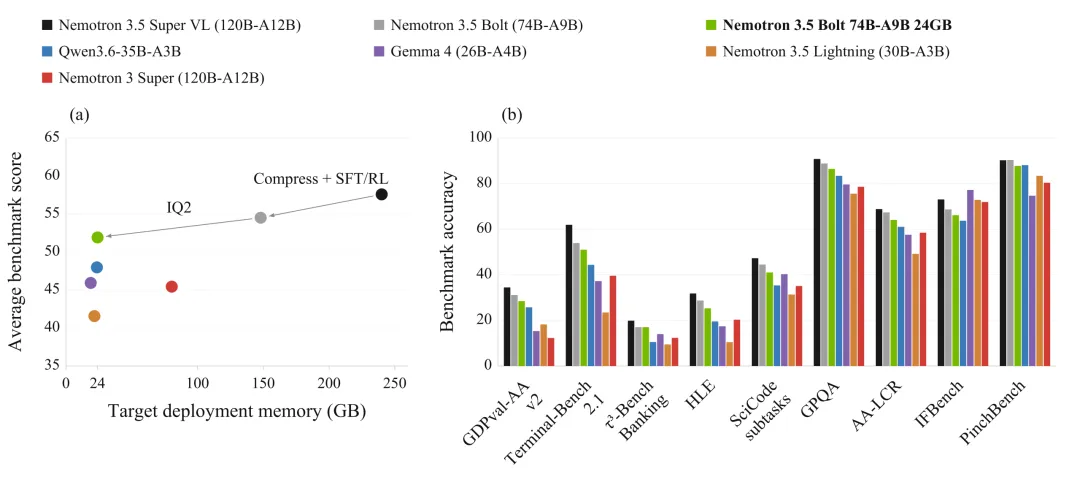
Next, each parameter takes up less space.The expert's weight was squeezed to about 2 bits.Other parts retain different accuracy and use "quantitative perceptual distillation" to supplement the teacher model in an attempt to recover the loss of accuracy.Weight is finally down to 22.1GB.。
In this group of experiments, with the same memory budget, the large models were trained to lose weight, but they had a higher accuracy rate than the small models were trained from scratch and then quantified by 4 bits.
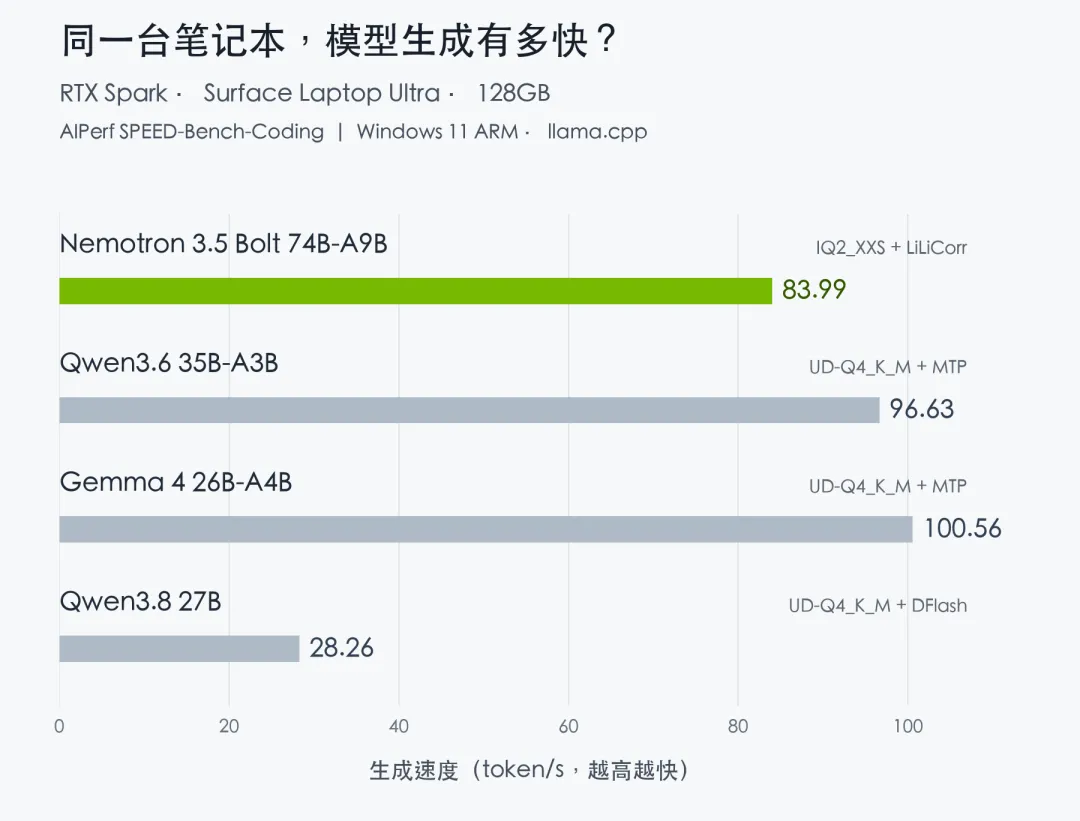
Bolt asked for a small model called LiLiCorr to be drafted first, and the main model was accepted in batches, reducing the wait for each token to be generated.
In a code-generation test at Intel, the Surface Laptop Ultra, a 128GB version of the RTX Spark, allowed Bolt to run.About 84 tokens per second。
When you actually install a computer, you should also keep caching, visual modules, and small accelerator models in place.32GB of memory or unified memory can be used as a planning starting point, with 48 to 64GB more room.It's just a weighted bill, 22.1GB.
128GB new worldwide release, old yellow soft hard
RTX Spark's computers were sold out, and it was time for these models to come into play. Blackwell's RTX GPU and Grace CPU were integrated into a superchip that shared the CPU and GPU.Maximum unified memory of 128GB。
The model is very thin, and the computer has a tight spot on this side. Both sides are pushed forward, and local agents are easier to run.
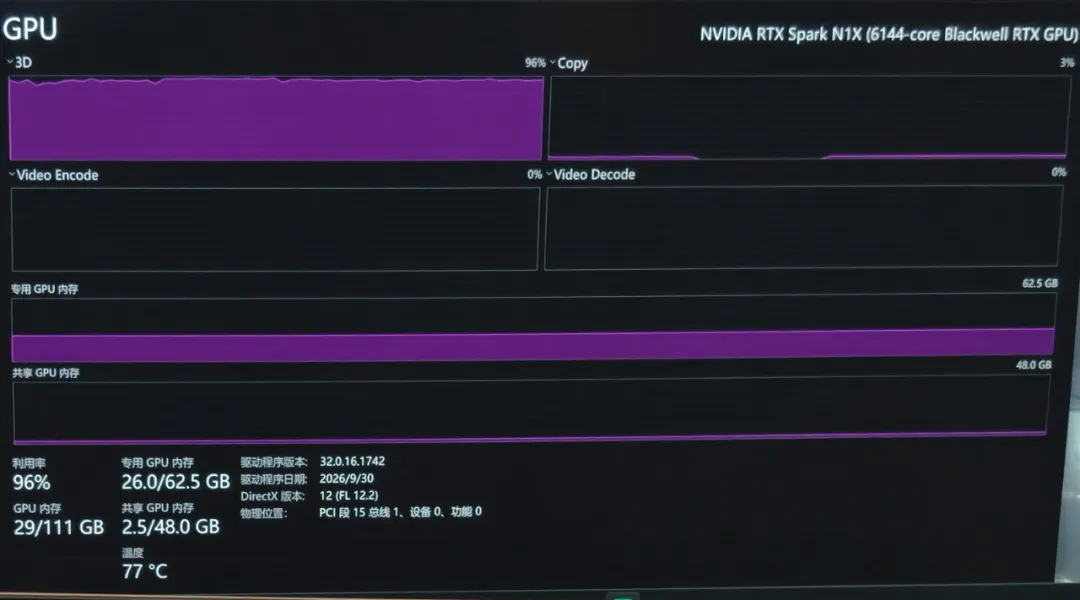
Artificial Analysis took a larger model to test the threshold.The light weight is 77GB.。
The 64GB MacBook Pro and 32GB RTX 5090 were unable to be installed.The 128GB RTX Spark laptop is still running.。
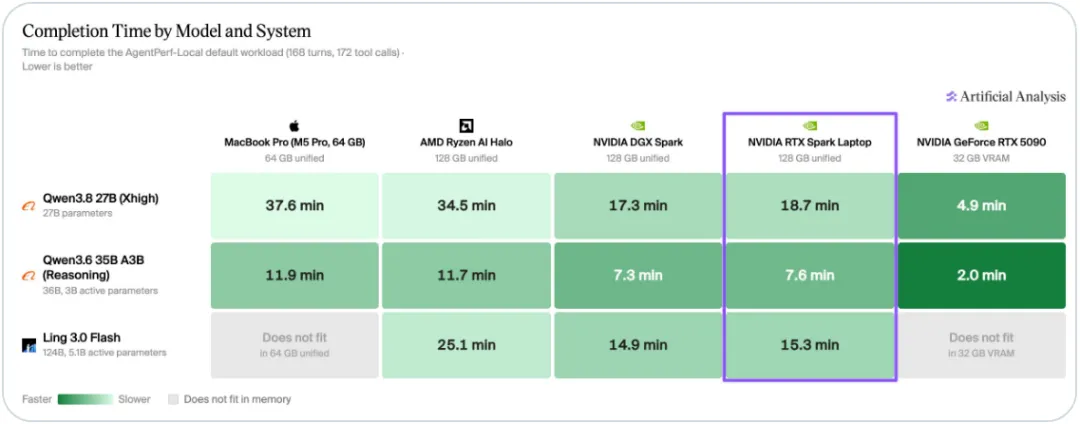
The flagship graphics card will also experience this embarrassment: it's faster, the model is too big, so it can't enter the door.
Invisalign also included OpenClaw and Hermes in the application ecosystem at the time of launch and provided guided installation. In order to get more people to grow lobsters, the first line can never pre-examine the environmental configuration.
In addition to raising dragonflies, the computer also takes care of the original live. RTX Spark initially supports hundreds of games, Photoshop and Premiere's native support is also available through the initial test version, completing AI tasks, and playing games after clips.

There are 74 billion parameters that are not large, and there is a smaller one.Nemotron 3.5 Bolt E4B 4GBThe program will be launched on October 23 and will focus on local voice assistants, interactive roles, and more.
Super VL takes over the complexities of the company, Bolt moves the daily tasks of Agent into the notebook, and E4B takes care of the lighter equipment.
Old Yellow's calculator is also clear: open the model, allowing more AI tasks to be used on the user's GPU; open the new computer, and take over the demand.
After buying "productivity tools" for so many years, the desire of workers to work can be a little bold:
"Computer, you're busy first, I'm off".
RoboInd editorial channelResearch, robotics companies and market intelligence for cross-border sourcing.Explore the channel ↗
Share this
End of editorialExplore more from Global Robotics News ↗