The first author of this paper is from the University of Xiamen's Space Perception and Computing Laboratory (ASC Lab) Class of 2025, Ph.D. student Wang Haiyan, Master's degree Liang Xiaojing Class of 2025, and the author of the communication is Shenzhen Vice-Professor of Xiamen University, and was co-authored by Zhang Haiyan, Hu Huangwei, Wang Shicheng, Matsunbango Vice-Researchers, Prof. Wen Wencheng, and Prof. Wang Chen.
How many people who use large models have experienced this: an AI that can't do anything, calls several AIs to "meet". Write code, you can have an AI write, measure an AI, change an AI; answer questions, you can have several AIs look at the data, then summarize the vote.
But you'll soon discover a stark fact: teamwork is easy, deployment is difficult. The same AI, who leads, who makes conclusions, who listens to who, how information flows. This set of "organizational structures" directly determines the team's fighting power.
So the question is: can this set of "organizational architectures" allow AI to learn by itself instead of having engineers draw at night?
FlowMAS has been adopted by the NeurIPS 2026 Machine Learning Summit: transforming large model multi-intelligent "architectural design" into a learning generating problem. Using the generating flow network (GFlowNet) as an engine, combined with the two weapons of "curiosity" and "information theory", the AI team's method of building for the first time is both automated, diverse, and cost-effective.
FlowMAS: Learning Multi-Agent Workflow Topology through Information-guided Generative Flow Network
Link to the paper:https://arxiv.org/abs/2609.37151
What is the "organization architecture" of large multi-intelligent models?
The object of the paper's study is called the large model intelligent workflow topology (LLM agentic workflow topology).
A node is an "algorithm" that can be understood as an AI employee with specific tasks, each with models, prompts, tools, and internal working patterns (such as mind-chain CoT, self-reflection Reflexion, programmer Programmer);
The side represents the message from whom to whom.
More complex organizational structures are composed of three basic "blocks":
Chain: a flowing waterline, with one end connected to the other;
Fan-out: A task assigned to multiple AI parallel explorations;
Fan-in: Multicast information is integrated into a single node.
Like Lego bricks, these three basic pieces can spell out arbitrarily complex structures like trees, shapes, and levels. The central question for the paper is: how to automatically generate the best spelling from a combination of explosive "spellings" in the face of a specific task?
Four gates, each with "inner wounds"
Before that, the academic community had explored four routes, each with its own pain points:
Craftsmen (MetaGPT, LLM-Debate, etc.): Senior engineers with experience in hand drawing architecture.
Search groups (ADAS, AFlow, etc.): Repeat trials and errors, iterative assessments in a huge design space. It works well, but it is extremely "burning money" and every single architecture needs to actually call a large model, tokens like water flow; the more calculators available, the easier it is to "fail" to search.
Text gradients (OneFlow, etc.): let the big model be the "coach", look at the results, write comments, propose amendments. The problem is that the comments are too rough.
G-Designer, MaAS, GTD, etc.): Directly "draw" architectures with generating models are the most powerful currently. But the "engines" they use, such as VAE, spreading models, were designed to generate images, vectors, and could not cope with the topography of this discrete and complex dependence on data.
FlowMAS First Tip: Replace an engine "born for discrete structure"
The core generating skeleton chosen by FlowMAS is the generating flow network (Generative Flow Networks, GFlowNets). The framework was proposed by Turing Prize winner Yoshua Bengio's team and was the first to be used to generate drug molecules to efficiently explore a variety of candidates in discrete combined spaces.
Its idea is elegant: to see the whole production process as a flow on a circular graph. Starting from a blank, each node, one side, is to push the flow forward; the goal of training is to make the probability of each final structure being sampled equal to its reward (comprehensive scores such as task performance, cost).
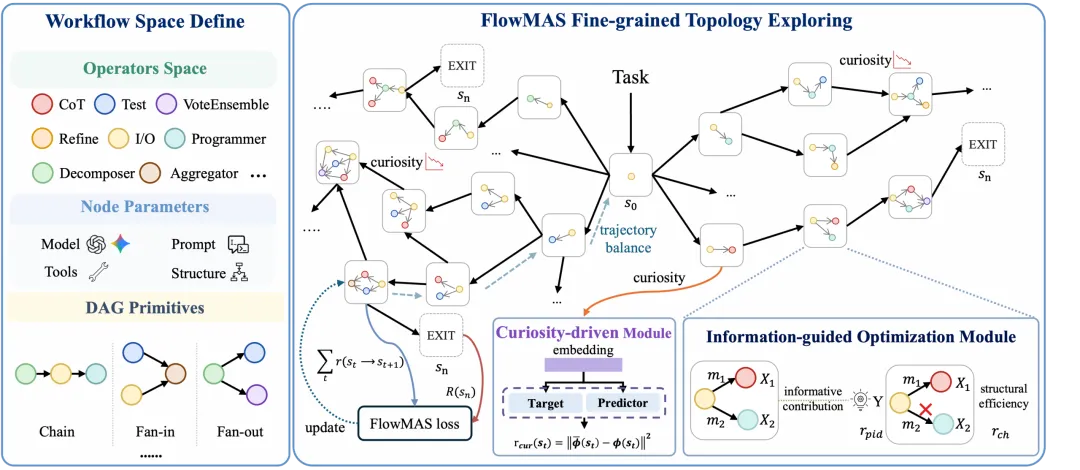
Figure 1 provides an overview of the FlowMAS framework. Source: Figure 1, page 3.
Put the engine in the car and fix two craters.
GFlowNet is good, but it's born of molecules that move directly to large model multi-intelligent systems that are "water resistant":
Structural challenges: Models are easy to "buckle up" on the basis of final rewards alone and cannot explore a sufficiently diverse architecture.
Information challenge: molecules have no "communication" problem, and the life-span of large model multi-intelligent systems is precisely the exchange of information. The information given by multiple AI may be complementary, may be redundant, or may produce a "chemical reaction", which directly determines the collaborative failure.
The key mechanism innovation of FlowMAS is: scoring at the end of different periods, usually with "processory rewards". The paper proposes that each step built into the workflow is evaluated by an intermediate structure and injected into the "intermediate rewards flow", reintroducing GFlowNet's constancy of flow and trajectory.
Two "secret weapons": curiosity + information
The process rewards are provided by two modules:
Curiosity-driven modules (CDM): reward for "new structures never seen before". Borrowing the idea of Random Network Distillation from reinforcement learning: using a trainable predictive network to match the output of a fixed target network. The more incorrectly guessed, the more novel the structure and the higher the reward.
Information guiding optimization modules (IOM): Use information theory to rate the quality of collaboration.
Partial Information Decomposition (PID) is the idea of dividing multiple upstream AI contributions to the information in response into three "unique, redundant, collaborative" segments that are specifically rewarded with "1+1>2".
Effective channel reward: to make up a Gram matrix and calculate the similarity of the residual strings that flow along each path, to measure whether information is evenly distributed across each communication path. Too low, indicating that information is crammed into a few "main channels" with redundant occupancy or "touch fish" branches; too high and uniform, indicating that each path is contributing.
It is worth mentioning that information scoring is only used during the training phase; the deployment of reasoning requires neither standard answers nor these rewards, and does not increase the cost of use at all.
Experiments: Whole lead and save more money
6 open benchmarks: mathematical reasoning for GSM 8K/MATH, code generation for HumanEval/MBPP, reading understanding for HotpotQA/DROP) × 3 major model bases (GPT-4o-mini, Llama-3.1-8B, Gemma-4-26B) × 15 baseline methods.
The result is clear:
On the Llama-3.1-8B, the six FlowMASs averaged 70.50 points, which is above the strongest automation baseline MaAS ((67.73) and AFlow ((67.55)); GPT-4o-mini was the same overall first as on the Gemma-4-26B ((average 81.40/86.92)).
On all three pillars, FlowMAS averaged 8.17 points higher than the manual design method and 6.12 points higher than the existing automation method.
The advantages are particularly evident in the weaker 8B small model, which can also be used to build stronger teams.
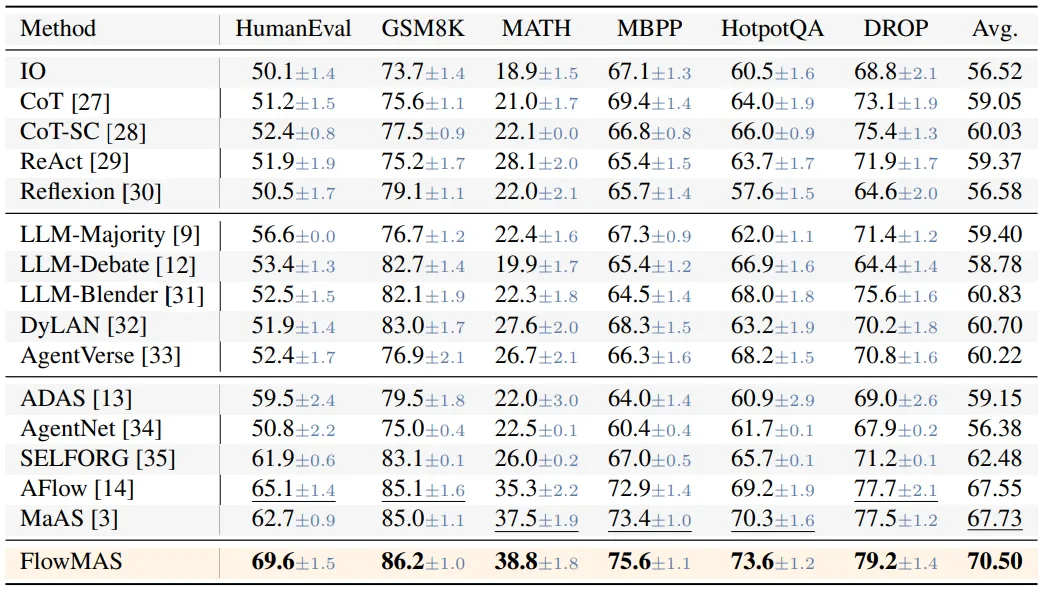
Table 1 compares performance on six public benchmarks. Source: Original paper Table 1, page 7.
On HumanEval, AFlow's reasoned token consumption is more than 15 times that of FlowMAS, while the accuracy is 4.5 points lower; ADAS's training token consumption is up to 220 times that of FlowMAS.
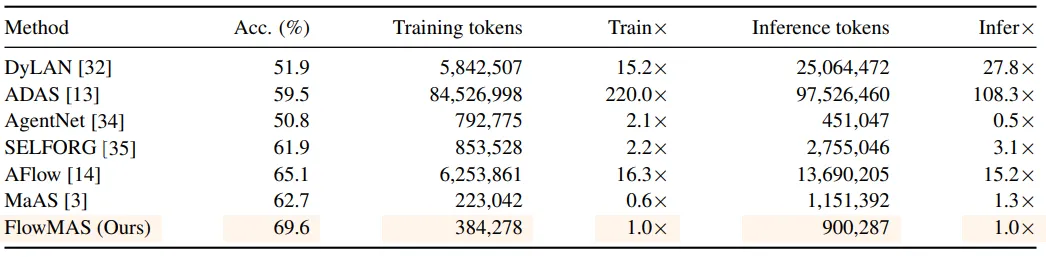
Table 2 shows the comparison of computational efficiency at HumanEval. Source: Table 3, page 8.
The dilution experiment further validated the need for the design: replacing the engine with VAE, graph diffusion, Transformer or MLP, with a complete decline in performance; removing the Curiosity Module or Information Steering Module, with similarly noticeable declines in performance (HumanEval dropped from 69.6 to 62.8), and replacing graph editing distances, ICM, LLM-as-Judge and other alternatives.
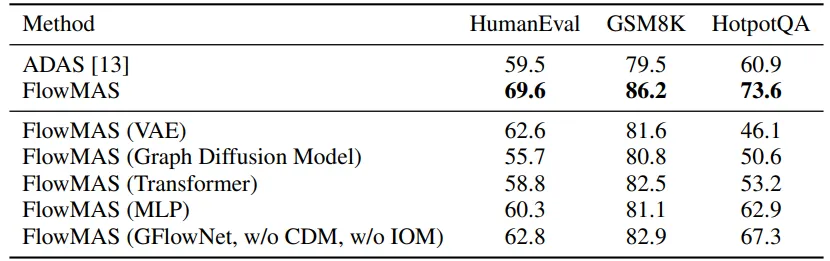
Table 3 compares the performance of different generating backbones. Source: Original paper Table 4, page 8.
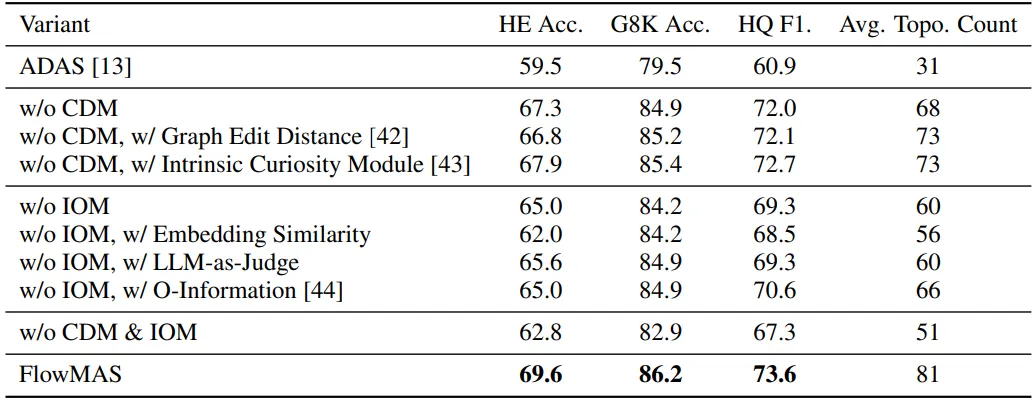
Table 4 shows the dissolution of different modules. Source: Original paper Table 5, page 9.
An intuitive example: in the DROP reading comprehension task, FlowMAS automatically evolves the partitioning structure of "evidence extraction, decomposition, decomposition, decomposition, decomposition" and responds to the problem; while the AFlow and MaAS-produced architecture cannot explicitly decompose the evidence, and the binary answer is wrong.
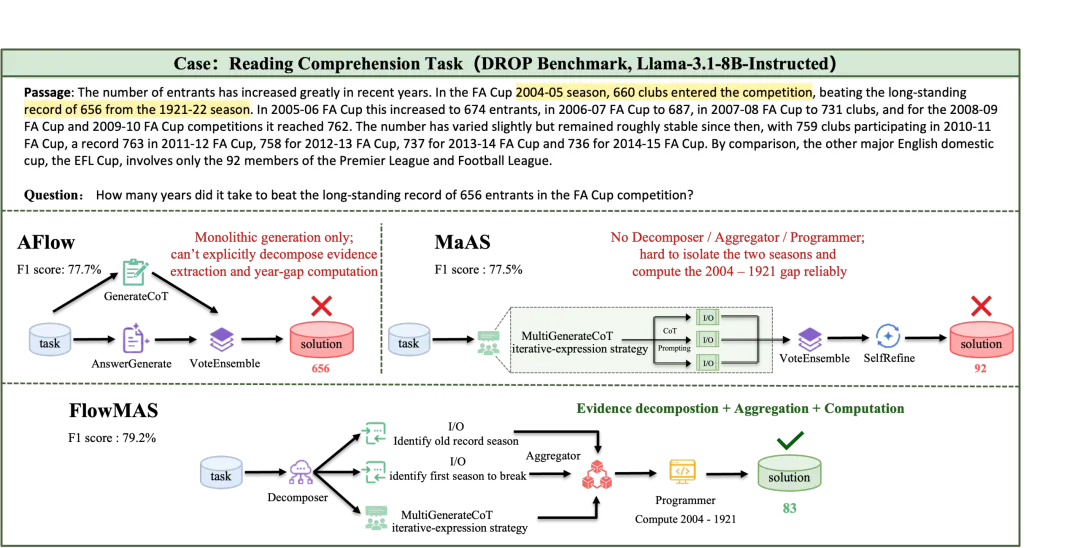
What is the meaning of this verse?
In the past, we've tweaked the words, tweaked the individual models; today, we're starting to tweak the teams. FlowMAS is about: turning "how to organize an AI team" from a manual art into a learning, optimizing, measurable scientific problem.
As the number of AI employees increases, it is "managing AI" itself that is perhaps most in need of AI.
© THE