In the typical workflow of an intelligent organism, the model must be free-form thinking before performing each action: analyzing the current observation, evaluating the evidence already available, then deciding the next action. This type of thinking is central to the ReAct paradigm, but it also leads to realistic reasoning costs.
A team of researchers from Apple and Carnegie Mellon University recently proposed a new framework, SSR (Selection-based Structured Reasoning), which redesigned the link: instead of generating logic by token, rather than having the model "select questions" from a set of default reasoning options.
Selection-Based Structured Reasoning: Toward Efficient Multimodal Search Agents
Authors: Apple, Carnegie Mellon University
Address of the paper:https://arxiv.org/abs/2610.01892
The main page of the project:https://zfy0314.github.io/ssr-webpage/
One motivation: Is small-scale literature worth it?
Today, most search agents follow a similar pattern of interaction to ReAct: observation, observation, observation, observation, observation, observation, observation, observation, observation, and observation.
Using a multi-form search, for example: a model sees a photo of a building, and the question is, "What exhibition will be held next in this building?" A typical Agent will have a free-form thinking: "This image looks like a museum... I need to first determine what the building is... and then search for its most recent exhibition"..., then construct a search query and call tools accordingly.
However, this "think-and-do" pattern exposes obvious sexuality pricing problems in small models. Researchers observed that small end-to-end models like 2B, 4B sometimes generate considerable reasoning content, but this content does not necessarily help to generate the next move and final decision.
More importantly, the research team, by analyzing a large number of search tracks, found that although the entities, queries, and observations of each subject differed, the higher-level reasoning logic for determining the next action appeared repeatedly. For example, at an AI conference, where the chip was hosted and when the chip was founded, the two seemingly unrelated topics shared the same reasoning logic: chip entities were known but the target information was missing, and chip entities added to the target attributes to search for chip.
This means that the search agent's reasoning space doesn't have to cover the entire natural language space. Instead of generating it from scratch every time, it's better to pre-define a set of replicable reasoning options so that the model completes the reasoning as a selection question.
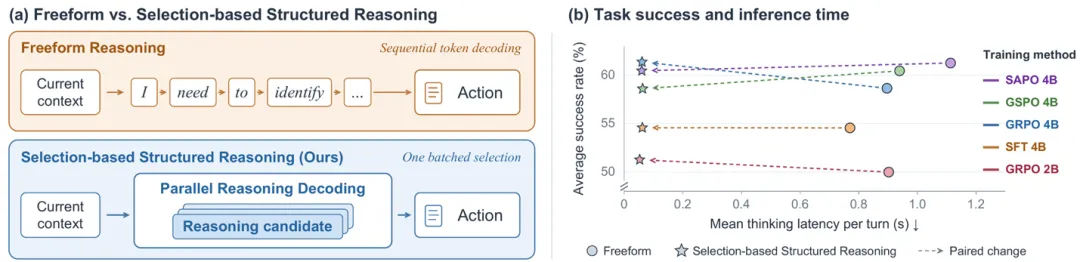
Reasoning as a selection problem has improved the speed of reasoning.
Method 2: Selection-Based Structured Reasoning
2.1 Library of reasoning and selective reasoning
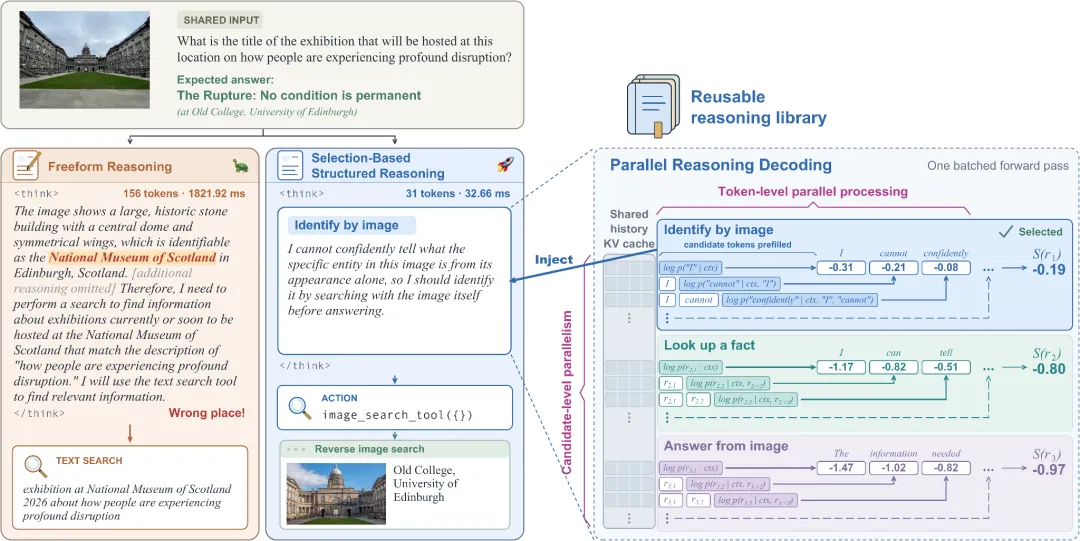
The core of SSR is a library of reasoning that contains 6 reasoning options: uncertainty when entities in a chart are used to search for an image to identify an image; need specific facts when text search queries are required; need to cut or enlarge the local area of an image when looking at details; evidence is gathered based on evidence responses; read directly to an image when there is an answer in an image; and answer directly when common sense can answer.
With each round of interaction, the agent no longer generates a rationale word for word, but selects a rationale from the rationale library as the current round, and then generates a specific action based on the selected rationale, such as which query to use in this search, which box to cut. This design will unravel the execution details related to repeatable rationale options and instances: the options provide a rationale for "why do you do this", and the action generation is responsible for "how do you do it specifically".
2.2 Scoring with the model itself, without the need for additional headings
The approach of the research team is to directly allow the LLM itself to act as a classifier. For each reasoning option, it calculates the probability average based on the current context; and after softmax is distributed to the categories in the reasoning library, the reasoning selection is completed by sampling. The entire selection process does not require any additional task heads, nor does it require SFT warm start, dividing with the movement to share the same set of model parameters and system prompt.
2.3 Parallel Reasoning Decoding: the "parallel decoding" of reasoning
This is the direct source of the SSR efficiency advantage. Since all of the reasoning options are predefined, the betting can be completely parallel: at the token level, by forcing a one-time prefill of the entire option, all of the tokens seem to be calculated in a batched forward pass; at the reasoning option level, all of the options share the same context KV cache while betting.
An intuitive example of this was given to an architectural photograph of the University of Edinburgh, which asked for an exhibition title on the subject of monkeys undergoing a profound transformation. A 4B model generated a long thought process of 156 tokens, taking 1821.92 milliseconds, but misjudged the building to be the National Museum of Scotland, which ultimately led to the wrong search direction. The SSR, with only 32.66 milliseconds, precisely selected the inference option of monkeys identifying objects by image, and directly triggered the image search.
2.4 Training: Direct access to both SFT and RL
An additional advantage of SSR is that, since reasoning is constrained within the reasoning library, SSR can be trained directly with RL without the need for SFT warm start. While many existing work requires a "specific way of thinking" of the SFT church model, SSR not only saves data construction and training time at the SFT stage, but also makes the model behaviour more predictable and controllable.
Three, the experiment: the accuracy is basically flat and the reasoning is 10 times faster.
The team evaluated Qwen3-VL 2B/4B models, H100 + SGLang reasoning engines, MMSearch, HR-MMSearch, FVQA-test, InfoSeek, Simple VQA, Live VQA, and MAT-Search on a total of seven multi-modal search benchmarks:
Search accuracy is flat: 4B SSR (GRPO) has an average success rate of 61.37%, compared to SOTA of the same size; 2B SSR is flat at 51.26%, comparable to the zero sample 8B model. In the four training methods of GRPO / GSPO / SAPO / SFT, SSR is equivalent to free-form thinking versions.
The speed of reasoning was significantly improved: the delay for each round of reasoning decreased by over 90%, and the overall delay for each subject model decreased by 28:54%. Compared to baselines such as Chain-of-Draft, Sketch-of-Thought, Efficiency Rewards RL, Probe & Prefill, SSR has the highest success rate, with p95 reasoning delay of only 0.07 seconds (baseline 0.8 times 1.9) and is more stable.
Some of the findings of the dissolution experiments include:
Semantics is important. The average success rate decreases by 3.9% if a model chooses only the number (such as "[1]") rather than the full text, and 7 benchmarks are completely impaired. This shows that it is true that the semantic understanding of the model is based on natural language differentiation, rather than the study of a purely indexed classifier.
Options increased from single-choice to 6-choice, with an average success rate of 61.37% from 37.24% in single-choice to 61.37% in single-choice; the increase from 1-choice to 2-choice resulted in a jump of 17.27 percentage points, demonstrating that more and more fine-grained options can better guide motion generation.
Selection is customizable. The same checkpoint presents different selection distributions on different benchmarks: SimpleVQA, which answers simple facts, has the highest proportion of "image-based responses", and HR-MMSearch, which is based on high-resolution images, has the highest proportion of "image detail checks".
In contrast to the self-reported version. The experiment found that if a self-reported method was used to train a model to literally generate an option in a reasoning library, it would have to rely on SFT to teach it to follow the format; the RL, which relies solely on the prompt aggregation reward, could not restrict the model from "rethinking", while the SSR directly guarantees from the mechanism that the reasoning results must come from a predefined reasoning library.
Conclusion: redefining reasoning space
In the team's view, this work may be more about "shortening CoT" than it is about "shortening CoT", but it raises a more fundamental question: Does the way reasoning is expressed necessarily depend on unrestricted natural language generation?
Free-form thinking is critical to open mathematical reasoning, theoretical proofs, or code design; but in multi-cycle searches and tool use scenarios, agents often face only a few high-level decisions: whether the current information is sufficient, whether entities in a chart need to be identified, whether to continue searching, whether to enlarge a localized area. Really highly dependent on specific inputs, such as search queries, tool arguments, crop coordinates and final answers, are still generated freely by models; while strategic-level reasoning is not necessarily generated every time in a complete language space.
Therefore, SSR should be understood as a reorganization of the reasoning space: from a fully open language space to a compact, reproducible, semantically clear strategic space. The model does not stop thinking, only replaces part of the reasoning generated by the token with selection and inference in structured reasoning space.
© THE