Git, the 20-year-old version control tool that governs programmers, has been replaced by a new system created by Anthropic.
Only seven engineers and Claude, who was deeply involved in the development, completed all of this.
Within five months, Anthropic developed the internal source code control system Scion, the backed-up code review tool Antique, and several other related systems from scratch, and completed the migration of the entire unit code warehouse from Git to Scion.
What does this mean? It took a few months for a few people with AI to create a new system and replace it directly with their own Git, which they had been using for years.
Why do you want to build a Git replacement?
The reason is simple: Anthropic's AI programming scale is so large that the original development infrastructure can't cope.
Data from Anthropic shows that in May this year, it combined an average of about 2,500 code changes per day. By September, that number had surpassed 30,000, increasing more than 12 times in just four months. And, Anthropic expects that growth will not slow down in the short term. Potential demand for code mergers is almost unlimited, and code output will increase further whenever a bottleneck is resolved.
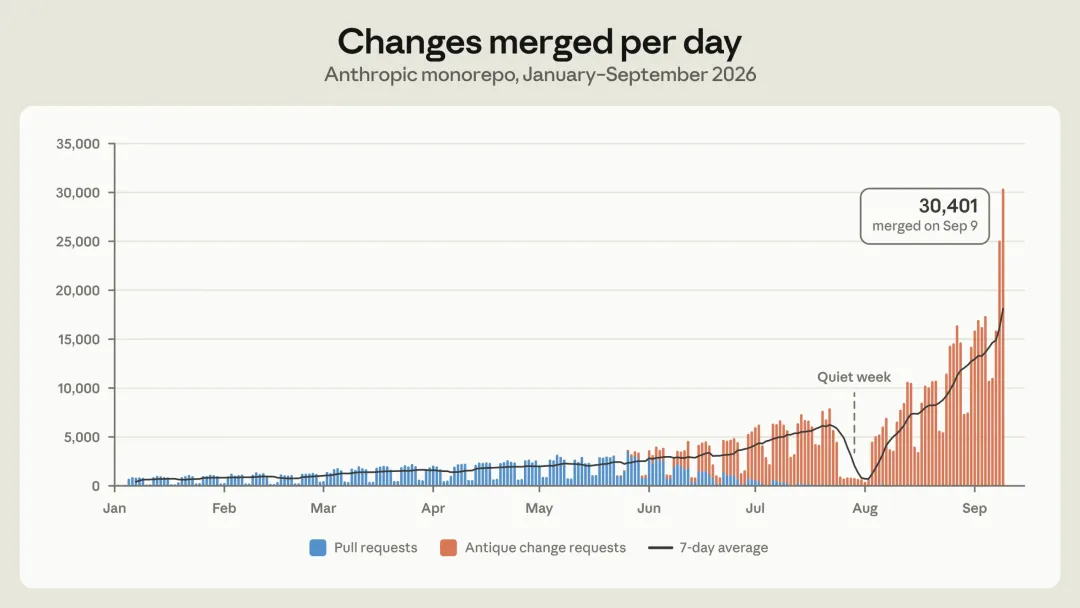
Against the backdrop of reality, Anthropic developed an in-house version control system and moved the entire Monorepo (single code repository) from Git to Scion in five months.
Anthropic provides a complete overview of the entire process in its latest blog.
One, the expanding Monorepo.
Before introducing Scion, it is necessary to explain how special the workload of Anthropic is. The extent to which it uses Claude's writing software far exceeds that of the vast majority of companies. Among them, where tools designed for human development at scale are beginning to struggle. Source code control is just one example.
Anthropic predicts that not many companies will face the same problem in the near term. But as AI programming tools become more popular, other companies should not be facing similar bottlenecks for long. This is why we decided to share Scion's design and development experience.
Git is a decentralized system. Each clone receives a complete, independent code repository. Even if it is completely offline, developers can calculate code differences, view the submission history, track the modification records of a line of code, and detect arbitrary versions. For the vast majority of code repositories, this design is reasonable and is an important reason why Git has become an industry standard.
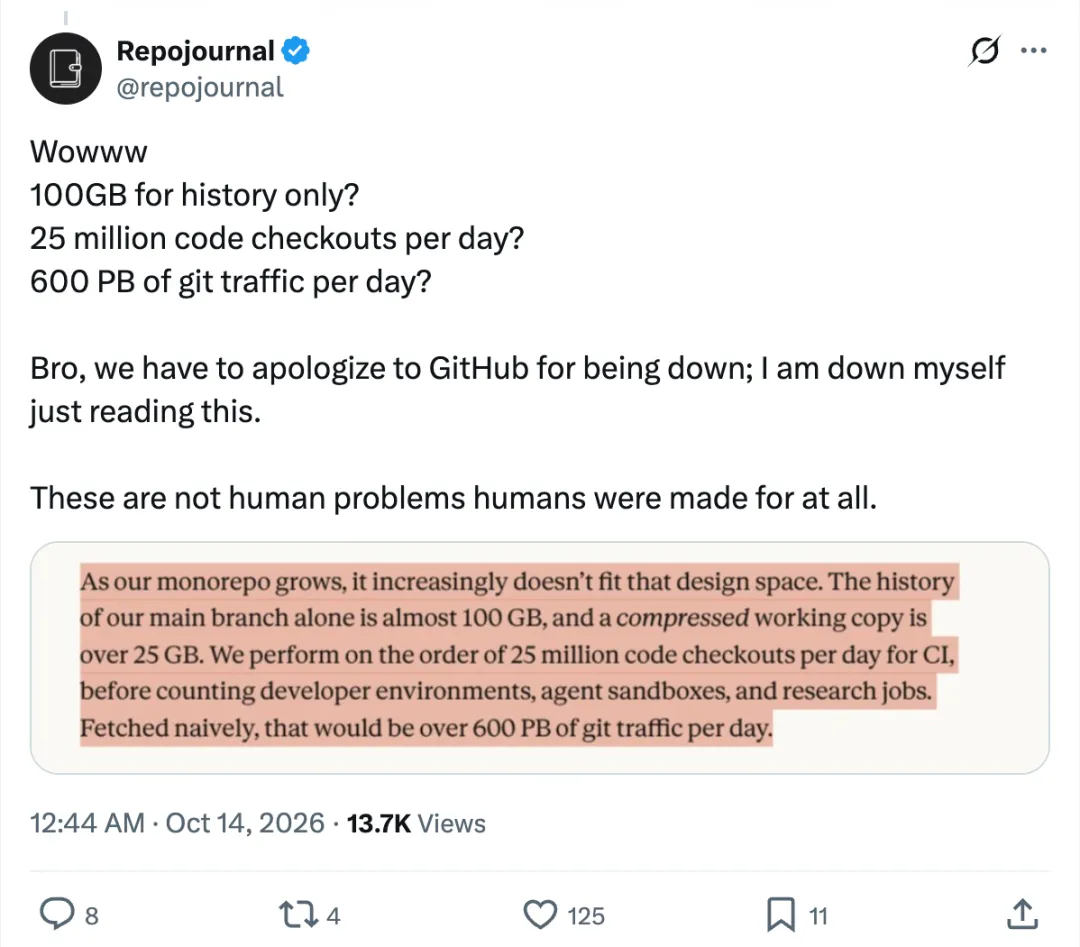
But as Anthropic's Monorepo continues to grow, Git's design is becoming increasingly difficult to meet. Currently, only the main branch's historical data is close to 100GB, and the workload after compression is more than 25GB. CI systems alone perform about 25 million code detections per day, not counting development environments, Agent sandboxes and research tasks.
Git, of course, also provides functionality for processing some of the warehouse data, such as shallow cloning, scarcity detection, and Promisor Remote. There are also some common ways in the industry to deal with large Monorepo, such as building an internal Git mirror, or keeping code warehouses fast in object storage.
These methods have all been used by Anthropic. At peak loads, they even run hundreds of Git mirror servers in-house. These programs did help for a while. But as the number of code combinations grew, they became increasingly difficult to maintain. Between two snapshots updates, the gap between snapshots and the latest version of the main branch will grow.
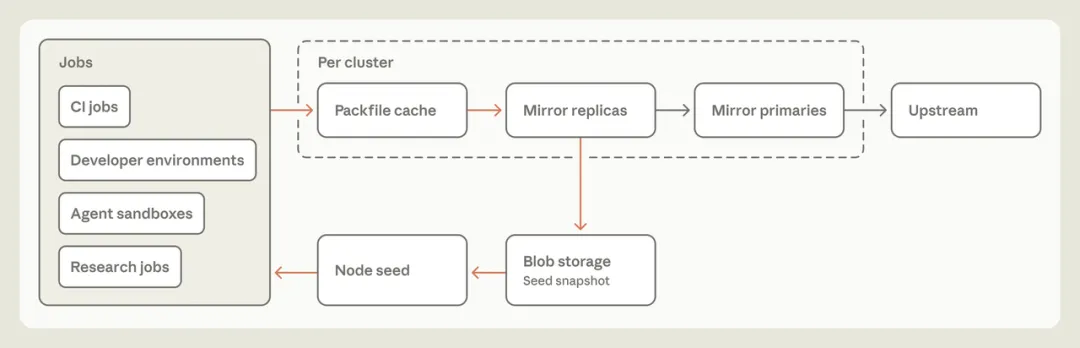
Typical architecture for expanding Git code detection capabilities.
Later, Anthropic re-examined its use and discovered a problem. Like most companies, Anthropic has actually been using Git as a centralized system, with all development work revolving around an authoritative code repository. But clients are almost always Agent and automation tasks, which are always online.
So Anthropic started thinking: What would it look like if the source code control system was designed from the ground up with Agent's characteristics of always being online?
Second, Agent-sized source code control.
As Agent begins to write large amounts of code, many traditional assumptions in software development are changing. Anthropic took these changes into account when designing Scion, so it adopted a different approach to Git in several core principles. Of course, the source code control of the super-large Monorepo is not unprecedented. Both Piper at Google and Sapling at Meta have accumulated extensive experience, and Anthropic has also referenced these practices when developing Scion.
Scion mainly follows the following design principles:
1. The customer is always online.
Git assumes that the client needs to work offline, so it must maintain a complete code repository locally. But the client of Anthropic is almost Agent and automation tasks, so Scion designs the client and communication protocols around servers that are always accessible.
2. The client and server assume different responsibilities.
In Git, each client has the ability to act as a complete Git server. Scion handles most of the work to the server, including querying file history and blame information, creating submissions, executing mergers and variants, etc. The client is only responsible for maintaining a local object cache of a limited size, writing files in work copies to disk, monitoring file system changes, and providing user-friendly interfaces.
3. Complete source code control services to support more new applications.
In Git, if a CI task or other tool wants to query code repository information, such as who last modified a line of code, or what is the relationship between the two submissions, it usually needs to maintain a local repository itself. Another way is to rely on the API provided by specific servers, but these APIs do not necessarily answer all questions.
Anthropic's automated binary positioning and code backflow lines are examples. Without this low-cost, programmatic access to the source code, these tools can be difficult to run at the current scale.
4. All components must support horizontal expansion.
In the past, Anthropic has run at most hundreds of Git mirror servers, which have taken up a large amount of computing resources. And it will be very difficult to continue expanding once the size of the code repository exceeds the disk or memory capacity of a single mirror server.
Scion stores the code warehouse data in a distributed manner and each component can be extended independently. There is no complete physical code warehouse in the entire system, nor on the server. Scion also does not have a mechanism compatible with the Git packfile (compressed object packet), so there is no need to perform the relevant warehouse maintenance operations.
5. Submissions must be light enough, support incremental processing, and do not require locking.
In Git, the developers submit the code locally and then modify the sharing by pushing it out. All Scion's submissions, variations, and mergers are done on the server end, so there's no need to push. But in this case, the server must be able to process these operations quickly. The cost of creating submissions and updating the relevant data structure must be proportional to the size of the changes in the code, but not to the size of the entire warehouse. Otherwise, the server will not be able to keep up with the code submission speed sooner.
Scion's development process also strives to minimize the use of ref. Ref ref refers to submitted references, such as branches and labels, and usually retains only the necessary references, such as main branches or publishing branches. Because of the need for universal data that all servers share in maintaining consistency, the future is likely to be an expansion bottleneck.
6. Work copies can be omitted to detect only the required data by default.
Anthropic's Monorepo is very large, and the CI performs tens of millions of code detections every day, so they want to avoid unnecessary code detection operations as much as possible. For example, if a CI task needs to calculate the difference between a single submission and its merged base point, it can query directly to the Scion server.
Scion's protocol mainly revolves around scarcity detection and virtualization detection designs. Scarcity detection contains only directories that the client explicitly requires, while virtualization detection loads files only when it is really needed. Thus, even if the task must use files on the disk, only actual read content is required.
Three, how Scion works.
After learning these design principles, we go on to see how Scion implements them. These experiences can be applied to other source code control systems and may help with other aspects of the software development process.
Structure of data
In Scion, the basic unit of work is called Changeset, which is a record in a write-ahead log.
Changeset saves most of the common information in the Git Commit, but the data is organized differently. Git Commit saves a pointer to a directory tree, while Changeset saves a list of files that have changed relative to the first parent submitted, as well as a pointer to the contents of the compressed file content in the object storage.
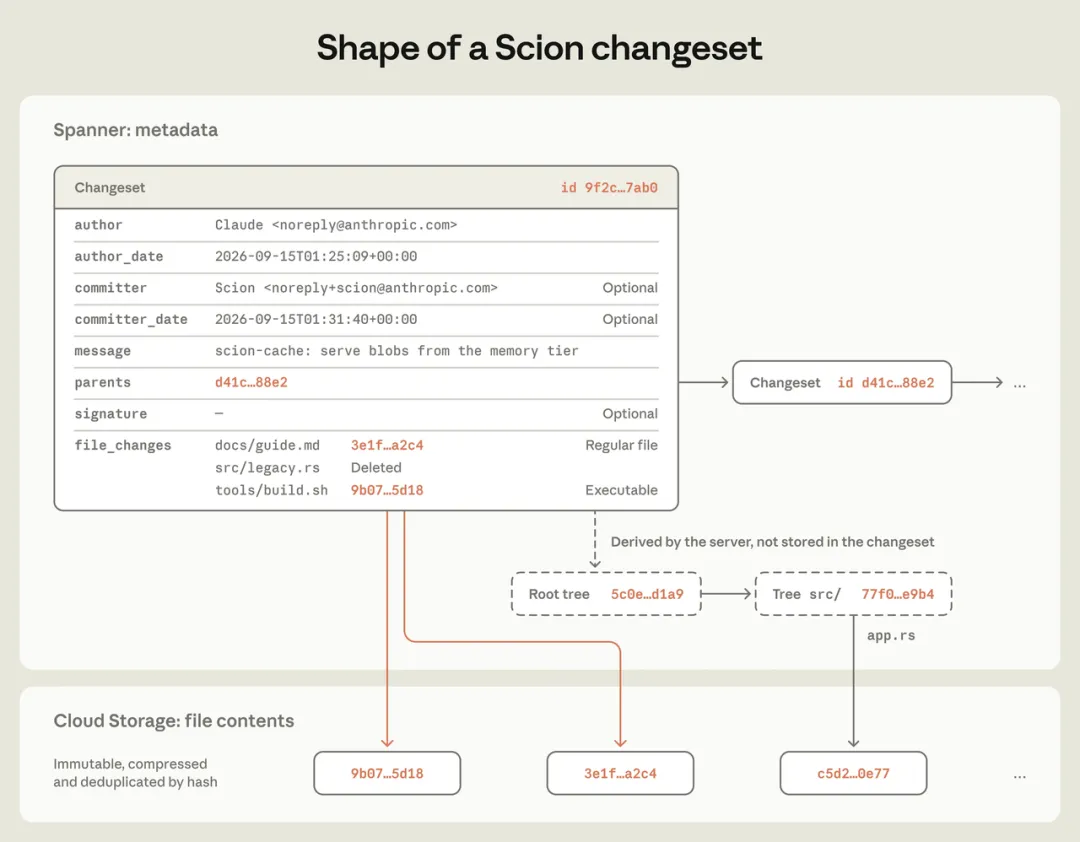
Changeset data structure in Scion.
This structure enables Scion to receive changes at extremely high throughput. Since it does not need to receive a packfile, does not need to be locked or cross-server coordinated, nor does it need to move ref. Strictly speaking, Scion still supports ref. But neither creating nor obtaining submissions is dependent on ref, so mobile ref only needs to perform a comparison and swap operation on Spanner's single-line data, which is separate from creating Changeset.
However, Changeset only records the content of changes that occur. On the basis of these records, it is not possible to quickly answer who last modified a line of code, or which submissions a file has undergone. To address these issues, Scion will build additional data structures based on Changeset, including data structures specifically used to query the blame and file path history, and to speed up the submission of graph queries.
All derived data is calculated using a common mechanism. Each derived data is defined by a recursive definition: derived data from a particular Changeset can be calculated based on the corresponding data from its parent Changeset.
This mechanism has three advantages.
First, a derivative data can be easily added if it is found that an operation can be accelerated by a new data structure.
Second, each derivative can independently decide whether to calculate it beforehand or wait until it is actually needed to calculate it again, so as to avoid generating unusable data.
Finally, clients do not need to understand the internal implementation of these data structures, so they can continuously optimize the data structure at the server end without having to modify the client.
With the development of Scion, Anthropic has repeatedly added new derivative data types, such as those used to detect file duplication, and new indexes for path-based file searches.
Expansion of Scion
A small cluster of Scion servers is responsible for providing clients with a variety of source code control APIs, including access to Changeset, calculating diff, searching for merger bases and obtaining Blobs, etc. All source code data uses content addressing, so once the data is written, the content does not change. Any server can cache this data without having to confirm it with other servers.
As a result, Scion servers are able to extend horizontally, requiring little coordination with each other. These servers are essentially like large caches, but can also compute derivative data on demand and write the results back to Spanner.
In the past, if CI tasks or other tools needed to query submitted ancestor relationships, track code modification records, they had to first obtain and maintain code repositories, which would lead to a considerable maintenance burden. In fact, in the early days of the migration, we didn't have our own client accounts, storage formats, and communication protocols, when Scion could only answer these metadata queries.
Scion's scn client has several important differences with Git in terms of data acquisition protocols, so it can adopt a more scalable architecture; CPU costs significantly lower than Git servers. Scion does not let the client tell the server which data they already have when negotiating data, but directly requests the client's desired directory tree and Blob object. The client starts with the root directory tree, checks which directory tree objects are missing in the local storage, and then returns the request to the server. Once the directory tree is obtained, Blob is obtained in the same way. Each request is directed to a clear and unchanging object, so the cache can return the result.
The entire architecture is very similar to traditional layered caching systems. This method is highly efficient and supports intermittent forwarding, as the entire process does not need to rely on a single volume of packfile responses that can reach several GB.
In Anthropic's computing cluster, the client communicates with a security process called scion-daemon via Socket. Scion-daemon stores code objects for the entire computing node. Since most nodes need access to Monorepo, different tasks at the same node often repeat a large number of the same objects, so caching is more efficiently managed by a unified security process. Each scion-daemon loads a regularly updated snapshot when it launches. It then communicates only with the region's directory tree and Blob caching server, which are known as scion-cache.
scion-cache transmits objects directly from memory, and the format used is the format that the security process ultimately writes to the disk. Therefore, the cache server does not need to calculate which objects are missing from the client, nor does it need to perform differential compression. When an object is missing from the cache, scion-cache requests the authorized server scion-server to read data from the Spanner or cloud storage as needed.
Scion-daemon、scion-cache and scion-server all use the same RPC interface, so the client does not need to know the topological structure of the entire caching system. In theory, any layer can communicate with other layers. However, Anthropic strictly prescribes access relationships between different layers to isolate failures. For example, if a region scion-cache fails, Anthropic does not want a large number of requests to flow directly upstream to the scion-server, ultimately causing the entire system to crash.
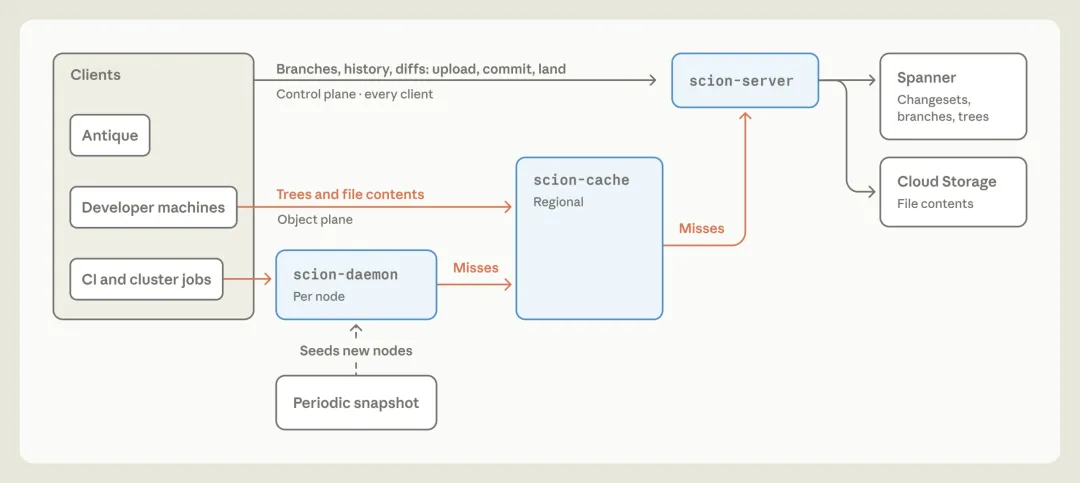
Scion code detects the architecture.
Each layer of the system has a caching rate of more than 99% and does not require long-term maintenance, so it can be conveniently scaled as needed. Compared to the previous Git mirror infrastructure, Scion has reduced its CPU and memory resource occupancy by 200 times. The code detection speed of the CI and research tasks has been increased by about two levels, from the last few minutes to a few seconds. This releases a large amount of resources for the entire computing cluster, saving only the CI system 25% of CPU capacity.
Four, what did you learn from developing Scion?
Anthropic began developing Scion at the same time as Claude Mythos Preview and Claude Tag began to be available within Anthropic. Both models further increased our demand for Scion on the one hand, and significantly accelerated development progress on the other.
Here's a very representative example. Earlier this year, Anthropic basically hand-crafted the first version of the Git to Scion data import stream prototype. At the time, Anthropic felt that the program was pretty good. It wasn't until later with an early internal version of the Claude Mythos Preview that Anthropic had Claude rewrite the entire program without giving it any additional instructions. As a result, Claude directly wrote a version that reduced memory consumption by 20 times, increased runtime by 4 times, while preserving all the implicit constraints on data import sequence and data structure in the original program.
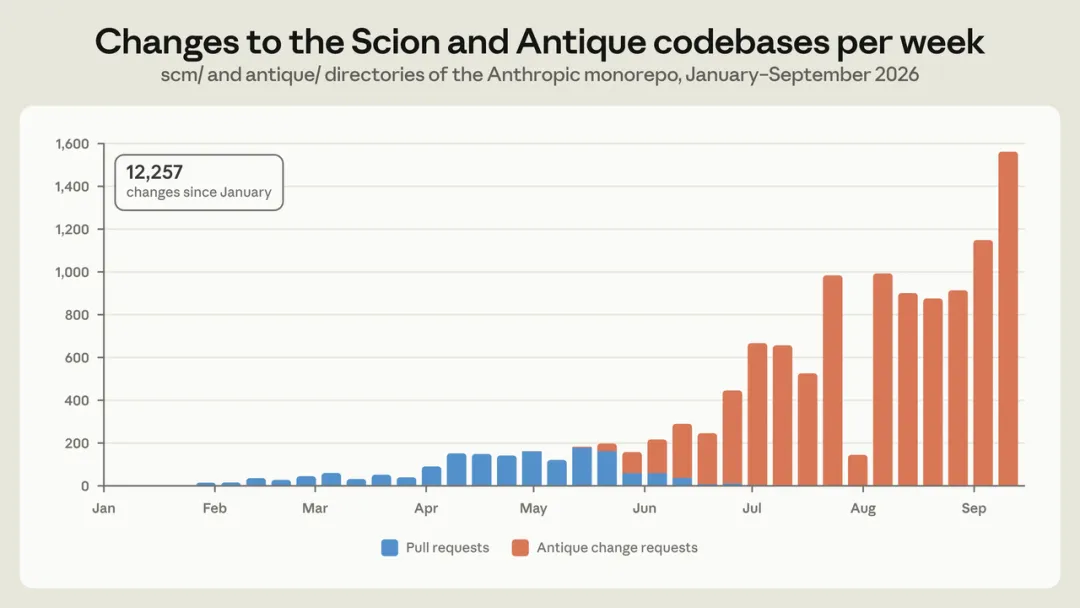
From January to September 2026, Scion and Antique combined the number of code changes per week.
The experience of developing and running Scion has given Anthropic some new insights into software development for large-scale agents.
Small teams rapidly develop large systems that will become increasingly common
A team of only seven people developed Scion and the code review tool Antique in five months, built about half of the systems and completed a complete migration to them.
Moreover, the entire development and migration process took place at Anthropic over a period of 10 times the number of code mergers per day. In the past, the development and deployment of such a set of source code control systems usually required more engineers to be completed after years of repeated iteration and gradual migration.
Anthropic believes that rapid, flexible system development and migration will become increasingly common in the future.
Engineers are still important, but the way we work is changing
All of the engineers involved in this project now think that Claude's ability to write code has exceeded their own. But engineers still play an irreplaceable role. Team members understand the overall relationship between systems and know what the different architectural designs need to do. Anthropic knows what problems they want to solve, how large the system needs to be supported, so that they can make reasonable design decisions.
The agent sometimes violates the core constraints that the system would have to abide by in order to meet a certain code pattern. This is particularly common during the migration process. For example, several systems require inquiries about when a code change is merged into the main branch.
This method is very effective in many respects, but sometimes focuses too much on local problems. Therefore, experienced engineers need to timely guide Claude to avoid it in order to deal with the risks in the hypothesis and to design the system too complex. For example, one review of the reliability of another internal service was too cautious, resulting in Claude adding a large number of additional tests to make the system more complex. Currently, the members of the Anthropic team will still review each code change request in the system.
Significantly improved system performance and code quality
Claude was able to write a large amount of code at a much faster rate than human engineers, making Scion one of the most comprehensive and well-developed test libraries Anthropic has ever come into contact with. Although the development time was very tight, Anthropic built a complete isolation, replicable simulation test that covered a variety of complex infrastructure interactions and source code control operations that it had previously encountered.
In addition, Anthropic has incorporated blur testing and perfected limit flow mechanisms. Claude also often finds it easy to find important performance optimization opportunities. For example, one time it found that a submitted ancestor relationship query algorithm omitted an already-indexed one, so there was room for optimization. If given to an expert, such a problem may take days or even weeks to analyze and optimize.
Improvements in the actual performance of the Scion Original Code Warehouse.
Laid a new foundation for the security management of Monorepo
For Monorepo, which is large in size, security and compliance with capacity and scalability are equally important. Anthropic has considered these issues from the very beginning of Scion's design. Scion supports extensive code warehouse access control and can set permissions for single directories. This protects the most sensitive code while retaining Monorepo's advantages.
Additionally, the code review tools developed by Anthropic also support complex, semantically based approval constraints. For example, systems can distinguish between simple changes that modify only comments, and changes that involve sensitive procedural logic. Thus, human reviewers can focus their efforts on influencing larger changes.
System operation can reach a new level
The Anthropic team used Claude Tag extensively to monitor various components of the system, such as creating Slack channels that allowed Claude to keep an eye on the performance of a component.
Currently, Anthropic has Superfan in charge of the scion-daemon, Superfan in charge of the scion-cache, and Superfan in charge of the Antique merger queue. They can access the system's telemetry data and logs.
Of course, Anthropic still retains traditional alerts for all systems. In contrast, Superfans have been able to detect some very subtle problems that have never occurred before, making traditional alerts seem somewhat unique.
Thinking about a lot of things in the past
The project prompted Anthropic to re-examine the workflow of those designed for human development at scale. For example, in the scenario of large-scale programming with Agent, the traditional merger queue may not be very reasonable. Hundreds or even thousands of code changes may be incorporated into the warehouse while a set of tests is running.
Until now, Anthropic has not been able to effectively replicate the industry's usual way of managing merger queues through global warehouse locks. Therefore, Anthropic has put more effort into automation testing after the merger of the code, as well as automation testing before deployment. Of course, this means that simultaneous code changes can cause conflicts.
What does this mean for the broader developer ecosystem?
Anthropic believes that Scion is just part of solving the scalability problem that comes with increasing AI Agent capabilities. Sharing these details is hopeful that other teams can get some inspiration from our practice.
However, Anthropic does not consider Scion's program to be applicable to all scenarios. Scion is unlikely to work as a general alternative to Git. The design ideas it introduces are mainly applicable to the truly massive Monorepo, such as a warehouse shared by tens of thousands of engineers, or one continuously generated by a large number of agents.
In addition, Anthropic has a special condition that it is able to consume tokens for internal tasks, much larger than other companies are willing to take on in reality. This is done both to meet their own software development needs and to test Claude's ability. In real life, it is very difficult to make Scion a product that can be widely used by other companies.
Scion is very different from Git. If other companies want to migrate to Scion, they need to migrate all of the components of the entire software development process, as well as supporting code review, code search, and CI systems. These systems within Anthropic are highly customized and difficult for other companies to directly adopt.
Anthropic also worries that the end product will be of little use if it tries to develop an open version that meets everyone's needs. However, Anthropic expects that in the next 6 to 12 months, this problem will become more common. If every company using Git solves a similar problem on its own, it will obviously waste a lot of engineering resources.
Therefore, Anthropic believes that the most valuable practice at present is to share their own design ideas so that other developers can apply some of the line-effective programs in Scion to Git without having to completely abandon the existing Git model as a whole. For example, Git servers do not necessarily have to work in the same way as Git clients.
Git hosting platforms, like Scion, can provide complete server-side RPC interfaces. These interfaces can even be standardized between different code hosting platforms, allowing Git clients to make direct calls. Git's current data consultation protocols do not necessarily need to be maintained as they were.
The link is as follows:
© THE