How far away is AI from the cutting edge of science?
Recently, the OpenRSI Index has attracted attention on X. To date, the project's posts have been viewed more than 133,000 times, and related topics have appeared on X's Today's News list.
Figure 1 The OpenRSI-Index appears in X's Today's News directory.
As big language models approach consensus on some assessment benchmarks, cutting-edge researchers face an increasingly difficult question: to what extent can progress on the list translate into progress in real research?
Publishing a list is not equivalent to effective scientific research, and merely running a task is not equivalent to the ability to continue to advance research.
From large-scale data pre-training to human feedback reinforcement (RLHF), model evolution is always dependent on effective feedback signals. A key bottleneck emerges as research moves towards regressive self-improvement (RSI):
When a model tries to improve on another model, and even tries to improve itself, who defines the really effective environmental feedback for it?
This is the starting point of the OpenRSI Index: Is it possible for scientific intelligence to find better ways to improve models of human-designed training within clear experimental boundaries?
Website:
GitHub:
X:
If a smartphone uses thousands of GPUs, it's not going to work.
What's going to happen?
The OpenRSI Index is based on real-world influences from open-source research projects that give existing models, codes, data, and training programs to the intelligence community to continue improving on top of these achievements. Projects such as Marin, Qwen, GPIC have thus become research intelligence projects that cover pre-training, post-training and image generation.
These tasks require real-world model training experiments, with computational inputs ranging in size from thousands to tens of thousands of H100 hours. The three representative tasks shown on the website are:
Marin-Scaling-Ladder, a research and development project based on Marin's Open Source Basic Model, requires the same set of optimizer rules to be applied to six classes of models, covering 5.5 to 2.545 million parameters, to test whether a method can continue to be effective after a change in model size.
Post-training: Design a better reinforcement learning mission for Qwen. Qwen-122B-RL-Merge allows intelligent agents to generate verifiable training tasks, improving the performance of Qwen models in multiple fields such as mathematics, coding, and more.
Visual generation: Learn better generating methods from GPIC data. Smart entities start from shared model checkpoints to explore architecture, training goals, or improvements to training programs; each candidate program re-trains for up to 10 million images. A single runtime of 5,815 H100 hours.
The three tasks, put together, correspond to three questions: can the method be established across scale? will the agent be based on feedback organisational experiments? can an improvement be clearly attributed?
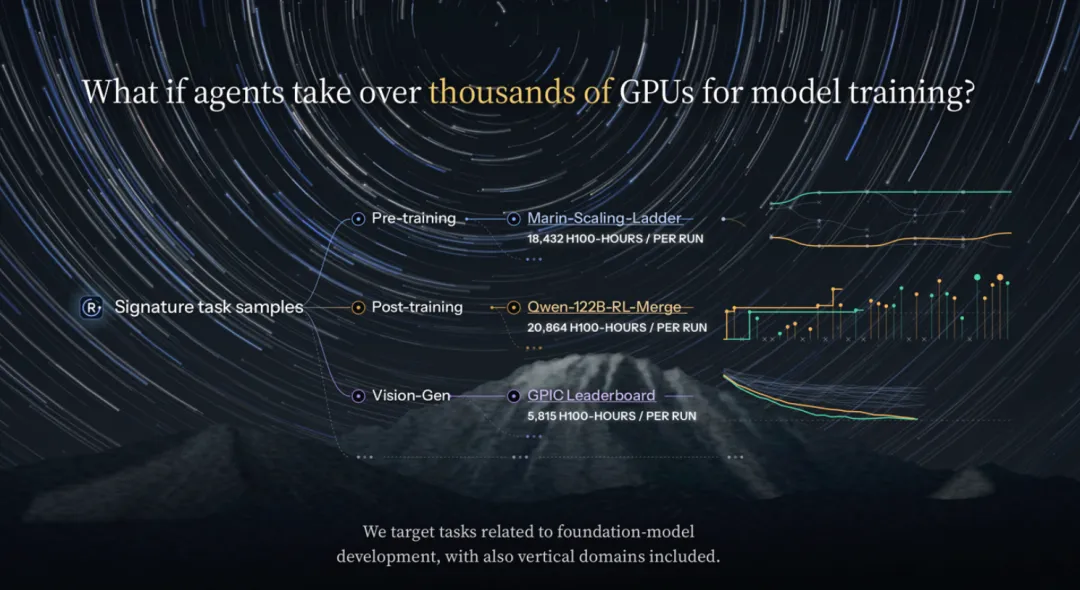
Figure 2 shows the representative tasks of the OpenRSI Index covering pre-training, post-training and visual generation, while giving the H100-hour scale at which each task is executed.
If you look at these figures alone, the OpenRSI Index can easily be understood as simply making the benchmark more expensive. What it really wants to change is not just the scale of the calculations, but the actual complexity of the assessments.
In order to obtain stable, comparable results, traditional Benchmarks tend to fix environments, shrink tasks, compress problems into a boundary-clear, answer-clear test question. This design is of course valuable, but it is increasingly associated with real-world experimental errors, scale changes, limited budgets, and failed experiments.
These calculations are consumed in real training and experiments. The following is an experimental progression of the GPIC text graph: The intelligent body repeatedly adjusts the training program and continues to improve based on the evaluation of the images generated.
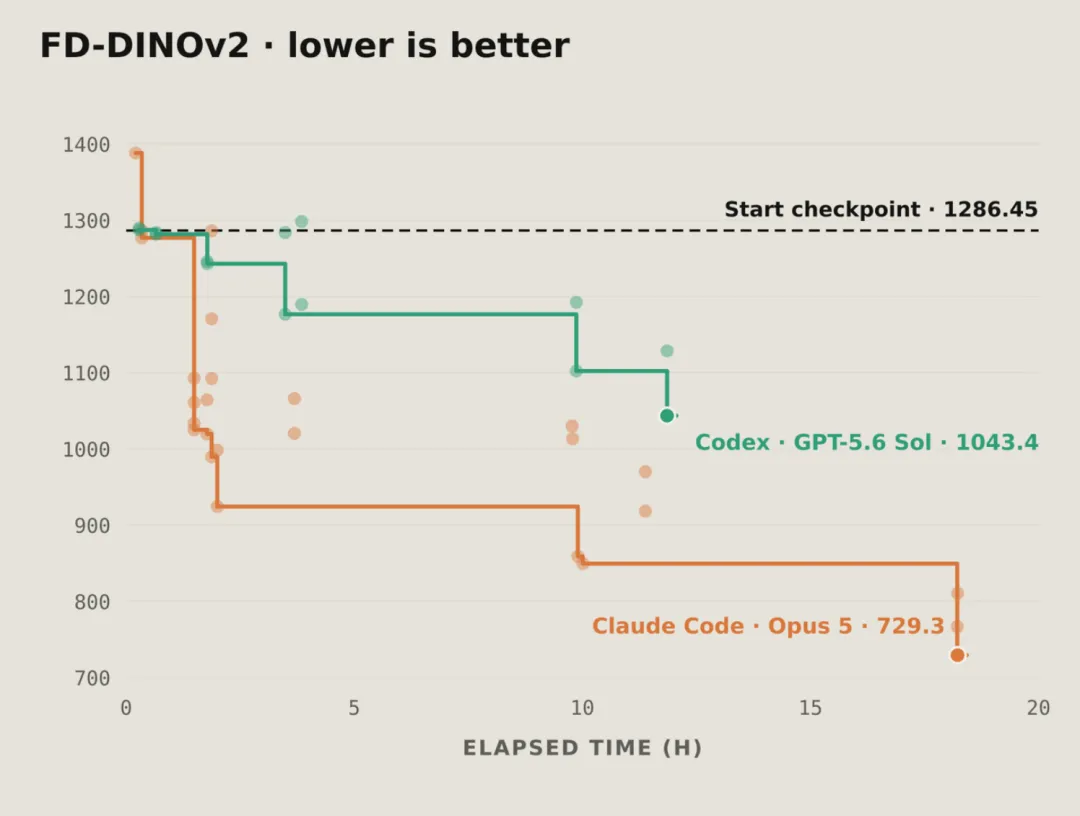
Figure 3 Public experimental measurement records of GPIC text graphing tasks. The horizontal axis is the study time; longitudinal axis FD-DINOv2 measures the difference in characteristic distribution between the generated image and the reference image, the lower the better.
The task also covers emerging open-source research. For example, Open-Jev corresponding Kev decision architecture tasks allowing the intelligent to improve small models of the probability of direct decision output, explore decision structures and training methods. Open tasks also involve robotics, retrieval, reasoning and underlying system optimization.
The ultimate answer to these tasks is: Can intelligent agents improve training programs designed by humans and find better ways?
It's an independent testing environment.
In the field of scientific research, there is a chain of suspicions
Researchers who have done rigorous experiments have found that increasing test scores is not the end of the study.
Is it because the modulation darkened the distribution of the test set?
Did chance magnify the slightest disturbance?
If it is re-approved, will the change be reinstated?
Data pollution, testing correlations with irreversible experiments, is a problem that can't be avoided when assessing models that are improving themselves. So, a key principle is that AI's experimental workspace is isolated from the final acceptance environment.
In the OpenRSI Index, each task has a clear resource and code boundary: which modules are allowed to modify, how many resources can be invoked, and what environment is ultimately accepted.
When submitted, the system suspends the work area and saves snapshots, assigning a clean evaluation environment to the newly started. Private testing is not given to the AI that performs the research, and changes in the documentation in the evaluation environment are not returned to the work area, but scores and regulated feedback are returned. Hardness violations such as altered reward paths, leaked evaluation information, over-budgeting, and so on.
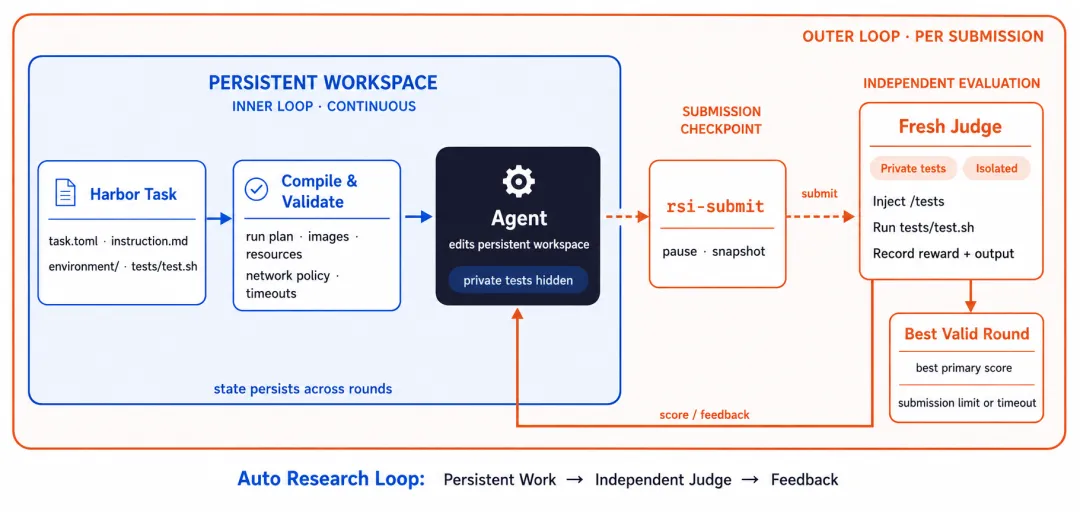
Figure 4 of the RSI-Harness workspace, independent acceptance and feedback processes.
This mechanism actually consists of two cycles.
An internal loop is a research loop: Agent modifies code in a persistent workspace, runs experiments, and continues research based on feedback.
The external loop is a verification loop: each formal submission is frozen as a snapshot and then handed over to a newly launched independent Judge for re-acceptance.
Under this operating mechanism, the OpenRSI Index does not require the agent to give the correct answer once in a while. It allows the agent to repeatedly try and make mistakes. But every time a claim is made, one condition must be met: not only to improve in its own experimental record, but to continue to exist in an environment beyond its control.
Clear constraints and independent acceptance provide a verifiable basis for the results. Exactly what an effective submission can reveal still depends on specific tasks, budgets, and evaluation criteria. But the validity of the method and the traceability of the results give researchers at least a more specific basis for answering: Is my work in itself credible?
A powerful group of mentors
The OpenRSI Index's coaching staff brings together scholars from different fields of study.
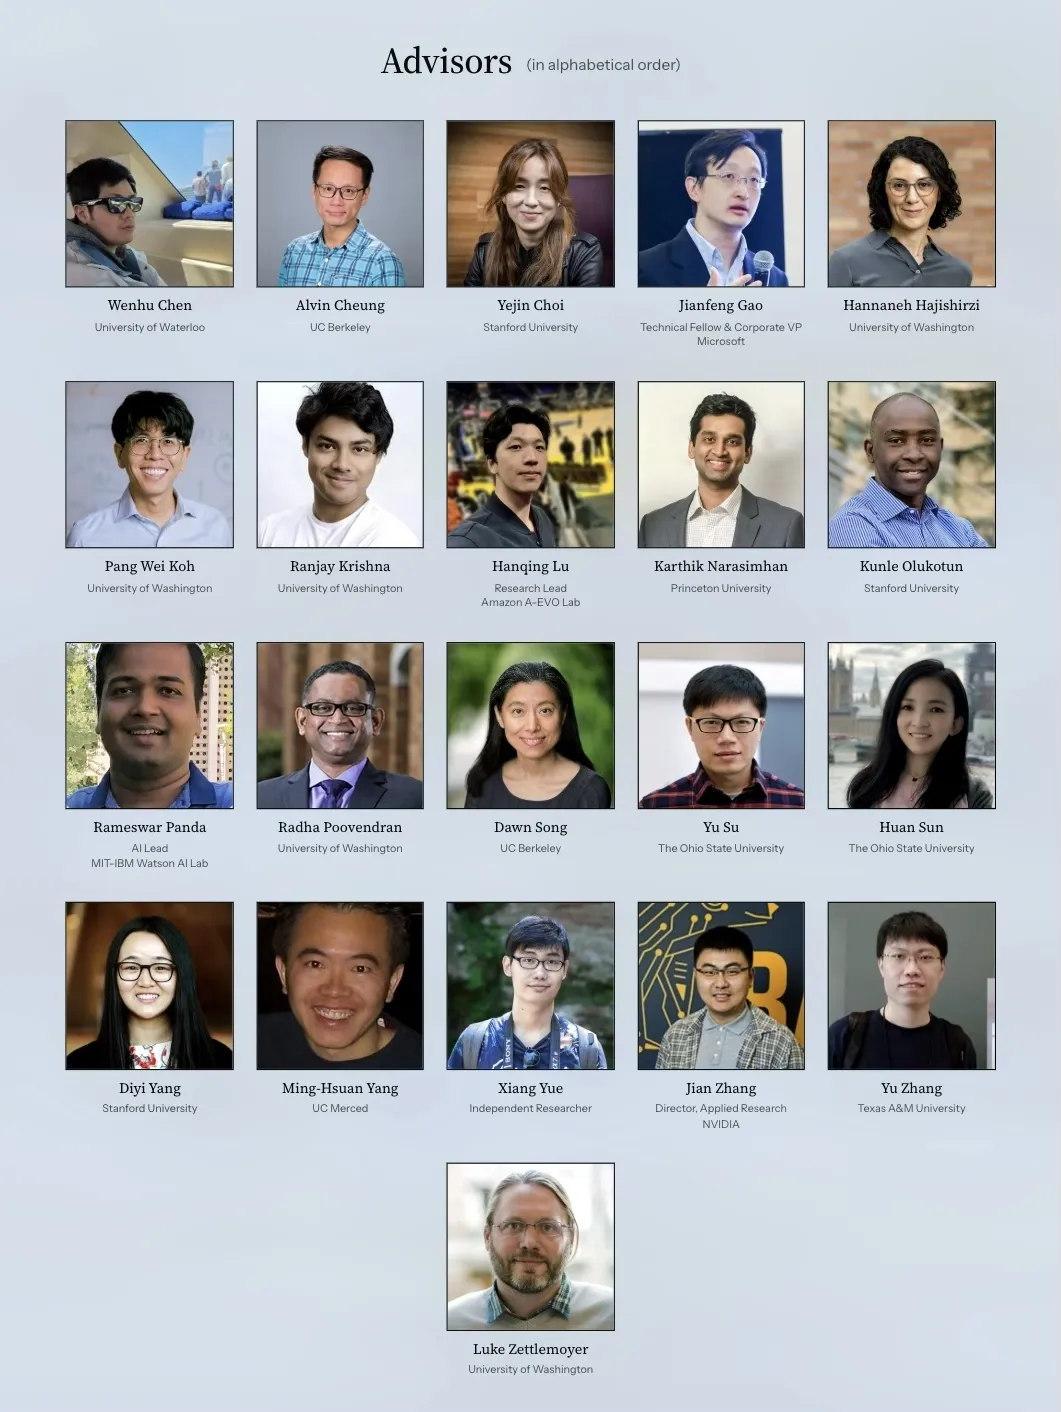
Figure 5 of the OpenRSI Index, ranked in alphabetical order by last name.
Luke Zettlemoyer is the co-author of RoBERTa, BART and Toolformer at the University of Washington, where his research extends from language model pre-training to model autonomous learning tools.
Karthik Narasimhan is one of the four authors of the first-generation GPT paper at Princeton University, and co-author of ReAct, SWE-bench and SWE-agent, which investigates large-scale models, smart-body approaches and real-world software engineering assessments.
Yejin Choi is a researcher at Stanford University. He represents the common-sense reasoning benchmark HellaSwag, the common-sense knowledge base ATOMIC and the knowledge generation model COMET, and continues to explore the common-sense understanding and reasoning capabilities of the model.
Dawn Song is the co-author of classic assessment benchmarks such as MMLU, ExMATH, and participates in Agents Who Lastam, E.L.E., CyberGym, and ExploitGym, which will extend the assessment to real career tasks, vulnerability recovery, and vulnerability exploitation.
The advisory team also includes Wenhu Chen, Alvin Cheung, Jianfeng Gao, Pang Wei Koh, Ranjay Krishna, Hanqing Lu, Kunle Olukotun, Rameswar Panda, and Radha Poov.