Today is the fourth day of Tibo's "28 consecutive days of release or reschedule".
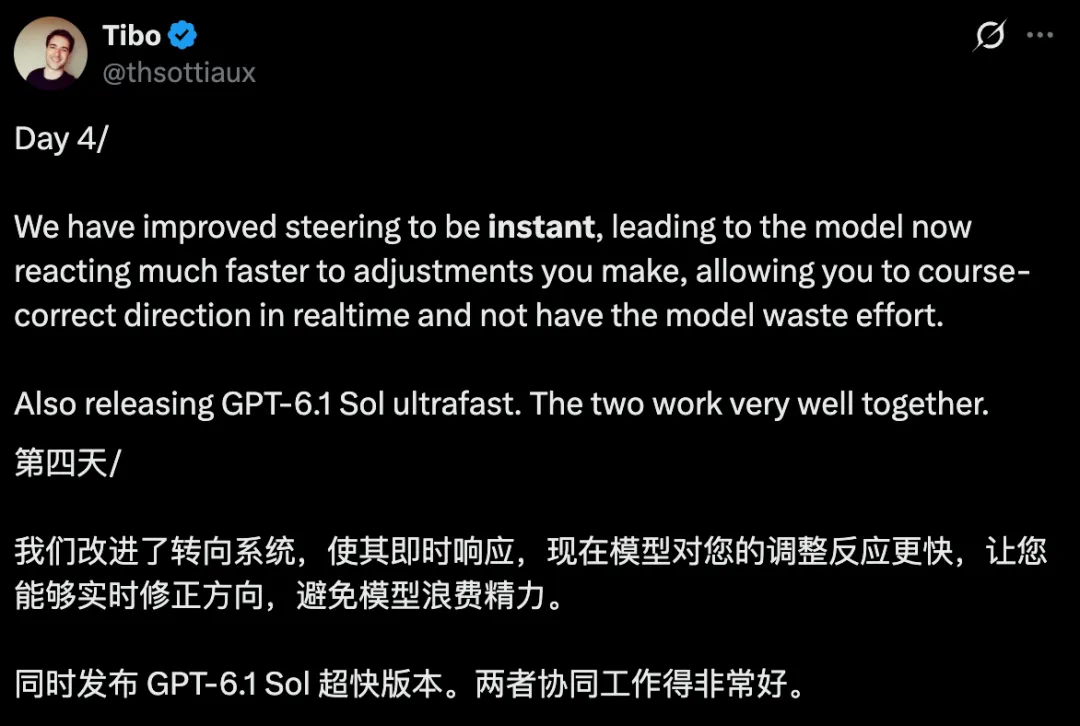
Yesterday, OpenAI decided to open GPT-6 to all users (including free and paid users) and today launched the Ultrafast version of the all-new model GPT-6.1 Sol! combined with an updated model control system to enable timely response to user instruction adjustments.
Turning pressure increase
GPT-6.1 Sol itself, released on DevDay on September 29, is positioned as "ability close to Astra, price of one-fifth". The standard API pricing is $2 per million of input tokens, $10 for output, and is already one of the highest-price flagship models currently available.
On this basis, the ultrafast mode directly increases the speed to eight times.
OpenAI calls it "Near-Astra intelligence at up to 8x faster speeds than Sol Standard".
This is the second iteration of OpenAI's "Ultrafast" concept. Earlier this year, they worked with Cerebras to launch the Ultrafast preview version of the GPT-5.6 Sol, which claimed output speeds of up to 750 tokens/s, 14 times the standard speed. GPT-6.1 Sol Ultrafast's 8-fold acceleration seems somewhat conservative, but given that the 6.1 Sol's own intelligence level has significantly exceeded 5.6 Sol, it can accelerate up to 8 times on higher capability baselines, with higher gold content.
The implications of this speed for development scenarios are beyond doubt. Typical uses of OpenAI include: online fault detection, real-time navigation applications for smart devices, and any real-time interaction scenarios where "money is burning every second".
In terms of API pricing, Ultrafast is $12 per million of token input and $60 of token output, six times the standard version.
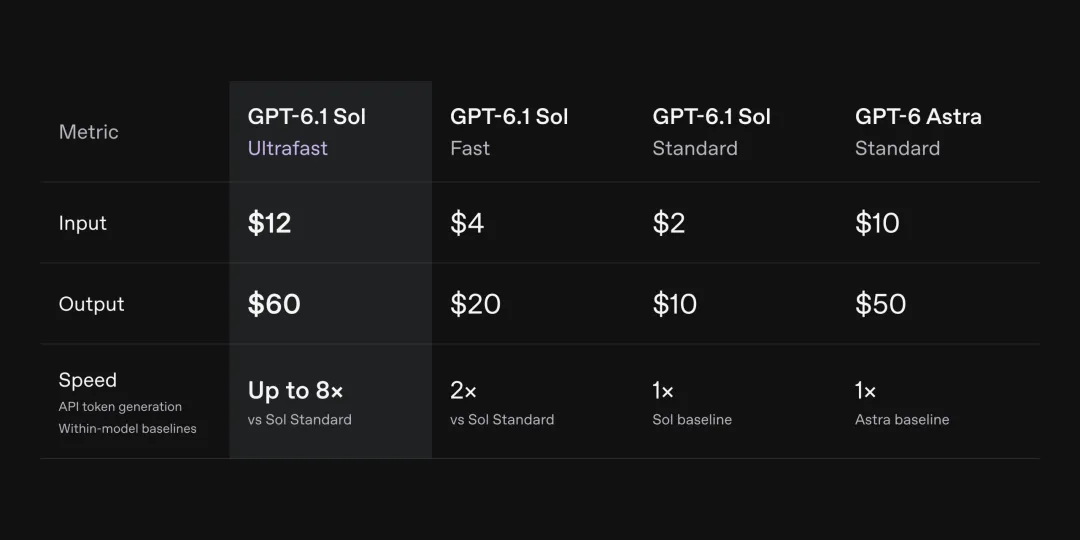
OpenAI developer relationship engineer Dominik Kundel gives a more intuitive positioning: "Approximately Astra-level intelligence is 8 times faster than Sol and costs only 1.2 times that of Astra".
Contrary to Astra's standard API pricing ($10 per million input, $50 per million output), Ultrafast is actually only a little bit expensive, but it's much faster than Astra's response rate. If Astra's speed isn't enough in your business scenario, Ultrafast offers an option to "pay a little bit more for a bunch of speed".
Ultrafast's capability parameters are tempting, but one key message is almost drowned in the announcement.
At the end of Codex and ChatGPT Work, Ultrafast is open only to Pro 500 subscribers, with qualifying subscription fees for Enterprise users and Edu users.
The Pro 500 is a high-end subscription plan launched by OpenAI this year for $500 per month. This means that for ordinary ChatGPT Plus users ($20/month) or even Pro users ($200/month) who want to use Ultrafast in ChatGPT or Codex, more money is needed.
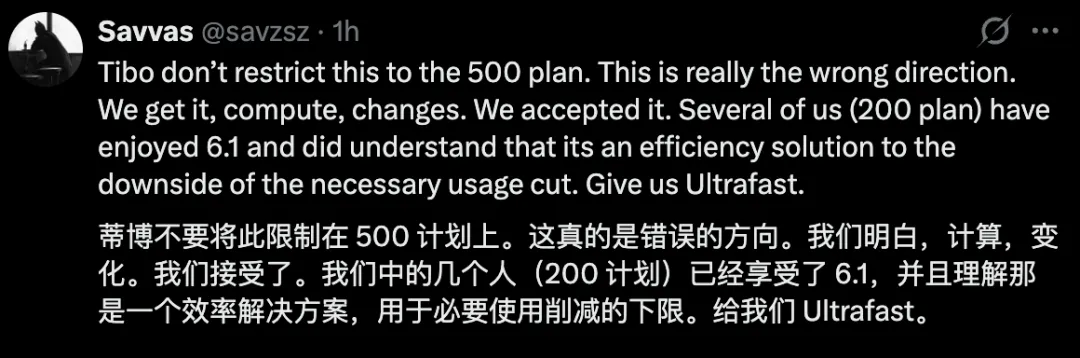
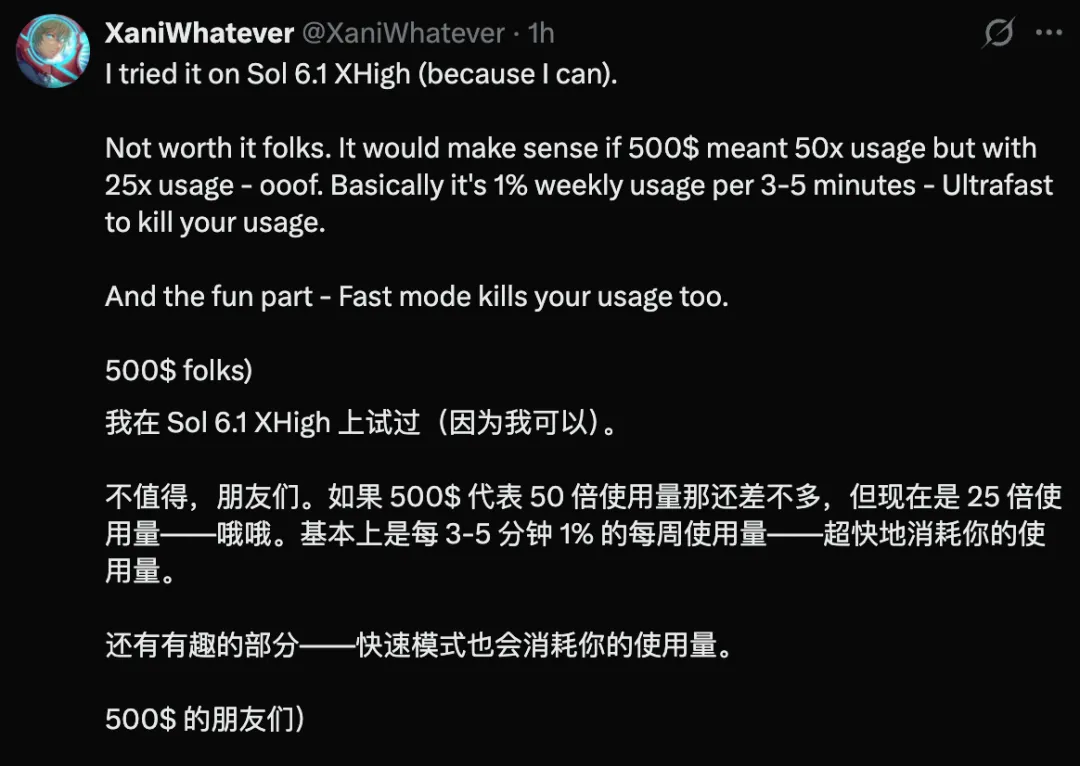
Some developers have said that Ultrafast is surprisingly fast in XHigh effort mode, but the speed of token consumption is equally surprising, with a 25x usage limit corresponding to a $500 monthly fee in this mode, "burning down 1% in a few minutes". Some have questioned the logic itself: "If Ultrafast consumes my usage limit faster, why not let all paying users choose for themselves?
Of course, the end of the API is not limited to subscription levels, and developers can call up the gpt-6.1-sol model directly and enable Ultrafast mode, for a small fee.
The instant value of GPT-6.1 Sol Ultrafast is that it offers an API-level combination of "near flagship intelligence + extreme speed" without having to wait for Astra's price reduction. For ordinary users, the improvement in the instant response experience may be more direct, after all, no one likes to stare at the models going crazy in the wrong direction.
What will Day 5 bring? See you tomorrow.