The big model will fight in September, and the DeepSeek will fight.
At 3:00 p.m. today, the official DeepSeek community was notified that DeepSeek V4.1 Flash had started testing directly.
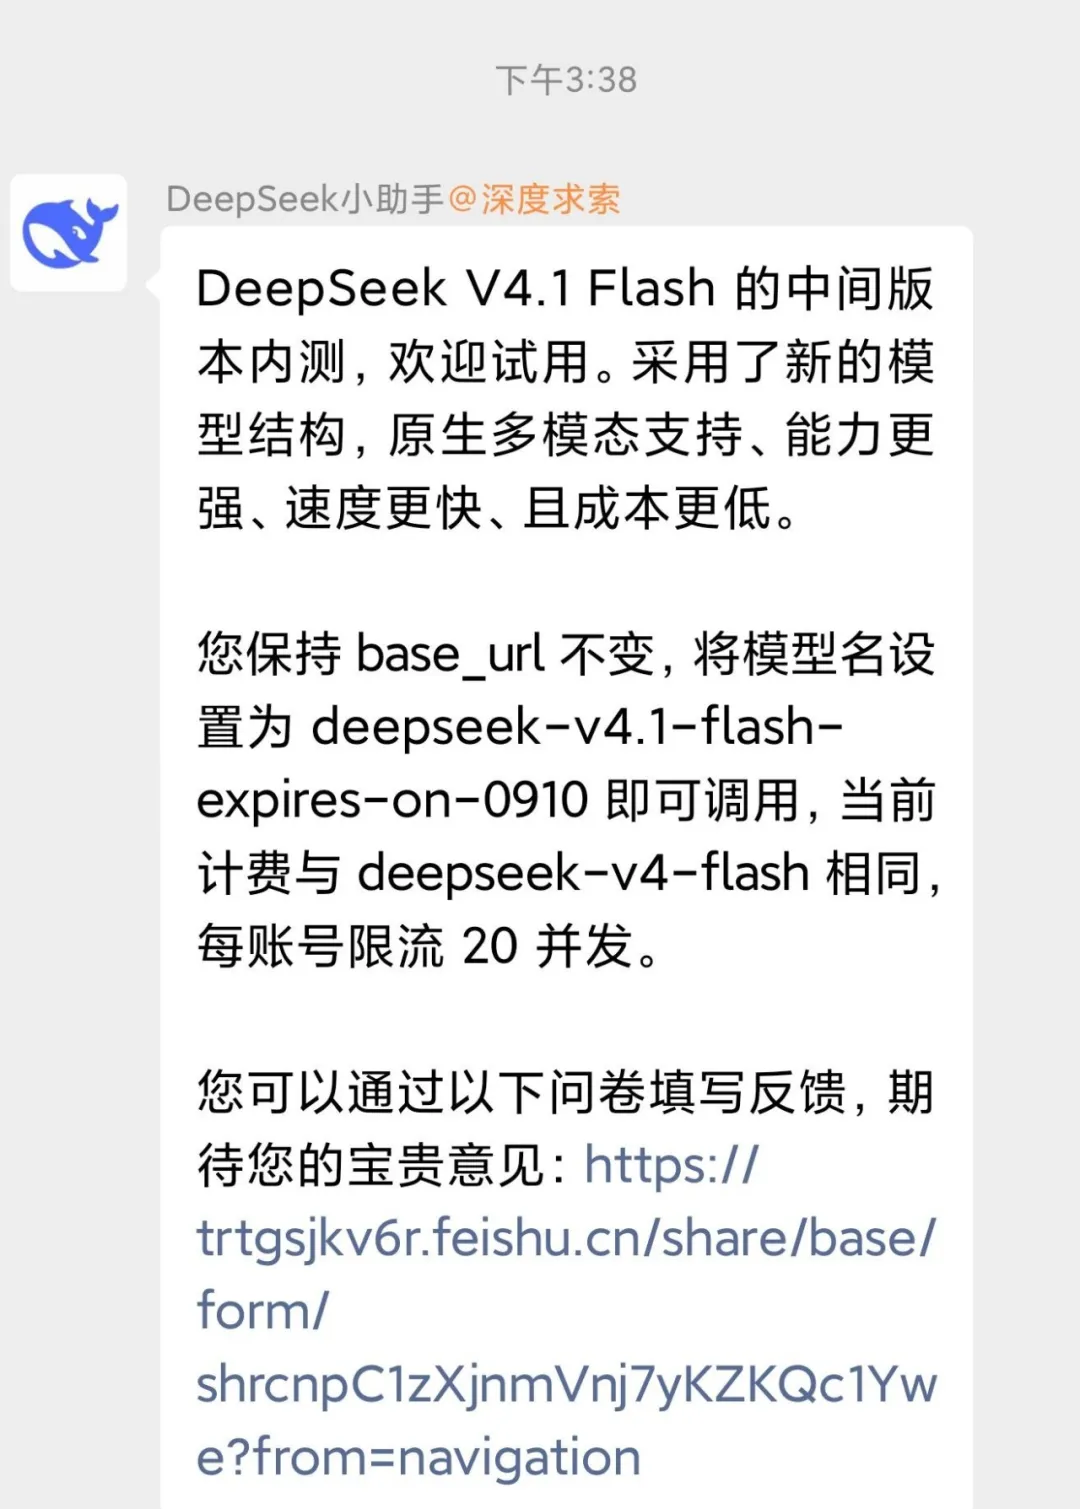
Although there are no special restrictions for users who use API services, the model can be added manually under the existing DeepSeek server: deepseek-v4.1-flash-expires-on-0910, retaining the original API Key and base_url and then selecting it directly in the new dialog.
DeepSeek V4-Flash-0731, which went online in late July, retained its original model structure and achieved a significant improvement in capability only after re-training; on August 13, the official DeepSeek V4 Pro version was released in conjunction with DeepSeek Harness, which began attempting to maximize capabilities through layout ecology; and the deepseek-v4-flash-vision-exp, which was unveiled on August 21, supported image mixed input, ending the unprecedented history of DeepSeek's big model.
It is worth noting that this V4.1 Flash update is not a simple post-training update.
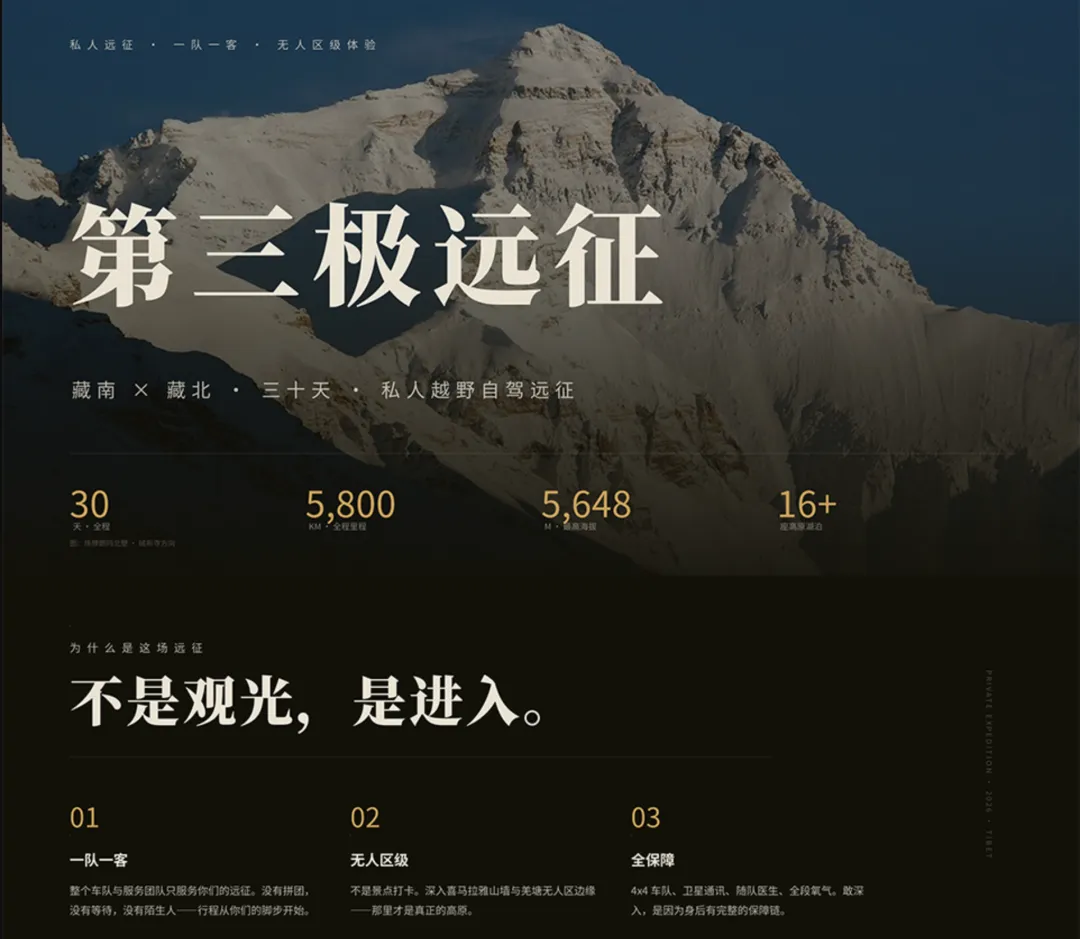
An official example of V4-Flash-Vision-Exp: generating a commercial customized Tibetan self-driving PPT under the Agent framework.
DeepSeek has made it clear that V4.1 Flash uses a "new model structure" to create more expectations.
Currently, because it is only intuitive, the official information is not much. It seems that the new structure officially declared is not so much about the overthrow of the model architecture, but can be modified with attention mechanisms, expert networks, visual modules, etc. However, since there are "native multi-models", we can expect that the new model will have further improvements in most of the task capabilities, like the previous v4-flash-vision-exp.
The other interesting part is that "speed is faster", and some people in the community have already achieved the level of 400 tokens/s, faster than the Gemini 3.8 Flash.
Users also give a more intuitive contrast: under the same task, V4.1 Flash retrieves context 5.2 times faster than V4-Flash-Vision-Exp, 49k generates SVG code 6 times faster than V4-Flash-Vision-Exp.
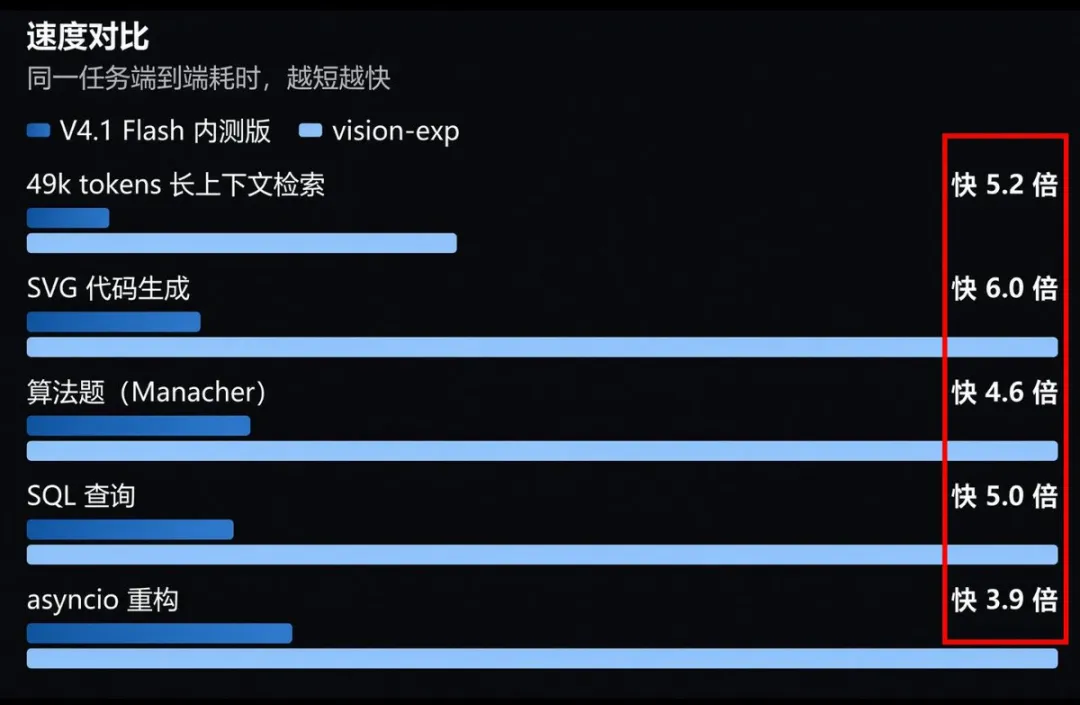
Netizens have demonstrated that V4.1 Flash improves its end-to-end speed by about 3.9 times that of V4-Flash-Vision-Exp in long-term context retrieval, code generation, and algorithm queries. Source: X user @NFT_Chen.
In the end, it's "cheaper", and while the current billing is the same as V4 Flash, many people are already looking forward to the drop in price of DeepSeek.
We also tested for the first time, making an html version of Mario MVP mini-game, which took about 7 hours and cost less than 2 bucks.
It takes "immediate play" as its primary goal, not stacking up a lot of enemies and punches at once, but ensuring the most basic details of "Mario Little Game":
Gold coins, monkeys, water pipes are almost 100% intact.
In an html version of Copper PPT about FDE, it doesn't just come up and ask what FDE is and who is listening to this PPT.
Then go online and look for the latest information, determine what the outline says first and then what it says, then translate the content into plain white to understand, and finally organize it into html.
Finally, since the model's name is "Expires-on-0910", it could mean that the version will be officially void in less than two days.