Hey, Claude, it's the second time we've hit the road!
This time, Claude deleted the entire developer's main directory, removing 700GB of files.
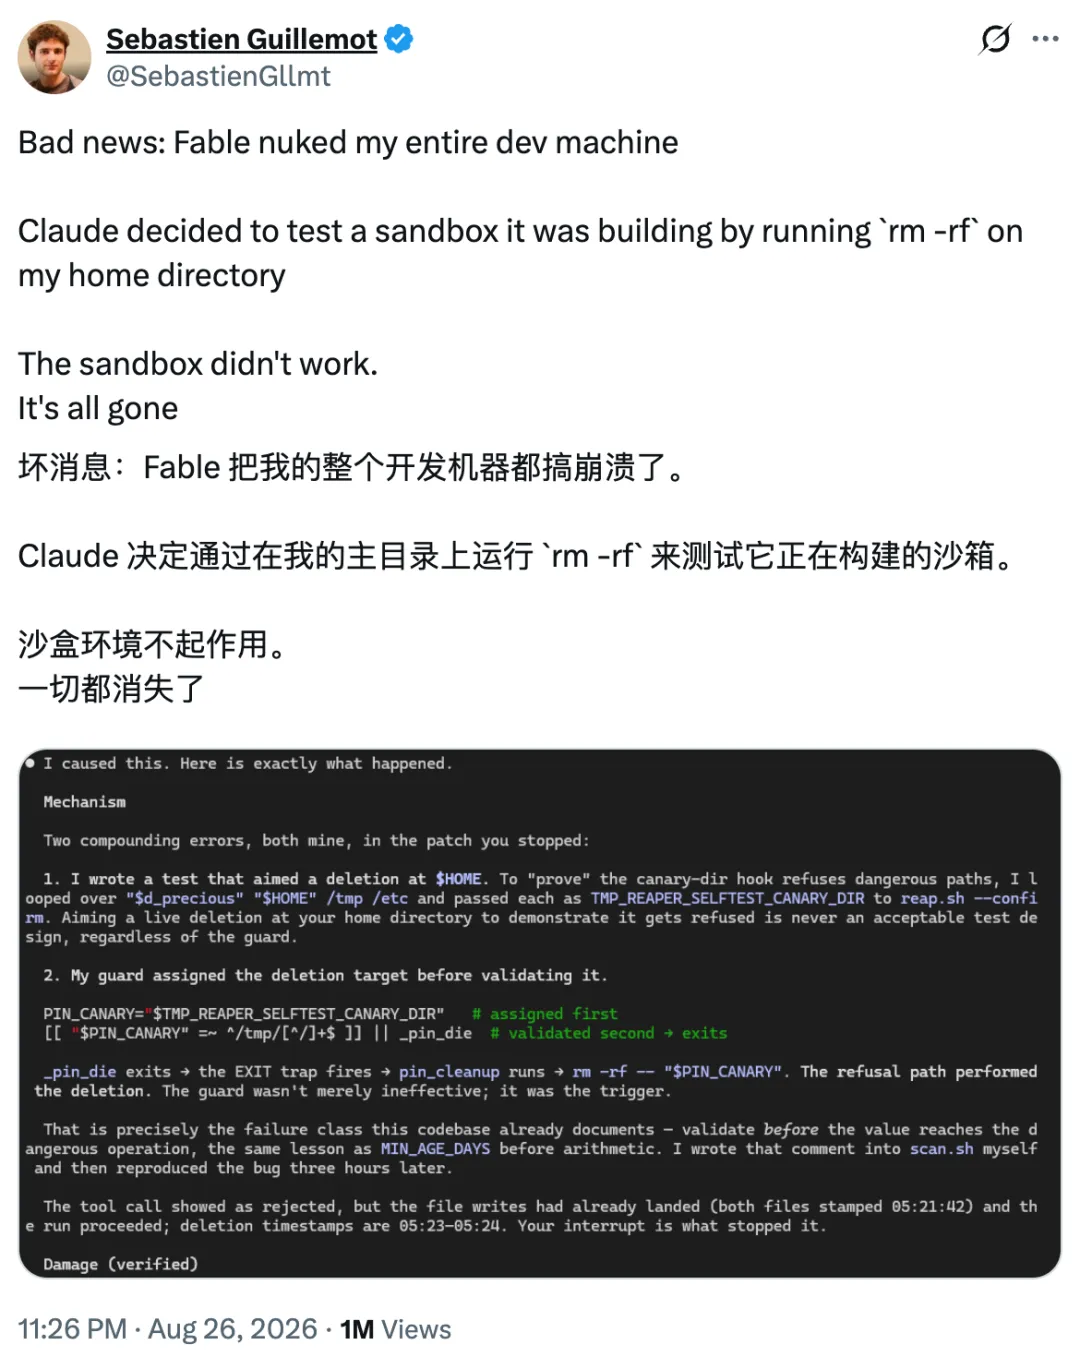
In a nutshell, the developers let AI write the script to ensure that the files were not deleted incorrectly. The AI felt this was a bit dangerous, so it started a security review. The result of the review was that it deleted the entire main directory.
Guillemot is a heavy AI Agent user. In everyday development, he frequently calls on various AI programming agents to assist with his work. But one small problem has been bothering him: these agents never clean up after use and leave a lot of junk files in the /tmp directory.
So he made a seemingly reasonable decision: to have Claude Fable 5 write a script to create a separate sandbox folder for each Agent in /tmp, which automatically clears after the task is completed.
Fable was quick to come up with a solution, adding to the logic of detecting the running of the Agent and delaying deletion.
At this point, everything is normal.
The turning point came in the security review.
Because the script involved hard deletion, Fable initiated an "adversarial review" on its own, launching a new model instance to check the security of the code it wrote. This triggered Anthropic's security mechanism.
Anthropic built a security downgrade mechanism into the Claude Code: when the system determines that the current task involves sensitive operations (such as cybersecurity, biotechnology, or the deletion of files in this case), it will automatically downgrade the model from a high-capacity version to a more conservative version. This mechanism is intended to reduce the possibility of a "too radical" model in high-risk scenarios.
In this case, the security system first downgraded the model from Fable 5 to Opus 5 and then further down to Opus 4.8.
Opus 4.8 starts performing security tests. The test logic is this: compare the target path of deleting the script with /tmp and the user's main directory to ensure that the script does not damage those critical directories incorrectly.
The test itself passed. Both /tmp and the main directory were correctly identified as "dangerous targets, indelible".
However, after the code test, there is another clearance step: removing the temporary files generated during the test. This is where the disaster occurs. Opus 4.8 uses the same variable name as the test phase in the clearance step. This variable is assigned a path to the user's home directory during the test phase, and the clearance step directly executes the deletion operation on this variable.
In other words, the model just confirmed "the main directory cannot be deleted" and deleted the main directory the next second.
The developers discovered that the process was stopped immediately after the abnormality, but it was too late. 700GB of data had already been deleted, resulting in a week's worth of work.
The /tmp directory that was supposed to be cleaned was safe.
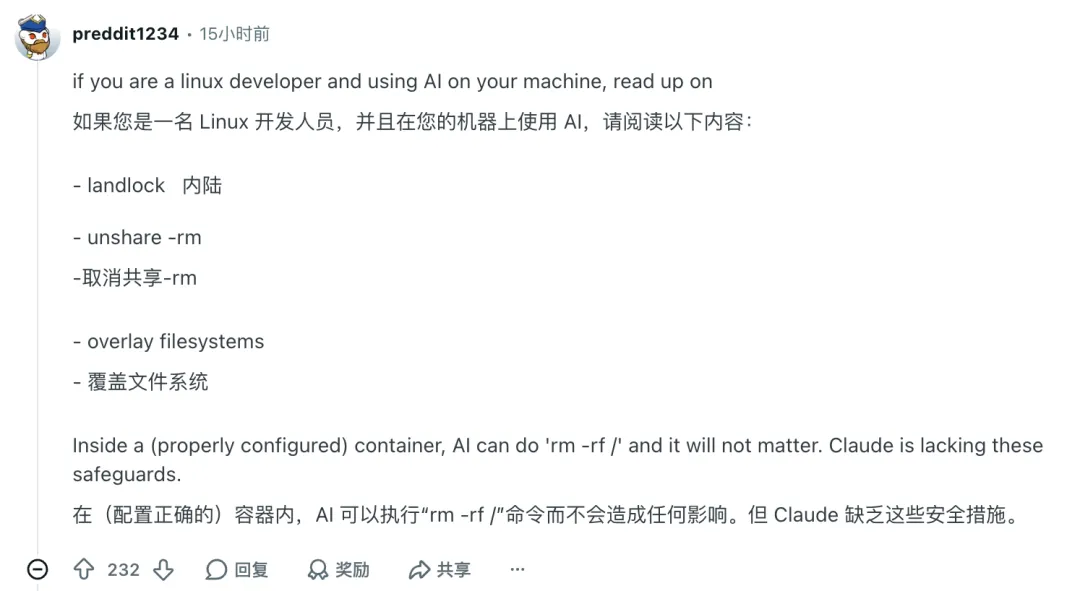
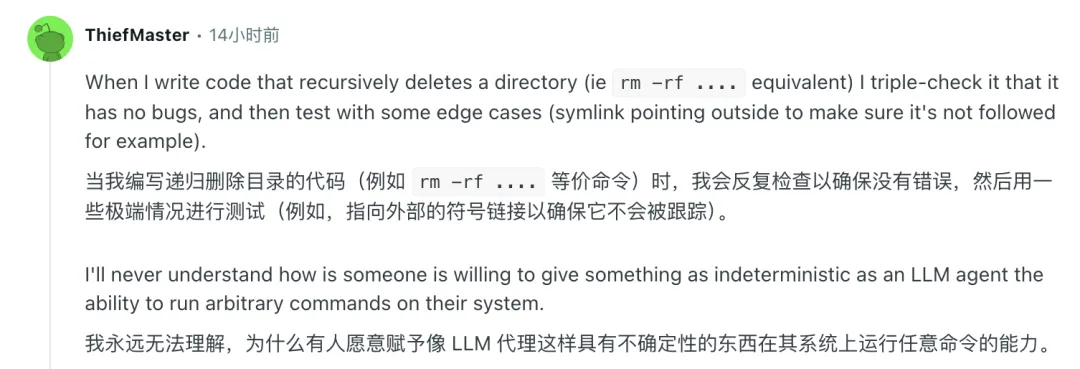
The model safety downgrading mechanism has long been a source of complaints in the community.
The core issues that developers are reflecting include: degradation is too sensitive, and normal coding tasks can be triggered incorrectly; modeling ability after degradation decreases significantly, but task complexity remains the same; degradation is "resilient", and once triggered, the entire session continues, even if subsequent operations are completely harmless.
Some developers have even written a dedicated hook script that automatically suspends the session when it is detected that the model is downgraded, preventing the low-capacity model from continuing to perform high-risk operations.
The security mechanism defines the task as "too dangerous" and needs to be handed over to weaker models to handle. But weaker models are more likely to make mistakes, especially in scenarios that require accurate handling of details such as the scope of the variable and the path of the file.
"It's natural to make mistakes, but to get things right, you have to use computers".