It's the first time in the history of the world.
Just now, the world's first 3 trillion-parameter open-source model, the Kimi K3, is officially open source!
Moonshot AI announced the release of the Kimi K3 model weight, technical report, and open source support for the key Infra technologies for training the Kimi K3 model: MoonEP, FlashKDA, and AgentEnv.
K3 is not only a 2.8T native multi-modal MoE giant with parameters up to 2.8T, but also the world's first open source model in long-logic chain programming, cross-context intelligence collaboration, and complex reasoning to match the most powerful closed-source models currently available (Fable 5 and GPT-5.6 Sol).
This landmark work not only demonstrates the strong strength of China's AI team in R&D, but also brings true front-end intelligence to the open source community.
K3 Open Weight, ushering in an era of 3 trillion parametric open-source AIOn July 27, 2026, Moonshot AI fulfilled its promise that the full model weight of the Kimi K3 will be officially released to the global open source community.
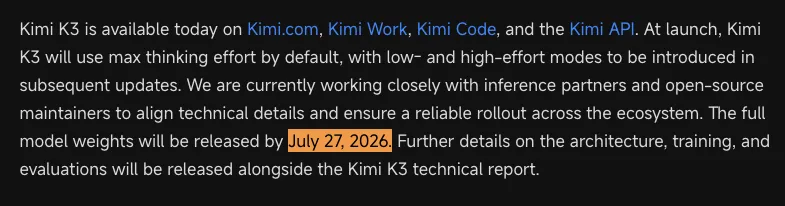
This marks the official entry of the open-source model into a new era of 2.8 trillion parameters, and the Kimi K3 also became the world's first truly landing 3 trillion parameter-level open-source model.
This release includes not only the model weight, but also the relevant technical details and reports.
Moonshot said they have worked closely with several reasoning partners and open source advocates to ensure K3 runs reliably across mainstream hardware and frameworks.
This means that chip developers can download full weight for local deployment or re-development; research institutions can explore topics such as ultra-large-scale MoE, new attention mechanisms based on K3; and enterprises can build proprietary transcendental contextual knowledge systems and smart agent clusters.
Open source communities will kick off a new wave of applications!
Parametric scale: Raise the ceiling once moreOver the past year, the Kimi series has been updating the parameters and capabilities of the open source model almost every quarter.
K3's 2.8T parameter is not only one of the largest open-source models currently known, but also the first to truly transcend the existence of the "3T Club".
In comparison to its predecessors, K2 and K3 have made significant breakthroughs in architecture:
KDA hybrid linear attention mechanism, designed for ultra-long sequence design;
Attention Residuals, enhancing the training stability of deep models;
MoE was greatly optimized: 896 experts activated only 16 and combined with the Stable LatentMoE framework greatly improved computational efficiency while maintaining huge parameters.
According to official data, these innovations have improved the overall expansion efficiency of K3 by about 2.5 times that of K2, effectively balancing "scale" with "availability".
The main difference from the Kimi K2.5 is that the visual encoder MoonViT-V2 of the Kimi K3 is trained from scratch, relying solely on subsequent token predictions, and can be directly adjusted to the characteristics of the encoder based on language modeling objectives.
During the entire training, the MoonViT-V2 remained stable.
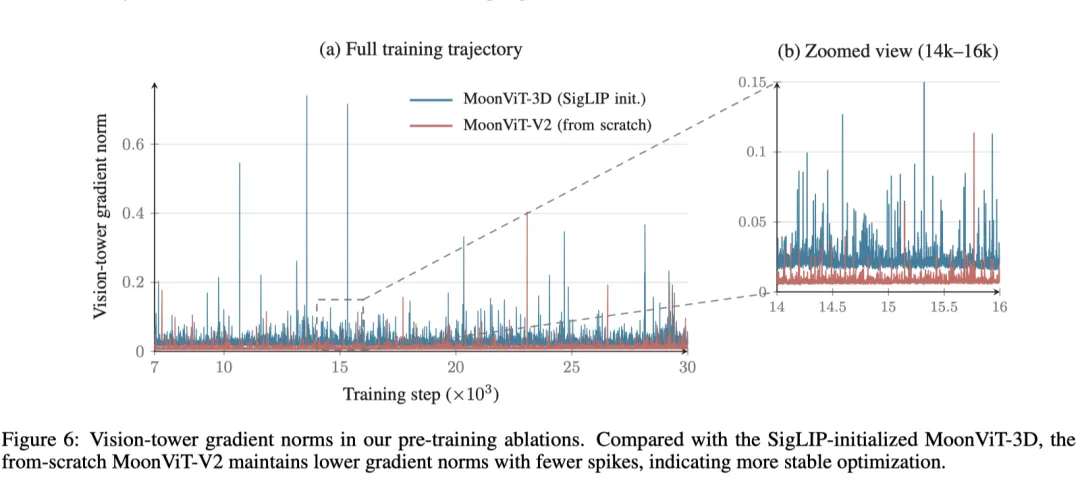
It is worth noting that the performance of the MoonViT-V2 in visual evaluation is comparable to the baseline model of SigLIP initialization.
It supports over 1 million tokens in context and is multimodal in nature.
In short, K3 is an integrated evolution of architectural innovation and its adaptation to the scene.
The official technology blog emphasizes that "front-end intelligence belongs to everyone". Kimi K3 is the latest practice of this concept.
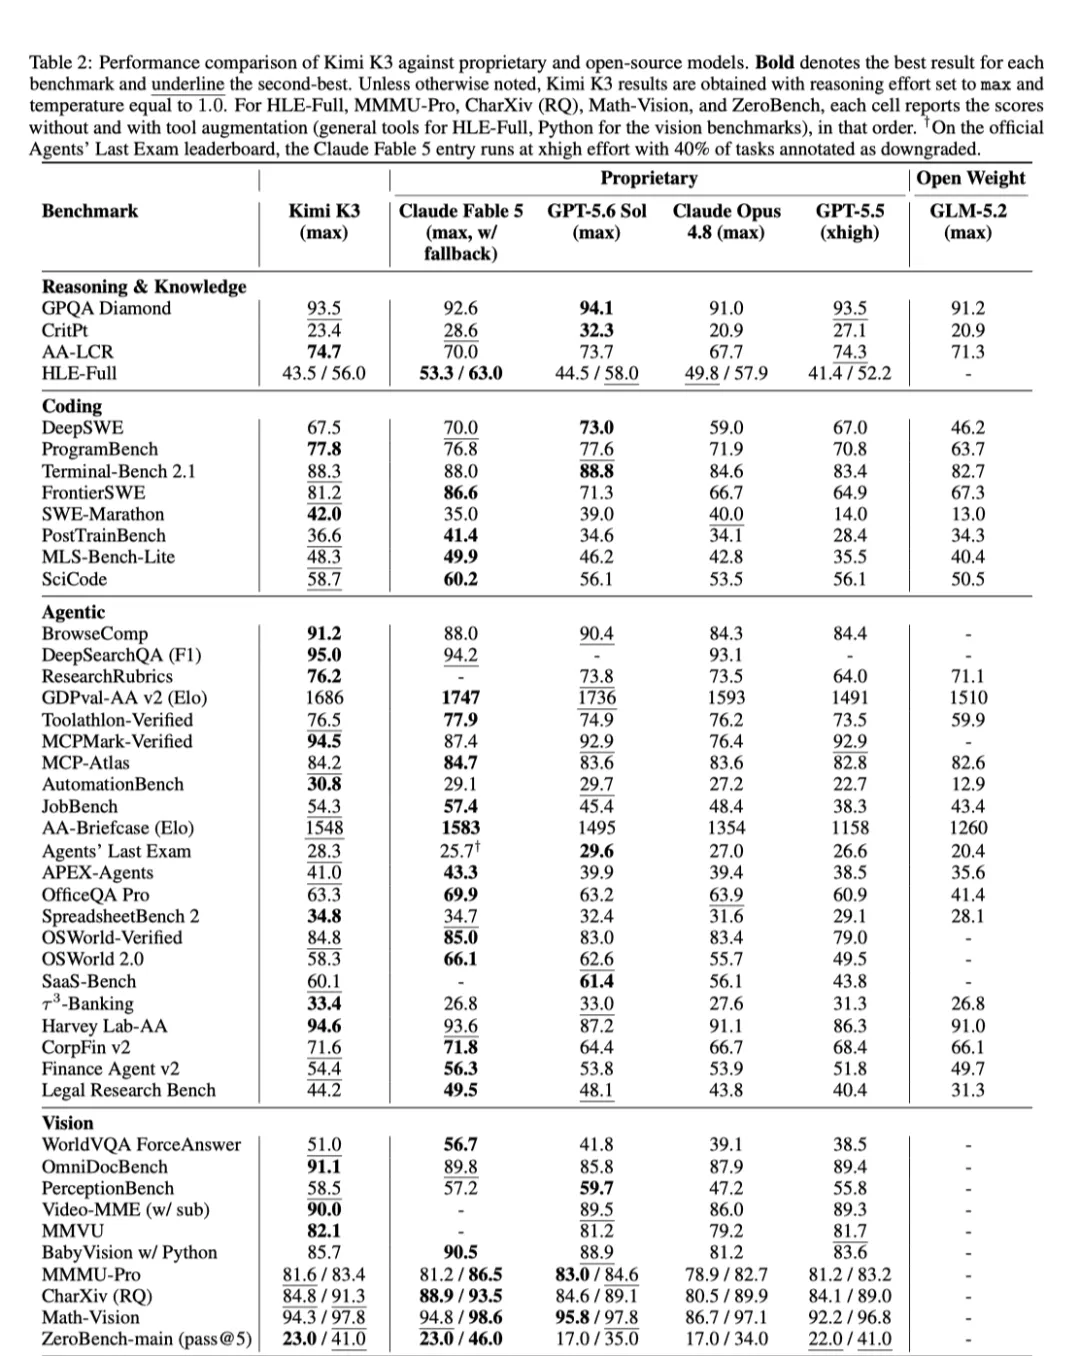
According to official and third-party assessments by Moonshot, Kimi K3 excels in programming, code agents, front-end development, and context-based reasoning.
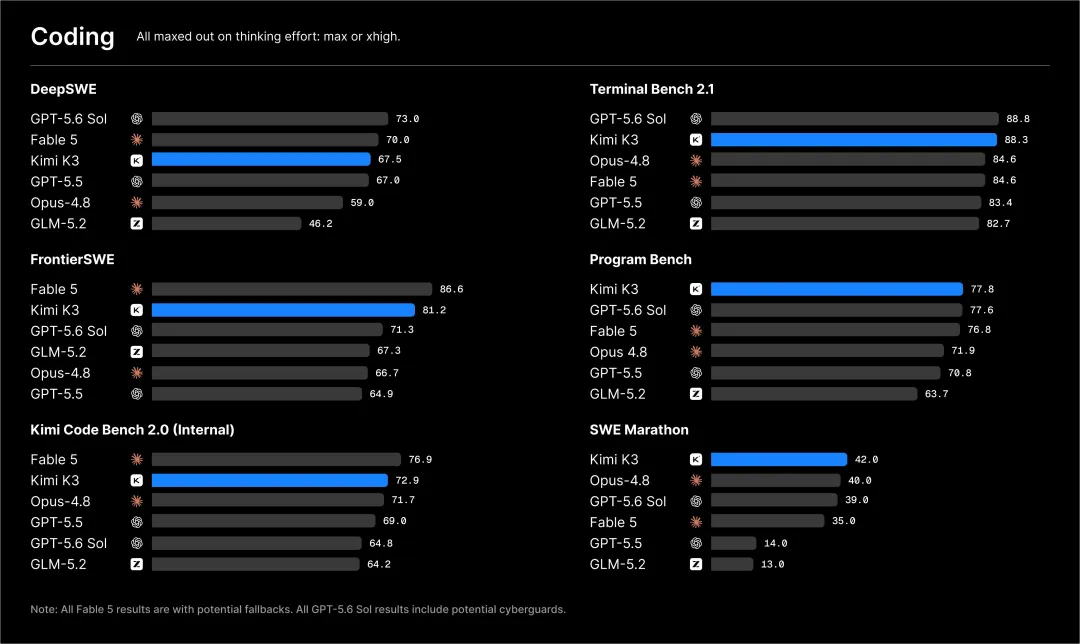
Its overall intelligence level ranks first in the global ladder, behind only a handful of closed-source top models, and is a leader in the open-source camp.
Kimi K3 technical report readThis is a 47-page technical report, released alongside the open source message.
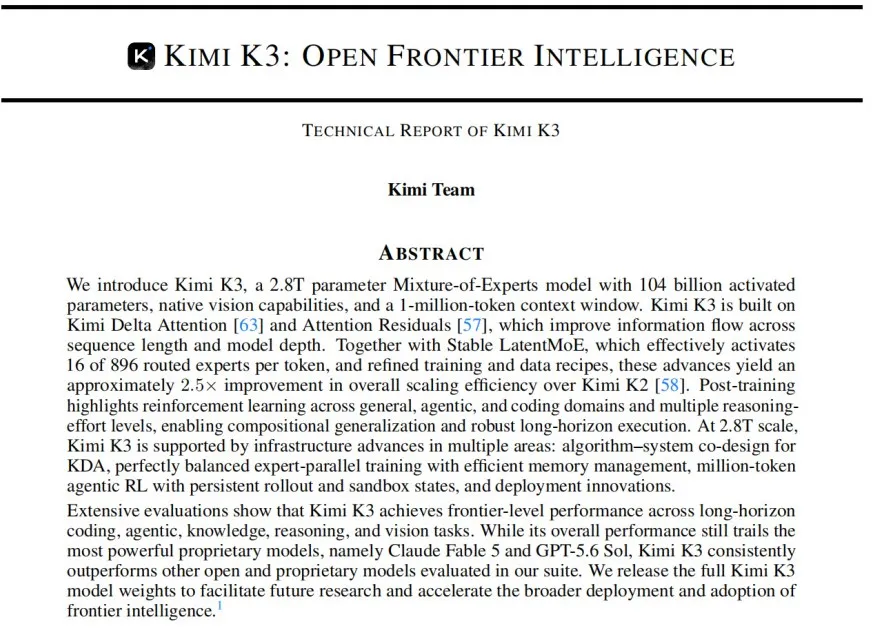
The following is the core content of the technical report:
The six-sided warrior is the source of 2.8 trillion arguments.Kimi K3 tells us that open source models can also do extreme scaling and reasoning.
The core data of Kimi K3 is lavish:
This is an amazing body:The total number of parameters is high.2.88 trillionFor each token, the activation parameters are:$104 billion。
It's a million degrees below:It's a great way to get started.One million tokensIt's a great way to get to the bottom of the page.
This is the first time I've seen this.Vision and text are intertwined from the first day of pre-training, with no later "combination" alignment stage.
I've been thinking about the test-time scaling:It supports multiple levels of Thinking Effort, from Low, High to Max, and can "think and backtrack" like humans in complex tasks.
Three major architectural innovations: 2.5x expansion efficiencyTraining a 3 trillion-parameter-level model is not a simple way to stack GPUs.
Kimi K3 is about 2.5 times more efficient in overall expansion than its predecessor, Kimi K2.
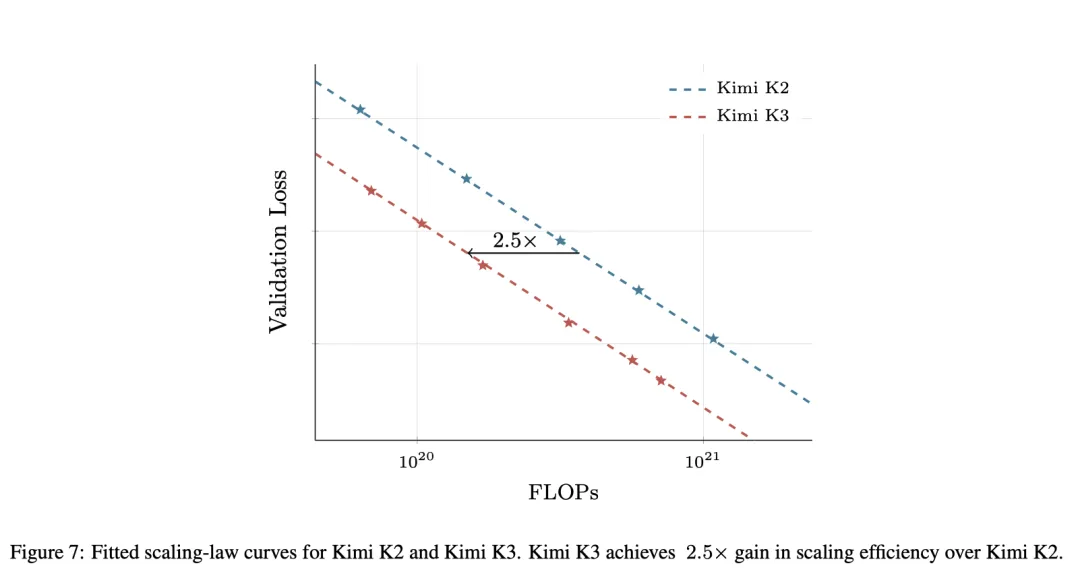
This is due to its extremely elegant and violent architectural design.
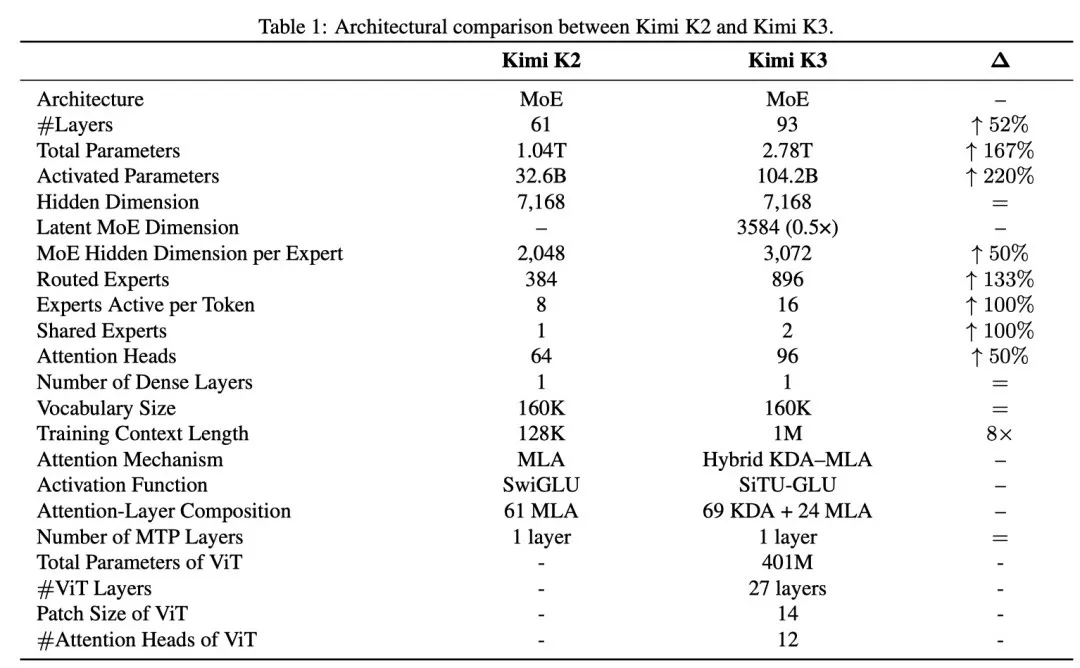
1. Mixed attention mechanism: KDA + Gated MLA
The traditional Softmax attention mechanism uses the KV Cache's memory to explode instantaneously when handling a million-level context. The Kimi K3 uses a unique hybrid architecture.
Each block contains three layers of Kimi Delta Attention (KDA) and one layer of Gated MLA.
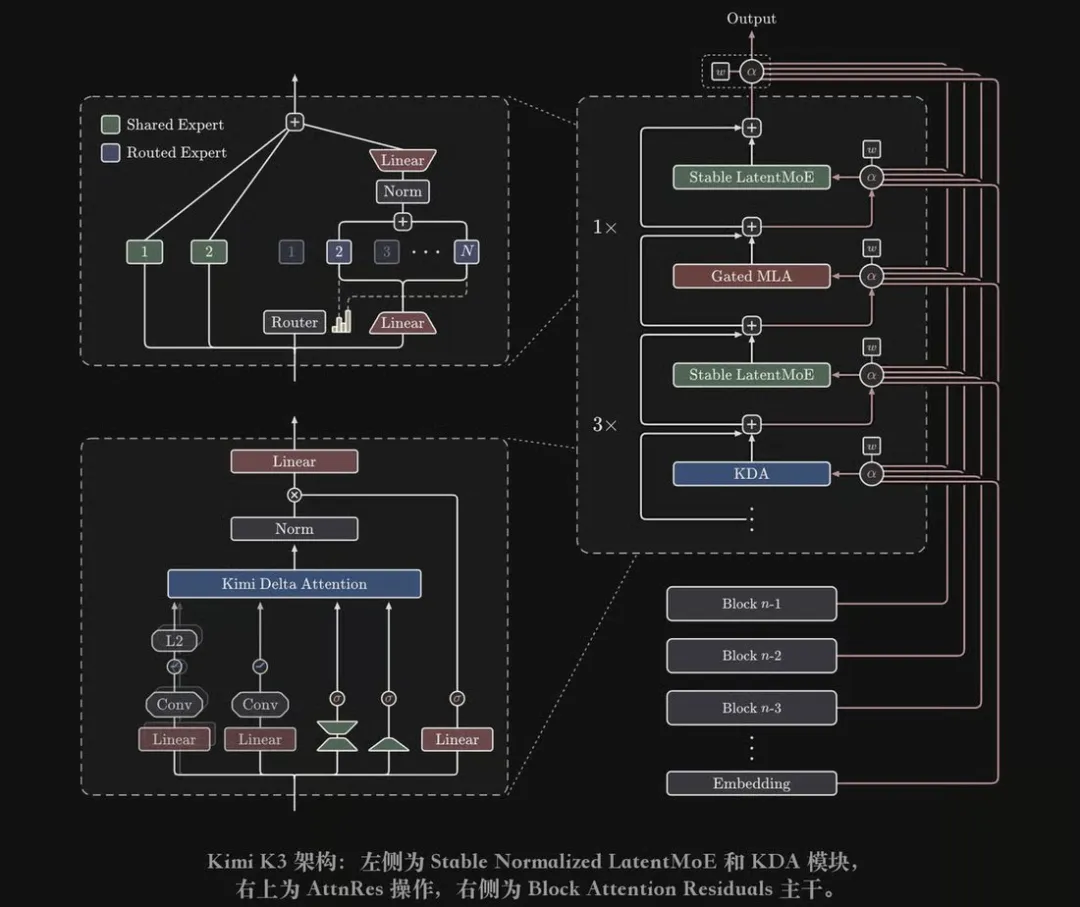
KDA (linear attention):It is responsible for efficiently mixing long sequences, compressing the longer context into a fixed-sized loop state, completely breaking the memory curse of the longer context.
Gated MLA:Cyclically maintaining extreme global information retrieval capabilities.
This combination of 3:1 preserves both the long text and the soul of detail.
2. Attention Residuals
In ultra-deep networks, information is often lost in layered transmission. Kimi K3 introduced Attention Residuals, which allows the current layer "trans-level" to read directly all of the layers' characteristics.
3. Stable Latent MoE as in Thailand
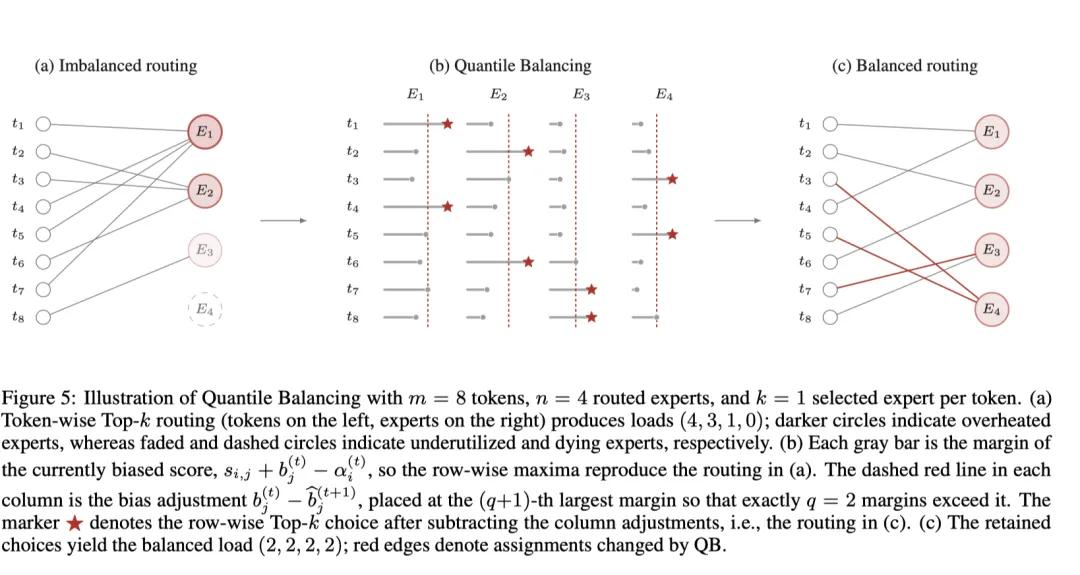
The number of experts on the route of Kimi K3 has risen to896 people.Each token is activated.16 of them.In order to maintain training stability in extreme scarcity (extremely few parameters are activated), the team sacrificed two large killers.
Activate the SiTU-GLU functionIt perfectly solves the problem of traditional SwiGLUs that can cause activation explosion at extreme scale.
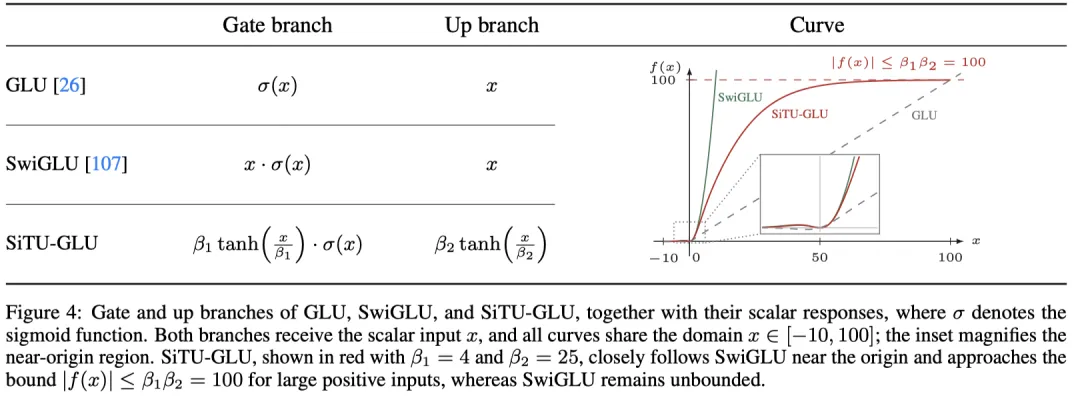
Quantile Balancing (quantile balancing)Abandoning traditional auxiliary loss functions and adopting a method of dynamic adjustment of bias, 896 experts "didn't stick around or get tired" and achieved near-perfect load balance.
The strength of the big model is not only in pre-training, but also in "post-training/RL"."One million tokens of ultra-long-range intelligence"It's customized.
1. Extremely complex white box sandbox training (AgentENV)
Kimi K3's training environment is no longer a simple question and answer, but a real simulator. The Dark Side of the Moon has developed a sandbox based on a microVM.AgentENV。
In this environment, Kimi K3 goes through hundreds of steps: writing code, scanning, searching for bugs, self-correcting. It even plays human employees in a simulated Slack, Notion, Gmail environment, dealing with ultra-long wait times that span "virtual days".
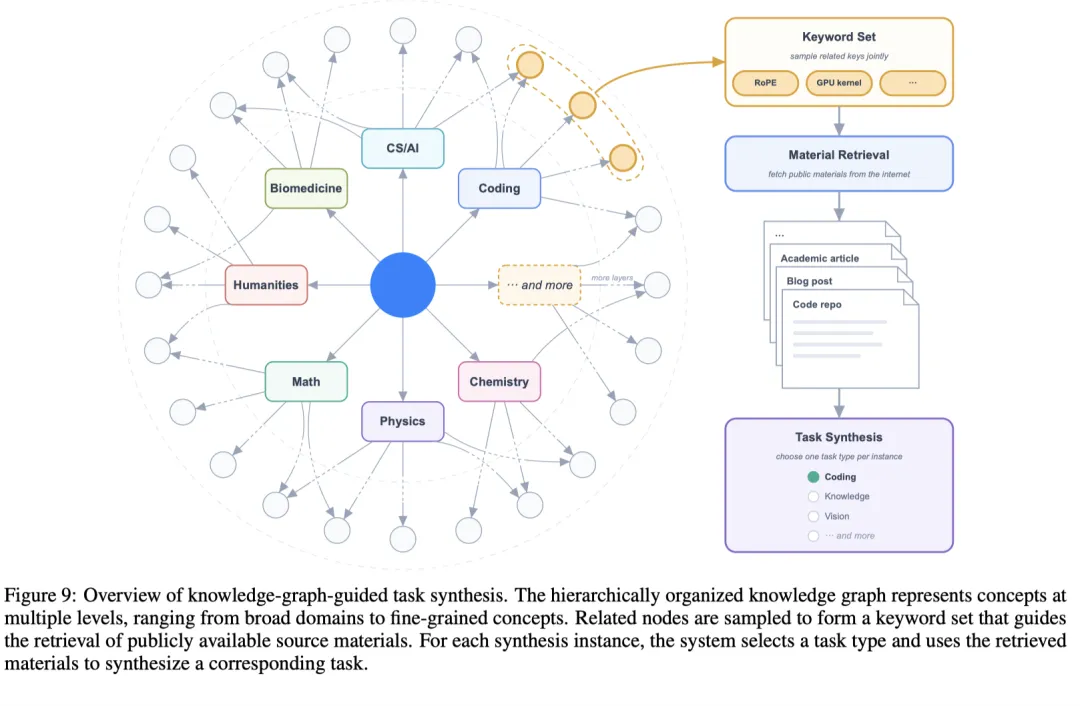
2. Synthesis of knowledge chart-guided tasks
In order to increase the visibility of the model, the R&D team constructed a self-evolving knowledge graph that enabled reptilian intelligences to automatically capture and synthesize the entire web, covering a variety of high-difficulty verification tasks from astrophysics to front-end development, in order to "torture" K3.
3. Multi-layered thinking distillation (MOPD)
The Kimi K3 cross-trains expert models in the three fields of general, intelligent, and coding, and reinforces training at the three levels of "thinking effort", low, high, and extreme.
Finally, by distilling multi-teacher on-policy distillation into a unified model, these powerful capabilities have been consolidated.
2.8T parameters, 1M in context, are not only a test of algorithms, but also an epic challenge for systems engineering.
The Kimi Infra team gave a surprising response.
MoonEP (Expert on Zero Waste in Parallel):In MoE training, uneven computational power is the norm. MoonEP achieves a fully dynamic and absolutely balanced computational allocation through extremely fine online integer linear planning and "zero-copy" communication.
KDA integrates Prefix Cache:For the hybrid architecture, the team rewrote the underlying reasoning engine, allowing KDA's loop state and MLA's KV Cache to be perfectly shared and replicated in a memory pool. This means that the response speed of K3 will increase exponentially when processing requests containing hundreds of thousands of words in the same antecedent.
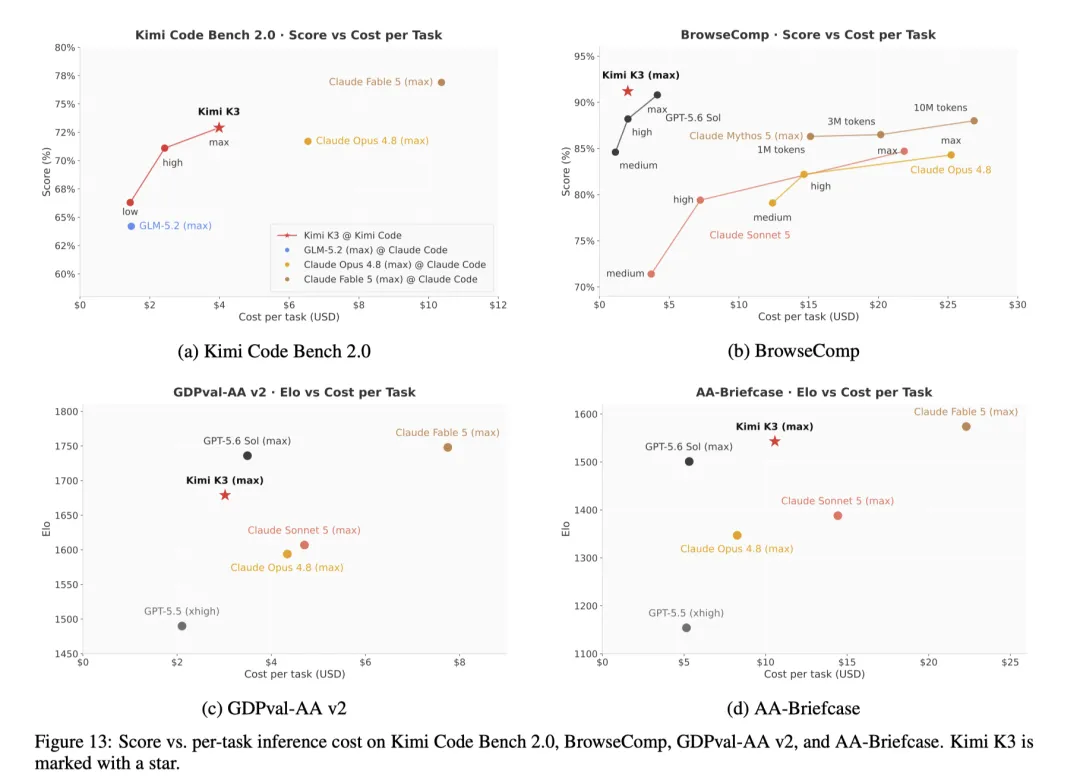
Experimental performance: approaching or exceeding human polarityIn the comprehensive evaluation presented in the report, the Kimi K3 has been demonstrated in public and internal benchmarking tests.Overall, it surpassed Claude Opus 4.8, GLM-5.2 and GPT-5.5, and is closer to the current strongest Claude Fable 5 and GPT-5.6 Sol.
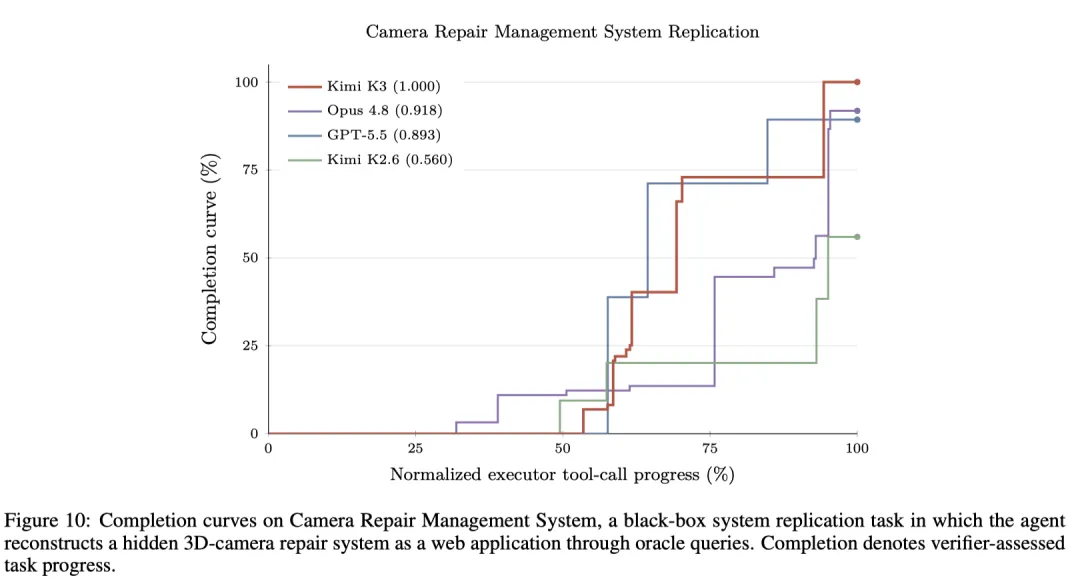
Kimi K3's performance in the real Arctic mission was amazing.
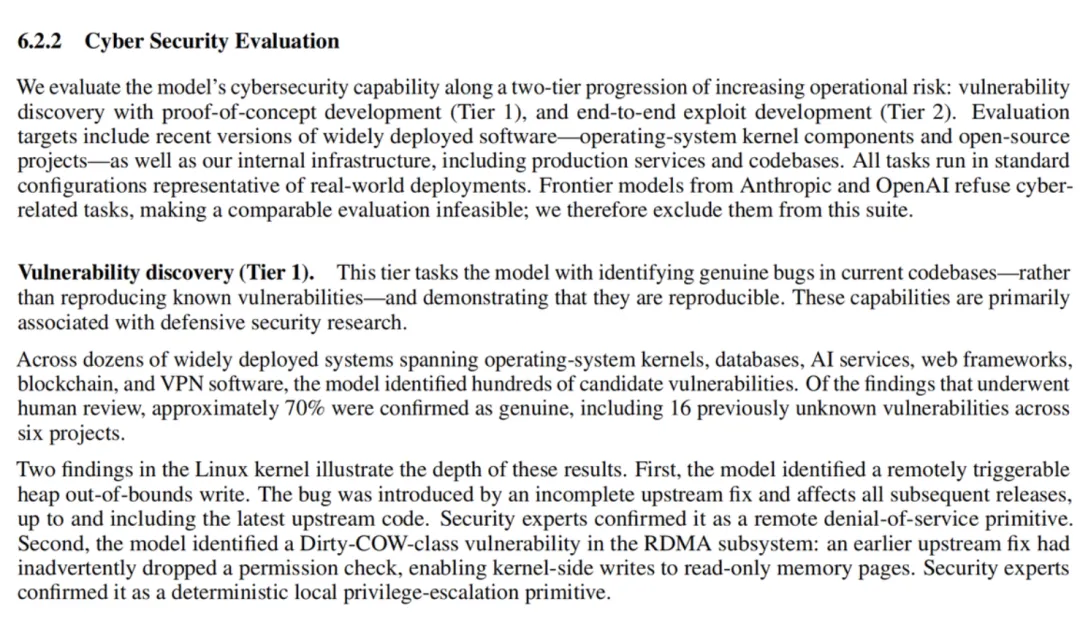
Finding the Zero-Day vulnerability in the Linux kernel
In an extremely hardcore cybersecurity assessment, Kimi K3 not only wrote exploit software using known vulnerabilities, but also discovered several unknown zero-day vulnerabilities in the latest Linux kernel code independently!
Including a remotely triggered stack of cross-border writing and a local privilege loophole, the findings have been verified by human security experts.
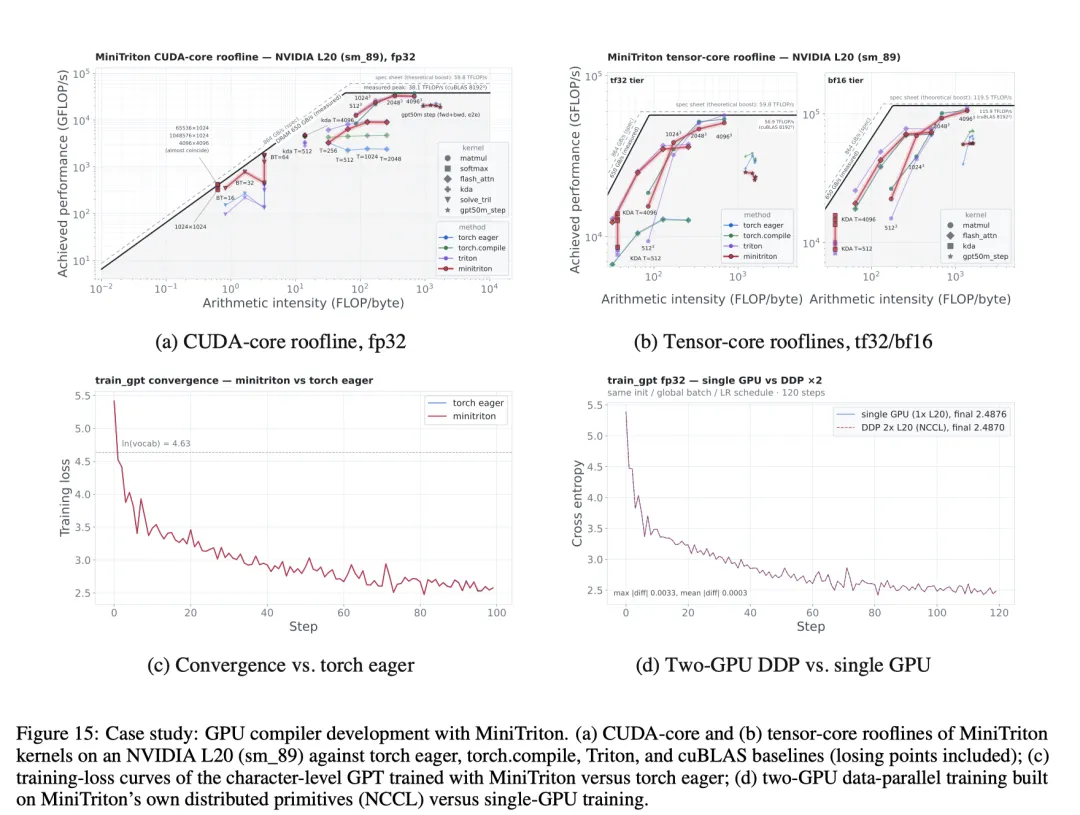
Blasting the GPU compiler
Kimi K3 independently developed a GPU compiler called MiniTriton, which contains complete code generation pipelines, and optimized for ultra-high difficulty kernels (such as KDA, DSA) to reduce runtime by more than 70%, approaching the hardware's theoretical limit.
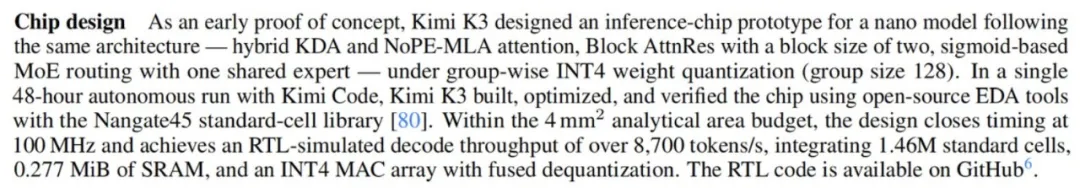
In 48 hours, a chip (Nano-KPU) was designed.
As an early proof of concept, K3 was locked in a sandbox for 48 hours, using fully autonomous open-source EDA tools to design, optimize and validate an AI reasoning chip based on a 45nm process from scratch, and finally successfully passed the time-closure!
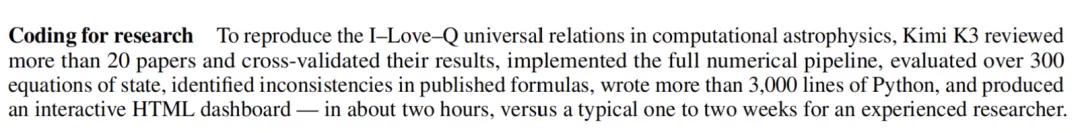
Substitute researchers working
In order to reproduce a common relationship in astrophysics, K3 independently read more than 20 papers, wrote more than 3,000 lines of Python code to build a complete numerical pipeline, found contradictions in published paper formulas, and generated interactive data boards.Two hours.It's done in there.
 Extreme sex ratio
What about the cost of the most powerful closed-source model?
Thanks to quantitative sensing training (MXFP4 weight/MXFP8 activation), speculative decoding (Draft Model) and insane optimization at the bottom of the system, the price of the Kimi K3 is terrifying.
In statistics from Artificial Analysis, a third-party platform, the Kimi K3 maintains its first-tier performance while maintaining its high performance.I'm not sure if I'm going to be able to do that.The cost of a single mission is only half that of the GPT-5.6 Sol, even more so than Claude Fable.5It's almost a quantity!
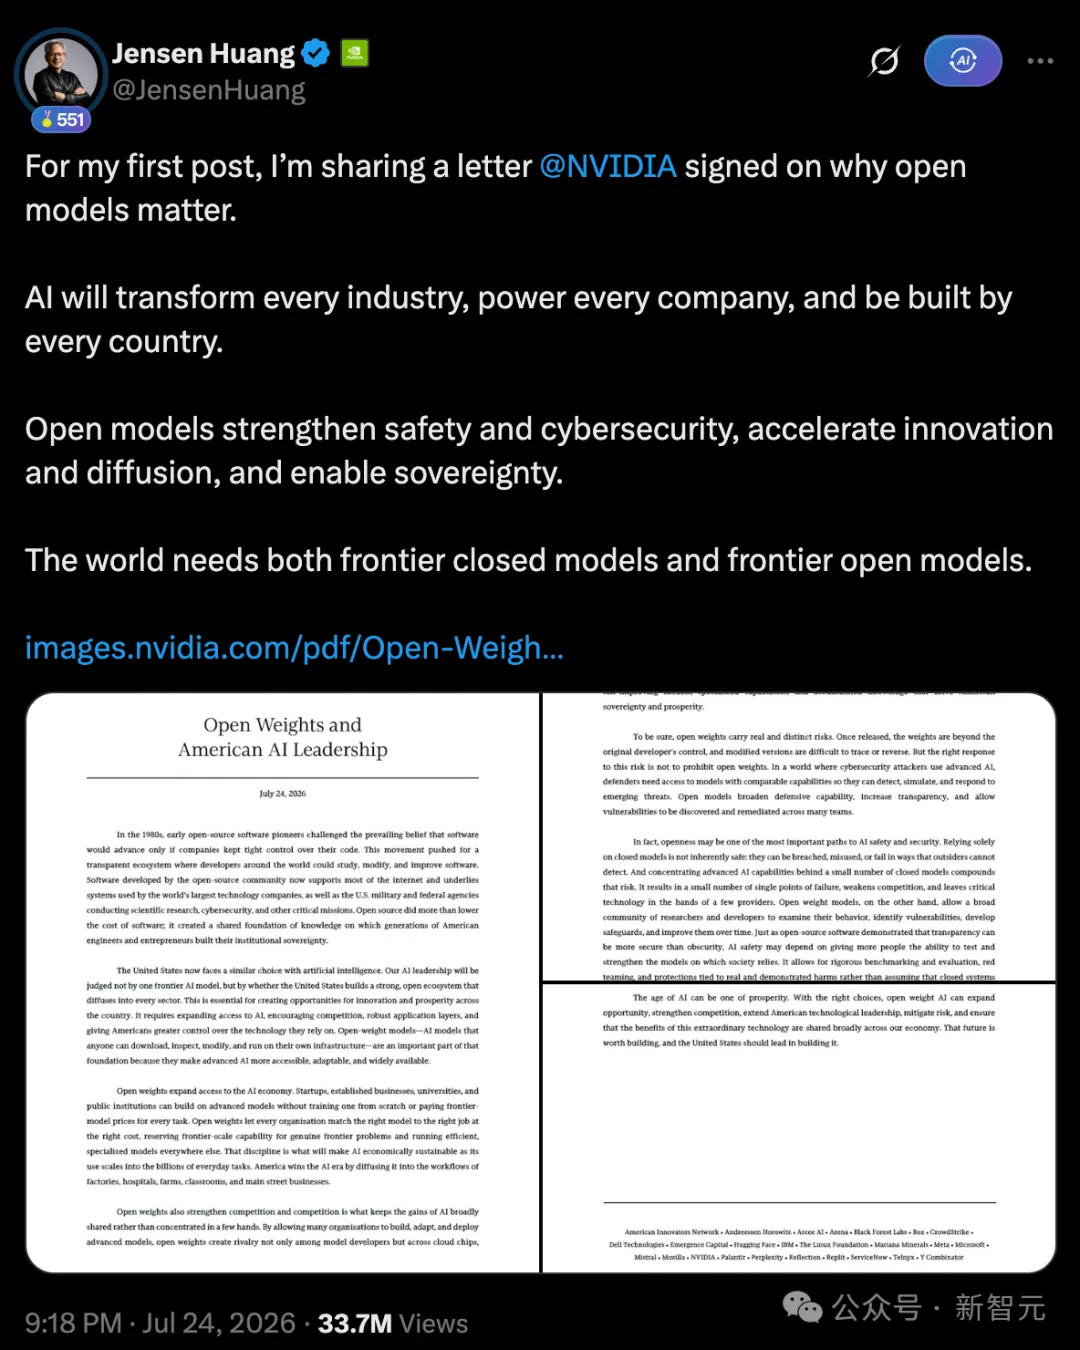
Recently, nearly 200 Silicon Valley founders have spoken out against the U.S. government cutting off channels for U.S. businesses to access the open source model.
Just this weekend, Huang launched its first push on X, with 25 companies co-signing why open source is important.
These 25 lists, including Intel, Microsoft, Meta, IBM, a16z, YC, and others, almost cover the half-walled Rivers of Silicon Valley.
There is no doubt that K3 is a full-fledged open source, even more important, at this peak.
In today's Arena.ai list, the Kimi K3 remains in the Top 2 globally.
Open source light that illuminates the forefront of intelligenceThe national open source route is also an opportunity for a tunnel supercar in the face of a closed source giant.
It is anticipated that a large number of community-optimized versions, local deployment schemes and vertical applications will emerge with the full opening of K3 weights.
Once the open source of Lama, Meta broke the monopoly of the closed source giant, ignited the enthusiasm of the global open source AI community, and spawned countless derivative models and applications.
Today, the rise of open-source AI in China, represented by K3, may radically change the rules of the game for big models around the world.
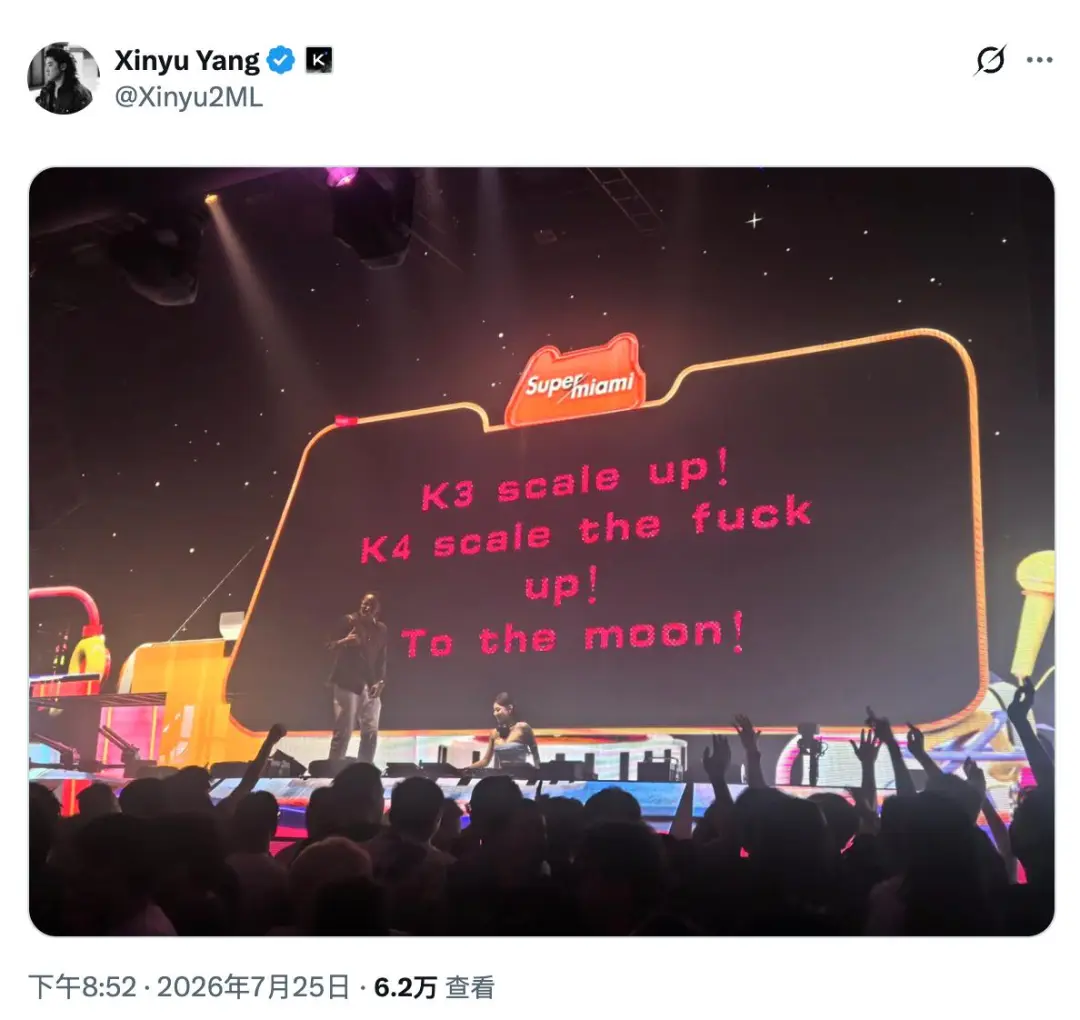
According to reports, the Kimi team held a celebration at a bar on Friday. The live screen reads "K3, expansion upgrade", "K4, give me a hard time" and "Run to the Moon".
Just hours before the launch of Kimi K3, it was announced that Kimi K 3.1 would be released next month.
"While overall Kimi K3 is still slightly behind the most powerful closed-source model, it has firmly established a whole new frontier in the open-source space".
Kimi K3 was born in space, breaking the bias that "only closed source giants can play with a million-level agent and slow thinking".
When the code, weight and technical details are unreservedly open, the Star Ocean of Open Source AI is just getting started.