One Skill can make DeepSeek V4 Pro better than Fable 5?
Two days ago, J-Space quickly brushed the screen with an exaggerated set of test results, not expecting a complete overhaul today.
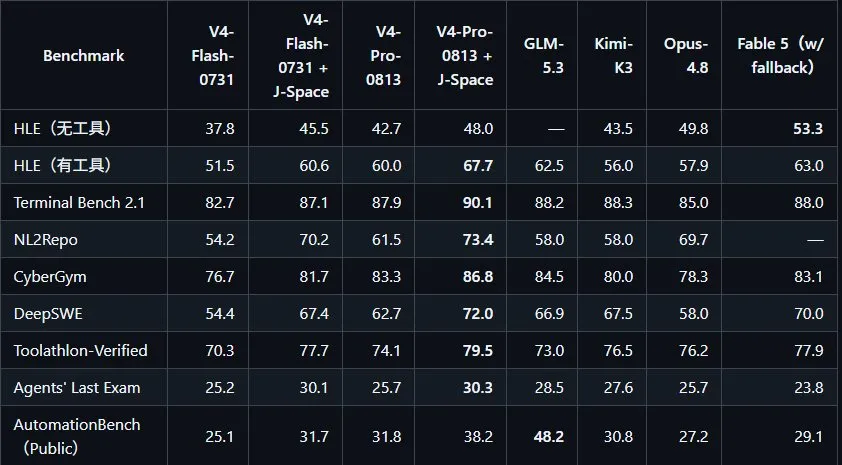
The authors claim that just by bringing a Skill into the Agent environment, V4 Pro can be significantly improved on multiple benchmarks, with some achievements even exceeding Fable 5, and speeds and Token efficiency more than doubled.
However, the results of the community review are quite the opposite, not only did not improve the score, but also spent more tokens.
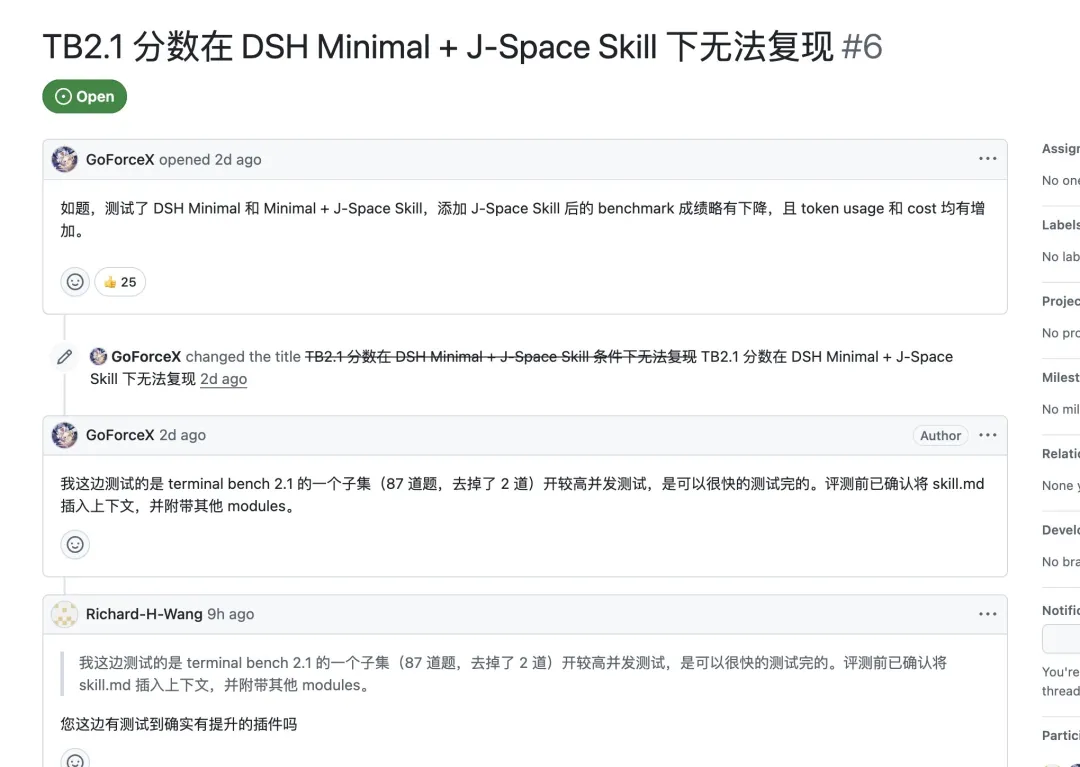
In the face of questioning from netizens, the authors not only failed to disclose the full assessment records or run logs, but also were exposed to removing the questionable issue.
In the meantime, a rave turned into a public hoax.
A Skill to make V4 Pro better than Fable 5?
The project is called J-Space Cognition Suite V3.6.
According to the project, this is a set of unrelated reasoning-time controls. It does not modify the model weight, nor does it require thinning, but adds to the Agent operating environment in the form of Skill.
DeepSeek V4 × J-Space is capable of releasing reports.
The authors of the project classify the common mismanagement of the Agent into four situations.
The first is the overloading of the workflow. The tasks are crammed into too much target, limit and tool information at the same time, and the really important content is flooded instead.
A name, numerical value, or task goal is gradually changed between multiple rounds of reasoning and multiple documents.
The third was ineffective retesting. After the call failed, the model did not retain the diagnostic information, only running again along the original route.
The fourth is premature completion. The model generates a seemingly fluid response, mistakenly assuming that the task has been completed, without verifying whether the results are actually available.
These problems are particularly common in long-range Agent missions.
J-Space attempts to organize the entire execution process into a more stable cycle: short judgments, execution of operations, in-depth reasoning, verification of results, and recovery of diagnostic information after encountering problems.
It will also limit content that remains active at the same time in the current workspace, writing down key objectives, verified information, unresolved issues, and the next steps in operations into the external ledger.
Simply put, J-Space wants to prevent models from forgetting what they're doing in the process.
It sounds simple, but the results are quite surprising.
The report claims that after joining J-Space, the V4 Pro's Terminal Bench score increased from 87.9 to 90.1,NL2Repo jumped from 61.5 to 73.4, and DeepSWE jumped from 62.7 to 72.0.
In contrast to the public performance in the report, V4 Pro even outperformed Fable 5 and Opus 4.8 on some aspects of the Agent and programming benchmarks.
False reversals are deleted
The first negative results came from Issue from the J-Space warehouse.#10。
One developer conducted two rounds of A/B testing using V4 Flash, covering mathematical reasoning, code generation, warehouse development, and disruption recovery.
In the second round of experiments, the control group and the J-Space group ran three rounds, for a total of 12 rounds respectively.
The results showed no significant difference in the completion of the final task between the two groups, while the J-Space group consumed more resources.
In third-party blindness, the control group scored an average of 8.30, while the J-Space group scored only 7.87.
The experiment was limited in scale and used V4 Flash and customization tasks that could not cover all of the benchmarks in the J-Space report, but also raised some questions about "the performance, speed and efficiency improvement of Token at the same time".
Afterwards, more substantive results emerged.
User Jyleaves in Issue#26The company said it deployed V4 Flash with eight NVIDIA H20s and loaded J-Space in DeepSeek Harness Standard mode.
In 89 routes, the model passed 69 routes, scoring a final score of 77.5%, while the corresponding score given by the J-Space report was 87.1%.
The testers also said that the failed mission had been restarted at least three times and had not been upgraded in the report and questioned the authenticity of the project data.
As a result, the testers asked the authors to disclose the complete assessment environment, test process and sample output.
More to the point, there are developers at Issue.#23The company said its previously published questionnaire Issue was deleted by the authors, so it can only re-post backups.
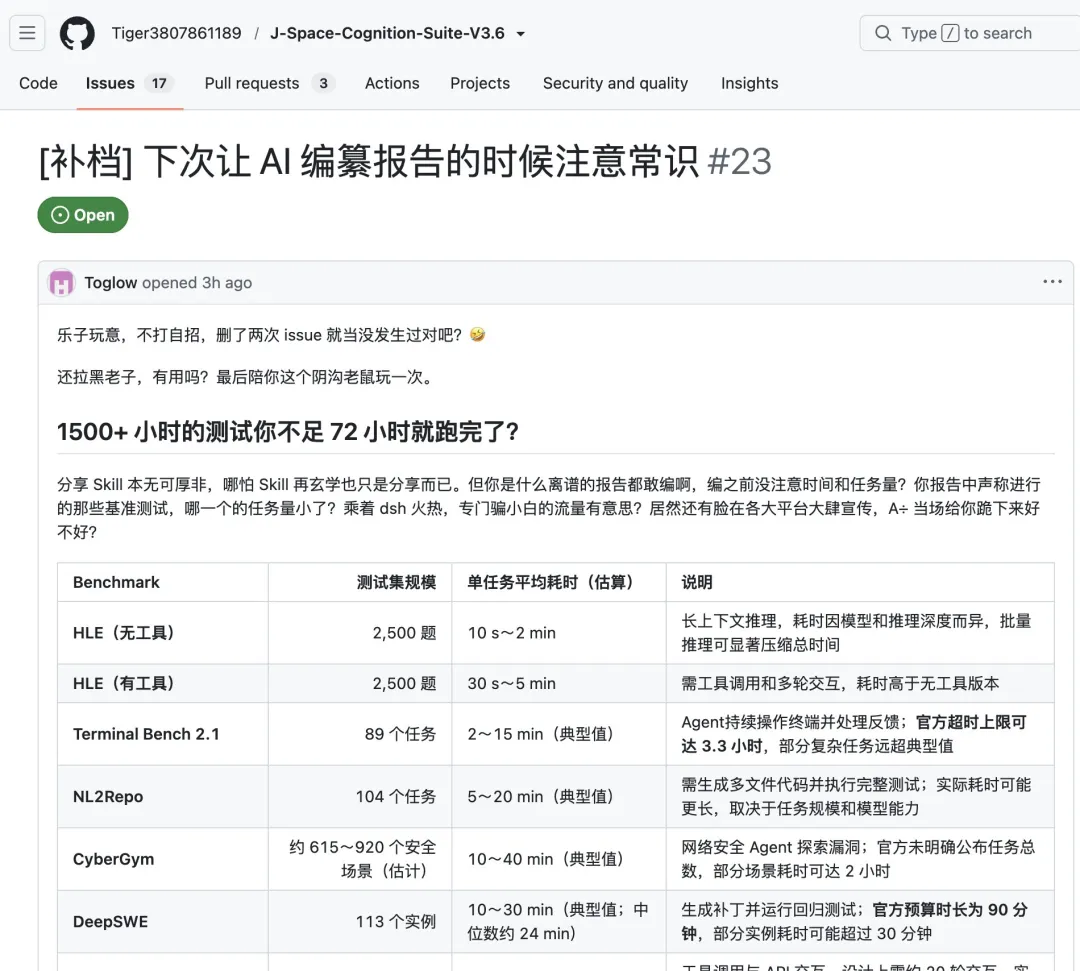
It's not the same as trying to make a name for yourself.
Exactly where the V4 Pro is.
It's rare for an intelligent disguise to be invented out of thin air, and everything seems to be going smoothly as long as it takes advantage of the fact that it already exists.
J-Space accidentally stepped on V4 Pro's top concern: it was too sensitive to the external operating environment.
From the very beginning, we found that V4 Pro performed very poorly under different users and different calling conditions.
The official version of the game was released that evening, with two similar suggestions to test the 3D helicopter game. At 0:50 a.m., the results of the model production were still very rough; less than four hours later, it delivered a much more complete project.
Netizens speculate that the differences may come from outside the model, such as Harness.
In an engineering task called Project2, the same V4 Pro running in DeepSeek Harness's Standard mode scored 91 points, the PTC mode scored 92 points, and after switching to the less tooly Minimal mode, the two tests scored 99 points and 96 points respectively.
Models and missions remain unchanged, with the external operating environment bringing a gap of nearly 8 points.
In the meantime, a number of targeted initiatives have emerged.
The Routing Suite attempts to choose a reasoning model based on the type of task, to prevent models from overthinking simple tasks, encountering complex tasks and acting prematurely.
GitHub:
Anchored Standard focuses on the first model request: the first round uses brief hints and a small amount of tools to get the V4 Pro into a relatively stable trajectory and then open up full tool capabilities.
GitHub:
This is where J-Space is most confusing, borrowing from a real-life problem.
Moving forward with this set of logic, a "more than Fable 5" form can spread across the community in a matter of minutes, but it's not that easy to verify.
The higher the number, the more surprising the number, the better to ask a question.
The link is as follows: