It's the first time in the history of the world.
The AI circle has gone to hell again!
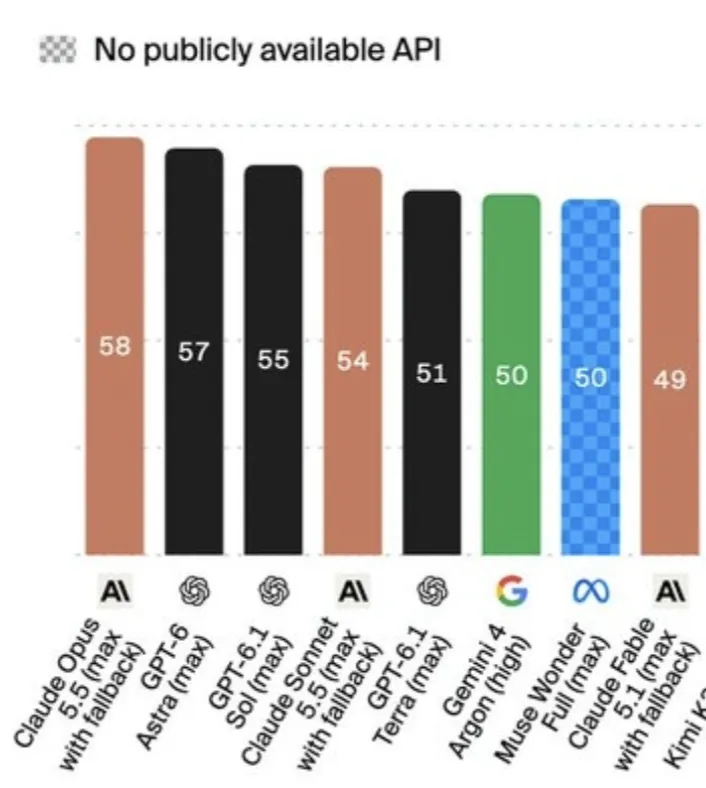
Artificial Analysis has just updated the Intelligence Index, officially launching v5 version, and Claude Opus 5.5 has taken the top spot, squeezing OpenAI's GPT-6 Astra down the aisle.
However, it wasn't long before Gemini 4 Carbon was released, surpassing the Claude Opus 5.5 for the first time!
But a mysterious model, code-named "Obsidian 3" suddenly surfaces, and all the clues point to the same name: Anthropic has not yet been released.Fable 5.5。
In less than a night, the champion of Opus 5.5 wins the GPT-6!The list of AI has been updated.
Artificial Analysis has released the latest Intelligence Index v5 list. This is one of the highest and most difficult gold-containing tests in the industry.
The result was unexpected, but also in a positive way.
It's an Anthropic.Claude Opus 5.5 wins by 58 points and takes first place.
OpenAI is the first of its kind.The GPT-6 Astra fell to second place with 57 points.
What's dramatic is that Google has released it.Gemini 4 Carbon, with a combined AA score of 59.
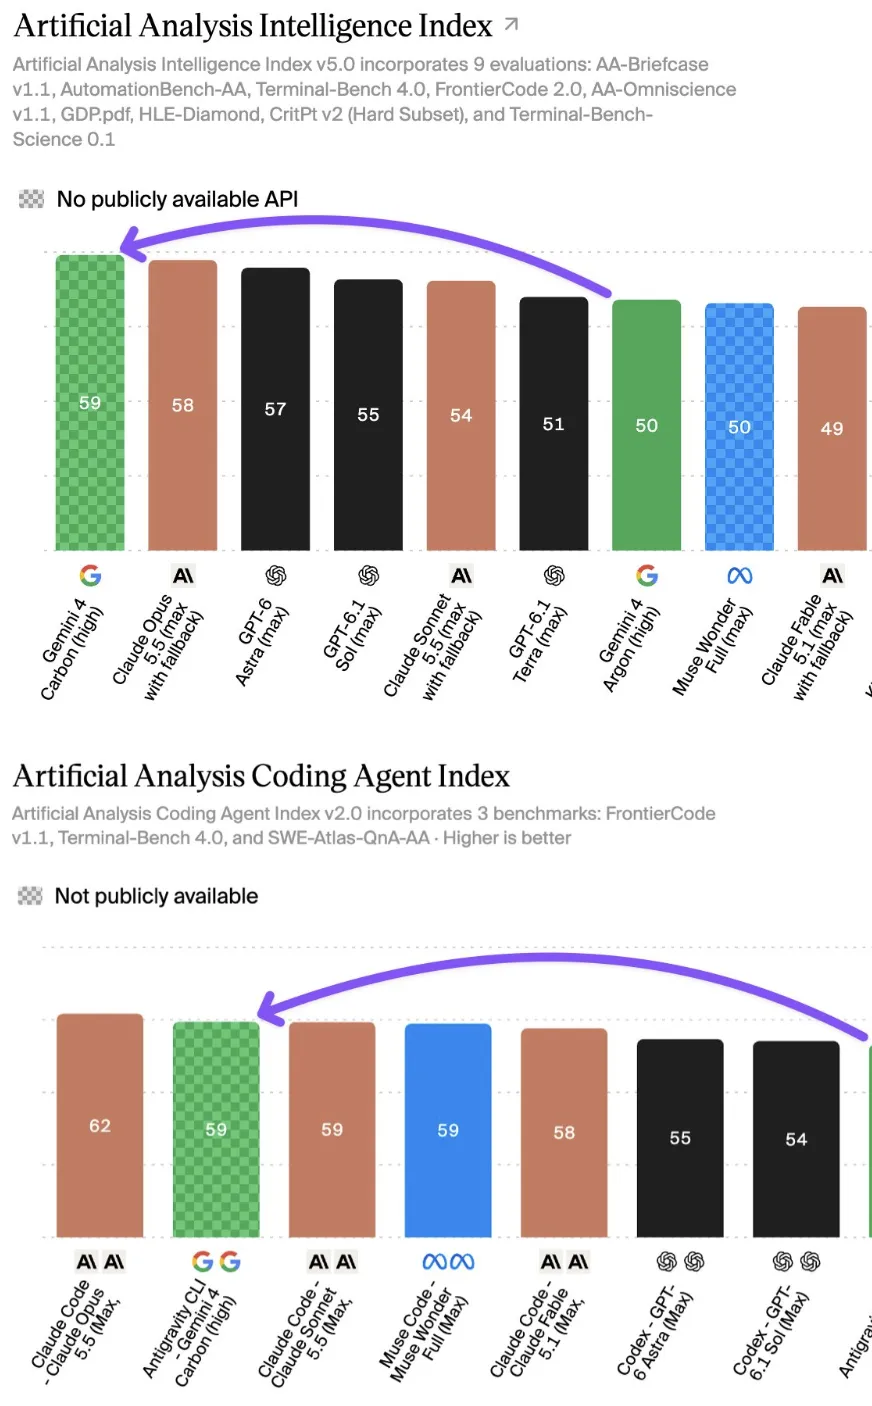
In the meantime, AI's throne is easily reigned twice overnight.
But on the programming intelligence index, Anthropic still leads by 62 points.
Why is there such a high amount of gold in the Anthropic Index of Programmed Intelligences? Because the rules of testing have changed, it has become extremely harsh.
The weight of private data has risen to 60%.
In past AI tests, everyone is browsing the list.
This time it didn't. Officials directly pulled the weight of private data sets to 60%.
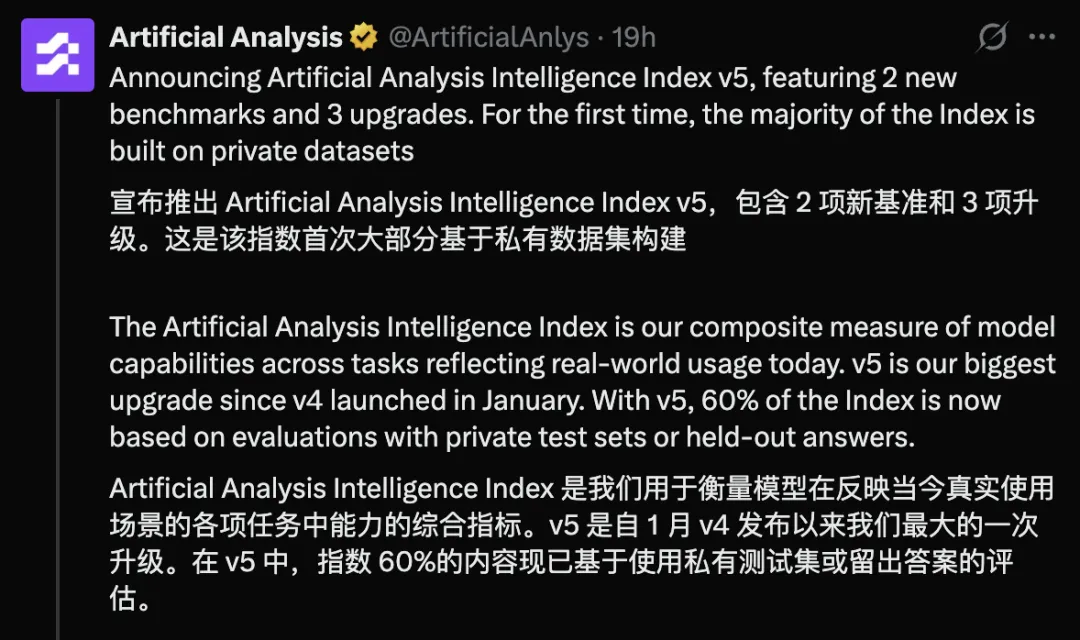
There is no public information, no historical work. Models have to think on the spot, solve problems on the spot.
This is the end of the era of the "death note hardback" mixed days.
Derya Unutmaz, a professor of immunology, commented that the new version is more rational, with the previous open source model being over-benchmaxxing against public benchmarks, and the gap in capabilities with the OpenAI, Anthropic and Gemini front-end models being clearly drawn.
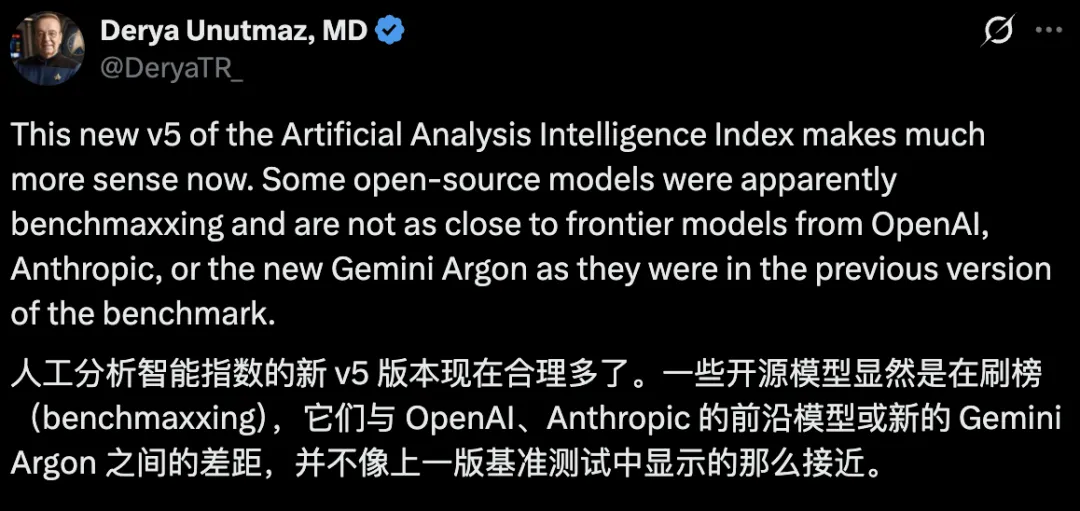
However, this does not mean that the gap between the two has widened, but that the measurement methods have changed.
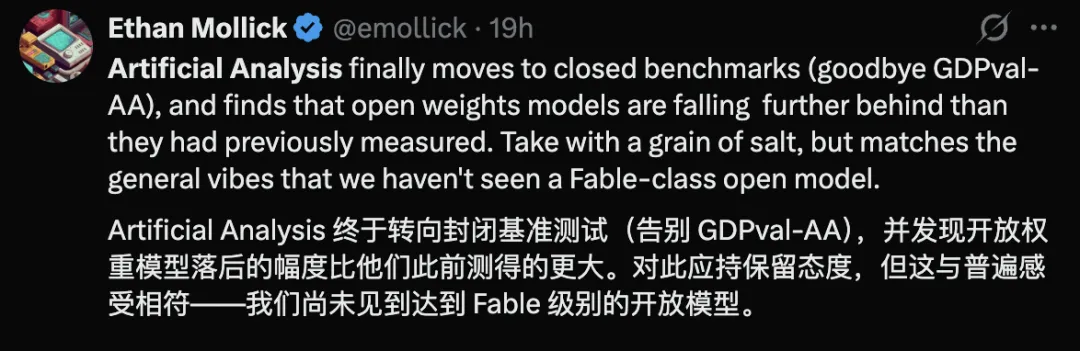
Introducing high-difficulty scientific workflow.
New challenges such as code and scientific workflow have been added.
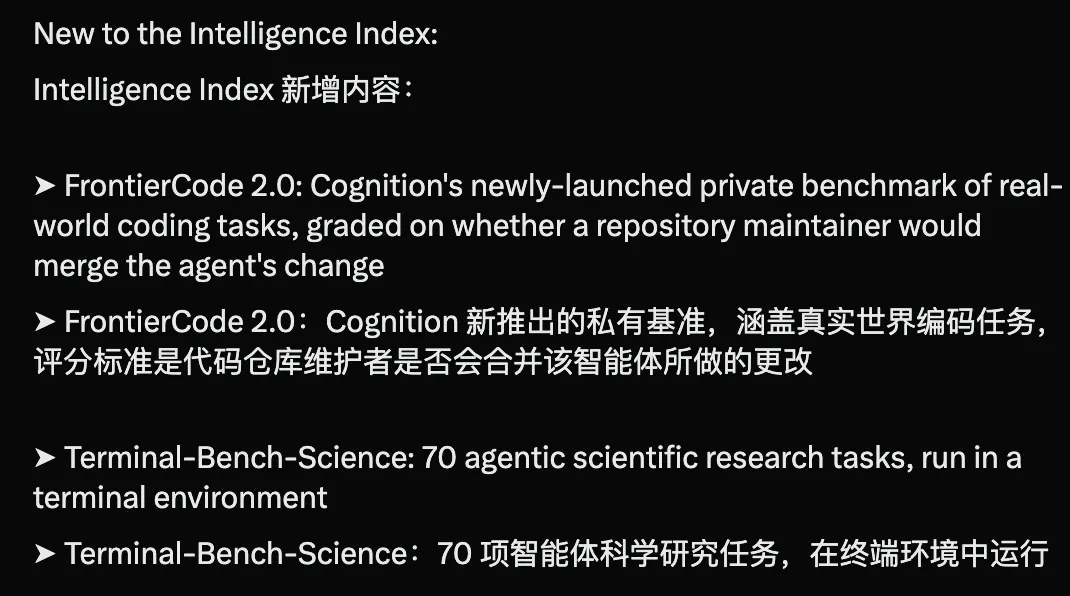
It's no longer as simple as writing a greedy snake code, but requiring AI to handle complex engineering logic like real programmers and researchers.
In such a high-pressure test, Opus 5.5 is stuck. It demonstrates the anthropic power of terror in complex logical reasoning and real-world scenarios.
Who is the hidden model Obsidian 3?Opus 5.5 climbs to the top, it's just a preview.
It's a real hardcore crap that's hidden in another agency's database.
Yesterday, the renowned AI testing agency Cognition released the latest version of its private programming benchmark:FrontierCode 2.0。
This is an extremely varied test: it contains 132 tasks in a real open source database.
The rating criteria are simple and rough: once the code is submitted, the project maintainer will be willing to merge your changes.
As long as a blocking check is not passed, zero points are directly counted and no sympathy points are scored. To prevent data contamination, the entire task is kept confidential.
Furthermore, Artificial Analysis will also run three times per mission in the Stirrup framework, eliminating chance.
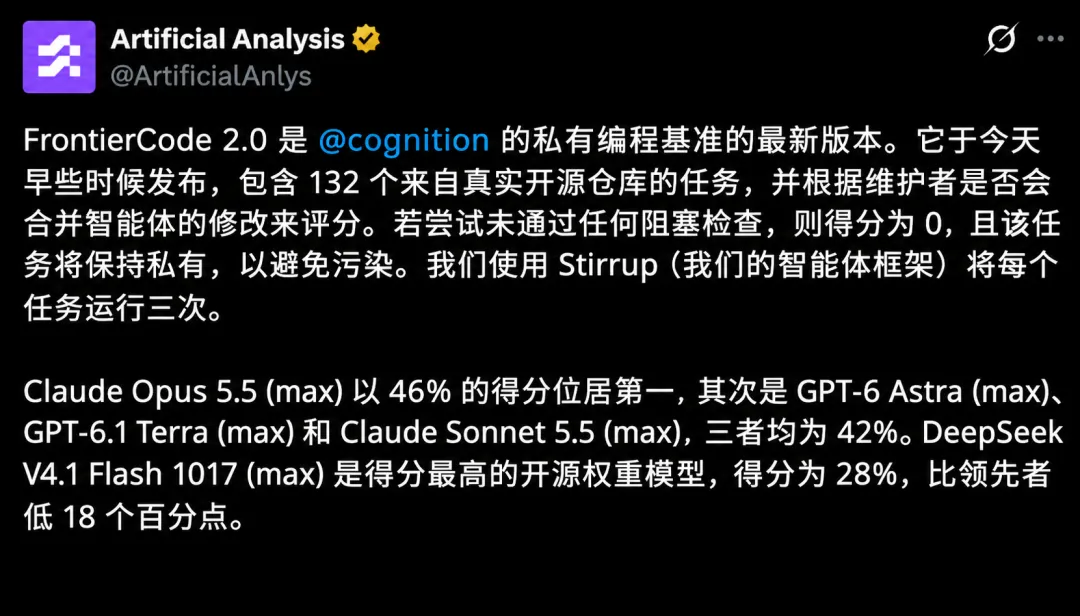
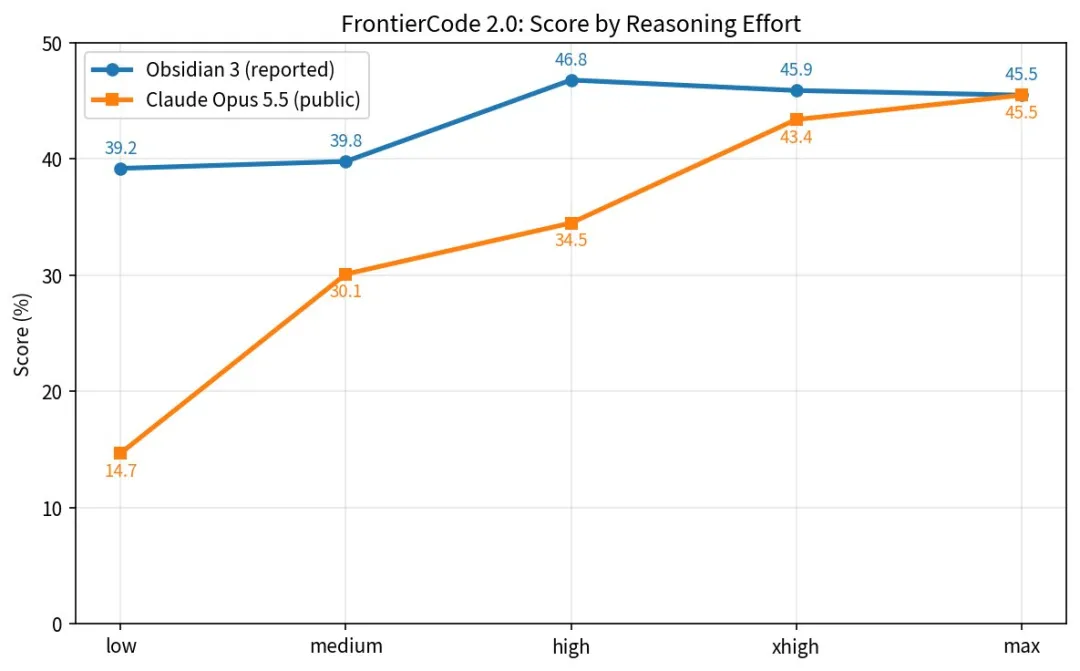
On this list, Claude Opus 5.5 (max) leads with 46% of the vote.
GPT-6 Astra (max), GPT-6.1 Terra (max) and Claude Sonnet 5.5 (max) followed, all dead at 42%.
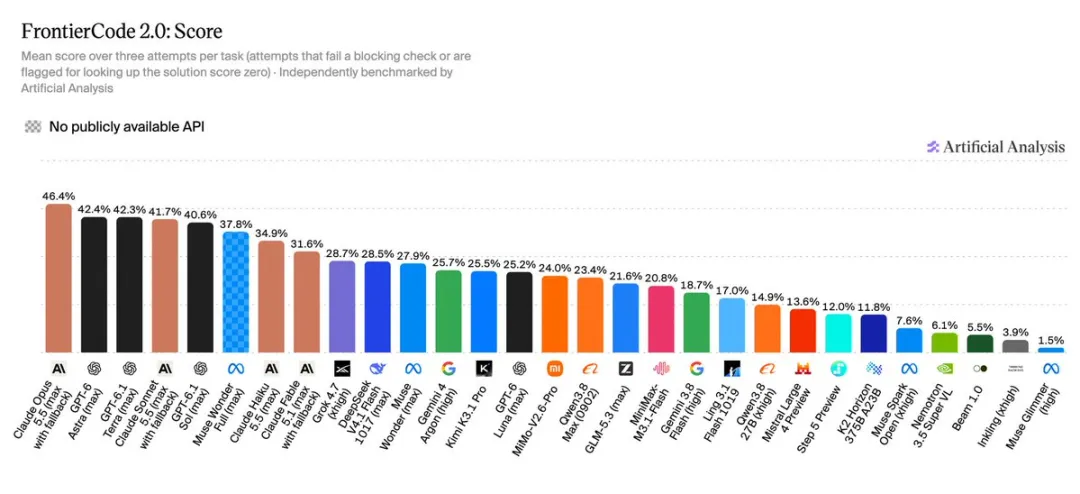
In the hidden code of data.json, a hidden model was discovered.Obsidian 3。
The data is breathtaking:
Obsidian 3, the high-reasoning model scores 46.8%.
It is hard to believe that the current first Opus 5.5 (45.5%) has been trampled underfoot.
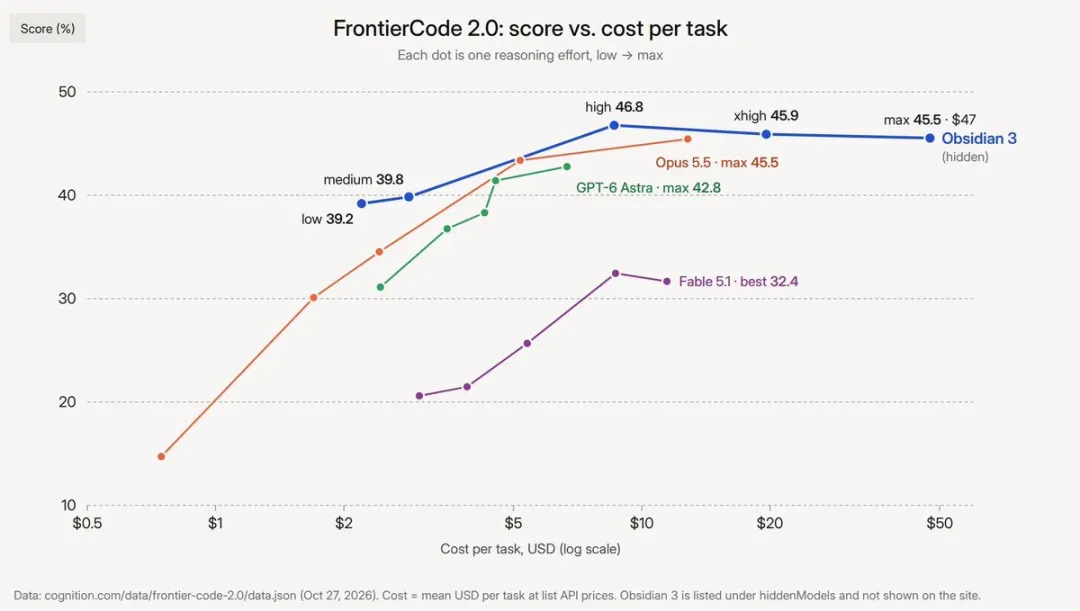
Who is this hidden champion?
The poets in the community quickly locked up the evidence: the testing framework.
Obsidian 3 operates in a claude-code environment. It is an exclusive testing framework and currently only six models from the Claude family are in use worldwide.
The truth is out: it's possible.This is the new generation of the Anthropic serial killer Fable 5.5, which has not yet been officially announced.
The cost of Fable 5.5 is a mystery.But the controversy came with it.
Some people are disappointed that, frankly, this does not enhance "sexuality" enough.
46.8% versus 45.5%, only up by 1.3 percentage points. In the maximum max mode, both are evenly spaced, at 45.5%.
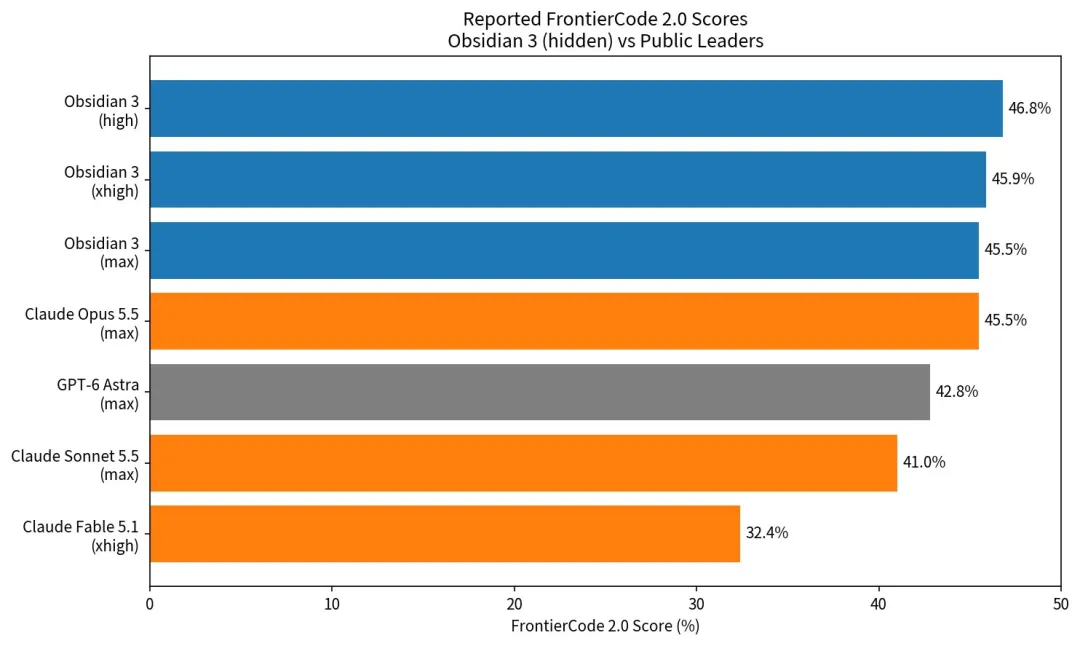
What is more important is the cost.
Data shows that Obsidian 3 costs about 3.6 times the cost of Opus 5.5 under the same input. In high mode, the cost of a single mission is up to $8.62; in some extreme max modes, the cost of a single mission even rises to about $47.
Running a task costs more than three hundred yuan. This is an unbearable figure for most developers.
This pricing ladder has a luxurious sense of "love in AI", which also indirectly excludes the dominant Gemini price.
"If this is Fable 5.5, it doesn't seem surprising enough". Some developers complained on X.
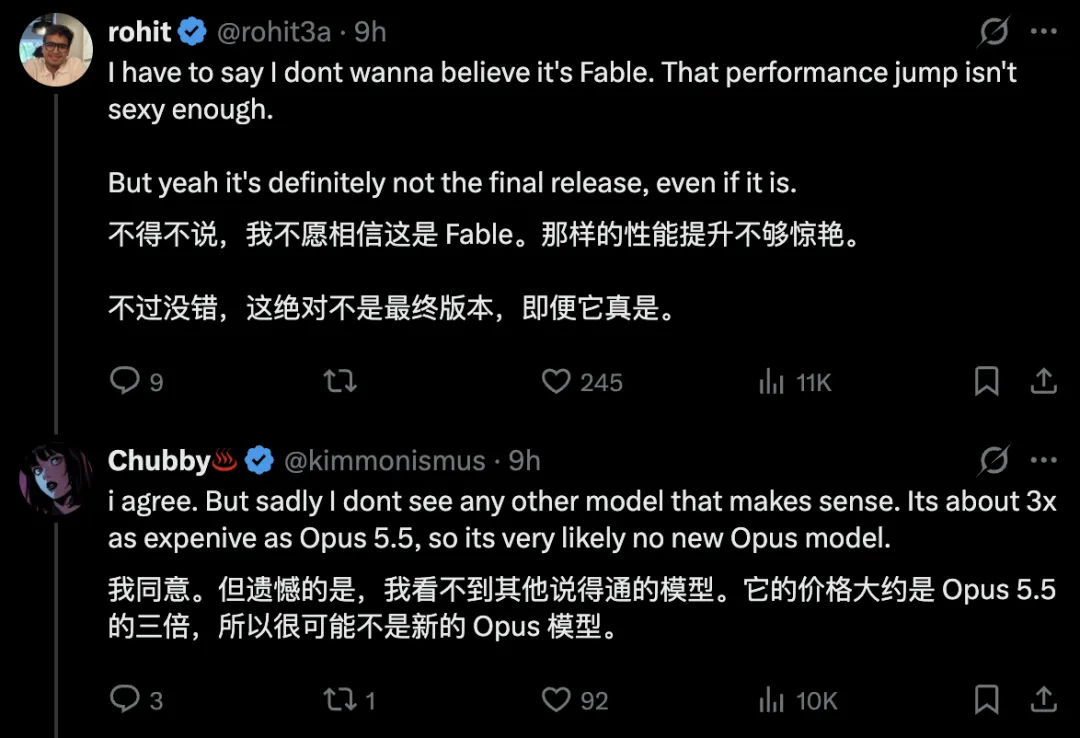
And the more you make it think, the worse it performs, and it feels like an early checkpoint, less likely to be the final release.
It's more like a checkpoint.
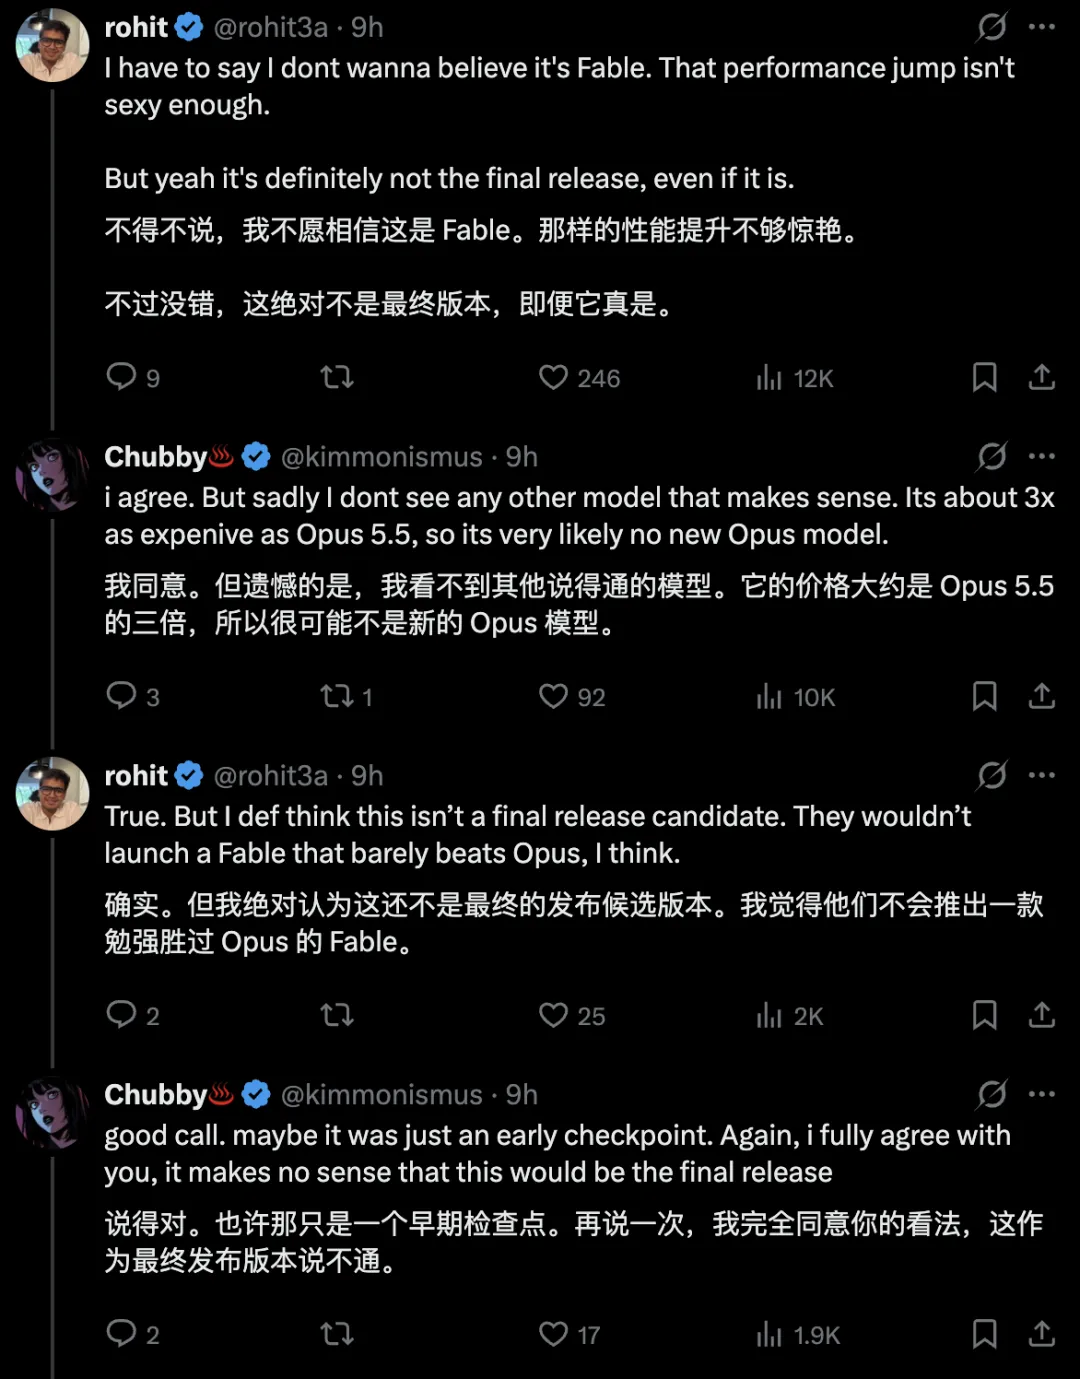
But others saw something different:
Don't be fooled by programmatic scores, the core positioning of Fable 5.5 is never a code-only "code farmer".
Although Obsidian 3 is only a small leader in programming success rates, it is extremely stable in the "middle and high reasoning range".
It's a real leap, somewhere else:
- Reason and intuition.
- to infer the true intentions of humanity.
- Raise the level of ambition of the task.
- The creative 'out of the box' thinking.
- Inventing unprecedented innovative solutions.
Solving a new "no one has ever touched" problem in a complex real-world scientific process is more valuable than fixing 100 known bugs.
In addition, the current leak is only test node data, which is highly unlikely to be the final release version of Fable 5.5.
If Cognition has not disclosed its benchmark tests, then everything is ready.
Maybe tomorrow, maybe the day after tomorrow, another big earthquake in the AI world has entered the countdown.
End: On the eve of the stormThis is a dramatic time-lapse.
Opus 5.5 defeated the GPT-6 Astra, proving Anthropic's control over programming.
The Gemini 4 Carbon vs. Opus 5.5, which proves that Google's treasure knife is not old and can still fight a war.
Hiding the champion Obsidian 3's thunderstorm indicates that Fable 5.5 is on the rise, ready to turn on the crankshaft at any time.
There is no myth that AI models can't be defeated.
Today, Gemini 4 is number one. Tomorrow, Claude Fable 5.5 may roll over the table.
Be prepared, the time interval between AI models being released may be shorter and shorter.