Imagine a teacher who has been working for twenty years as a carpenter, bringing an apprentice who has just entered. The teacher is experienced, but if the apprentice is unstable with a screwdriver, the teacher coughs up those "listening to the voice knows where it is wrong", and speaks plainly. The apprentice can't catch up. But once the apprentice has mastered the basic tasks, the experience of the teacher's apprentice will suddenly become a bit of money, causing the student's level to rise.
In robotic learning, there is an almost identical story.
When Does Legacy Data Start to Help? Emergent Transfer in Cross-Configuration Robot Learning (When Does Legacy Data Start to Help?
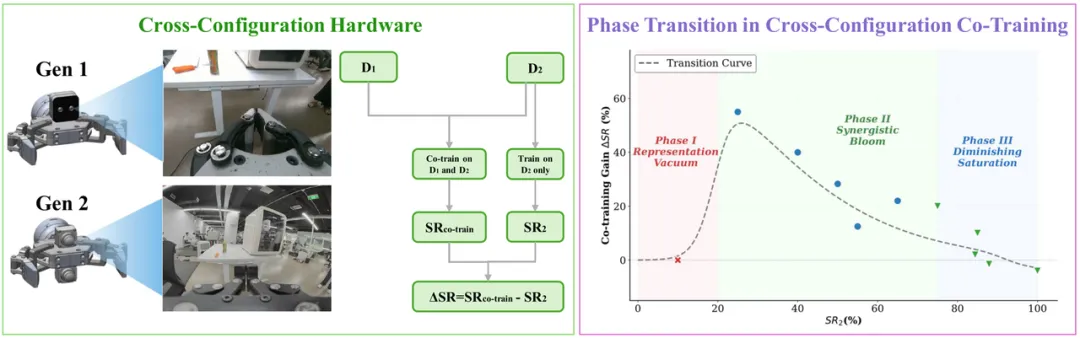
Figure 1: Three-phase rules for cross-configuration co-education
When Does Legacy Data Start to Help? Emergent Transfer in Cross-Configuration Robot Learning
Link to the paper:https://arxiv.org/abs/2607.25593
The main page of the project:https://xuezhiai123.github.io/legacy-data-transfer/
This is a real and expensive question:
When the hardware is upgraded, the old data is gone?
The reality is that robotic hardware has been evolving: cameras have been replaced by broader, clearer, and more flexible designs.
The problem is that these changes will directly change the robot's "pictures" and "the way it moves". So every time the hardware is upgraded, there's a real headache problem.
Will the demonstration data that was previously spent on the old hardware and collected a lot of money be used on the new robots?
A very natural idea is to combine a large amount of old data with new data collected on a small amount of new hardware (called "co-training/co-training") and to allow old data to "support" new robots.
But none of this answers a more critical question: Will old data be useful from the start when the hardware changes? The experience of migration learning tells us that when new and old data are too different, old data may not only be useless, but may even drag backwards and interfere with learning.
This is the first time I've seen this.
The old data isn't "the more the better", it's "the opening moment".
The team conducted a systematic experiment on a wheeled humanoid robot platform that spanned two generations of hardware, cameras, and claws, but the overall shape of the robot remained the same. They compared the performance of two strategies:
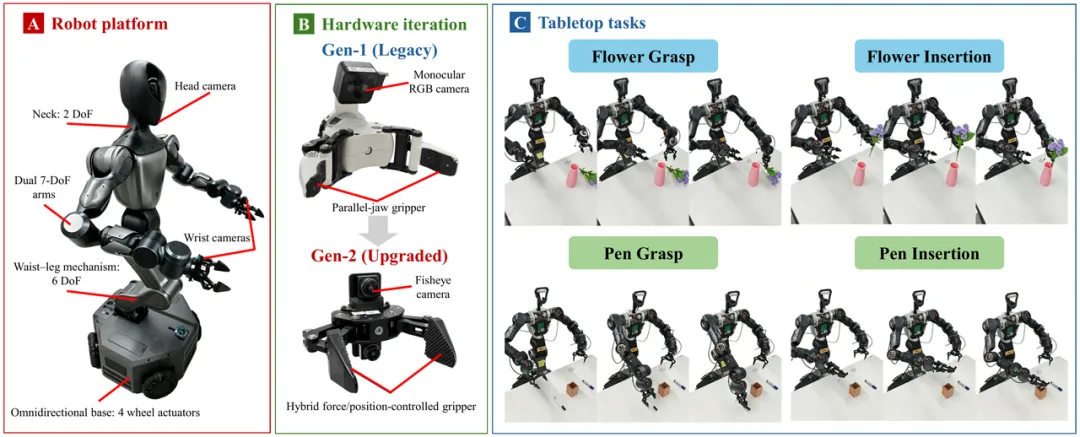
Figure 2: A real robot experiment platform with detailed operations such as plugs, pencils, etc.)
Only strategies that are trained with new data
Old data + strategies for training new data together
The results were very surprising. For example, the fine-grained operation of the "push flowers" task:
When the new hardware data is only 4.3 hours long, robots themselves can only achieve a 10 percent success rate, combined with the old data, the success rate stays the same, or 10 percent, the old data doesn't help at all.
But when the new hardware data increased to 15.6 hours, robots themselves could do 23.3 percent, and the 17 hours of old data were added, the success rate jumped directly to 86.7 percent, an increase of 63.4 percentage points!
In other words, just a slight improvement in the capabilities of the new robot itself will turn old data from "useless" to "gold".
To summarize the results of different tasks and different amounts of data, a clear "three-phase law" emerges:
1. Phase One: New robots are low: Old data is useless, and it's too bad.
2. Stage Two: Capacity crosses a critical point: The benefits of old data explode dramatically, resulting in significant improvements;
3. Stage 3: The marginal benefits of old data are starting to decline again.
This jump from "useless" to "suddenly useful" is what the team calls "emergent transfer". It is similar to the phenomenon of "emergent ability", "grokking", which is familiar to everyone in the field of large models.
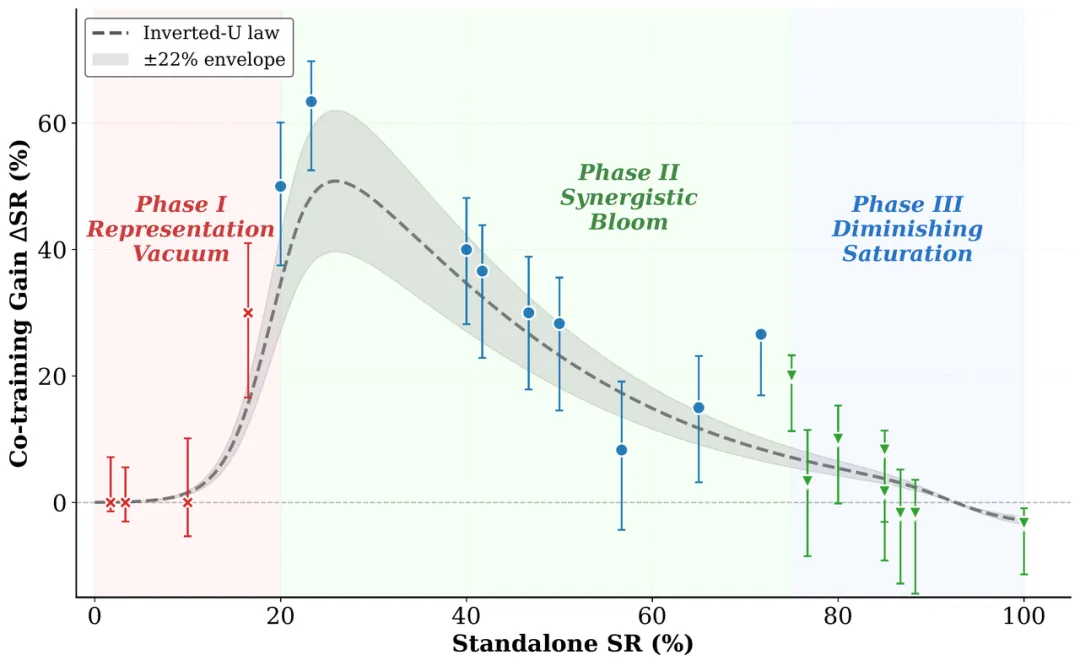
Figure 3: The three-phase shift curve. The migration threshold τ(T) marks the critical point at which old data is beginning to generate significant gains.
Why is this happening? A "migration threshold" and the two mechanisms behind it.
The team used a key concept to illustrate this shift: transfer threshold τ (T) transfer threshold.
Traditionally, it's "a basic skill level that students must first master", and it's only when the success rate of the new hardware strategy itself crosses the thresholds associated with the task that old data will start to help.
Undervalued: The basic structure of the new strategy-linked task is unlearned, giving it more and more "advanced experience" with older data, and it doesn't know how to use it;
Above the threshold: the learning direction of the new and old data begins to "coordinate" and the experience of the old data can migrate smoothly, resulting in a profit surge;
Near completion: There is little space to improve, and the marginal value of old data naturally drops.
The team further explains from a theoretical perspective that there are two mechanisms at the core:
Gradient Alignment: Explains "When does old data start to help?"
Residual Policy Uncertainty: Explains "why the benefits of old data decrease as they approach completion".
What's the use? A data collection strategy for "looking down on the fire".
The most real value of this law is that it guides how we spend our money on data collection.
In the past, it was assumed that "the more data, the better", and new hardware data was collected on a massive scale. But this work gave a smarter "phase-aware" data collection strategy:
First, only new hardware data is collected until the ability of new robots crosses the migration threshold; then the old data is introduced for joint training.
That is to say, let the pupil practice "open" and then ask the teacher to get out of the way, the effectiveness and sexuality are the highest.
The team tested this strategy in a completely new, non-rule-driven "moving-arms blossom" mission:
According to the phase-perception strategy, only 1.5 hours of new hardware data will be collected (as opposed to 8 hours in the past);
Mission success rate increased from 40.0% to 78.3%.
With less than one-fifth of the new data collected in exchange for a significant increase in success rates, this is significant for a real robot scenario that requires a lot of artificial demonstration and costs.
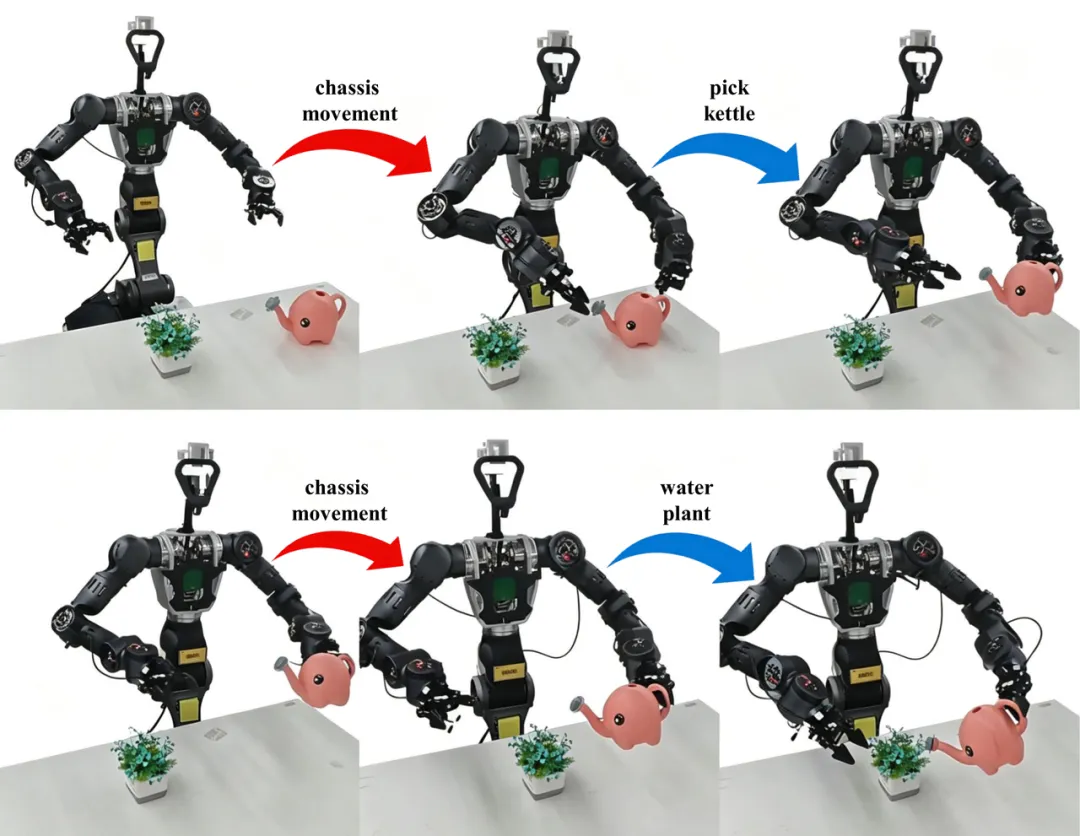
Figure 4: Moving two-armed squat missions. The phase perception strategy pushes the demand for new data from 8 hours to 1.5 hours, and the success rate rises from 40.0% to 78.3%.
Summary
The work systematically reveals and illustrates the phenomenon of "emerging migration" in cross-configurational robot learning, and the core contribution can be summarized in three ways:
1. Discover the three-phase migration rule: old data is useless when new hardware is low, revenue bursts after crossing thresholds, revenue declines when near full, and provide statistical support;
2. Proposes a migration threshold τ(T) with a theoretical explanation: using gradient alignment and residual strategic uncertainty, explains when the old data "began to be useful" and "why later returns declined";
3. Provide a downloadable data collection strategy: first take new data across thresholds, then introduce old data co-training, and compress the need for new data from 8 hours to 1.5 hours on the splash task.
This work answers a fundamental and practical question for the massive real-world deployment and the ever-changing physical intelligence of hardware: when and how should we replicate that expensive historical data in the face of hardware upgrades?
Author's note
The work was carried out by a team of post-training and reinforcement workers for the Intelligent Manipulation Model. Members of the team come from universities such as Qingdao, North Korea, Zurich, and other Federal Technical Universities, with PhDs. The team background covers large models, physical intelligence and autonomous driving, core members have worked in companies such as Baidu, Xiaomi, long-term deep-farm model training and experience in algorithm research and engineering landing.