On Tuesday evening, DeepSeek's open platform announced plans to re-adjust the pricing of the large model API, a welcome reduction.
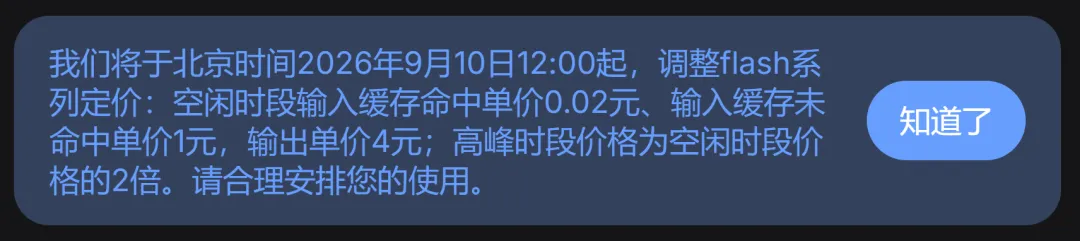
At the time of closing, the unit price was: input, 0.02 units; input, 2 units; output, 4 units; each unit was yuan/million tokens. At the peak, the price was twice as high as at the time of closing, i.e. 0.04 units; output, 8 units.
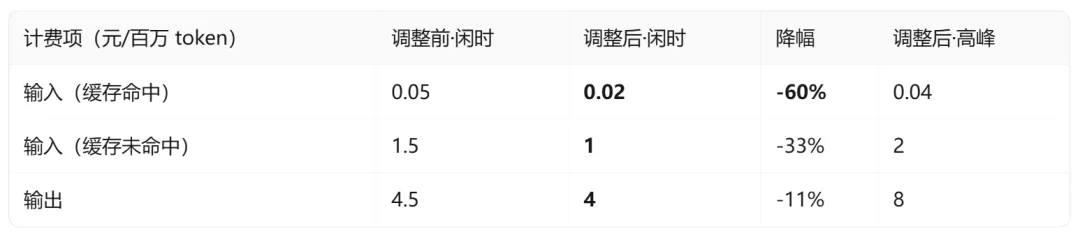
This adjustment only applies to the V4-Flash series, with the higher priced V4-Pro remaining unchanged. The new price will come into effect on September 10 at 12:00 Beijing time.
Officials also clarified that peak hours are 9:00 am to 12:00 pm, 14:00 am to 18:00 pm, Monday through Friday, Beijing time, and the remainder are free time.
DeepSeek's pricing has been widely debated. The official explanation is to more rationally tailor resources and encourage users to adjust task execution times. The outside world generally believes that DeepSeek V4 Flash 0731 is highly priced, attracts a large number of calls from users around the world, and that DeepSeek lacks sufficient computing power.
In the opposite direction, before the zero-hour strike price on August 17, Flash was a unit price of 0.02 yuan (cached) / 1 yuan (uncredited) / 2 yuan (output).
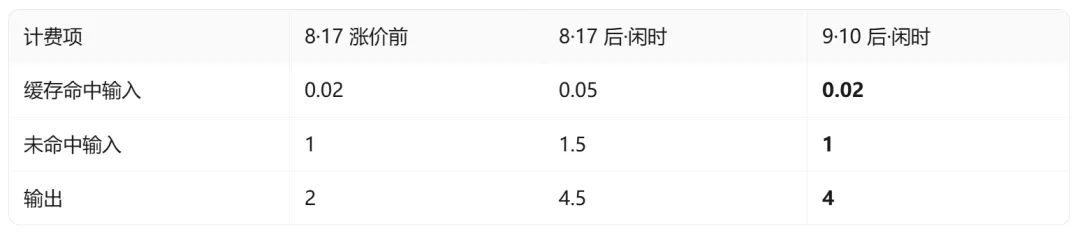
In other words, the two prices on the input side returned to the bid price and the output was still twice as much as before the bid price. If the difference is greater at the peak time: the new peak price is 0.04 / 2 / 8 yuan, compared to 0.02 / 1 / 2 yuan before the bid price, which is 2 times, 2 times and 4 times, respectively.
Therefore, whether users can actually go back to the "open" state of the past depends on the three variables of their application: the cache latency rate, the input output ratio, and the extent to which the task can be completed. The decrease will be evident in situations where the cache latency rate is high in the context, in fixed system prompts, in Agent loop calls, and in situations where the output is predominantly generated.
This price reduction is not an isolated event, and yesterday afternoon, DeepSeek announced the launch of the intermediate version of V4.1 Flash in the official exchange group: the model name is deepseek-v4.1-flash-expires-on-0910, the base_url is unchanged, the flow limit per account is 20 and the billing is temporarily the same as V4 Flash.
In addition to the original multi-modal, extremely fast reasoning speed, the new model is also said to reduce costs by upgrading the architecture. As seen through engineering and technical optimization of the large model itself, DeepSeek has been trying to improve the cost of reasoning.
Expires-on-0910 The model name indicates that the new model will automatically expire on September 10th, the same day as the price reduction.
This month, leading-edge AI companies have updated their big models, with the official version of DeepSeek's V4.1 offering a significant boost in capability, perhaps accompanied by a significant drop in prices.