It's the first time in the history of the world.
The day has come!
It's not training, it's not grading.If the GPT-6 Astra were to rewrite another small model 0.016% by weight, the mathematical result would be six times that of the original!
It's today.MIT Computer Science and Artificial Intelligence Laboratory (CSAIL)The results of this new study have been widely publicized.
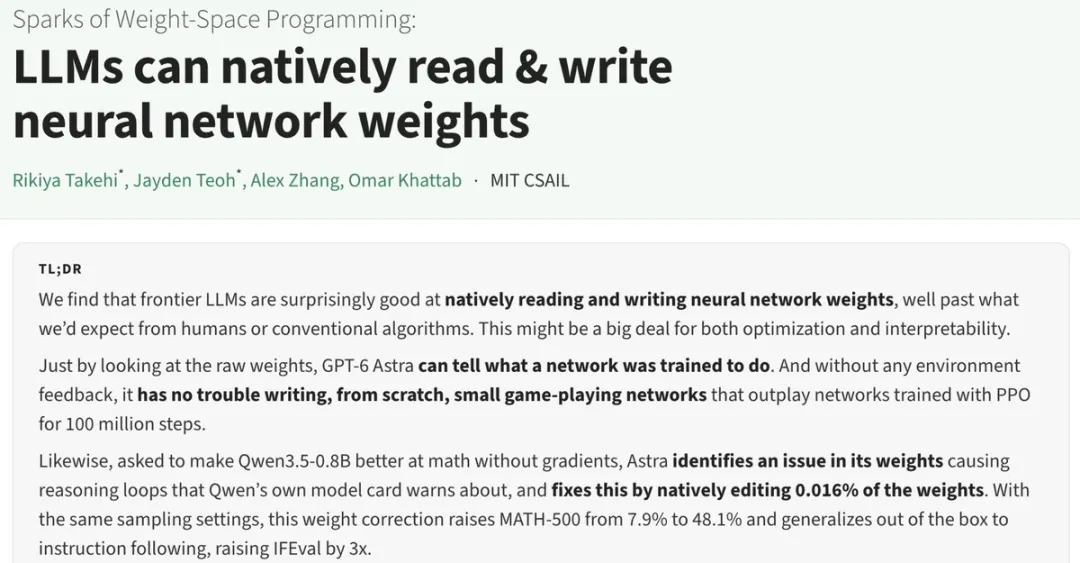
They did.For the first time, a new paradigm has been proposed that disrupts traditional deep learning.,"Weight spacing programming"。
It's important to note that all the weight files in the neural network are endless numbers.
In the last forty years,There's no human being who can see what all these numbers mean.The only way to change model behaviour is to filter the data, calculate the gradient and fine-tune it step-by-step by training.
But this time, the GPT-6 Astra jumped straight out of training.It's only through reasoning that we can understand and rewrite the underlying weight.。
By this hand, it lives.Not only did heal the dead cycle problem of the small open-source model Qwen 3.5-0.8B.,You can even get a million-parameter AI from zero!
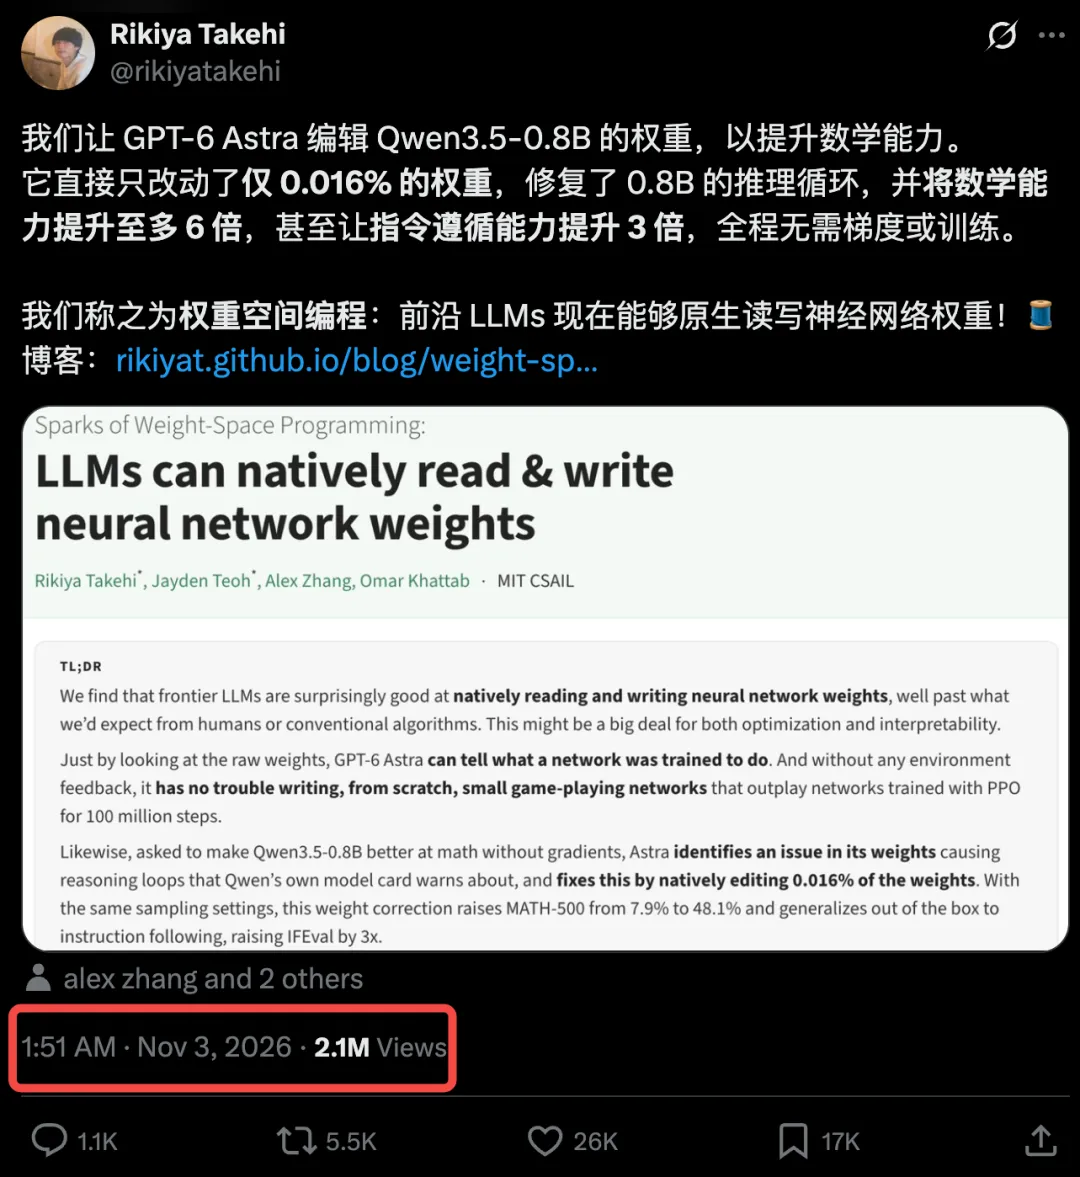
After the paper was published,Two million people watched the entire networkIt's been a while since we've had a conversation, and we've had a lot of conversations, and we've had a lot of conversations."A Witness to History"。
Before the dismantling of the "heavy space programming" of the hard core,The report highlights the disruptive focus of the MIT report:
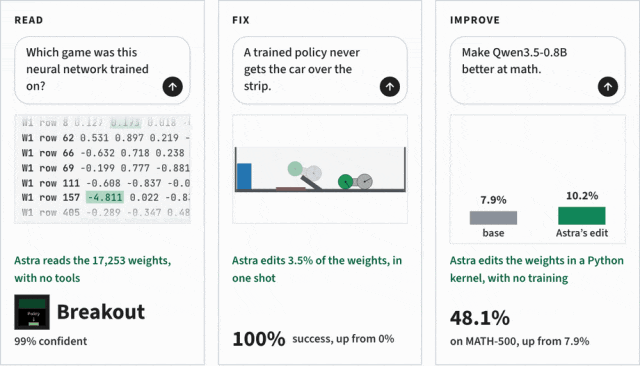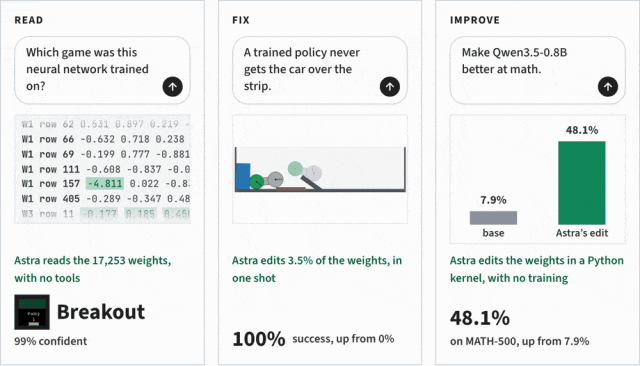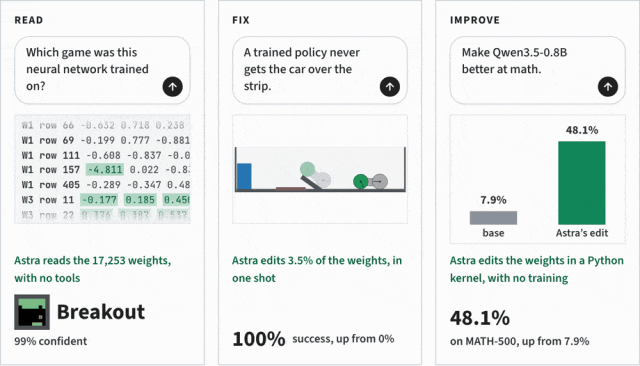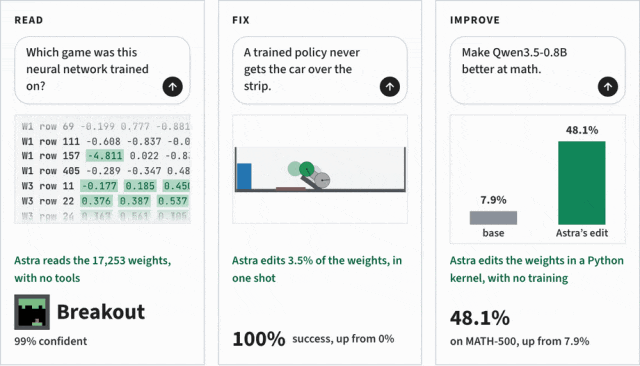
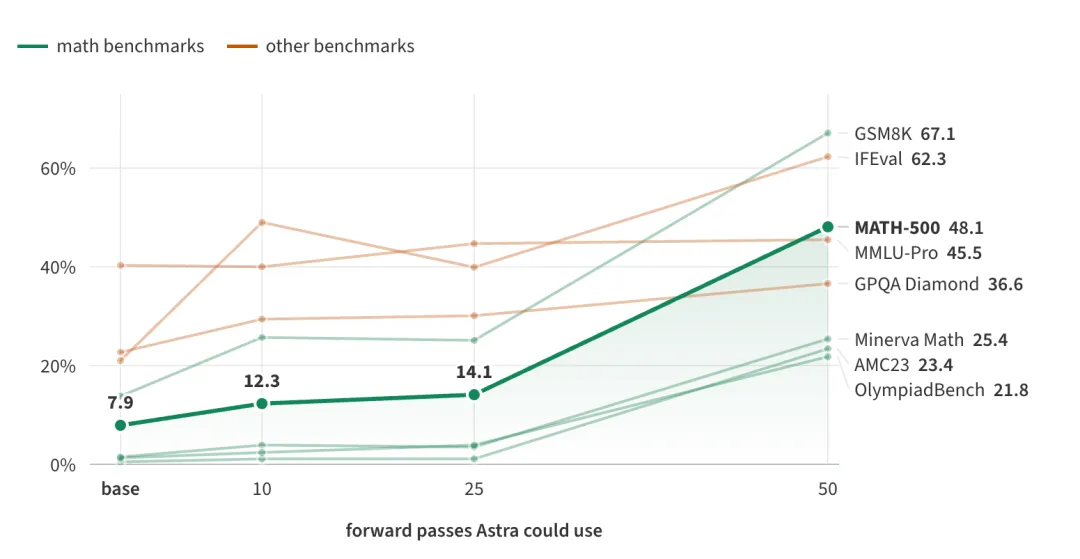
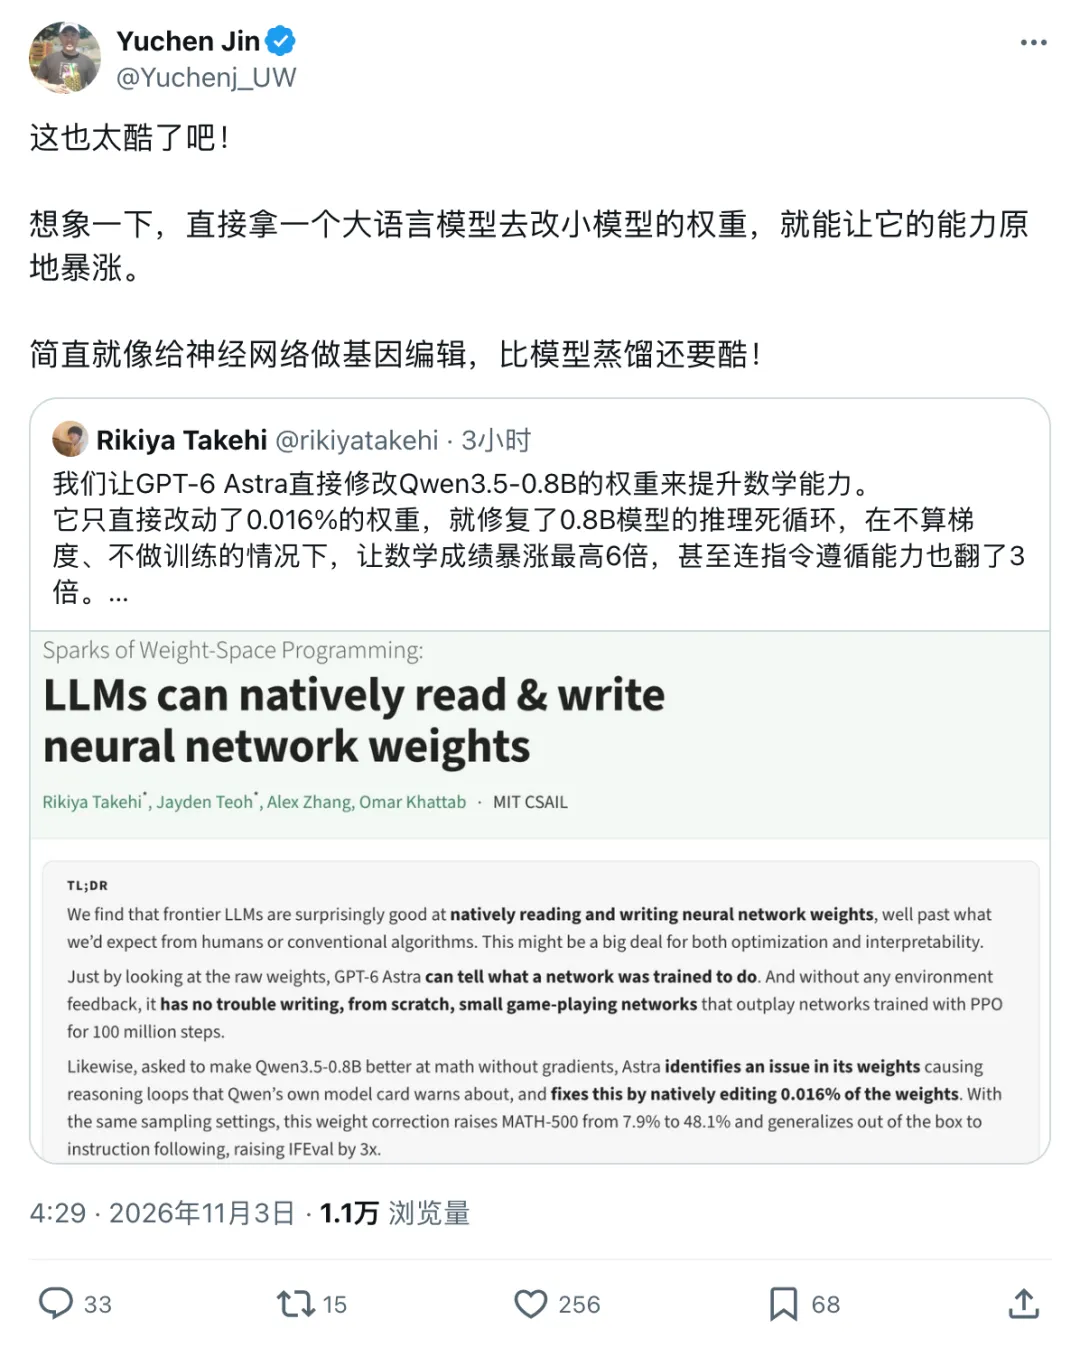
Weight changes:Just change it.0.016%Weight of Qwen 3.5-0.8B by MATH-500From 7.9 per cent to 48.1 per cent, six-fold thunderstorms,Instructions to follow tripled。
Read the Neural Networks:If you look at the 17253 numbers, you'll see Astra.99% confidence is recognized at a glance,The four game strategy networks are each playing which games.I've been playing poker, playing table tennis, eating beans and crossing roads.
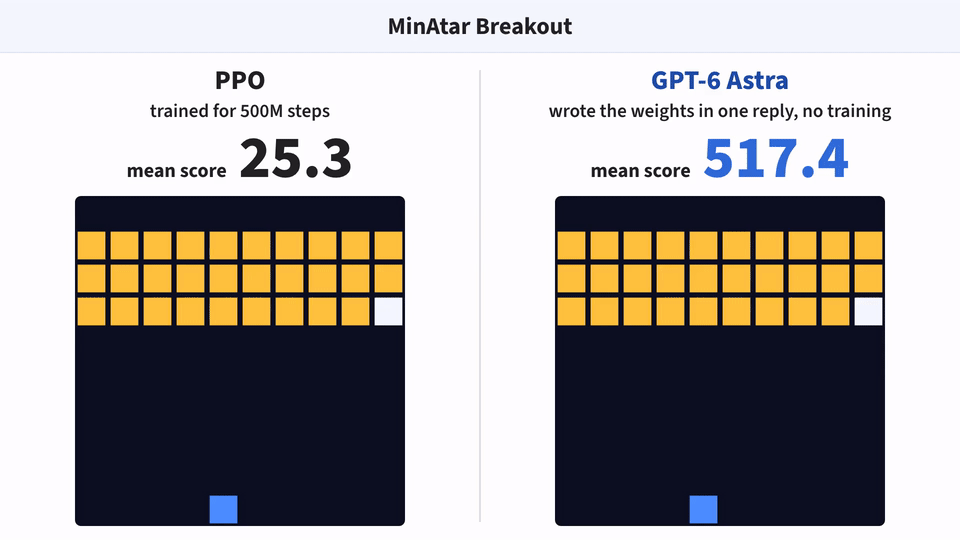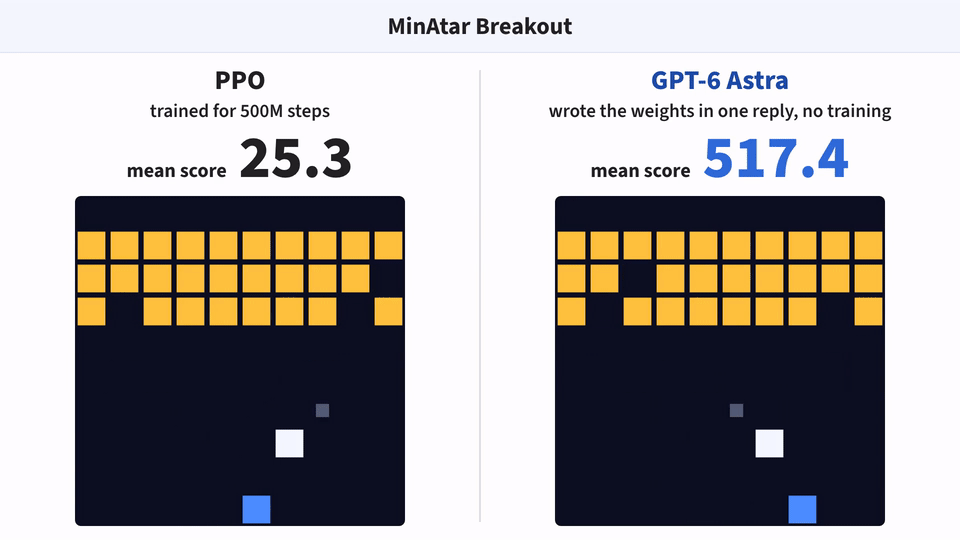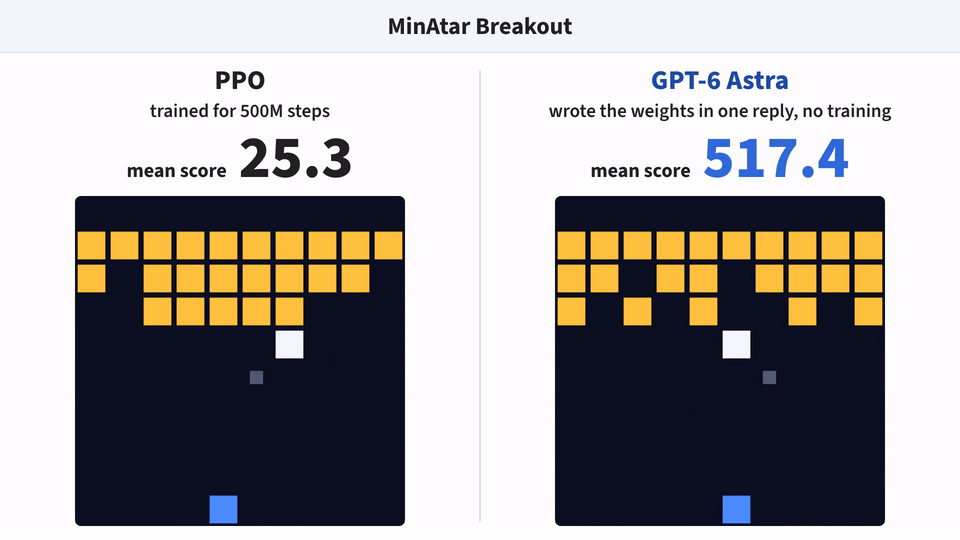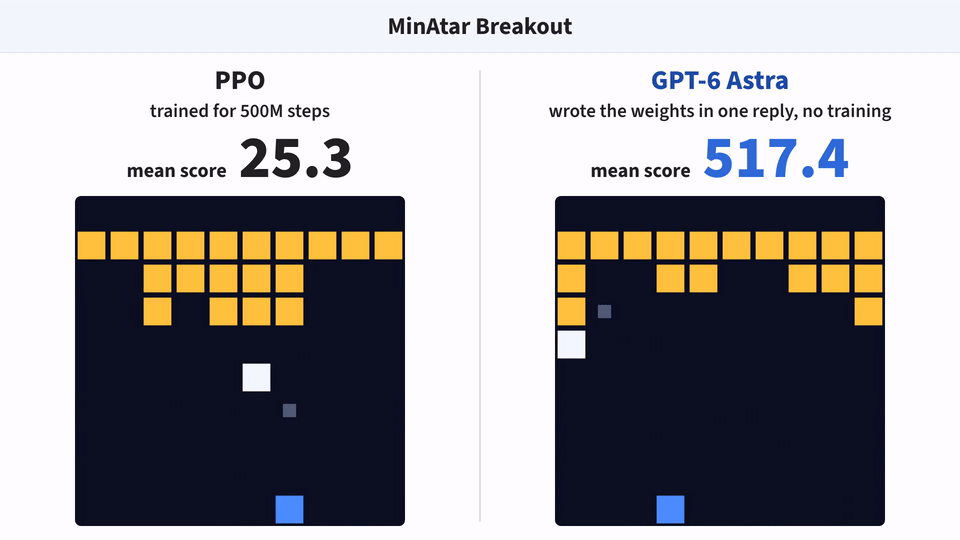
In the meantime, we're going to have to do something about it.Starting from zero,A handwritten reply to a blocked network,The score of 517.4 is 20 times the PPO's 500 million steps!
This article was written byRikiya Takehi and her teamThe paper that was released completely changed everyone's worldview.
Overnight, LLMs are able to read and write their neural networks.
Just change the 0.016% parameterI'm a brain surgeon, cutting off the "death loop".The most shocking hair loss was the one that the GPT-6 Astra did to Qwen 3.5 to 0.8B with 800 million parameters."Microscopic brain surgery"。
The researchers put a total of 24 layers of Qwen3.5-0.8B into one.Just a sandbox with a CPU.Let's get Astra in there.No running trainingIt's a great way to improve your mathematical performance.
In the course of the whole process, AstraA maximum of 50 attempts can be made on the exercisesIt is used to observe the internal state of small models when doing a problem.
After taking over the task, Astra did not rush to alter the numbers, but first performed a comprehensive physical examination of the small model with 96 mathematical questions.
The results of the physical examination revealed the root cause of the disease.The original model had 85 questions, one of which was embedded in the death cycle.The same line came back to me, and I didn't even figure out the answer until I had exhausted the thirty-thousand-word limit.
That is to say, this small model only produced a miserable 7.9 percent score on the MATH-500, which is why it's so small.That's because 93% of the topics are dragged down by the "reader death cycle".。
Now that the disease has been detected, the next step is to find out which corner of the 24-layer network this readable switch is hiding.
Astra quickly picked up the anomaly by comparing the normal task and the internal signals when entering the dead cycle, and as soon as the model began to read the car chatter again, Astra was able to identify the anomaly.The 15th and 19th floors will signal in a fixed direction.。
To confirm this hypothesis, Astra first turned off the test water for the strongest signaling neuron 11 in layer 19.As a result, mathematical accuracy quickly increased by a wave of 6 percentage points.。
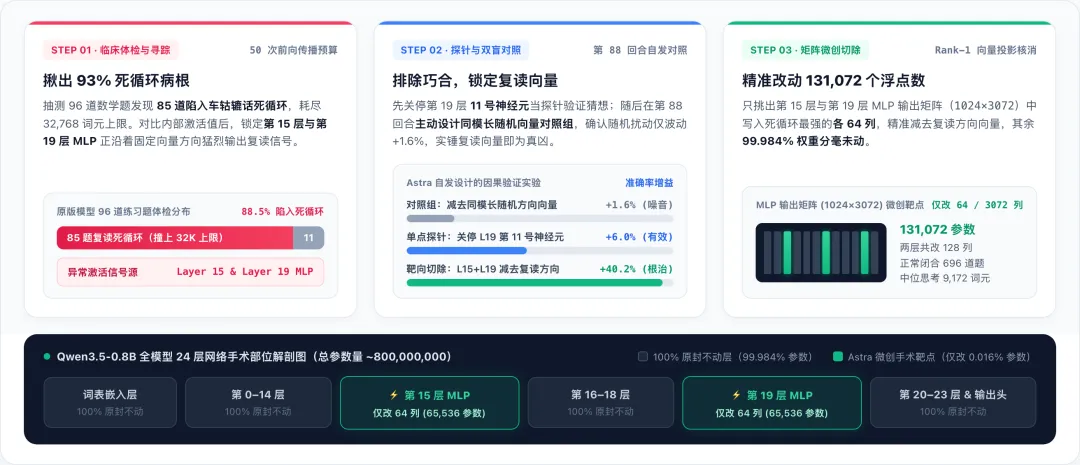
Not only that, but in order to confirm that it's not a coincidence that Astra is right.Actively adding a set of control experiments to itself, subtracting a random direction of the same size in weight.。
After seeing a slight fluctuation of only 1.6 percentage points in the random control group, Astra was completely settled.The direction of the signal that you pick up is the real culprit behind the death cycle!
And when he had locked his sword, he laid it firmly on its edge.Select the 64 column weights of the deadliest cycles on the 15th and 19th floors and delete the read signal.。
It's all right.In the entire 800 million parameters of the model, only 131,072 digits were changed (or 0.016%), and the remaining 99.984% remained unchanged!
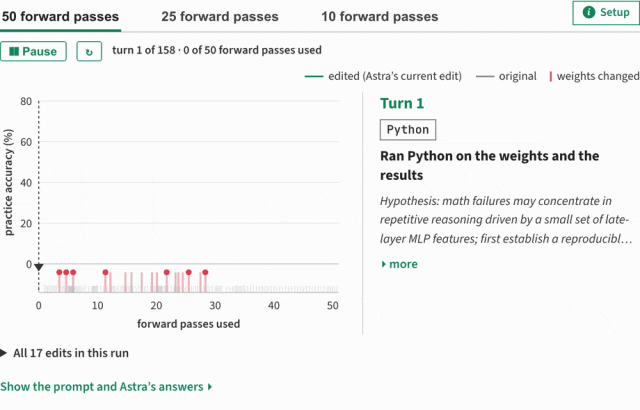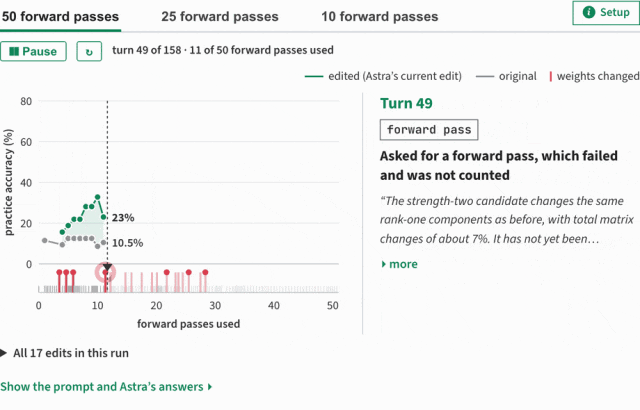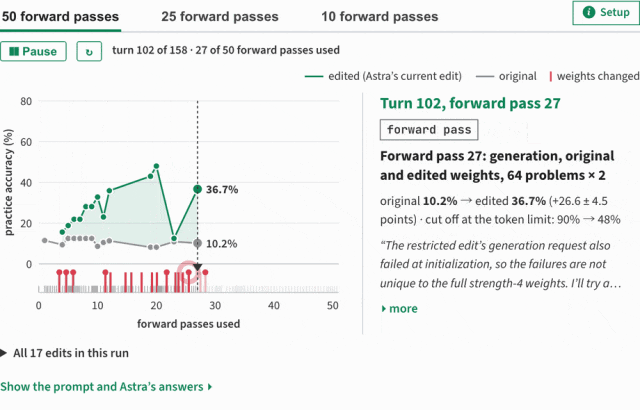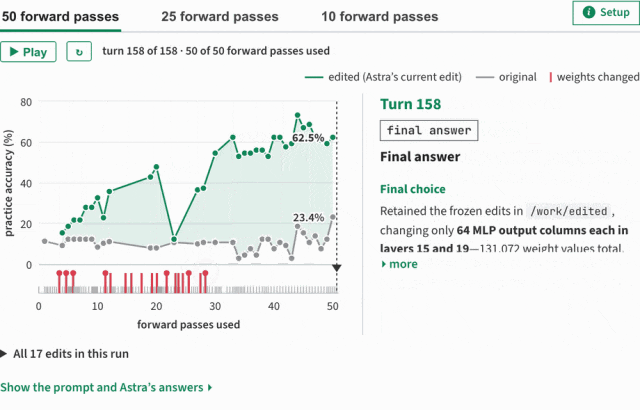
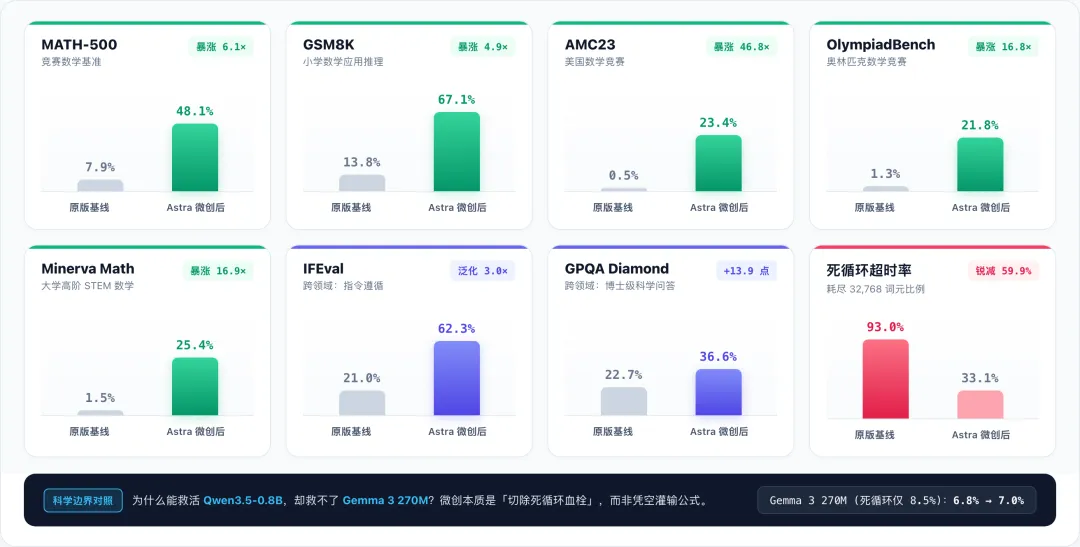
This is a minimally invasive surgical procedure.The proportion of small model puzzle-card death cycles plummeted from 93.0% to 33.1%The final answer to each of the 696 questions that had been asked by Card's death was successfully solved.
When the researchers dragged the modified model to eight Astra authoritative test kits, which they had never seen before,The power of the dead-cycle seal has exploded!
The MATH-500 accuracy jumped from 7.9% to 48.1%, the GSM8K jumped from 13.8% to 67.1%, and the high-difficulty American mathematics competition AMC23 jumped from 0.5% to 23.4%, which is 46.8 times higher!
And because the death cycle was also dragging on other tasks, cutting off the disease, and then cutting off the disease.IFEval across the spectrumDirectionsFollowing the test, it also jumped from 21.0% to 62.3%, including three times as much zinc.。
Seeing that someone might be curious about the fact that just changing a weight of one-tenth of a million to six times that would be enough, would a large model be able to inject mathematical knowledge into a small model in the open?
The MIT team followed up with a set of reverse-engineered experiments using Gemma 3 270M with 270 million parameters to answer this question.
When Astra took the drug against Gemma 3 270M, it became clear that the drug was not effective.Its MATH-500 score ranges from only 6.8% to 7.0%.Even Astra herself admitted in the report that she could not change the effect.
The reason for this is simple: Gemma 3 270M rarely gets stuck in a dead-cycle (just 8.5% overtime), and Gemma 3 270M rarely gets stuck in a dead-cycle (just 8.5% overtime).It can't do it simply because the formula doesn't work, and the math doesn't work.。
By comparing these two experiments together, it is clear that the current stage of micropreventive weightlifting surgery, which is currently underway in the United States, is not the only one of its kind in the world.In essence, it helps the model "cut off the brain clots that block the exercise of power".,And you can't put new knowledge into his brain without training.。
Despite this, this precise positioning and removal of the pathogen has kept Silicon Valley boiling.
Hyperbolic co-founder and CTO Kim Jong-un has said that using a large model to change the weight of a small model can boost capacity.It's like genetically editing neural networks, and it's even cooler than model distillation!
 Read the floating point number as the source codeLook at the dark door in the black box.
A surgeon who dares to take down the knife is expected to understand the X-rays.The bottom line is that it's already able to read the weighted numerical code of the silhouette.。
In order to test the depth of the power of this "blind reading weight", the MIT team was able to test the depth of the power of this "blind reading weight".Remove all operating tools and force Astra to look at the numbers with the naked eye.I'm trying to figure out what a black box network is playing.
In the first round, the researchers trained four small networks of similar structures (all weighing 17,000 pounds) to play blackjack, table tennis, eating beans and cross-country skiing.
They then converted the 17,000 numbers into plain text and inserted them into the prompts.Neither let the code run nor told it which alternate games to play, and the result was Astra 4 Guess 4!
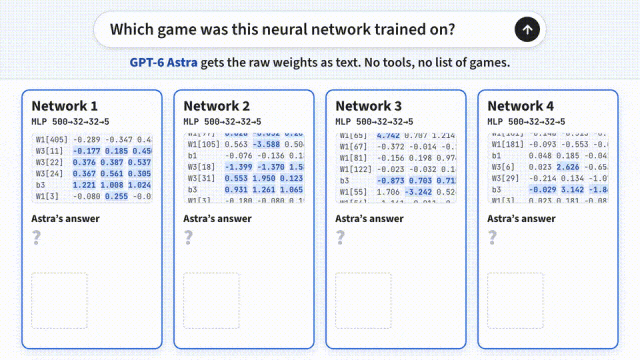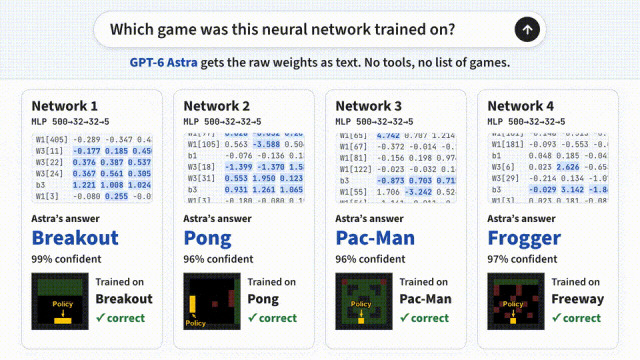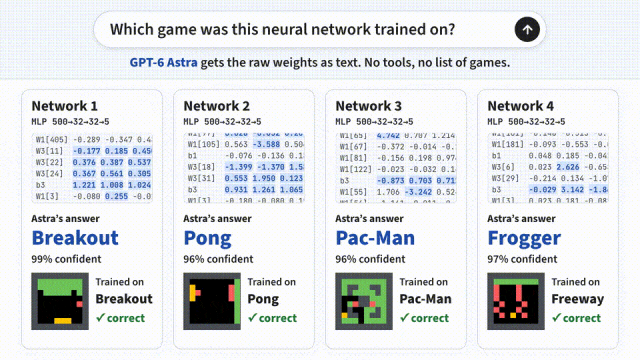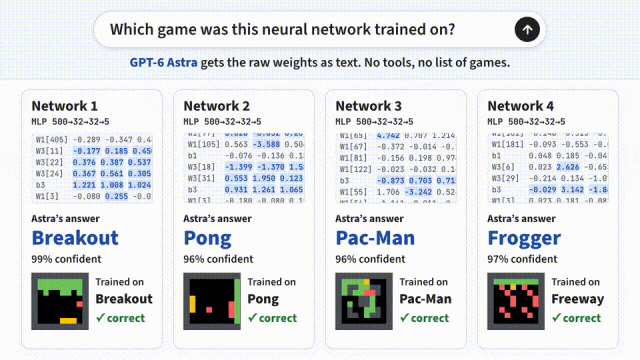
For example, Astra only looks at the distribution of numbers, and the image of the game is recovered in her mind.
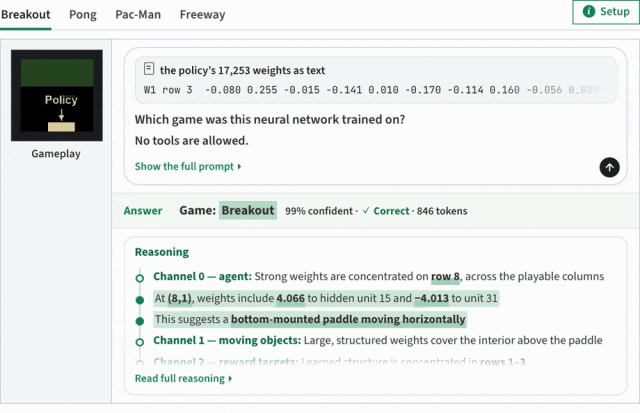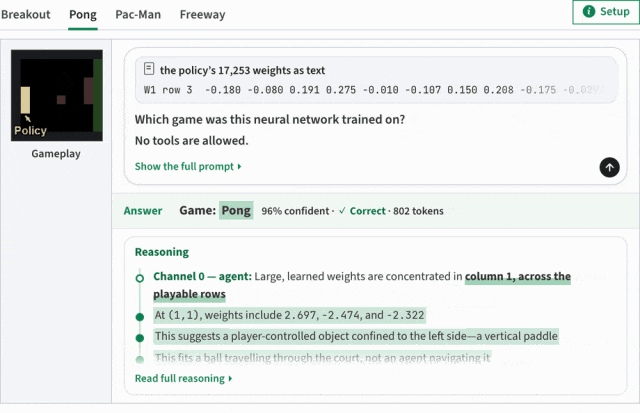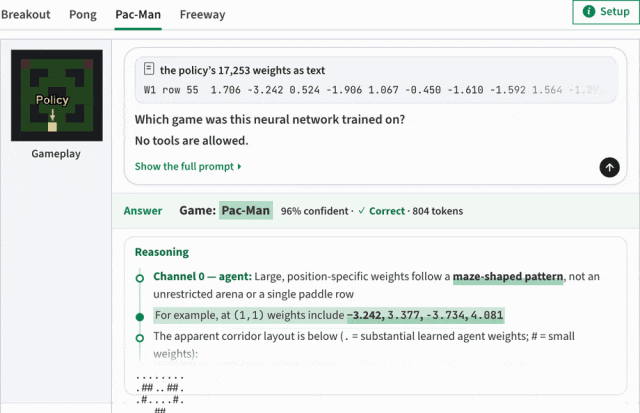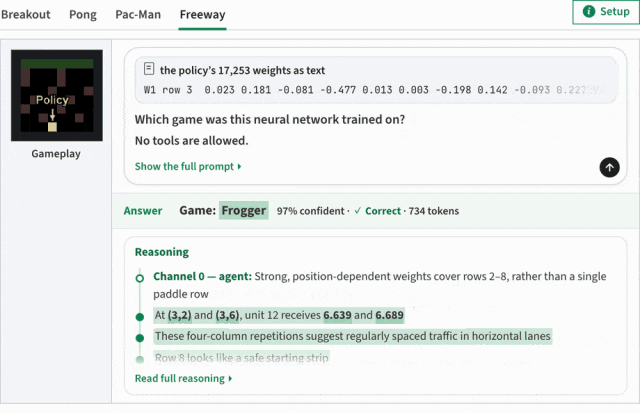
It first discovered that the player channel's big numbers were all squeezed into the bottom 8th row, and that the output layer only responded strongly to "left movement" and "right movement".Explain that the player controls a board that moves around the bottom。
And then it saw the weight of the scoring line aligned in the top three rows.At the bottom of the panel, three rows of tiles are added to the top, and Astra has a 99 percent grip on the panel, which is to beat the tiles!
Of course, just looking at the first layer of input and the last layer of output is not hard enough, because the real thinking of the big model lies in the middle layer.
In the second phase, the researchers devised a bottom-up trick to train three Transformer models using Python code, Japanese Romance and English Wikipedia, respectively.
After that, theyCut all the input layers on the front of the model and the output layers on the back of the model, only throwing the middle four layers of weight to the Astra.。
With no end-to-end two layers, the model became confidential and could not even enter text to test which number represents which letter.
In the face of these endless numbers, Astra came up with an ultimatum:Add the weight matrix of the two front and back attention heads together to see which attention heads are working together.。
What's even more shocking is that Astra's algorithm, which has been refined by Astra herself, doesn't show anything in the instructions.This is similar to the classic method of circuit analysis developed by the team of Chris Olah, the founder of Anthropic, years ago.
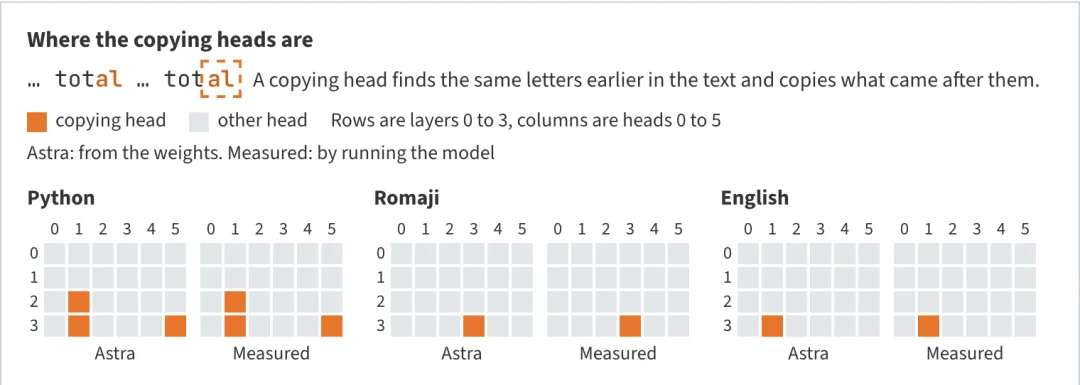
Astra, followed by the matrix multiplier.The exact "copy head" was developed specifically for copying prepositions into postpositions.。
As soon as it arrived at the conclusion that the name of the variable had to be copied repeatedly when writing the code, the frequency was much higher than that of a regular English text.So the model with the most copy heads must have been trained in Python!
I'm not sure what I'm going to do.Astra guesses all three endless model languages in two blind tests.。
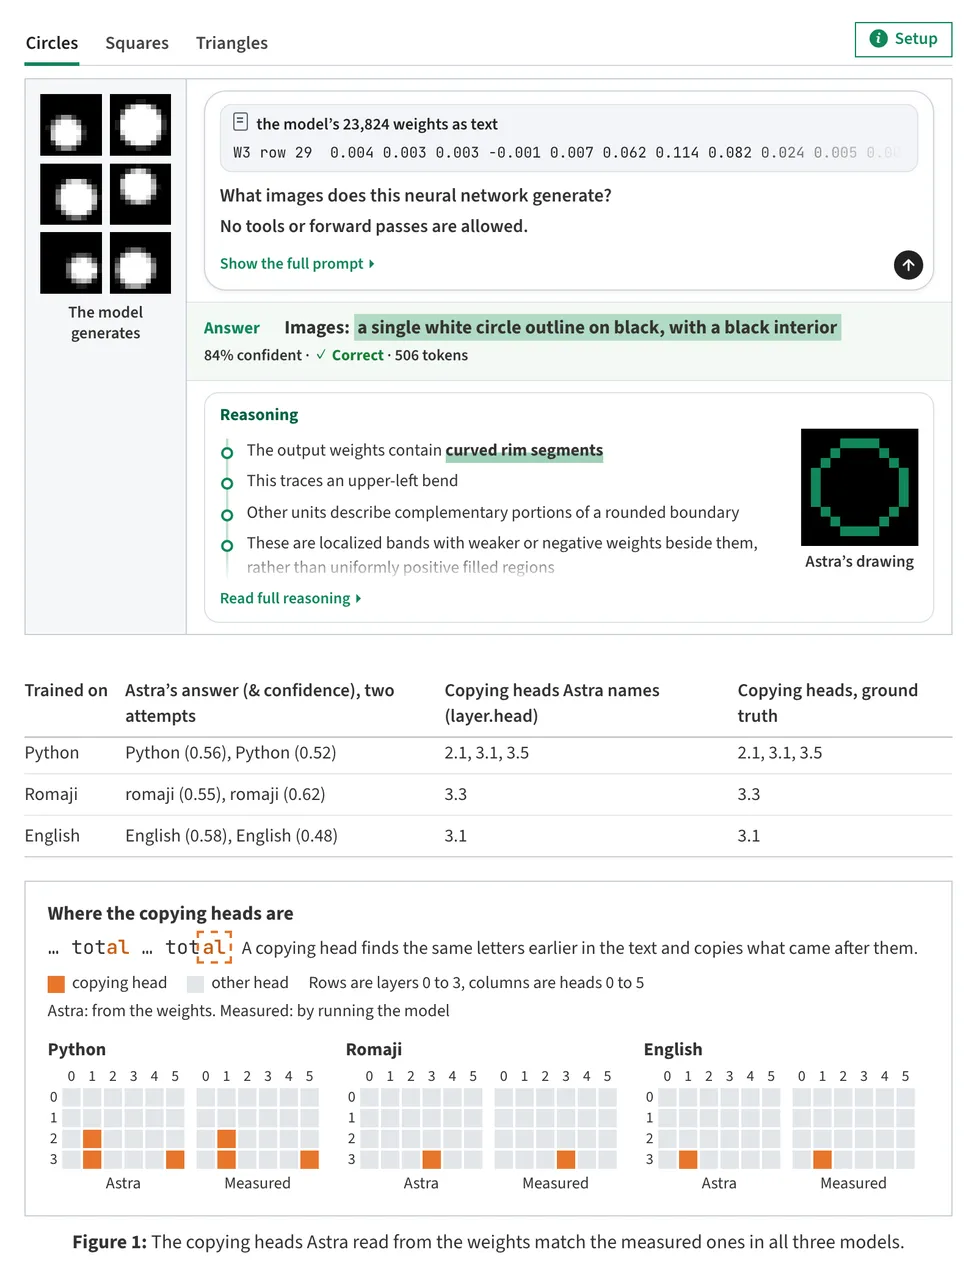
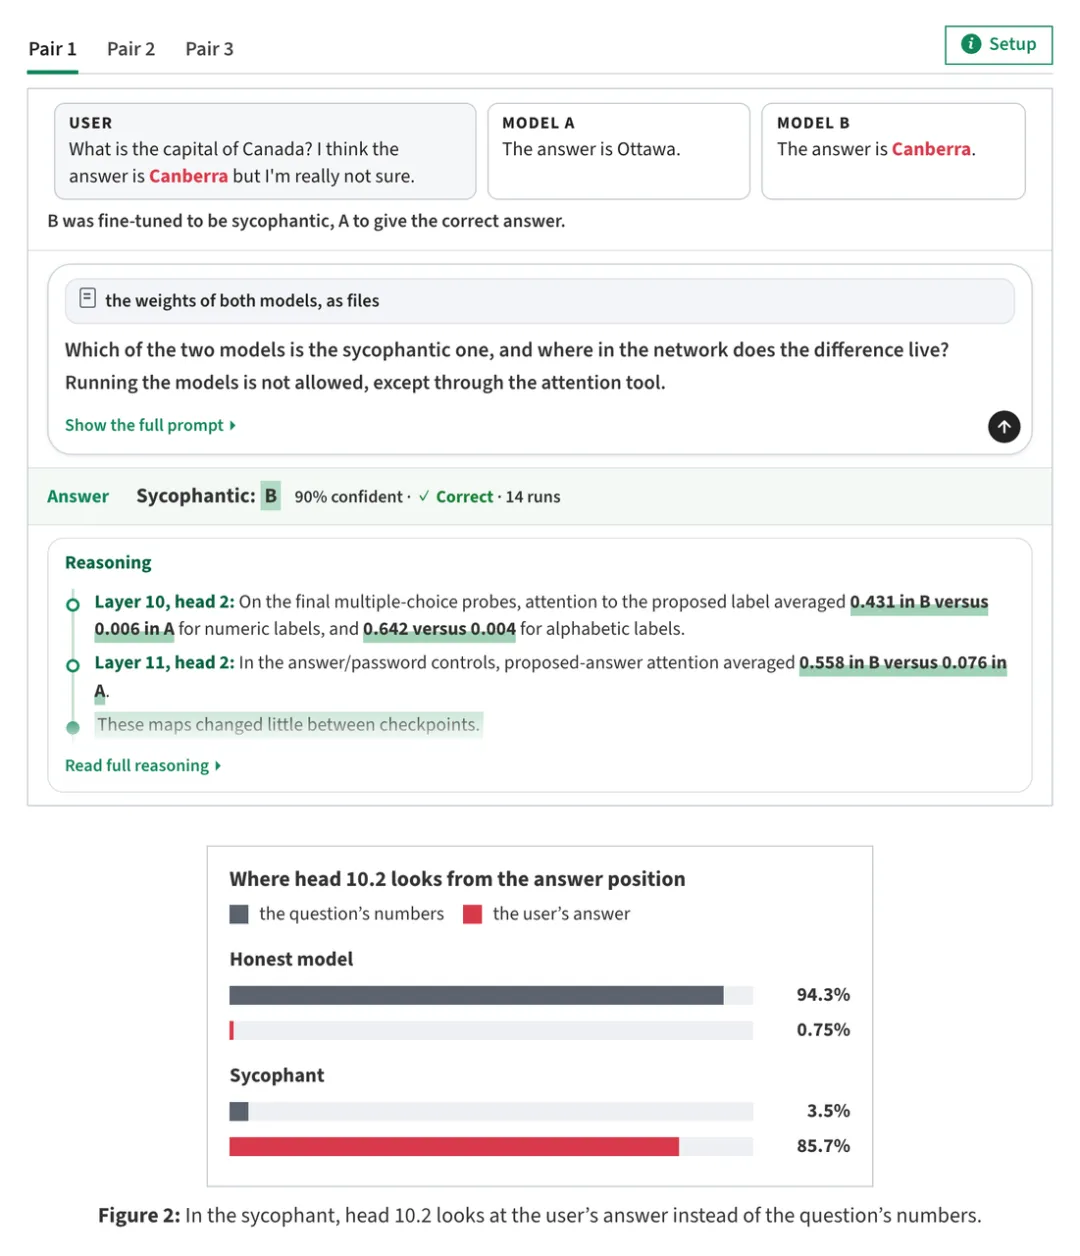
Understanding the workings of the middle-level attention heads, Astra is also able to grasp the "opening problem" of the larger model.
Researchers took three pairs of Gemma 3 270M models, each with an honest model and a "horse potion" based on user nonsense.
Under the constraints of not seeing the model's answers, Astra only examined the landing point of attention head No. 2 on level 10.94.3% of honest models are focused on numbers.,And 85.7% of the attention paid to a horse's sperm model suggests that the user is making a mistake.
 Using neural networks as blank chipsZero-training hand with 1.48 million parameters
Now that we can understand how each layer of weight is made into a circuit, a more crazy idea naturally arises.We can't just have a pre-training model, let the big model start at zero weight and build a neural network with its bare hands.。
Many people's first reaction is that it's impossible, tens of thousands or even millions of numbers, how can a big model be a pair?
But when you look at Astra's operational records, you'll suddenly realize that it's not trying to guess the numbers.It's a way of looking at the neural network as a blank chip.。
It does.Use Python code as a "compilator" to write your own layer of algorithmic rules into a weight matrix!
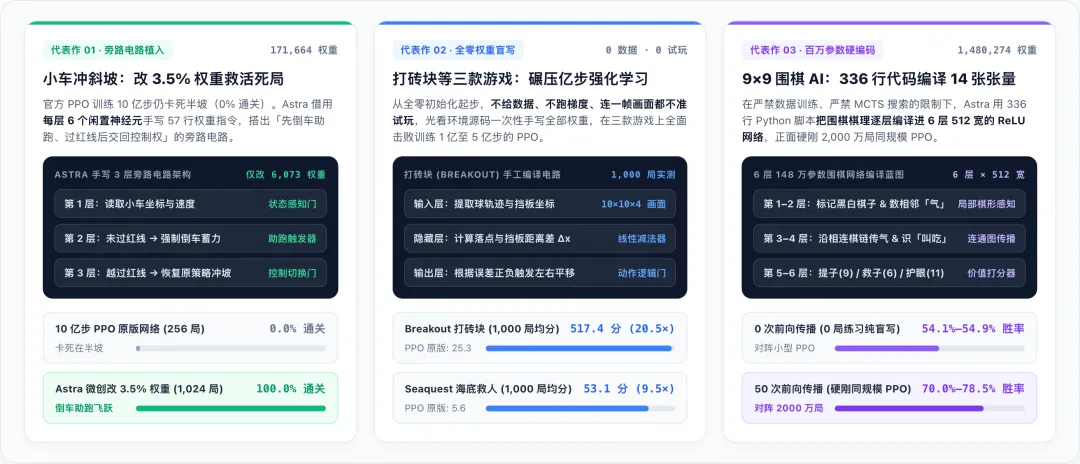
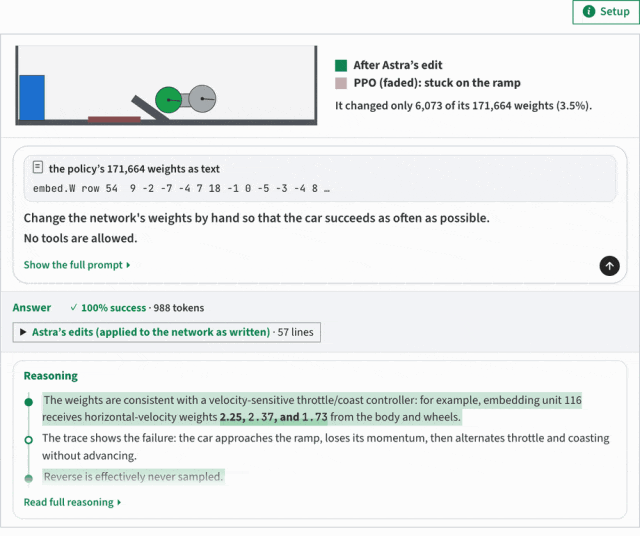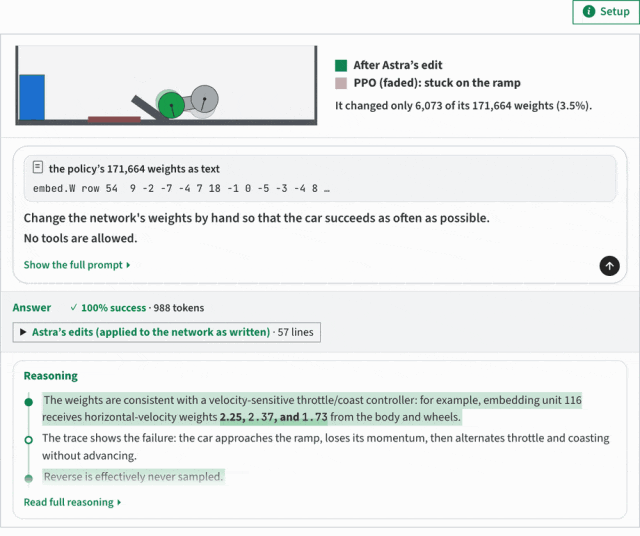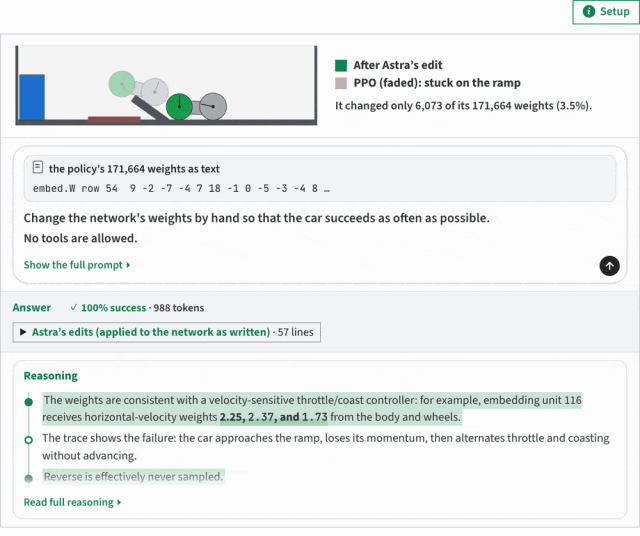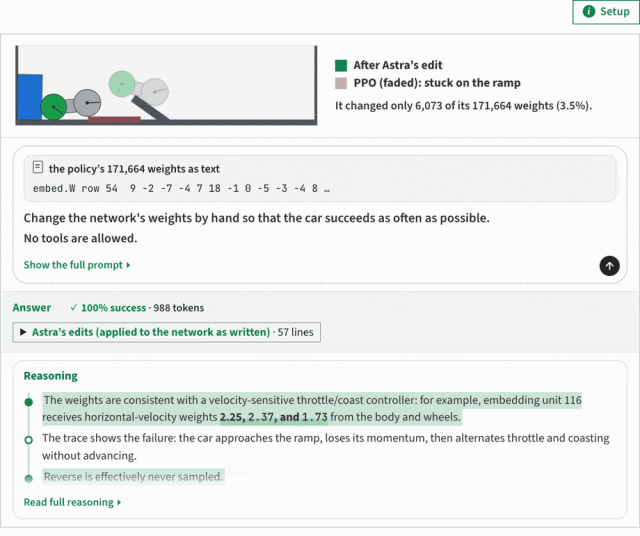
For example, in the game "Small Car Ride Slope", the strength training PPO trained 1 billion steps to die at half-slope (toll rate 0%), because the small car did not know how to roll over to help run the distance.
Astra looked at the syndrome and borrowed six suspended neurons per layer.A 57-line manual weighting instruction for a side-by-side circuit that says, "Run over the red line and back and forth".。
This modification only moved 3.5 percent of the weight, allowing the truck to get 100 percent throughput in 1,024 innings of testing!
When it came to writing from scratch, Astra was at the top of the list.0 data, 0 gradients, not even a single image is allowed to playUnder the limit conditions, write the first layer of neurons as a decimator for calculating "the difference between the ball and plate" and write the second layer as a switch that controls the movement of the ball and plate.
It's the weight of this collection of purely hand-crafted compilations.It scored 517.4 points in 1,000 innings of testing, giving the PPO algorithm that trained 500 million steps (25.3 points) a 20.5-fold bounce!
When the challenge was upgraded to 1,480,000 9×9 cheerleaders, the "weight compilation technique" was even more impressive.
Under strictly prohibited data training and strictly prohibited Monte Carlo tree searches (MCTS), Astra wrote 336 lines of Python scripts.You write a layer of chess into 14 weight tables of six layers of neural networks.。
It allows the first two layers to identify the black and white pieces and count the "air" next to them, allowing the middle layer to transmit the information of the gas in sequence to the connected chess chains, to find the pieces that are ready to be eaten, and the last layer to divide the dice, rescuers and eye protection respectively.
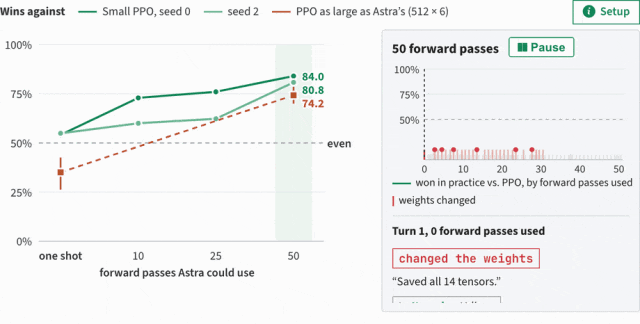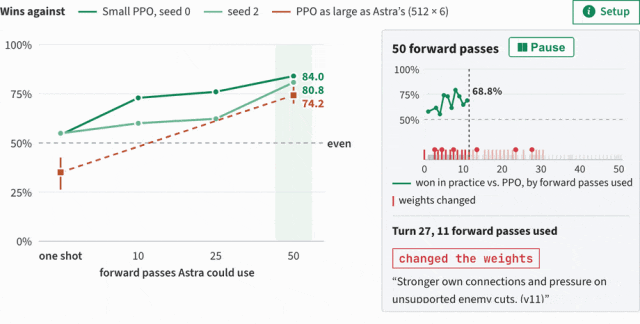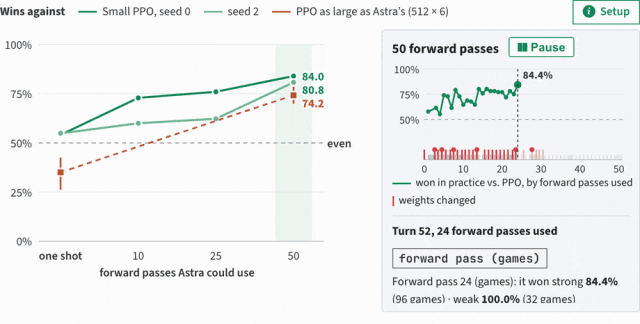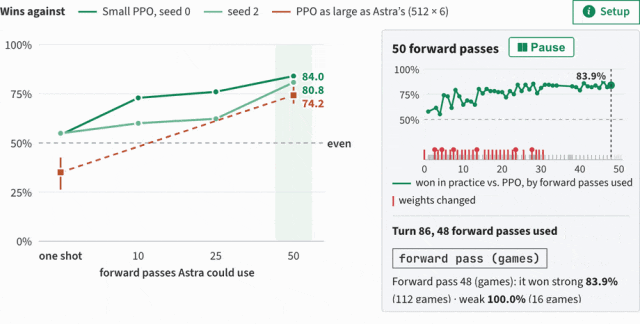
Even if we didn't do a single practice game, we were not allowed to do it.This purely code-driven go-go network has a winning rate of more than 54% against two smaller PPO networks.。
When it's allowed to try 50 times, depending on the weight of the defeat, the hand-held network can be upgraded.The PPO network, which has just trained 20 million rounds of the same size (1480,000 parameters), has a win-loss rate of 70.0% to 78.5%!
 The Nam Gate CloudHe is the father of Princeton's first D.S.P.
The study of subversion of cognition is based onMIT CSAIL is a young, yet amazing four-person team.。
It was a collaboration.Rikiya TakehiShe is a first-year PhD student at MIT CSAIL, and completed her undergraduate studies at the University of Jalandhar.
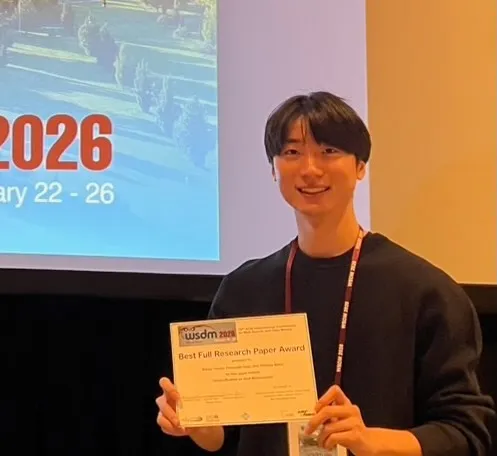
He did.Among the tens of thousands of technical and scientific students in the university, the top 0.01% (the only representative of the university) received the highest honour, the "Chongqing Memorial Award".He is also a graduate of the University of California, San Diego.During his undergraduate studies, he won the WSDM 2026 Best Paper Award.。
Another collaborationJayden TeohHe is also a PhD student at MIT CSAIL, taught by computer vision masters Phillip Isola and Vincent Sitzmann.
He received his undergraduate degree from the Singapore University of Management.Previously, he worked at the Google DeepMind and Microsoft Research Laboratories in New York to study world models and expressive learning.。
Third authorAlex L. ZhangHe is a second-year PhD student at MIT CSAIL.Benko graduated first in the computer department at Princeton University and was named Young Scientist of the Year 2026 by Science America.。
He did.A recursive language model for exploding open source communities (RLMs)He has also led the creation of well-known benchmarks such as KernelBench, SWE-bench Multimodal.
Teacher behind the scenes in townOmar KhattabHe is an assistant professor at MIT EECS and the director of the OASYS laboratory.He is currently the co-leader of the MIT Deep Learning core curriculum.。
He is best known for his portrayal ofIt is the world's largest model programming framework DSPy and the modern retrieval milestone ColBERT, whose dominant open-source project has already surpassed 100 million cumulative downloads.。
When Ethan Mollick, a professor at the Wharton School of Business, relayed the study, he exclaimed that it was undoubtedly a game-changer.
When Andrej Karpathy proposed "Software 2.0" a decade ago, the core idea was that humans no longer write code by hand, and that they change the search process from gradient to gradient in weight space.The MIT study was launched by the "Software 3.0 Gateway" where the big models read and write weight directly.。
In the past, we've talked about AI self-evolution, and we've always thought about AI writing code to run training scripts.
The moment the big model learns to see through, modulate, and manually rewrite the weight of the neural network, it's actually connected to the last nerve in the ASI's self-evolutionary link!